AI Agent Frameworks in 2026: LangGraph, CrewAI, OpenAI Agents SDK, Claude Agent SDK, Mastra and Google ADK (Compared)
Compare eight AI agent frameworks by language, state, MCP, approvals and current hosted prices. Pick the right runtime for production.



Pick LangGraph for a stateful workflow, CrewAI for a genuine team of role-based agents, Mastra for an agent inside a TypeScript app, and OpenAI Agents SDK for a compact application-owned agent loop. Across these 8 AI agent frameworks, the choice turns on who owns state, approvals and recovery.
Open source AI agent frameworks remove a library subscription from your budget. They leave model calls, hosting, storage and operational work to pay for. Documentation, repository licenses and maker pricing pages below were verified on 7 October 2026.
Claude Agent SDK deserves a separate decision: it embeds Claude Code's tool-using runtime in your application. Pydantic AI suits typed Python services; Vercel AI SDK suits a streaming web interface; Google ADK suits a Google-oriented agent system. A plain provider SDK loop remains a good choice when none of those extra primitives solves a problem you have.
AI agent frameworks comparison at a glance
The hosted column describes what you can buy from the maker. A hosted observability service records runs; a hosted runtime executes them. Those are different purchases, even when both sit beside a free library.
The choice flips when unfinished work must survive beyond the request that started it. If an operator can approve an action tomorrow, or a worker can die after a write, evaluate the persistence and resume path before the chat interface. MCP, the Model Context Protocol for exposing tools and resources to agents, does not supply that recovery guarantee by itself.
Agentic AI frameworks: how these were picked
These recommendations compare documented architecture, license scope and current prices. They are not performance measurements from running the frameworks.
The shortlist turns on six questions:
- Execution shape: Does your code declare the sequence, does a model choose the next tool, or do specialists delegate work?
- State ownership: What persists: messages, workflow position, shared memory, pending decisions or all of those?
- Recovery: What happens when the process restarts, a tool times out or the user returns later?
- Tool boundaries: Can you expose narrow application functions and the MCP servers you need?
- Human review: Can a person inspect the proposed action before execution, and can the decision resume correctly?
- Operating cost and license: Which features belong to the free core, which need a commercial agreement, and what does the hosted service meter?
The eight sections are ordered by useful production jobs. LangGraph is the default recommendation for the stateful workflow in the brief; it is not a universal winner over a smaller loop. A TypeScript product that mostly streams answers should not adopt a graph runtime merely to follow that recommendation.
Hosted no-code builders and observability products are excluded as framework picks. Logfire appears as an optional purchase beside Pydantic AI, not as a ninth framework. Specialized ecosystems outside this shortlist may fit an existing stack; adding them without the same state, approval and price analysis would make the decision harder.
AI agent orchestration frameworks: state and human review
The useful definition of state is the information another worker needs to continue the same business job correctly. An orchestration framework coordinates the steps, but you still need to decide which records make continuation safe.
Consider a refund assistant. Its history records the conversation and policy lookup. Its position records that eligibility was checked and the refund remains pending. Its review record identifies the amount and action a manager approved. Its receipt records whether the payment system accepted that operation.
Those records answer different questions. A transcript saying “refund approved” does not prove that a manager approved the current amount. A workflow checkpoint saying “call completed” does not substitute for the payment system's receipt. A stored receipt also needs a stable operation identifier, so a retry can recognize the same intended write.
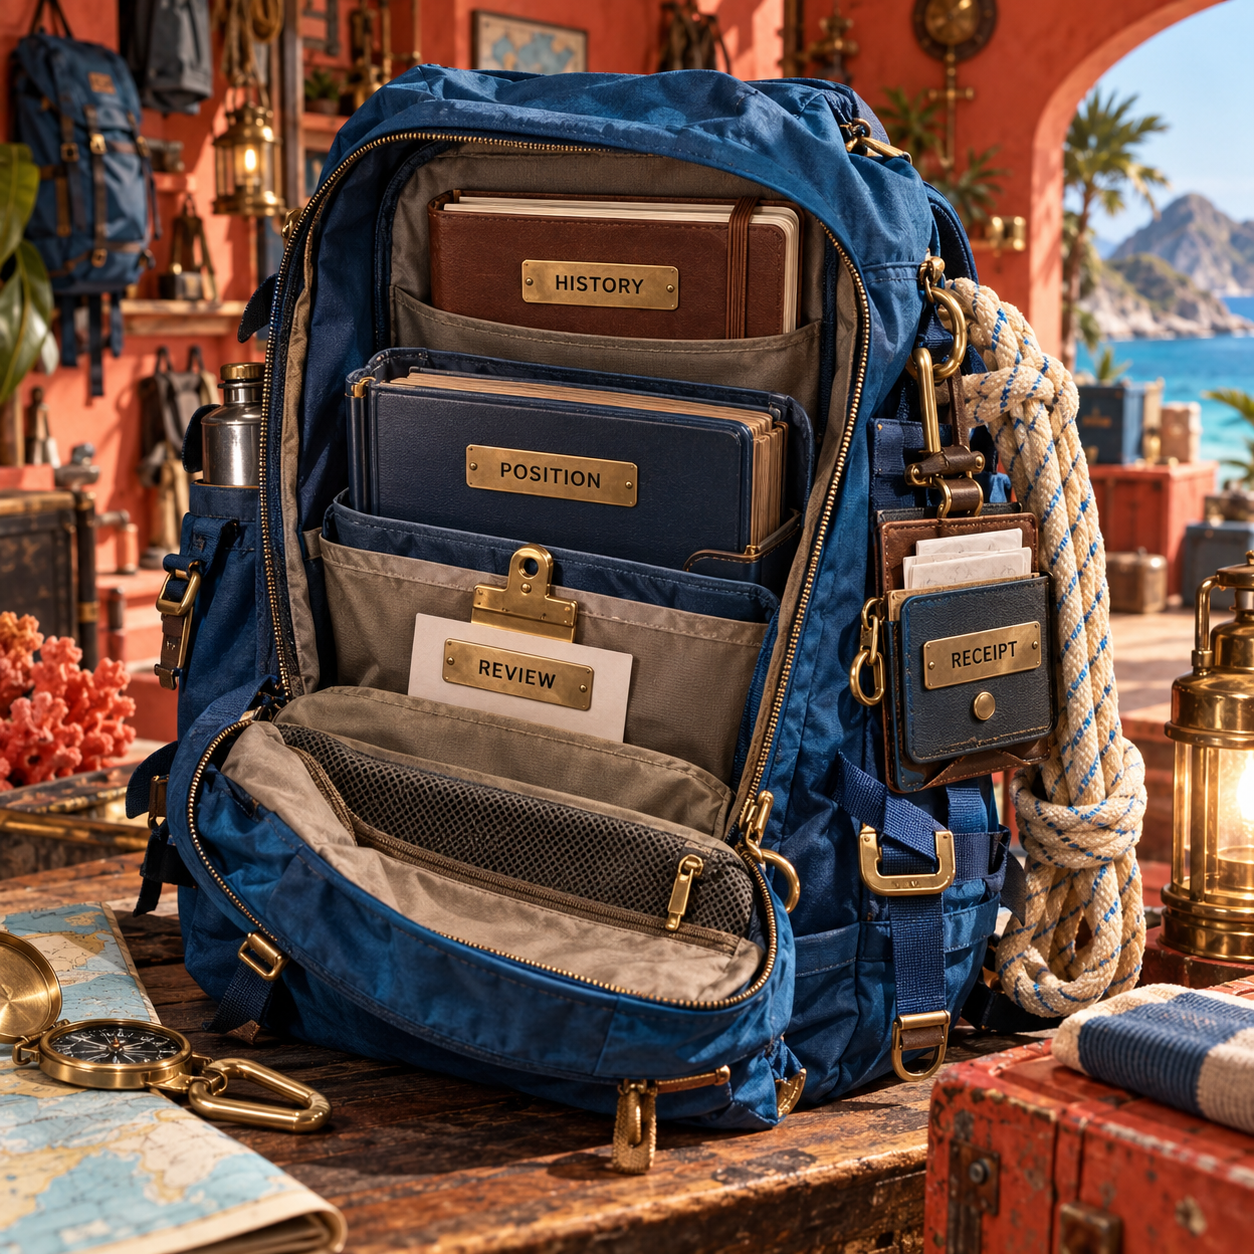
For a read-only research assistant, stored history may be enough. For onboarding that pauses for documents, a saved execution position becomes valuable. For a refund or account change, the approval and external receipt belong in the design before launch.
This is also where human review claims need scrutiny. A prompt that asks the model to be careful is an instruction. A tool gate that waits for a decision before executing is a control. An approval screen becomes useful operationally when it can show the exact arguments, authenticate the reviewer, store the decision and recover after a restart.
The SDK can expose the pause or approval request. Your product still owns the reviewer's authority and the action's validity. If the requested amount changes after approval, the earlier decision should not silently authorize the new amount. Treat that as an application contract, whichever framework you choose.
Best AI agent frameworks for each production job
1. LangGraph: best for a stateful multi-step workflow
LangGraph is the strongest starting point when your agent is a workflow with an execution position that matters. It is a low-level graph runtime: you define nodes, the work each node performs, and the transitions between them. Some nodes can be ordinary code and others can ask a model to choose what happens next. LangChain components are optional, so choosing LangGraph does not require putting every application operation behind another abstraction.
Language and license: Python and TypeScript/JavaScript; MIT-licensed core.
Best for: A case, onboarding process or research workflow that branches, pauses and resumes.
Standout: Explicit workflow state, thread checkpoints and a separate cross-thread store.
Pricing: Free core library. LangSmith Developer is $0/seat/month; Plus is $39/seat/month; Enterprise is Custom pricing. Each hosted plan has its own usage rules.
Free trial: Developer is a continuing free plan; paid deployment access begins with Plus.
For a technical founder building supplier onboarding, the useful unit is one supplier case. A document-extraction node can produce candidate fields; deterministic code can validate them; an agent can request missing evidence; a reviewer can approve the final record. The graph lets the operator see which transition is waiting rather than infer progress from a conversation.
State: Checkpointers save a thread's graph state. Stores hold application-defined information across threads, such as a supplier's stable profile. An in-memory checkpointer loses its contents when the process restarts, so a production design needs persistent storage. Keep large evidence files outside the checkpoint and store their references. Otherwise a compact control record turns into a growing copy of every artifact. These distinctions are documented in LangGraph persistence.
Tools, MCP and human review: Nodes can call your own application code. LangChain MCP adapters expose local stdio or remote Streamable HTTP tools to the graph. LangGraph's interrupt() pauses execution; the caller supplies a decision through Command(resume=...). The important detail is that the interrupted node restarts from its beginning when resumed. Put an external write before that pause and it can run again. The interrupt guide makes that behavior explicit.
The wall is the work you must own around a low-level runtime: state schemas, checkpoint retention, worker deployment, graph changes and recovery semantics. Durable execution is a capability you configure and design around. It is not a promise that a payment or email will happen exactly once regardless of your tool implementation.
Hosted costs, verified 7 October 2026: Developer includes one seat and 5k base traces/month. Plus includes 10k base traces/month across the organization and one free Serverless Small deployment. Additional serverless or dedicated deployments consume resources; the maker recommends dedicated deployments for customer-facing agents. Enterprise has custom pricing and self-hosted/hybrid options. The current unit is the LSU, at $1.00/LSU. Published deployment meters include runtime compute at 0.0675 LSU/vCPU-hour, runtime memory at 0.0090 LSU/GiB-hour, database compute at 0.177 LSU/vCPU-hour and database memory at 0.025 LSU/GiB-hour. LangSmith pricing is the source for those tiers and meters.
- Explicit transitions make an unfinished business case inspectable.
- Deterministic validation and model-directed work can share one graph.
- Checkpoints and interrupts support delayed human decisions.
- The MIT core can run without a hosted-platform subscription.
- You must operate persistent checkpoints and manage their retention.
- Resuming an interrupted node requires careful placement of side effects.
- Hosted collaboration and production deployment add seats and usage meters.
Use this mini-tutorial as the first design exercise, before connecting a write-capable tool:
Give the job a durable identity
Use one thread identifier per supplier case, customer request or other outcome. Reuse it when that job resumes; do not create a new thread because the worker changed.
Separate decisions from artifacts
Store the current stage, evidence references, proposed action and approval status in the state contract. Keep documents and large outputs in their own storage.
Configure persistent checkpoints
Replace the in-memory saver before the pilot needs restart recovery. Define retention and make the same thread available to a replacement worker.
Pause before the write
Use an interrupt to present the proposed action. After approval, call a narrow application tool with a stable operation identifier and save its result.
Exercise recovery
Restart the worker during a model call, while waiting for approval and after the external write. Confirm the job continues and the intended action is not duplicated.
Verdict: Choose LangGraph when saved workflow position and recovery are product requirements. Skip it when the job is a short request that your existing application can complete and retry cleanly.
2. CrewAI: best for a genuine team of role-based agents
CrewAI fits work that has distinct specialist roles and handoffs. Its Python abstraction groups agents into Crews, with roles, goals and tasks; Flows provide the surrounding event-driven process. The useful production pattern is to let a Crew perform a bounded piece of collaborative work and let a Flow own the stages around it.
Language and license: Python; MIT.
Best for: Research, analysis and drafting jobs with different responsibilities or tool access.
Standout: Role-based collaboration inside structured Flows.
Pricing: Free open-source library. Hosted Basic is Free with 50 workflow executions/month; Enterprise is Custom.
Free trial: Basic is a free plan. Enterprise offers Request trial; the pricing page gives no public trial duration.
A founder preparing account briefings can give a researcher access to evidence, an analyst the task of identifying relevant buying signals, and a writer responsibility for the final brief. Those roles earn their place when they have different inputs, permissions or acceptance criteria. Giving the same model three biographies and the same tools does not by itself create three useful specialists.
State: Flow state can be a dictionary or a Pydantic model, a Python schema that validates expected fields. The @persist mechanism saves state snapshots; SQLite is the default persistence backend and a custom implementation is supported. Persisted state can be restored under an existing identity or forked into another run. Keep a Flow's status separate from an agent's remembered facts: “the brief is awaiting review” is process state; “this account sells to hospitals” is knowledge. CrewAI Flows documents these controls and human feedback.
Tools and MCP: The current MCP surface supports agent configuration through mcps, with local stdio, HTTP and SSE transports, plus an adapter route. Tool filtering matters more than how many integrations you attach. A researcher should receive lookup tools; an agent drafting a brief should not inherit permission to mutate the customer account simply because the same MCP server exposes both operations.
Human review: Flow human feedback can pause work for approval or revision. Custom asynchronous feedback providers allow a product to collect a decision outside the original interactive process. Design the result of review as an explicit business decision, with the proposed artifact and reviewer recorded. A role named “reviewer” inside the Crew is still a model; it is not the human gate the operator will rely on.
The wall appears when collaboration expands faster than the task contracts. If a researcher changes its evidence format, an analyst may quietly interpret it differently, and the writer can turn that drift into a confident final document. Require a structured evidence handoff and a concrete acceptance rule at each boundary. Keep final writes outside unconstrained agent-to-agent discussion.
Hosted costs, verified 7 October 2026: The live CrewAI pricing page lists Basic Free, including a visual editor, AI copilot, GitHub integration and 50 workflow executions/month. Enterprise is Custom and offers governance plus deployment on CrewAI Cloud, your VPC or your infrastructure. There is no published fixed-dollar middle tier or per-execution overage to quote. A workload requiring 51 hosted executions exceeds the listed Basic allowance; it needs a commercial discussion or a different deployment plan. The open-source library's model and infrastructure bill remains separate.
- Roles map well to jobs with distinct responsibilities and evidence handoffs.
- Flows provide a process boundary around collaborative work.
- Persistent Flow state and human feedback are documented features.
- The open-source core and hosted platform are separate choices.
- Agent personas can add calls without improving the business result.
- Role boundaries still need typed inputs and acceptance rules.
- Hosted workloads beyond Basic have no public fixed entry price.
Verdict: Choose CrewAI when specialist ownership is part of the work. For a fixed validation-and-approval process, keep the Flow in charge and use only the agent roles that earn their model calls.
3. OpenAI Agents SDK: best for an application-owned agent loop
OpenAI Agents SDK is a good fit when your application should own deployment and data while a small runner manages model calls, tools and handoffs. An agent definition packages instructions and available capabilities; the runner continues until the agent produces a final answer, hands off or pauses. That is a useful amount of framework for a product that already has a backend, authentication and storage.
Language and license: Python and TypeScript; MIT-licensed open-source SDK.
Best for: An OpenAI-oriented application needing a tool loop, specialist handoffs and review controls.
Standout: A compact runner with SDK-managed tools and built-in tracing.
Pricing: No paid SDK seat tiers. Model calls and applicable hosted tools are usage-based; your runtime costs are separate.
Free trial: There is no SDK subscription to trial; do not assume API usage is free.
Imagine an account-support agent inside an existing SaaS product. Your backend already knows the signed-in user's account and entitlement. The agent can look up account context, ask for a missing detail and call a narrow cancellation-request tool. The useful abstraction is a controlled loop around those operations, not a second platform that tries to become your application database.
State: Official documentation offers local replay history, SDK sessions backed by your storage, a Conversations API identifier, or response-to-response continuation through a previous response ID. Pick a consistent strategy. Loading all local history while also asking the API to continue the same stored conversation can duplicate context. A conversation record also does not automatically record the lifecycle of an unrelated billing operation; retain that in your application.
Tools, MCP and human review: The SDK supports function tools, hosted tools and MCP, including SDK-managed local/private servers over stdio or Streamable HTTP. Approval interruptions return resumable state. Your application can approve or reject the proposed call, serialize that state for delayed review and resume the same run. Guardrails are automated checks; human approval is a separate decision. In the official human-review guide, input guardrails apply to the first agent and output guardrails to the final-producing agent. Put checks beside the tool that creates the side effect.
The wall is the orchestration you still operate. You need the storage adapter, job lifecycle, review interface and a way to resume on another worker. The SDK does not take over your business transaction log because it can return a resumable run. That division is attractive when those systems already exist; it becomes more work when you expected a fully hosted agent service.
Costs, verified 7 October 2026: As an example of the model bill, OpenAI's pricing page lists gpt-6.1-sol Standard short-context input at $2.00 per 1M tokens and output at $10.00 per 1M tokens. A hypothetical completed task using 20,000 uncached input tokens and 2,000 output tokens across all its calls costs $0.06 in model usage. At 5,000 tasks/month, that is $300 before tools, hosting, storage or observability. This is an arithmetic example, not a measured agent workload; other contexts, modes and caching have different rates.
OpenAI also offers a separate Agents API that runs a managed Codex harness. It is not a hosting tier for arbitrary Agents SDK code. Account for the managed path's model, tool, sandbox and third-party charges instead of assigning it an invented monthly plan. The distinction is developed in OpenAI Agents API vs Agents SDK.
- Fits existing Python and TypeScript application backends.
- Tools and handoffs give a small loop useful structure.
- Approval interruptions can carry a delayed decision back into the run.
- Built-in tracing makes the loop easier to inspect.
- Deployment, storage and the approval UI remain application work.
- Conversation continuation is not a complete business workflow log.
- Provider convenience should not be mistaken for a framework-wide cost cap.
Verdict: Choose it when your backend should own the system and the runner removes loop plumbing you would otherwise maintain. Start with the how to build an AI agent guide after making that ownership decision.
4. Claude Agent SDK: best for a file-and-command agent runtime
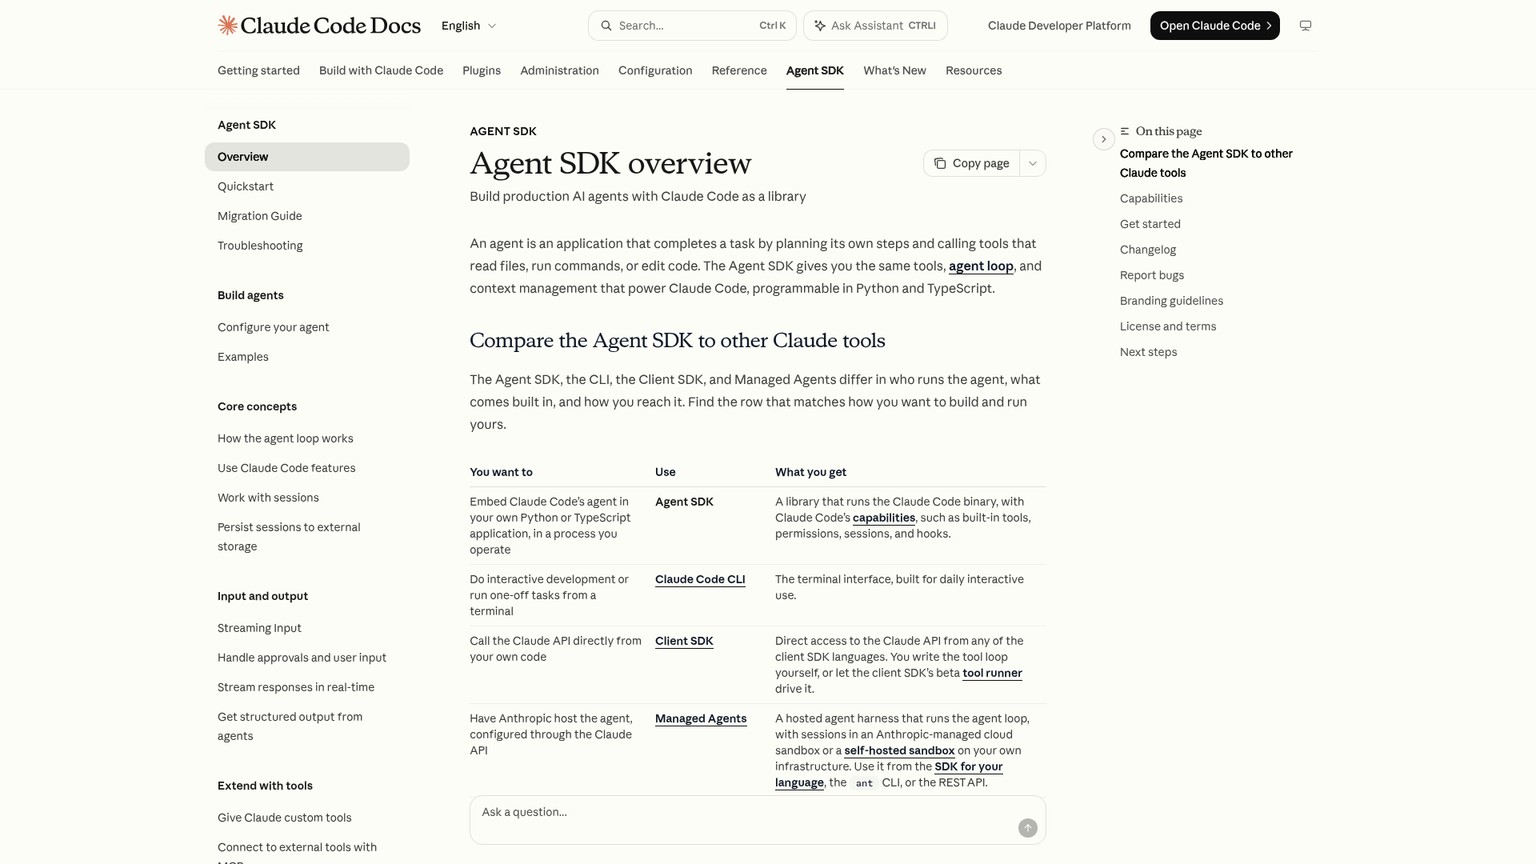
Claude Agent SDK is the relevant choice when the agent should work with files, commands and code using the runtime behind Claude Code. It embeds that runtime in a Python or TypeScript process you operate. That is a materially bigger decision than installing a client library to send a prompt to Claude.
Language and license: Python and TypeScript. The Python wrapper's LICENSE is MIT; Anthropic's SDK documentation says use is governed by its Commercial Terms, except separately licensed components.
Best for: A repository assistant, file-processing worker or coding agent that needs a ready tool-using runtime.
Standout: Built-in file and command tools, context management, sessions, hooks and subagents.
Pricing: No separate SDK subscription tier; API usage is metered. Separate Claude Managed Agents adds $0.08 per running session-hour to model tokens.
Free trial: No SDK subscription trial is required. Model access and hosted runtime use have their own billing.
For a developer building a repository maintenance service, the built-in runtime can read the tree, inspect relevant files and run commands. For a support chatbot that calls an account lookup and returns a draft, that same execution surface may be more than the product needs. Choose the harness because the work benefits from its environment, not because both products use Claude.
State: The SDK automatically writes conversation sessions to disk and supports continuation, explicit resume and forking. The documentation distinguishes conversation persistence from filesystem persistence: resuming a transcript does not revert or restore the files an agent edited. Moving work to another host also requires the necessary session files, not just an identifier. Your operator needs a storage and workspace policy that keeps the evidence and the working files aligned. Claude SDK sessions explains the boundary.
Tools, MCP and human review: Built-in capabilities include reading, writing and editing files, running commands and connecting MCP tools. Permission rules and modes control automatic execution; canUseTool handles calls that reach the runtime approval callback. An earlier automatic approval can bypass that callback. Use a PreToolUse hook when a check must apply to every tool call, and keep the actual environment's access boundaries under application control. These are runtime controls, not a substitute for isolating customer workspaces.
The wall is coupling to an execution environment and the Claude runtime. The SDK can manage its conversation, but your product must handle workspace provisioning, retained artifacts, credentials and review delivery. If a tenant's job resumes on a fresh container with none of its files, a session transcript will not reconstruct the filesystem for you.
Costs and terms, verified 7 October 2026: The SDK overview explicitly distinguishes the embedded Agent SDK, the direct Claude client SDK and Claude Managed Agents. For commercial products it directs developers to API-key authentication; a user's claude.ai subscription is not a hosted-agent allowance you can assume for your customers. The MIT Python wrapper does not make the entire bundled runtime a provider-neutral MIT framework.
The Claude pricing page lists Claude Sonnet 5.5 base input at $2/MTok and output at $10/MTok, with separate cache and other modifiers. Managed Agents charges standard model tokens plus $0.08 per session-hour while status is running; idle, rescheduling and terminated time are excluded. A hypothetical 100 running session-hours adds $8 in runtime, before model and tool charges. This is a separate hosted harness, not the same deployment mode as running the Agent SDK yourself.
- Built-in file and command capabilities suit environment-based work.
- Sessions and forks preserve conversational context for follow-up tasks.
- Hooks and permission controls expose meaningful review boundaries.
- A separate managed service is available when hosting the harness is the larger burden.
- Persisted conversation does not restore the working filesystem.
- You must operate or buy the execution environment around the agent.
- The wrapper license and commercial runtime terms need separate understanding.
Verdict: Choose it for work that needs the Claude Code runtime's capabilities. For a thin Claude tool loop, use the provider client SDK and keep the application's own tools and state.
5. Mastra: best for an agent inside a TypeScript app
Mastra is the better fit when a TypeScript product needs more than a streaming model response: agents, stored memory, tools and resumable workflows in one application framework. It supplies those primitives alongside a development interface, Mastra Studio. That makes it a useful middle ground between a small web-facing loop and a deliberately low-level workflow runtime.
Language and license: TypeScript. Core and most of the repository are Apache 2.0; code in ee/ directories uses the Mastra Enterprise License.
Best for: A TypeScript SaaS agent that needs application memory and background workflow stages.
Standout: Agents, memory, workflow snapshots and MCP client/server support in one stack.
Pricing: Platform Starter $0/month plus usage; Teams $250/month plus usage; Enterprise Custom. Self-hosted Free is $0/month; self-hosted Enterprise is Custom.
Free trial: Starter is an ongoing $0 plan with metered overages, not unlimited free operation.
Imagine a customer-success application that assembles renewal evidence, drafts a recommendation and waits for an account owner's review. The frontend and backend are already TypeScript. Mastra can express the agent and the surrounding workflow without making another language a prerequisite for the process.
State: Agent memory needs a configured storage provider. Message history, working memory and longer-running context management serve different needs from workflow position. A workflow's suspend() captures an execution snapshot; resume() supplies the expected data and continues the suspended work. Those snapshots persist across deployments and restarts when stored through the configured provider. The suspend-and-resume guide is the important read for an approval workflow, not merely a demo of chat memory.
Tools, MCP and human review: MCPClient consumes external tools; MCPServer can expose Mastra agents, tools and workflows to other clients. Both support stdio and Streamable HTTP. Tool approval and suspension events can be surfaced to your product, while a workflow can suspend for review and validate its resume data. Keep a proposal's identity stable across that pause. An owner approving a draft renewal action should resume the recorded proposal, not a fresh model-generated substitute.
The wall is the difference between available primitives and a configured production application. Storage, tenant isolation, retention, authentication and replay-safe tools still need deliberate design. Also inspect license boundaries before building around enterprise controls: the Apache core license does not cover every ee/ feature under the same terms.
Hosted costs, verified 7 October 2026: The live Mastra pricing page lists Starter with 100K observability events, then $10/100K; 24 CPU hours, then $0.35/hour; and 15-day retention. Teams is $250/month with 1M events, then $8/100K; 250 CPU hours, then $0.25/hour; and six-month retention. Both list unlimited users, deployments and projects. Enterprise is Custom pricing with negotiated volume, retention and support.
A Persistent Server for 24/7 uptime is listed at $100/project on Starter and Teams. The model gateway lists market rate plus 5.5%; memory, retrieval, databases and egress have additional meters. Self-hosted Free carries a $0 framework price; licensed self-hosted Enterprise is custom-priced with a flat annual fee. Model and infrastructure use remain separate when you host it yourself.
For a hypothetical month with 100 CPU hours and 300K events, Starter's compute/event overages are $26.60 plus $20, or $46.60 before other meters. Teams' $250 base is not automatically the cheaper path for that workload. Choose Teams for the features and usage shape it actually changes; do not upgrade simply because the agent is now in production.
- TypeScript agents and workflows fit an existing web application stack.
- Stored snapshots provide an explicit path for delayed workflow review.
- MCP consumption and serving support integration in both directions.
- The hosted platform and self-hosted core are separate choices.
- Persistence needs a real storage configuration and tenant design.
- Several hosted meters can sit outside the headline plan price.
- Enterprise repository features have a separate license boundary.
Verdict: Choose Mastra when the app needs agent behavior and workflow structure together. Choose Vercel AI SDK when the main work is a web interface around a smaller loop.
6. Google ADK: best for a Google-oriented agent system
Google ADK, the Agent Development Kit, fits a system that benefits from Google's agent tooling and deployment path while retaining code-defined agents and workflows. It supports Python, TypeScript, Go, Java and Kotlin. The framework can run on your infrastructure; using it does not itself require buying a hosted runtime.
Language and license: Python, TypeScript, Go, Java and Kotlin; Apache 2.0 core, verified in the Python repository.
Best for: An agent system whose existing operational stack is on Google Cloud.
Standout: Session services, scoped state, workflow composition and a managed deployment path.
Pricing: Free framework. Agent Runtime is usage-based, with standard on-demand compute at $0.085/vCPU-hour and RAM at $0.009/GiB-hour after their free allowances.
Free trial: Monthly hosted resource allowances exist; model tokens and other resource meters remain separate.
For an operations assistant in a Google Cloud application, the practical attraction is consistency with the environment your operator already knows. Your application can keep the user identity and access boundary in the existing backend while ADK coordinates tools and specialists. That may be more valuable than adopting another framework's cloud console solely for this agent.
State: Sessions contain events, conversation history and state. State prefixes distinguish application-wide values, user values and temporary values; unprefixed keys are session-scoped. The in-memory session service does not provide restart persistence. Database and Vertex AI session services provide persistent alternatives. Update state through tracked context/events rather than mutating a retrieved session object and assuming it was saved. The names of the cloud product have changed, but the ownership question remains: where will the replacement worker load the job?
Tools and MCP: ADK supports custom tools and MCP toolsets for local or remote servers. Check the implementation in your chosen language rather than assume every example applies to all five. The current native Agent Runtime deployment guide lists Python and Go; availability of a language SDK is not proof of identical managed-deployment support.
Human review: The experimental Tool Confirmation feature can pause a tool for a user or supervising system. Its current known limitations say DatabaseSessionService and VertexAiSessionService are not supported. TypeScript also requires manual confirmation logic within tool execution. This is a decisive compatibility check for a production job that must wait for review and survive a process restart. Do not independently select a persistent session service and Tool Confirmation and assume the pair is supported. If that pair is central to your design, use another approval mechanism you can validate or choose a framework whose documented pause/storage combination fits.
The wall is feature parity and backend compatibility. A broad language list can conceal a narrower path for the particular deployment or review feature you need. Verify the complete combination, including your session service and tool type, rather than approve the stack based on separate checkmarks.
Hosted costs, verified 7 October 2026: Google's Agent Platform pricing page uses shared resource meters. Standard on-demand Agent Compute includes 50 free vCPU-hours/month/account, then $0.085/vCPU-hour. Agent Memory includes 100 free GiB-hours/month/account, then $0.009/GiB-hour. Agent Storage has a 1 GiB-month free allowance; Sessions and Memory Bank describe storage at $0.30/GiB-month. Model tokens are separate.
The pricing page also lists eligible one-year savings rates of $0.0765/vCPU-hour and $0.0081/GiB-hour, and three-year rates of $0.068/vCPU-hour and $0.0072/GiB-hour. These are commitment options, not free-framework tiers. Session and memory operations also consume Agent Compute: a vCPU-hour at $0.085 corresponds to 3 million reads or 1 million writes. Keep them in the hosted estimate.
A hypothetical isolated runtime month with 100 vCPU-hours and 200 GiB-hours produces $5.15 in compute/RAM charges after those allowances. That excludes model usage, storage, session operations and any other consumption of the account's shared free resources. It is a component estimate, not a complete hosted-agent bill.
- Multiple language implementations give existing backends a path into ADK.
- Session services separate local development from persistent operation.
- Custom tools and MCP fit an application's existing service boundaries.
- Deployment can stay on your infrastructure or use Google's runtime.
- Language and managed-deployment support do not have blanket parity.
- Experimental Tool Confirmation excludes important persistent session backends.
- Shared cloud allowances and several resource meters complicate a headline price.
Verdict: Choose ADK when the required language, deployment and review combination is documented to work. Persistent human approval is the point where a generic Google Cloud preference should give way to compatibility evidence.
7. Pydantic AI: best for typed Python application services
Pydantic AI fits a Python backend whose agent must return validated data and use explicit application dependencies. Pydantic schemas describe the fields and types the system expects; the framework applies that discipline to agent outputs and tool interfaces. This is particularly useful when the next step consumes a structured decision rather than a paragraph of plausible text.
Language and license: Python; MIT.
Best for: An agent embedded in a Python service with strict input and output contracts.
Standout: Typed dependencies and validated output, with optional durable-execution backends.
Pricing: Free library. Optional Logfire Personal is Free, Team $49/month, Growth $249/month and Enterprise Custom.
Free trial: Logfire Personal is Free, forever; this is observability access, not free model execution.
Consider an intake service that returns a case category, evidence references and a recommended next action to an existing application. A validated output makes it easier to reject missing or malformed fields before an operator sees the result. It does not prove that the recommendation is true. You still need business rules, evidence checks and review for the action itself.
State: Message history can be carried between runs and serialized into your chosen store. That gives conversational continuity. For progress that must survive failures and restarts, Pydantic AI documents external durable-execution integrations, including Temporal, DBOS, Prefect and Restate. Those systems preserve execution progress; installing the agent library alone does not buy that runtime. An existing Python service with a durable job system should evaluate that integration before replacing its orchestration.
Tools and MCP: Current documentation uses MCPToolset, which wraps a FastMCP client for stdio, Streamable HTTP and SSE servers. Treat server identity and per-user credentials as application concerns. A shared server connection under one identity does not automatically become a separate authorization boundary for every user who asks the agent a question.
Human review: Deferred tools can wait for approval or an external execution result. An inline handler can resolve requests within the same run. For an external reviewer, the agent can return DeferredToolRequests; your application stores the history and outstanding calls, collects a decision, then starts a follow-up run with DeferredToolResults. That external continuation is a new agent run, so correlate it with the original conversation rather than assume its run identifier stayed the same. The deferred-tools guide documents the distinction.
The wall is the machinery around a strongly typed agent. The schema makes interfaces easier to reason about; it does not supply the reviewer's UI, durable queue or semantic correctness of the decision. If a document provides the wrong customer identifier in a valid string field, type validation can accept it. Validate identity and evidence independently before any write.
Hosted costs, verified 7 October 2026: Logfire pricing is a hosted observability and evaluation offer. Personal includes 10M telemetry records/month, hard-capped at $0, one seat and two read-only guests, three projects and 30-day retention. Team is $49/month with 10M records included, then $2 per million. It includes five seats, permits up to twelve, and charges $25 per extra seat. Growth is $249/month with unlimited seats, guests and projects, up to 90-day retention, and the same included record amount and $2/million overage. Enterprise is Custom, with Cloud, Dedicated and Self-hosted variants.
For six Team seats, the base is $74/month. At twelve seats it is $224/month. The thirteenth exceeds Team's seat cap; Growth is $249/month, only $25 above that twelve-seat Team base, with additional retention and organization features. None of those prices includes hosting your Pydantic AI agent or its model calls. Use the telemetry budget as a separate line, not as the cost of the agent runtime.
- Typed output makes downstream application contracts explicit.
- Python dependencies can carry existing services into the agent cleanly.
- Deferred tools support external approval and execution workflows.
- Durable integrations let an existing job engine retain ownership.
- Valid structure does not establish factual or business correctness.
- Message persistence and durable execution are different configurations.
- Hosted Logfire does not remove agent deployment responsibilities.
Verdict: Choose Pydantic AI when a typed Python service is the center of the product. Add durable execution only when the job needs it, and compare that engine's operating requirements separately.
8. Vercel AI SDK: best for a streaming agent web app
Vercel AI SDK fits a TypeScript or JavaScript application where the user interface, streaming response and tool loop are the immediate product. Its Core surface standardizes model and tool calls; its UI surface connects those interactions to a web interface. You can use the library without deploying the application to Vercel.
Language and license: TypeScript/JavaScript; Apache 2.0.
Best for: A chat or agent interface inside an existing web product.
Standout: Streaming UI primitives plus reusable tool loops across providers.
Pricing: Free library. Optional Vercel hosting: Hobby $0/month, Pro $20/month plus usage, Enterprise Custom. AI Gateway has separate credits.
Free trial: Hobby is a free personal-use plan; the hosting pricing page offers a Pro trial.
A founder adding an account assistant to a web application can stream an answer, show a tool's progress and ask the user to approve a change inside the same interface. If most of the work finishes in that interaction, this is a useful scope. A process that must wait for another department tomorrow needs a job lifecycle and persistence beyond a browser component.
State: Reusable agent loops do not automatically turn a chat into a durable business process. The documented message-persistence pattern stores UI messages in an application-owned store; production can use a database or cloud storage. Keep stable message identifiers and validate restored tool messages against current schemas. Decide separately what happens when the browser closes while the backend is still working. Chatbot message persistence explains the integration rather than claiming the SDK supplies your database.
Tools, MCP and human review: The MCP client exposes server tools to the model loop. The current local-tool approval API is toolApproval; the older needsApproval property is deprecated. Manual approval returns request parts, your UI gathers a decision, and a subsequent call consumes the approval response. Crucially, provider-executed tools are not controlled by this local approval setting. Configure those provider-side controls separately. The tool-calling documentation describes both the lifecycle and that boundary.
The wall is assuming a polished conversation surface is a workflow engine. The SDK gives you useful loop controls and ordinary code can express a known sequence. It does not make your hosting function wait indefinitely for a reviewer, preserve an external transaction receipt or authorize the person who clicked Approve. Keep the UI as a view into application state rather than the sole owner of the job.
Hosted costs, verified 7 October 2026: Vercel's hosting pricing lists Hobby at $0/month, Pro at $20/month and Enterprise as Custom. Hobby is restricted to noncommercial personal use. The Pro plan pricing details specify that the platform fee includes one deploying seat and $20 monthly usage credit; extra deploying seats are $20/month, while viewers are free. Three deploying seats therefore start at $60/month before on-demand consumption. The usage credit belongs to the plan; adding a seat does not multiply it.
Optional AI Gateway pricing lists a free tier with $5/month credit for eligible models and a paid tier using purchased pay-as-you-go credits. Token rates follow provider list prices with zero markup. Purchasing credits moves the account to the paid tier and ends the recurring free allowance; bring-your-own-key access is on the paid tier. Those gateway credits are distinct from the hosting plan's usage credit, and optional gateway features can have their own charges.
- Streaming and tool interactions fit a web product's interface directly.
- Core APIs support multiple model providers.
- Local tool approval can be presented through the application's UI.
- Library adoption does not require buying Vercel hosting.
- Your application still supplies persistent message and job storage.
- Local approval settings do not govern provider-executed tools.
- Hosting seats, hosting usage and gateway credits are separate budget lines.
Verdict: Choose Vercel AI SDK for the web-facing loop. Choose Mastra when agents and stored workflows need a larger shared framework, or add a separate durable job system when the task outlives the interaction.
Who should pick what
For a stateful multi-step workflow, start with LangGraph. The switch is not how many prompts you have; it is whether saved position, branching and delayed review are part of the outcome. Use an explicit graph when the operator needs to know where the case is and what can safely run next.
For a team of role-based agents, pick CrewAI. Give each role a separate job, evidence contract or tool boundary. If all the roles use the same input and produce the same sort of answer, simplify the design before selecting a collaboration framework.
For an agent inside a TypeScript web app, shortlist Mastra and Vercel AI SDK. Mastra earns its larger scope when stored memory and workflow suspension belong to the product. Vercel AI SDK earns its place when streaming and tool interaction are central and your backend already owns the rest. Existing application infrastructure can flip this choice: a mature job engine reduces the reason to adopt another workflow layer.
For a compact provider-oriented loop, choose OpenAI Agents SDK or the provider client SDK. OpenAI's agent runner adds tools, handoffs and approval state inside your application. For Claude, choose the Agent SDK specifically when built-in file and command work matters; choose the client SDK for a smaller custom loop.
For a Google-oriented system, consider ADK after checking the whole feature combination. The current Tool Confirmation limitations are enough to change a persistent-review architecture. Language support alone should not settle that decision.
AI agent frameworks Python teams should shortlist
LangGraph fits explicit workflow position; Pydantic AI fits a typed service and validated outputs; CrewAI fits distinct collaborating roles. OpenAI Agents SDK fits a smaller application-owned runner. Python availability is the starting constraint, while the state and approval model makes the final choice.
When the sequence is already known, keep ordinary code or a deterministic workflow in charge. The n8n Agents vs Workflows comparison develops that same boundary: the model chooses where judgment helps, while the workflow owns the actions you can declare in advance.
No framework: when a plain provider loop is better
Use a plain provider SDK loop when one model provider, a small set of tools and a bounded task cover the job. A read-only account lookup, document classification or short drafting request can often stay inside the backend you already operate.
The basic loop sends the request, validates any tool arguments, calls an allowed application function, returns the tool result and continues until the model finishes or reaches your stop rule. If the sequence is fixed, the application can call the required functions directly and ask the model only for the judgment or text it supplies.
This choice is attractive when your application already owns authentication, durable jobs, retry policy, storage and telemetry. A framework that merely wraps those existing pieces creates another interface to maintain. It becomes valuable when it removes a specific recurring burden, such as resumable workflow position, consistent handoffs or an approval-state lifecycle.
Set a maximum amount of work, retain the necessary history and log the outcome. “No framework” still needs a deliberate owner for failures. Once you are repeatedly writing checkpoint transitions, delayed approval handling or specialist orchestration yourself, reconsider the library that provides that missing primitive. Adopt it for the recurring problem you can name.
Open source AI agent frameworks: licenses and operating costs
The free-library decision and the hosted-platform decision should be separate budget approvals. LangGraph, CrewAI, OpenAI Agents SDK and Pydantic AI have MIT cores; Vercel AI SDK, Google ADK's verified Python core and Mastra's core use Apache 2.0. Mastra enterprise directories and the Claude runtime introduce separate terms. Claude's MIT Python wrapper is one component, not a blanket description of everything it runs.
Keep model usage, runtime resources, persistent storage, observability and review operations as separate estimate lines. A free trace allowance is not a free agent allowance. A model gateway credit is not hosting credit. A seat price is not a complete deployment price. The card-level examples above show the consequences without assigning an invented total to an unspecified workload.
For the operator, the most expensive ambiguity may be an action whose outcome is unknown after a timeout. Save the intended operation, obtain the required approval, execute through a narrow application tool and retain the external receipt. An idempotency key lets a repeated request identify the same intended operation rather than silently create another one; its behavior depends on your application and the destination service.
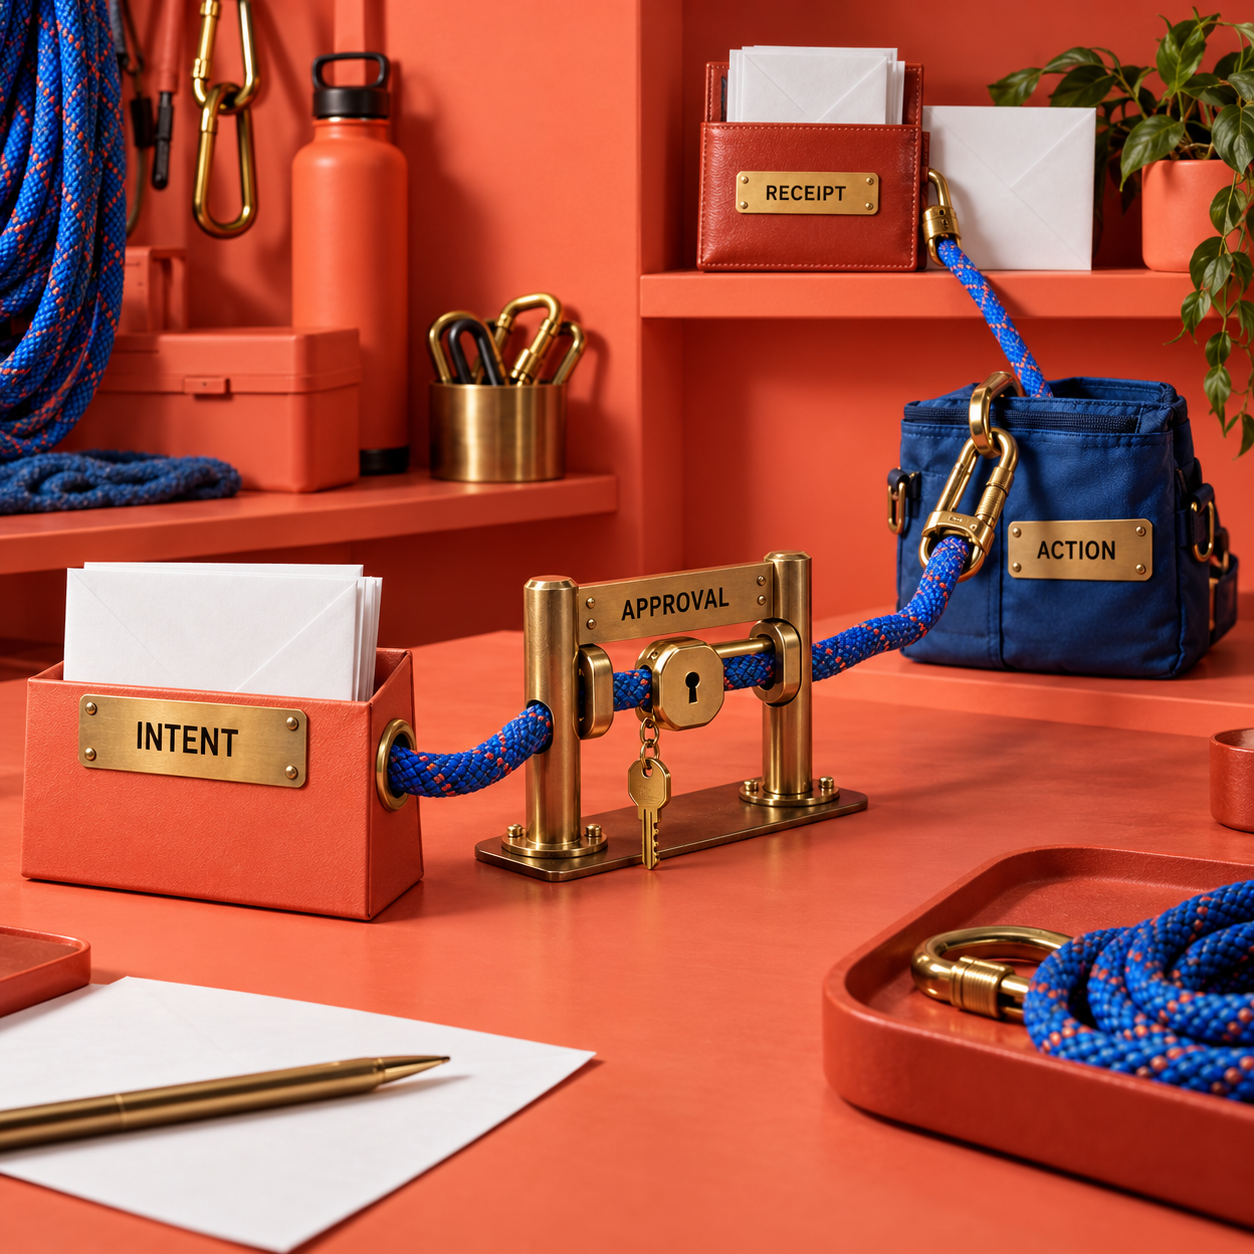
A checkpoint can restore the place in the workflow. It cannot, by itself, prove whether an external service committed a write immediately before the network failed. Design that receipt lookup with the tool, rather than make the model guess from its last message.
This is also the practical migration boundary. Keep business schemas, tool contracts and external-action records in application code you understand. Switching frameworks may still require changing execution state and persisted messages, but the core business operation should not have to be rediscovered from an agent transcript.
The ones to avoid
Avoid LangGraph for a simple classifier when the backend already calls the model, validates a result and stores it. A graph does not improve that job merely by making its diagram longer.
Avoid CrewAI for cosmetic personas. A researcher, strategist and writer need distinct responsibilities or evidence boundaries. Otherwise the role labels conceal a larger loop around the same task.
Avoid Claude Agent SDK for basic chat when you do not need its file, command or environment-based runtime. The direct client SDK is the smaller starting point for a custom provider loop.
Avoid Google ADK Tool Confirmation paired with an unsupported persistent session service. The current documented limitation applies to DatabaseSessionService and VertexAiSessionService. A central production approval requirement should not rest on an assumed combination.
Avoid treating Logfire or an AI Gateway as agent hosting. One observes work and the other routes model access. Neither choice answers who operates the application job and resumes it after failure.
AI agent development frameworks: choose this week
Choose the smallest candidate that can complete your actual recovery and review contract. The decision can be made with one representative business job, rather than a showcase of every possible agent feature.
Write the outcome and its boundaries
Name the completed result, the evidence required, the actions allowed and the actions that need review. Identify what the operator must know when a run stops halfway.
Shortlist by language and execution shape
Pick the framework for the durable workflow, collaborating roles, typed service or web-facing loop you are building. Keep a plain provider loop in the comparison if it meets the contract.
Exercise the interrupted paths
Restart the worker, return a tool error, reject an approval and deliver a duplicate event. Inspect the stored state and external receipts. A successful final answer alone does not establish recovery.
Measure the completed job's bill
Count all model calls and tool work, including retries and delegated activity. Add the exact hosted meters you used, then separate fixed platform fees from workload-dependent charges.
Assign operating ownership
Name the owner of storage, deployment, failed jobs, pending approvals and cost alerts. Commit to the candidate whose gaps you can operate this week.
Frequently asked questions
What are the 5 types of AI agents?
Five-type lists are educational taxonomies, and their definitions vary. They do not decide which framework can persist your workflow or enforce review. For this choice, specify execution shape, state, tool access and the permitted level of autonomy.
What are the big 4 AI agents?
There is no authoritative universal big four. LangGraph, CrewAI, OpenAI Agents SDK and Google ADK address different development jobs; treating them as a fixed quality leaderboard hides the production requirement that should determine your choice.
What are the frameworks for AI agents?
This comparison covers LangGraph, CrewAI, OpenAI Agents SDK, Claude Agent SDK, Mastra, Google ADK, Pydantic AI and Vercel AI SDK. They range from workflow runtimes to typed agent libraries and web-facing tool-loop SDKs, so start with the work you are building.
What are the 7 types of AI agents?
Seven-type lists also vary by source and are not a standard framework procurement model. A list of agent categories does not establish restart recovery, tool permission boundaries or compatibility between approval and storage features.
Is ChatGPT an agent or LLM?
ChatGPT is a user-facing product. An LLM is the underlying language model; an agent application combines a model with tools, state and a loop that can act toward a task. Those are different layers, and the product name does not select your application runtime.
What are the top 5 AI agents?
A task-specific shortlist is more useful than a universal top five. Start with LangGraph for stateful workflows, CrewAI for specialist teams, Mastra for TypeScript workflows, Pydantic AI for typed Python services and OpenAI Agents SDK for a compact application-owned loop. Other job shapes change the shortlist.
What is the newest AI agent?
There is no single useful answer across models, hosted products and development frameworks. For a build this week, read the current documentation for the capabilities you require and verify their deployment and storage compatibility. A newer release does not establish a better fit.
Is ChatGPT the best AI agent?
That depends on the user's task and required controls. It is a different question from choosing code to embed in your own product. A developer needs an answer about state ownership, tool execution, deployment, review and operating costs.
What are the top agentic AI frameworks in 2026?
The practical choices are task-dependent: LangGraph for explicit durable workflows; CrewAI for role-based collaboration; Mastra or Vercel AI SDK for different TypeScript application needs; Pydantic AI for typed Python; OpenAI Agents SDK for an application-owned runner; Claude Agent SDK for its file-and-command runtime; and Google ADK where the required combination is supported.
Use the AI Business Workflow Audit Checklist to scope the first agent job, its review boundary and its operating owner before committing to the framework.
- Last Updated
- Oct 7, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Codex Cloud
Set up a reusable Codex Cloud environment, keep coding tasks running with your laptop off, steer from your phone, and choose cloud or local CLI.Oct 7, 2026Build
GitHub Copilot Pricing (2026): The Seat Is the Floor, Credits Are the Bill
GitHub Copilot plans, AI Credits, model rates, and three worked monthly bills. Choose Pro, Pro+, Max, Business, or Enterprise with spending limits.Oct 6, 2026Build
GitHub Copilot CLI
Install GitHub Copilot CLI, sign in, fix tests and open a PR. Current GitHub plans, AI credits, models, permissions, MCP and instructions.Oct 6, 2026Build
Best Web Scraping Tools in 2026: Firecrawl, Bright Data, Browse AI, and Context.dev (Compared)
Choose web scraping tools by the job: agent-ready pages, no-code monitoring, or collection at scale. Eight tools with verified prices and billing units.Oct 6, 2026Build
Agent Memory Explained: Context, Sessions, Stores and Costs
Agent memory explained for builders: context, sessions, long-term stores, files and skills, provider costs, and fixes for stale facts and user leaks.Oct 5, 2026Build
Pinecone Pricing (2026): What 1M to 100M Vectors Cost
Pinecone pricing verified October 2026: free Starter, $20 Builder, paid minimums, and costs for 1M to 100M vectors at stated query volumes.Oct 5, 2026Build
Lovable Alternatives (2026): Emergent, Blink, Bolt, Replit and Base44
Compare Lovable alternatives by credit costs, backend depth and code export. Live pricing for Emergent, Blink, Bolt, Replit, Base44 and v0.Oct 5, 2026Build