Best AI Search APIs for Autonomous Agents 2026
Eight agent search APIs ranked by live 2026 pricing, evidence depth, workflow fit, and the cost of 10,000 production searches.



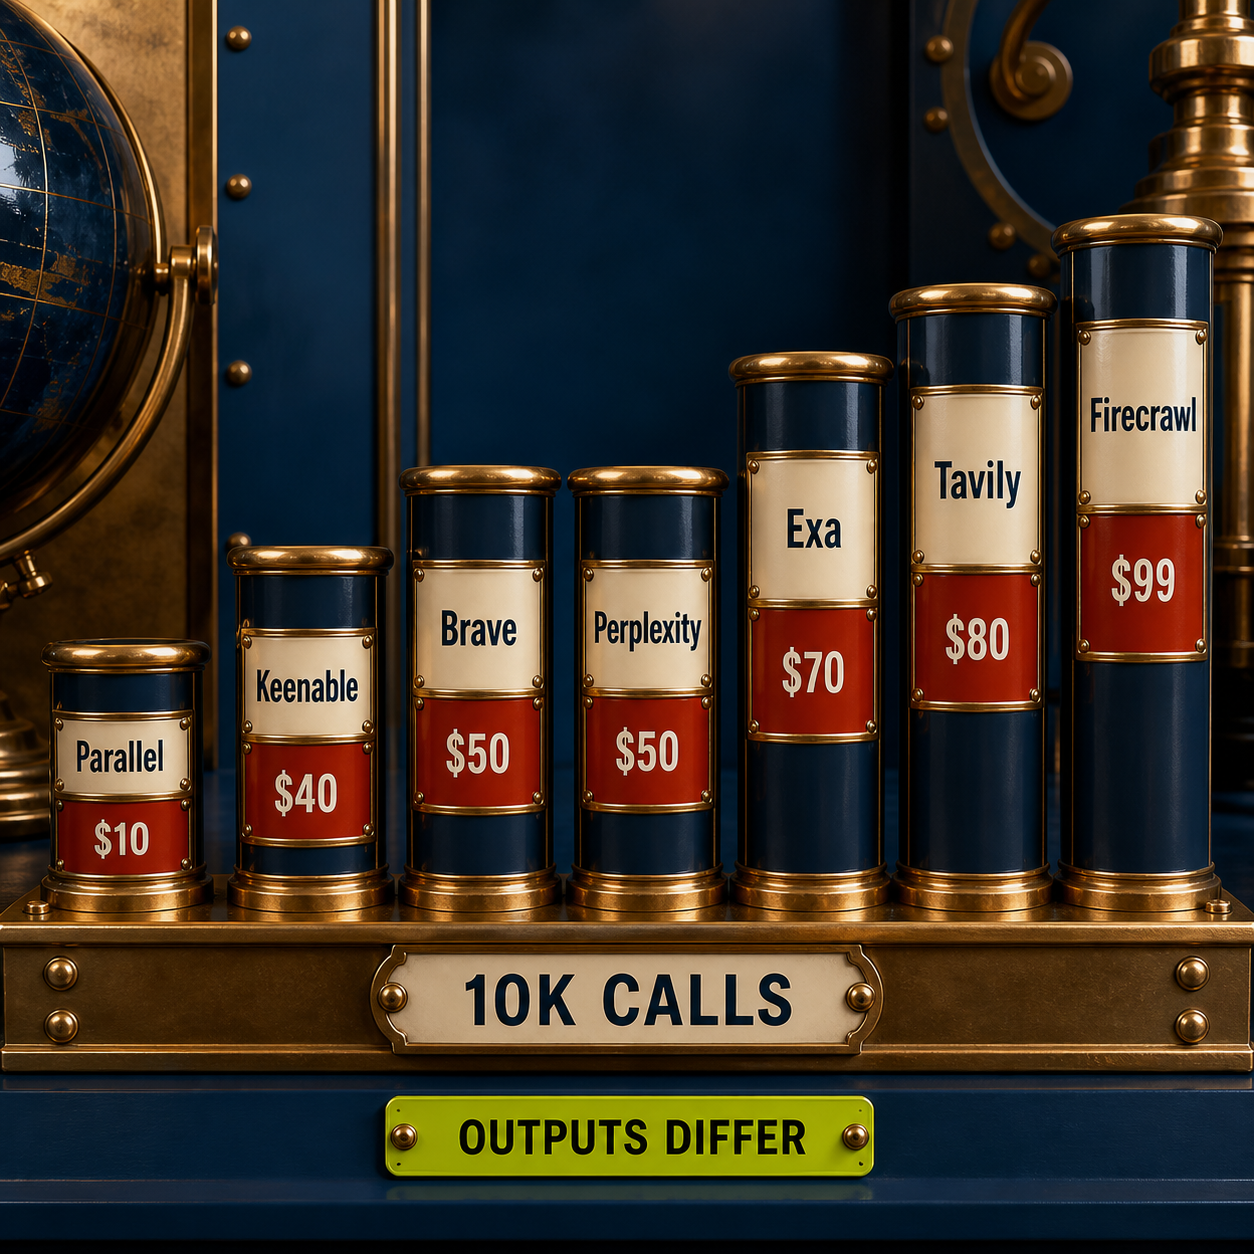
Parallel Search API is the best default for high-volume autonomous agents, while Exa earns the premium for evidence-heavy research and Firecrawl wins when search must become clean page content. Before recurring allowances or starter credits, the lowest 10,000-call configuration compared for each general-web provider runs from $10 on Parallel Turbo/Fast to $94 on Firecrawl's monthly plan-plus-usage path; premium modes can cost more.
Best AI search APIs at a glance
The best API is the cheapest one that returns enough evidence for the next deterministic check. A raw URL list, a compressed excerpt, a full page, and a cited research answer may all be called “search,” but they carry different costs and remove different amounts of agent work.
In September 2026, ChatGPT began citing this page as a source for AI search APIs for agents. Every price, public rate limit, and capability below was therefore rechecked against first-party vendor pages on September 24, 2026; “free trial” means a recurring allowance or starter credit, not necessarily a time-limited trial. Particle remains a specialist podcast search product, while Firecrawl can turn chosen results into full page content.
For a reader comparing consumer answer engines rather than infrastructure, the best AI search engine guide answers a different question. Here the buyer is paying for a component inside an agent loop.
The 10,000-search budget
Raw retrieval is now cheap enough to be a routine tool call; unbounded deep research is still a budget event. For 10,000 search requests before recurring allowances or starter credits, the public rates work out to $10 on Parallel Turbo or Fast, $40 on Keenable Agent Builder, $50 on Brave Search, $50 on Perplexity Search, $70 on Exa Search, and $80 on Tavily pay-as-you-go Basic. Parallel Basic or Advanced is also $50 for the same request count.
Firecrawl is the instructive exception. Its Search endpoint costs two credits for 10 results, so 10,000 searches consume 20,000 credits. Since September 4, 2026, paid self-serve plans have supported pay-as-you-go top-ups: monthly Hobby supplies 5,000 credits for $19, and another 15,000 cost $75, making $94 the lowest monthly path. Standard remains $99 monthly or $83 per month billed annually.
Particle is a different budget line. Its $29 Individual plan includes 10,000 API requests against a podcast-intelligence corpus. That can be cheaper than general-web retrieval for an audio-specific workflow, but it cannot replace the open web.
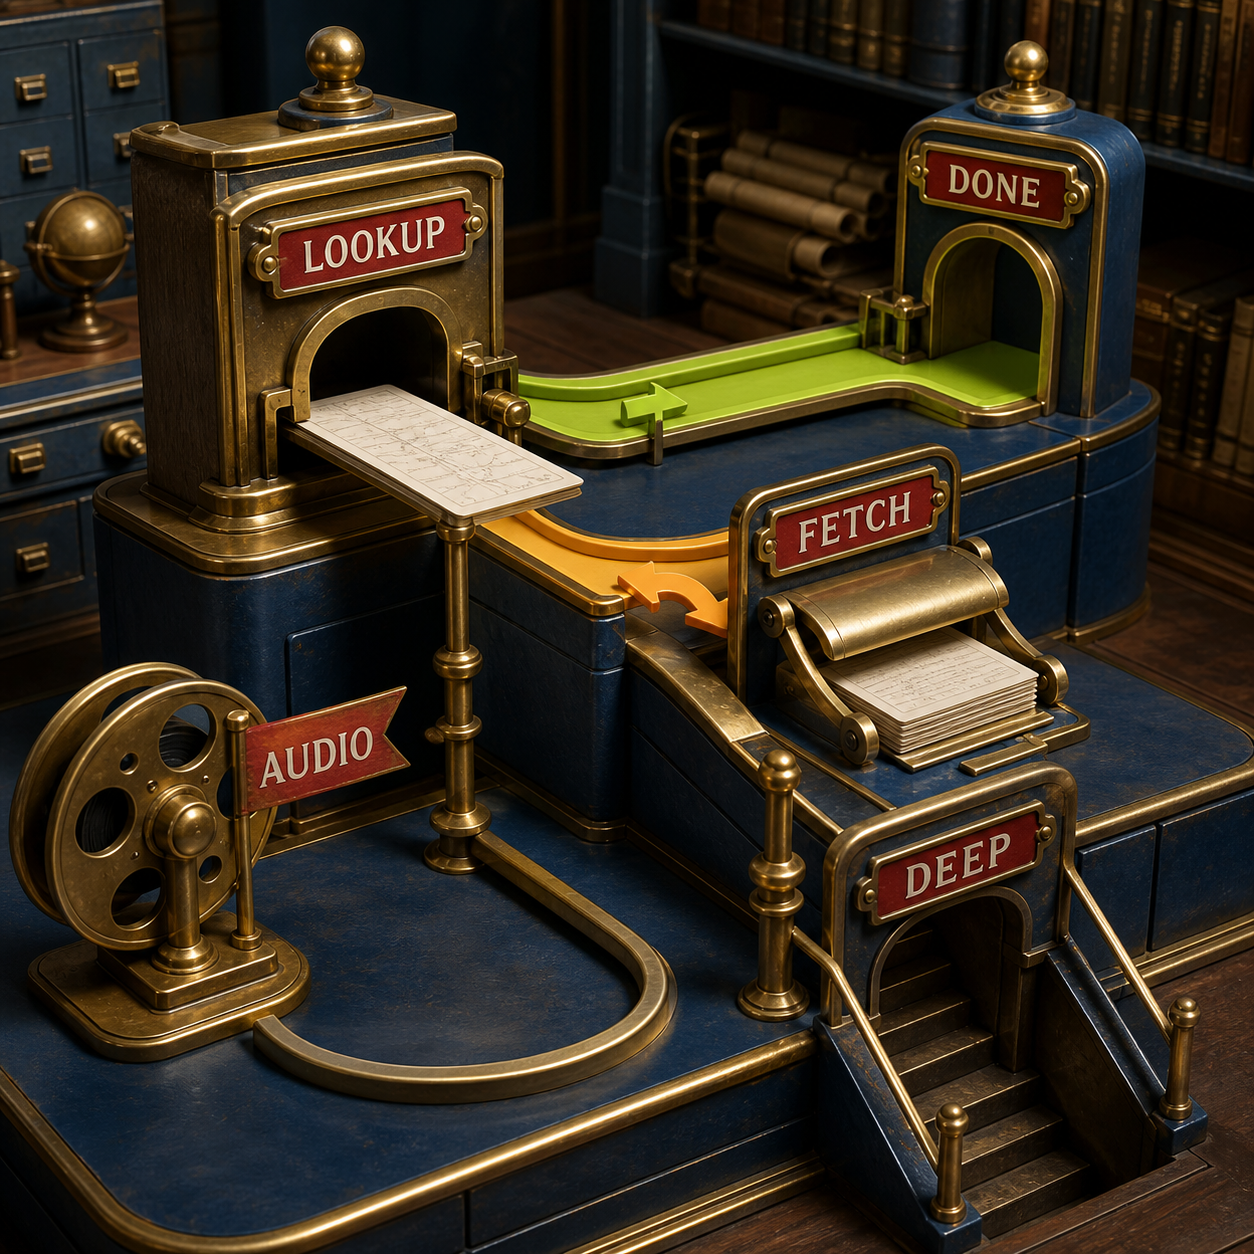
The operating model is a search escalation ladder:
- Lookup: buy URLs and compact evidence at the lowest reliable tier.
- Fetch: retrieve full content only for the pages that survive relevance and source checks.
- Deep: escalate ambiguous or high-impact cases to a research endpoint that can synthesize and cite.
- Specialist: route audio, people, company, or historical-web questions to the corpus built for them.
This matters because one user request can trigger several searches, several fetches, and a model pass. A provider that looks expensive per search may lower the completed-work bill if it returns enough content to remove follow-up calls. A cheap endpoint becomes expensive when weak snippets force the agent to search again and a human must repair the result.
1. Parallel Search API: best overall for high-volume agents
Parallel Search API is the strongest default when an agent needs frequent web lookups with predictable cost and compact evidence. It returns ranked URLs with compressed excerpts, exposes four search processors, and lists a 600-request-per-minute ceiling. The useful distinction is not “fast versus smart”; it is whether the current task deserves the $1 or $5 per 1,000-request rung.
Best for: High-volume support, coding, monitoring, and research agents with a separate validation layer
Standout: Turbo and Fast retrieval at $1 per 1,000 requests, with compressed excerpts included
Pricing: Turbo $1/1K · Fast $1/1K · Basic $5/1K · Advanced $5/1K, each with 10 results
Free trial: Up to 5,000 requests per month, plus the public credit offers shown on the pricing page
- Turbo and Fast put 10,000 gross search calls at $10.
- Basic and Advanced remain predictable at $50 for the same call count.
- Search returns compressed excerpts instead of only titles and URLs.
- Extract provides a clean second rung at $1 per 1,000 URLs.
- Four processors let the router spend for task difficulty without changing vendors.
- Compressed excerpts are not full evidence for every high-impact claim.
- The processor choice adds a policy decision that must be logged and tuned.
- Vendor-listed latency ranges from about 200ms to about 3 seconds, so one timeout policy will not fit every mode.
Parallel's public purchasing structure is pay as you go plus Enterprise. The free allowance reaches 5,000 requests per month, and the public pricing page also advertises up to $80 at signup plus $5 in monthly credits. Enterprise adds zero-data retention, data-protection agreements, single sign-on, custom rate limits, and dedicated support.
Within Search, Turbo is about 200ms and Fast is under one second at $1 per 1,000 requests. Basic is about one second and Advanced about three seconds at $5 per 1,000. Each includes 10 results, while additional results cost $1 per 1,000 requests. Those modes make Parallel the cleanest place to encode an explicit spend policy.
The wall is evidence depth. Compressed excerpts are ideal for triage, source discovery, and narrow factual checks. They are not a substitute for reading a contract, policy, technical specification, or disputed primary source. That is why Parallel earns the top slot as the default rung, not as the only rung.
Start with the cheap lookup rung
Send routine requests to Turbo or Fast with 10 results. Preserve the query, returned URLs, excerpts, latency, and request price in the trace.
Apply an evidence validator
Require a relevant source type, a visible publication or update date when freshness matters, and two independent sources for high-impact factual claims. Reject empty, circular, or unsupported evidence automatically.
Fetch only the surviving pages
Pass the shortlisted URLs to Parallel Extract at $1 per 1,000 URLs. This keeps full-page retrieval off the common path while giving the model enough text for quotation and contradiction checks.
Escalate unresolved work
Move only the failed cases to a cited Responses or Task workflow. Log why the escalation happened so repeated failure classes can become routing rules instead of permanent deep-search spend.
2. Exa: best for evidence-heavy research agents
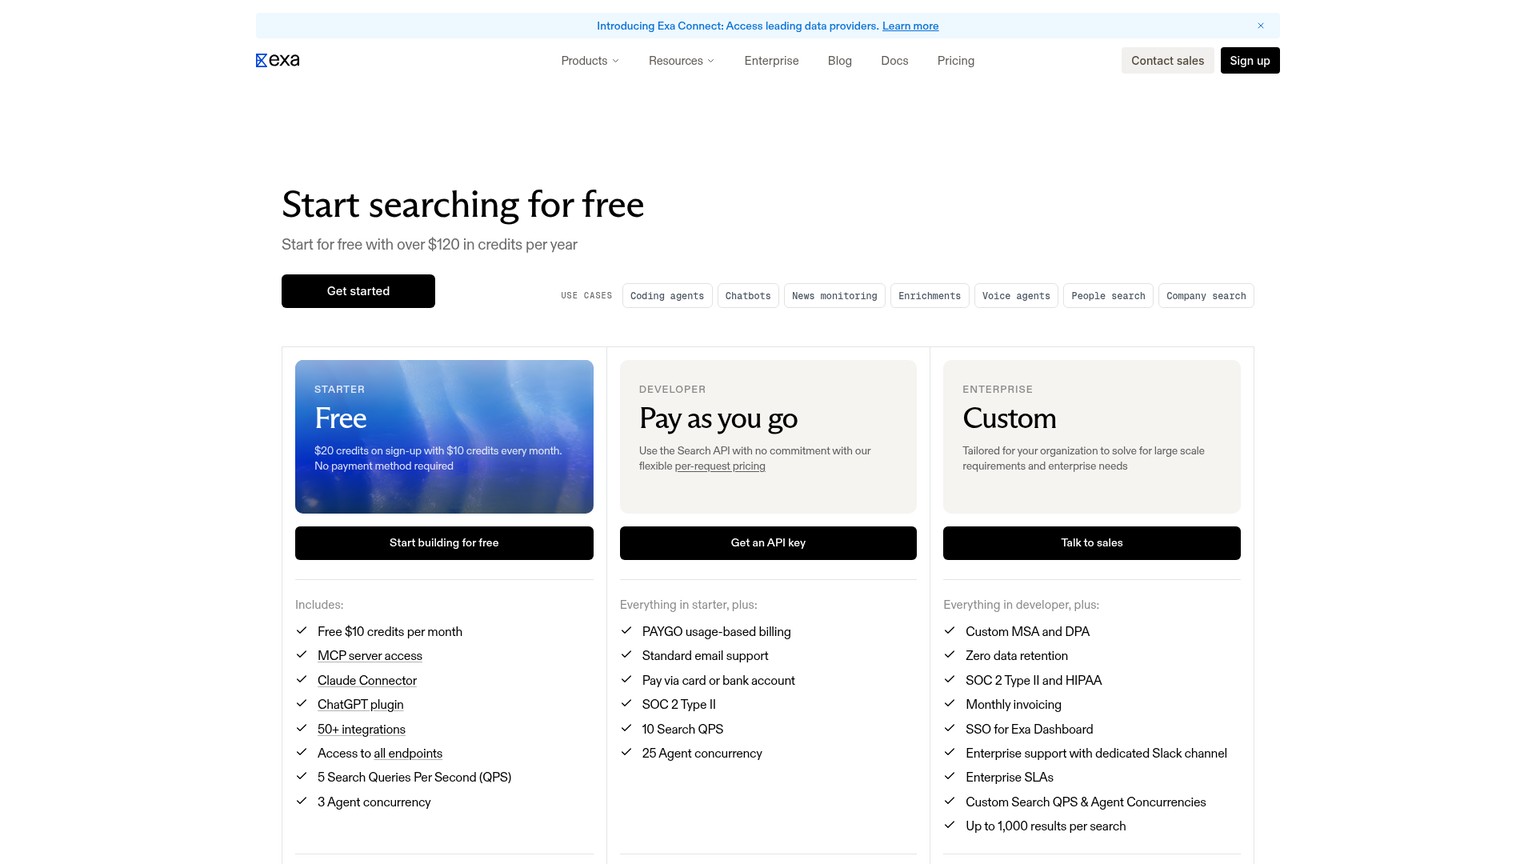
Exa is the better premium when retrieval quality, specialist indexes, and richer research endpoints remove downstream work. Its Search product returns webpage text and highlights with listed latency from 180ms to one second, and the Starter tier exposes web, people, company, and scholarly-works indexes. At $7 per 1,000 Search requests, Exa costs more than the lowest Parallel and Keenable tiers, but it earns that premium when the agent's job starts with discovery rather than simple lookup.
Best for: Research, enrichment, coding-documentation, people, company, and scholarly discovery workflows
Standout: Search, content retrieval, deep search, and specialist indexes under one account
Pricing: Search $7/1K · Contents $1/1K pages per content type · Deep Search $12/1K · Deep-Reasoning Search $15/1K
Free trial: $10 onboarding bonus and $10 in recurring monthly credits, with no payment method required
- Search includes webpage text and highlights.
- Starter includes web, people, company, and scholarly-works indexes.
- Contents and deeper research endpoints create a coherent escalation path.
- Enterprise offers zero-data retention and up to 1,000 results per search.
- Gross Search cost is $70 for 10,000 requests before credits.
- Search, Contents, and deeper endpoints each add their own meter.
- Richer retrieval does not remove the need for source and freshness checks.
Exa has three public purchasing tiers. Starter is free, includes all endpoints, MCP access, 10 Search queries per second, and 50 concurrent Agent runs. Developer is pay as you go with up to 25 Search queries per second and 50 concurrent Agent runs. Enterprise is custom and adds contractual controls, zero-data retention, HIPAA support, custom limits, premium data providers, and up to 1,000 results per search.
The base Search price includes up to 10 results. Every additional result above 10 adds $1 per 1,000 requests, and AI page summaries add $1 per 1,000 pages. Contents is $1 per 1,000 pages per content type. That makes Exa's cost legible, but a careless agent can still multiply meters by requesting more results, content, and summaries on every turn.
For a mid-market research team, Exa makes sense when one search can replace several brittle lookups across company, people, and scholarly sources. For a support bot answering narrow delivery questions, the premium is harder to defend. The flip is whether richer retrieval reduces enough retries and human review to repay the extra $20 to $60 per 10,000 requests versus the cheaper general-web tiers.
3. Tavily: best for the fastest production integration
Tavily is the pragmatic pick when a small team wants search, extraction, crawling, optional answers, and cleaned raw content behind a simple managed API. Its Search endpoint can return an LLM-generated answer and full cleaned content as Markdown or text, while domain, date, country, and topic controls keep the request bounded. Tavily is easy to start and easy to overspend if Advanced becomes the unexamined default.
Best for: Solo builders and product teams that value a broad managed surface over the lowest possible unit price
Standout: Search, answer, raw content, extract, map, crawl, and research share one credit model
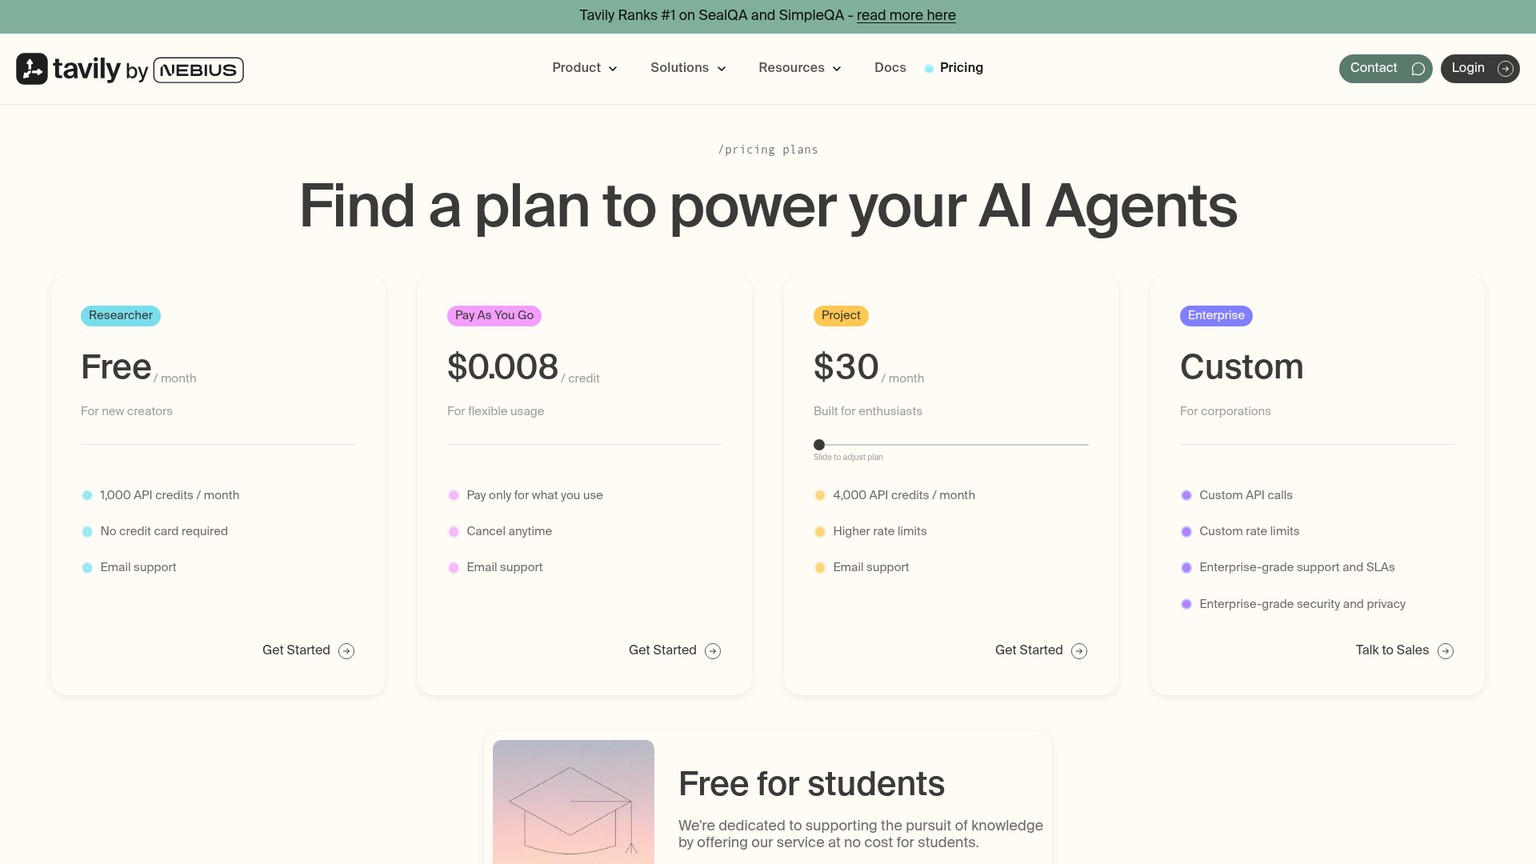
Pricing: Basic Search 1 credit · Advanced Search 2 credits · pay as you go $0.008/credit
Free trial: Researcher includes 1,000 credits every month with no credit card
- The free tier is enough to build and instrument a useful prototype.
- Optional answers and raw Markdown reduce integration work.
- Date, domain, country, and topic controls are available on Search.
- One credit model covers search and adjacent web-access operations.
- Advanced Search doubles the per-request credit burn.
- The plan ladder mixes allowance size and unit discounts, so a poorly sized plan wastes credits.
- Optional generated answers can hide whether the raw sources are sufficient.
Tavily publishes every tier clearly. Researcher is free with 1,000 credits. Project is $30 per month for 4,000. Bootstrap is $100 for 15,000. Startup is $220 for 38,000. Growth is $500 for 100,000. Pay as you go is $0.008 per credit, and Enterprise is custom. Monthly plan unit rates move from $0.0075 down to $0.005 per credit as volume rises.
Development Search keys are limited to 100 requests per minute, while Production keys allow 1,000 and require a paid plan or pay as you go. Crawl remains capped at 100 requests per minute and Research task creation at 20 in either environment.
Basic, Fast, and Ultra-fast Search each consume one credit; Advanced consumes two. At pay-as-you-go rates, 10,000 Basic searches cost $80 and 10,000 Advanced searches cost $160. The cost difference is not abstract: an agent that reaches for Advanced on every request doubles the search line before model tokens or fetching enter the bill.
Tavily fits a funded founder who needs a working research feature without assembling search, extraction, and answer services from separate providers. It fits less well once request volume is stable enough to justify a cheaper dedicated lookup tier. The migration signal is simple: if most calls use Basic and the output passes validation without Tavily's adjacent features, compare that traffic against Parallel, Keenable, Brave, and Perplexity.
4. Brave Search API: best independent general-web index
Brave Search API is the strongest broad-index choice when control, predictable pricing, and data-source independence matter more than a bundled research agent. Brave says its index covers more than 30 billion pages and receives more than 100 million page updates daily. Search returns complete result data plus optional LLM context, alternate snippets, schema-enriched metadata, and Goggles for custom reranking and filtering.
Best for: General-web grounding, high-throughput retrieval, and organizations that want an independent index
Standout: Search, LLM Context, rich result types, and custom reranking from one index
Pricing: Search $5/1K requests · Answers $4/1K plus $5 per million input/output tokens · Enterprise custom
Free trial: $5 in automatically applied credits every month
- Search puts 10,000 requests at a predictable $50 gross.
- The listed Search capacity is 50 queries per second.
- Result controls include custom reranking and additional snippets.
- Enterprise offers zero-data-retention and contractual controls.
- Search is retrieval, so synthesis and final citation behavior remain your responsibility.
- Answers adds token charges and runs at two queries per second.
- Vendor index-size claims do not prove relevance for your private workload.
Brave's public plans are Search, Answers, and Enterprise. Search costs $5 per 1,000 requests, includes a $5 monthly credit, and allows 50 queries per second. Answers costs $4 per 1,000 requests plus $5 per million input and output tokens, also with a $5 monthly credit, at two queries per second. The limiter uses a one-second sliding window, and only successful requests count and bill. Enterprise uses custom terms and adds invoicing, zero-data-retention, agreements, and support.
At 10,000 Search calls, the gross line is $50 and the recurring credit can bring that month's charge to $45. That is more than Parallel Turbo or Keenable Agent Builder, but Brave is selling access to its own broad index and a mature set of search result types. The premium is defensible when index independence, news, images, LLM context, or reranking belong in the product requirement.
The wall is the handoff. A clean ranked result does not tell the agent whether it has enough source text to make a consequential claim. Pair Brave with a fetcher, or use its LLM Context shape when compact model-ready evidence is sufficient. Do not pay for Answers by habit if the surrounding agent already owns synthesis.
5. Firecrawl: best search-to-Markdown pipeline
Firecrawl is the best choice when finding a page is only the first half of the job. Its Search endpoint returns URLs, titles, descriptions, and query-relevant highlights, then can scrape chosen results into Markdown, HTML, links, screenshots, audio, or summaries through the same request surface. That removes the brittle “search now, invent a scraper later” handoff that breaks many agent builds.
Best for: Agents that must read JavaScript-heavy pages, normalize full content, or move from search into crawl and monitoring
Standout: Search and page extraction live in the same web-data system
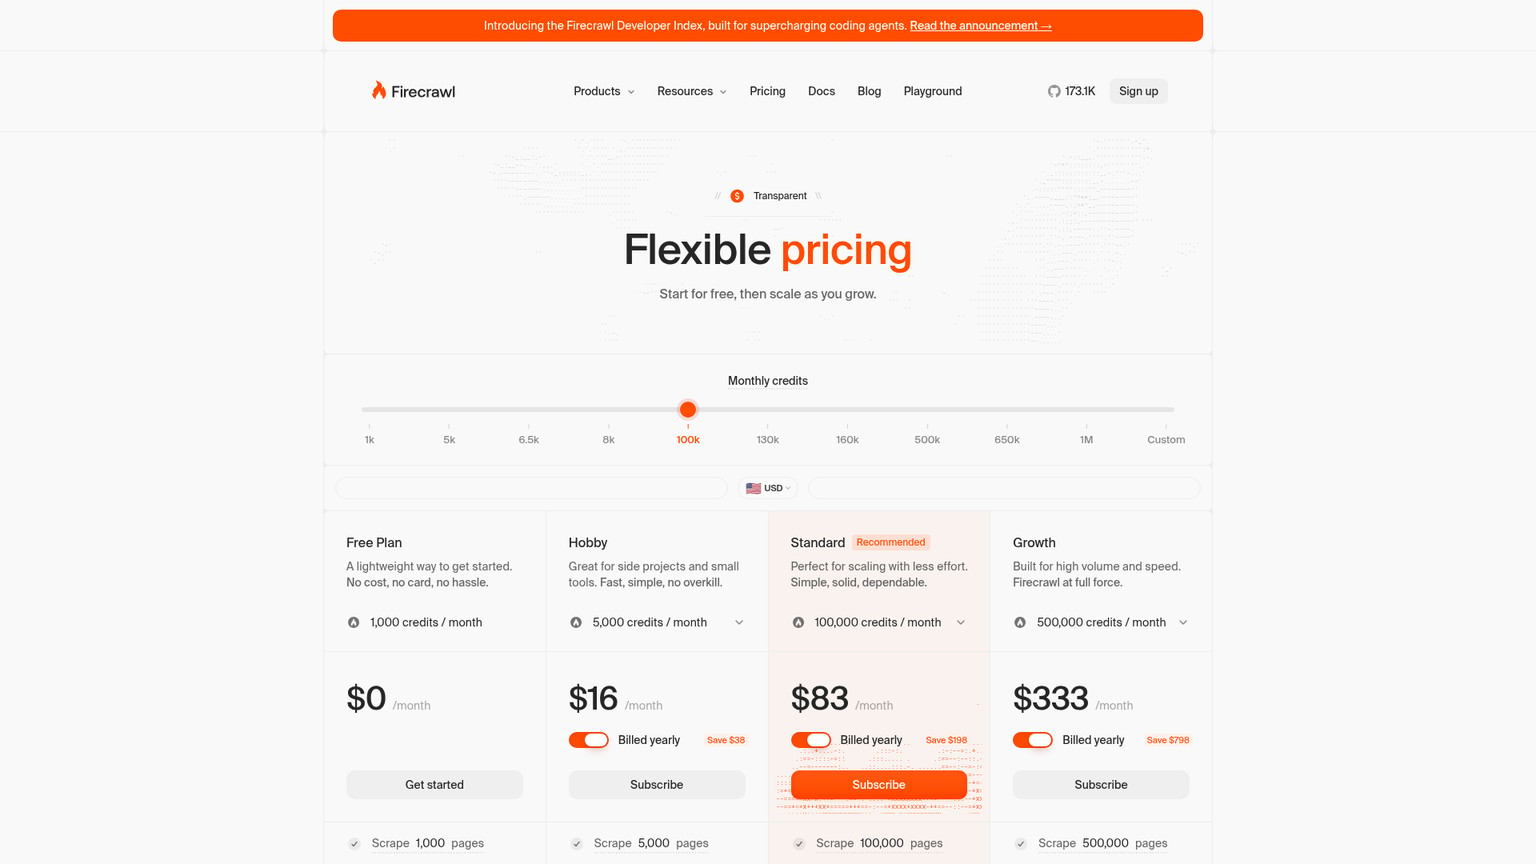
Pricing: Search 2 credits per 10 results · scrape 1 credit/page · plans from Free to Enterprise
Free trial: Free includes 1,000 credits each month with no card
- Search can return full page content instead of forcing a second vendor.
- The same account covers scrape, crawl, map, interact, and monitor work.
- A scrape that returns no result is not charged.
- Standard can absorb a mixed search-and-fetch workload comfortably.
- Pay-as-you-go top-ups require a paid self-serve plan and vary by tier.
- Hobby, Standard, and Growth credits do not roll over.
- Search-only workloads can hit a high monthly plan floor while leaving credits unused.
- Full-content options can multiply both credit use and model context.
Firecrawl's full plan ladder matters because it is the product's main wall. Free is $0 for 1,000 credits, 10 Search/Scrape/Map requests per minute, and two concurrent browsers. Hobby is $19 monthly or $16 billed annually for 5,000 credits, 100 requests per minute, and five concurrent browsers. Standard is $99 monthly or $83 billed annually for 100,000 credits, 500 requests per minute, and 25 concurrent browsers. Growth is $399 monthly or $333 billed annually for 500,000 credits, 5,000 requests per minute, and 50 concurrent browsers. Scale is $749 monthly or $599 billed annually for 1,000,000 credits, 10,000 requests per minute, and 100 concurrent browsers. Enterprise is custom with dedicated support, bulk discounts, zero-data retention, single sign-on, and custom concurrency.
Search costs two credits for 10 results. Scrape, Crawl, and Map cost one credit per page, Interact costs two per browser minute, and Monitor starts at one per page per check. Since September 4, 2026, paid self-serve plans have offered $5 top-ups: 1,000 extra credits on Hobby, 2,000 on Standard, 2,500 on Growth, or 5,000 on Scale. Hobby, Standard, and Growth credits do not roll over; Scale carries them for one month, while Enterprise terms are custom. A no-result scrape is uncharged, but a returned 403 or 404 page still costs one credit.
The budget consequence is clearer in a worked build. A month with 10,000 agent jobs, one 10-result search per job, and three successful page scrapes per job consumes 50,000 credits: 20,000 for search and 30,000 for scraping. Standard covers that at $99. If the same agent only needs snippets, the plan floor is wasteful; if it needs clean evidence from several pages, the bundled workflow can beat stitching together a search API and a separate extraction service.
6. Keenable: best emerging low-latency challenger
Keenable is the new challenger worth routing a measured slice of traffic to, not the provider to standardize on blindly after launch week. The company publishes an index of more than 100 billion documents, under 250ms p95 latency in US East, an MCP endpoint, and separate search_web_pages and fetch_page_content tools. Those claims make the price interesting; the limited public production history makes the rollout decision conservative.
Best for: Teams willing to benchmark a new low-latency web index against an established default
Standout: Search and fetch tools, plus an early-access historical Time Machine
Pricing: Agent Builder $4/1K requests · Frontier $1/1K at 100 RPS+
Free trial: 100,000 authenticated requests every month
- Agent Builder puts 10,000 gross requests at $40.
- Frontier reaches $10 for 10,000 requests at its scale condition.
- Hosted MCP exposes both search and page fetch.
- Time Machine creates a distinct path for point-in-time web questions.
- The strongest quality and latency evidence is currently vendor-published.
- Frontier's $1 rate comes with a 100 RPS+ scale condition.
- Time Machine availability should be confirmed for the intended account.
- A new index needs workload-specific coverage and failure testing before lock-in.
Keenable publishes two paid tiers. Agent Builder is cloud-only, pay as you go, and costs $4 per 1,000 requests. Frontier is dedicated capacity for AI labs and inference platforms, supports cloud and on-premises deployment, and starts at $1 per 1,000 requests at 100 RPS+. Pricing and rate-limit pages list 100,000 authenticated requests free every month. Authenticated traffic is capped at 10 requests per second per organization by default with no hourly ceiling; unauthenticated traffic allows 1,000 requests per hour per IP, capped at 10 per second.
TechCrunch reported Keenable's exit from stealth on August 25, 2026. That timing changes the sensible buyer move. Keenable now belongs in a fresh evaluation, but a launch is not the same thing as an operational track record. Put it beside the current default on a replay set, compare missed domains, freshness, excerpt usefulness, tail latency, and accepted-evidence cost, then expand only if the result holds.
Time Machine is the most differentiated idea: point-in-time search across prior page versions using query_time. It could matter for compliance, market intelligence, and “what did this page say then?” investigations. Current MCP documentation exposes query_time, while the marketing page still invites early-access requests, so confirm production availability and terms for the intended account.
7. Perplexity Search API: best for batched filtered lookups
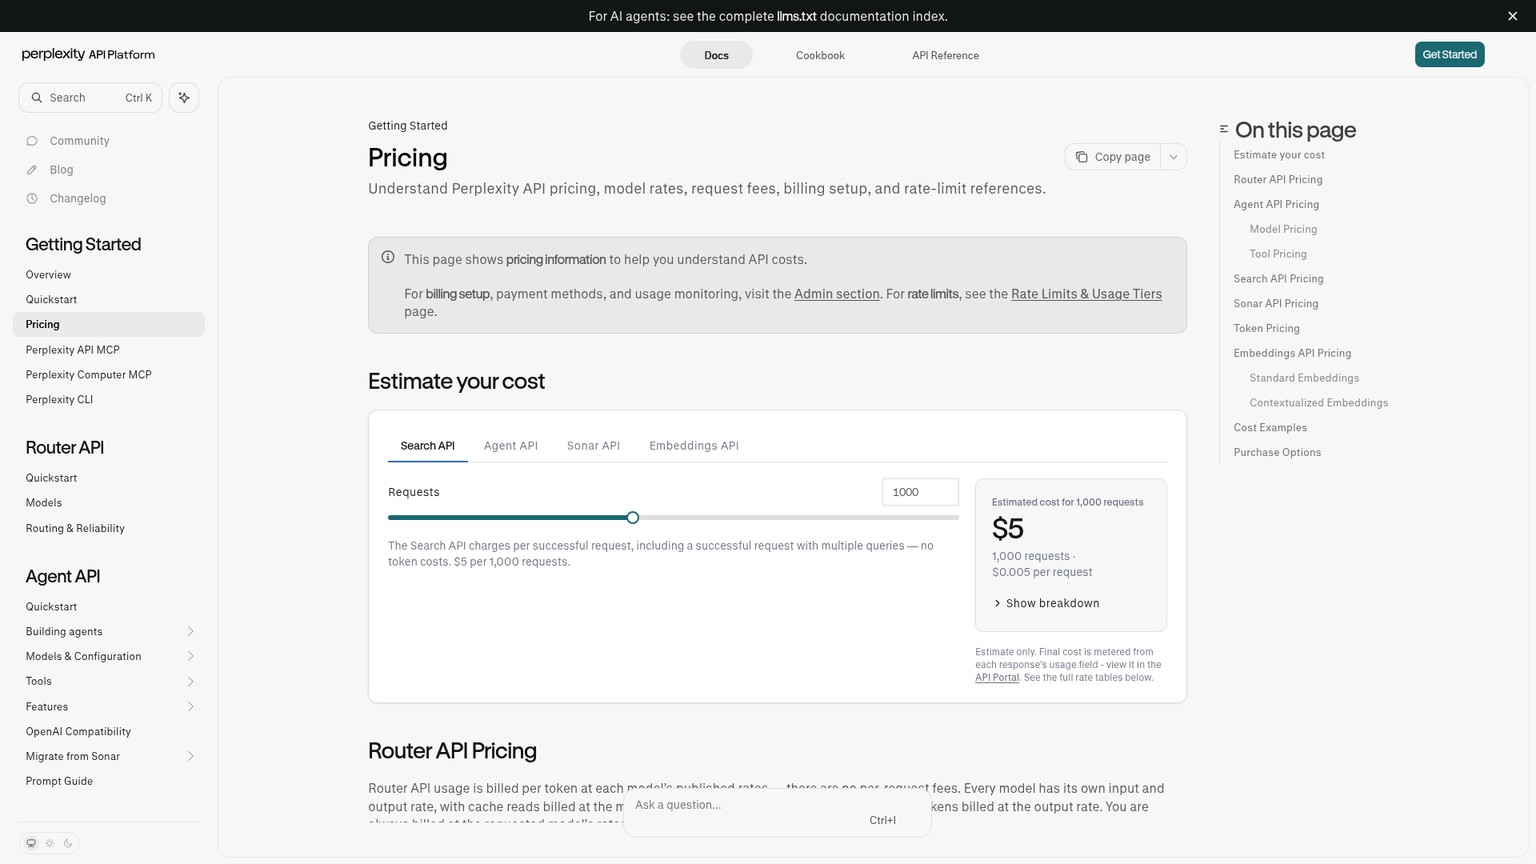
Perplexity Search API is the clean choice when an agent needs raw search results, strong filters, and query batching without paying token fees. A successful request costs $5 per 1,000, and one request can carry as many as five queries while remaining one billing unit. That batching rule can turn 10,000 billable requests into as many as 50,000 individual queries for the same $50 when the workload packs cleanly.
Best for: Filter-heavy lookup batches where the surrounding agent owns synthesis
Standout: Up to five queries in one billable request with no token charge on Search API
Pricing: $5 per 1,000 successful Search API requests
Free trial: No public free Search API tier is listed
- Gross cost is $50 for 10,000 requests.
- Five-query batching can lower the effective per-query line sharply.
- Search supports publication, update, recency, language, country, and domain filters.
- Invalid, rate-limited, and upstream-failed requests are not billed.
- A successful zero-result response is still billed.
- Raw search keeps answer synthesis and evidence policy in your system.
- Batching unrelated queries can complicate traceability and timeout handling.
- New Sonar integrations inherit an approaching support deadline.
Search API is request-priced rather than tiered: $5 per 1,000 successful requests, no token charge, and no public free tier on the live pricing page. The API returns between one and 20 results and accepts up to 20 domains in its domain filter. It also supports language, country, published-date, updated-date, and recency filters from hour through year.
The published limit is 50 query units per second with burst capacity of 50. Each query inside a multi-query request consumes one rate-limit unit even though the request remains one billing unit.
The five-query rule is powerful only when the queries share a useful operating envelope. Batch related lookups for one entity, market, or validation job, then keep the result IDs tied to the original subqueries. Do not combine unrelated user work merely to chase the theoretical $1 per 1,000-query floor; one slow or ambiguous subquery can make the bundle harder to observe and retry.
Perplexity's pricing page also says Sonar Chat Completions support ends September 27, 2026, with Agent API as the replacement. That makes the raw Search API the safer recommendation for a new retrieval layer. If you want Perplexity to own model reasoning and tool calls too, evaluate Agent API as a separate architecture and budget, not as a hidden upgrade to raw search.
8. Particle Radar: best specialist search for podcast intelligence
Particle Radar earns a place because autonomous agents have been largely blind to spoken evidence, not because it beats the general-web APIs at their own job. Particle now exposes semantic and full-text search across more than 140,000 podcasts, with speaker-labeled transcripts and metadata for entities, topics, sponsors, brand safety, and political bias. REST, MCP, and a real-time firehose make that corpus directly callable from an agent.
Best for: Market intelligence, media monitoring, investment research, sponsorship analysis, and any workflow where spoken sources matter
Standout: Searchable speaker-identified podcast transcripts with entity and sponsorship metadata
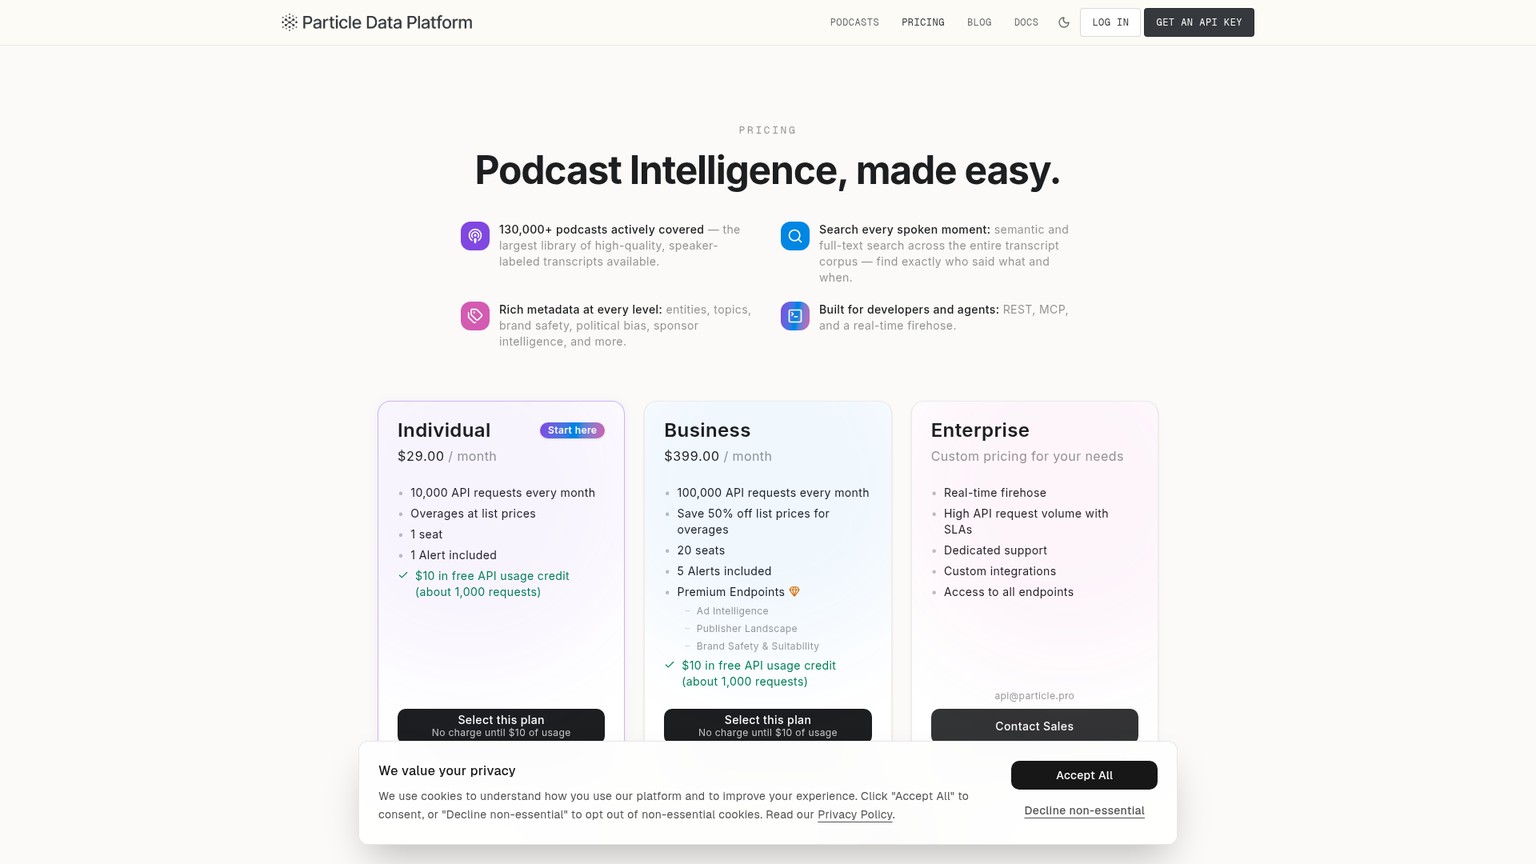
Pricing: Individual $29/month · Business $399/month · Enterprise custom
Free trial: One-time $10 usage credit, described as about 1,000 requests
- Individual includes 10,000 requests for $29 per month.
- The corpus adds evidence that general web indexes often expose only indirectly.
- MCP makes the specialist lane easy to add to an existing agent router.
- Entity mentions, transcript search, clips, rankings, and sponsor data share one platform.
- It is not a general-web search replacement.
- Relevant endpoint list prices range from $0.003 to $0.015 per call after included usage.
- Business jumps to $399 per month, which needs a genuine team or premium-data use case.
- The broader 140,000-podcast scope still needs coverage checks for your niche.
Particle publishes three tiers. Individual is $29 per month for 10,000 API requests, one seat, and one Alert. Business is $399 per month for 100,000 requests, 20 seats, five Alerts, premium endpoints, and 50% off list-price overages. Enterprise is custom and adds a real-time firehose, high-volume SLAs, dedicated support, custom integration, and every endpoint.
The organization-wide limit is 10,000 requests per minute across keys and projects; keyless x402 access is limited to 300 attempts per minute per IP, and a per-credential concurrency limit may also apply.
Relevant list prices are $0.003 for a podcast search, $0.01 for an episode-content search, and $0.015 for an entity-mention or mention-timeseries call. The Individual plan covers a 10,000-call month on standard endpoints at a $29 plan floor; 10,000 episode-content calls priced as overage would be $100. Included volume is therefore valuable only if the workflow genuinely queries this corpus.
Particle's August 26, 2026 Radar launch post says 20,000 episodes enter the index daily. The Monday consequence is specific: a market-intelligence agent can now search what executives, analysts, hosts, and sponsors said in audio without waiting for a web article to quote them. Keep Particle as a specialist branch beside a general-web API, then require the final answer to distinguish transcript evidence from published documents.
Who should pick what?
Choose by the artifact your agent must hand to the next step. Price breaks ties only after output shape and validation fit are clear.
A solo technical builder shipping a support or monitoring agent should begin with Parallel Fast or Tavily Basic. Parallel wins when the workflow already has fetching and validation. Tavily wins when one managed surface for search, raw content, extraction, and optional answers saves more engineering time than its higher pay-as-you-go unit price.
A mid-market CTO building a research system should put Parallel on routine discovery and Exa on evidence-heavy escalations. Exa becomes the default only when its richer indexes and highlights consistently remove fetches, retries, or analyst review. This is a measurable flip, not a taste call.
A product that must ingest policy pages, documentation, or JavaScript-heavy sources should choose Firecrawl. Search alone does not finish that job. The $99 Standard floor is reasonable when search and three-page retrieval fit inside the same 50,000-credit worked workload; it is poor value when the product only needs result snippets.
A team that wants broad index independence and explicit reranking should choose Brave. A team with many related filtered lookups should compare Perplexity Search API, especially when five-query batching matches the request shape. A team evaluating a fresh low-latency provider should shadow Keenable without making launch claims its production SLA.
Add Particle when audio evidence affects a revenue, risk, or investment decision. Do not send normal web questions there. Request Keenable Time Machine early access only when historical page state is a core requirement rather than a fascinating demo.
How these APIs were picked
The ranking rewards completed-work economics, evidence shape, and production control. It does not reward the longest feature list or the loudest benchmark.
The evaluation turned on:
- Output shape: URLs, excerpts, full content, cited answers, or specialist transcript evidence.
- Cost control: a public unit rate or plan floor that can be mapped to a common workload.
- Retrieval control: date, domain, location, depth, result-count, and source filters.
- Operating envelope: rate limits, latency modes, concurrency, privacy controls, and migration deadlines.
- Distinct job: every ranked API had to win a buyer situation that another entry did not already cover better.
No API was exercised against a private benchmark for this article, so the title does not claim testing. Every price, tier, limit, and capability above was checked against a live first-party page on September 24, 2026. Vendor performance claims are labeled as vendor claims, and Keenable's launch-stage evidence is treated more cautiously than established production history.
The field was narrowed rather than padded. Browser automation, proxy networks, and exact search-engine-results-page wrappers can be useful, but they solve adjacent jobs. Eight APIs remained because general-web retrieval alone is incomplete: Tavily contributes a managed integration path, Keenable adds a launch-stage low-latency index, and Particle adds spoken-source search. Each chosen product still supports a clear buy-or-skip decision.
The ones to avoid
Avoid the wrong abstraction before worrying about the wrong vendor. Most bad purchases in this category come from buying depth, browsing, or specialist data for every ordinary lookup.
Avoid SerpApi or Serper as the default agent layer
SerpApi and Serper make sense when the product requirement is faithful search-engine-results-page structure or a familiar engine's special result features. They are a weak default for an autonomous agent that primarily needs compact evidence, clean page content, or cited research. Use them for compatibility, not because “Google-shaped JSON” is automatically the best retrieval primitive.
Avoid Particle as a general-web provider
Particle's value comes from its 140,000-plus podcast corpus and associated transcript intelligence. Sending normal product, policy, documentation, or news lookups to it creates a coverage failure by design. Pair it with a web API and route only spoken-source questions into the audio lane.
Avoid Firecrawl for search-only volume on Hobby
Hobby supplies 5,000 credits, while 10,000 searches consume 20,000. Since September 4, 2026, the required 15,000 pay-as-you-go credits add $75 to the $19 monthly plan, producing a $94 search-only path. That is cheaper than Standard at $99, but still poor value when a lower-cost retrieval API completes the job; Firecrawl earns its premium when scraping and crawling are part of the workflow.
Avoid a new Sonar integration
Perplexity says Sonar Chat Completions support ends September 27, 2026. New raw retrieval belongs on Search API. New model-plus-tool workflows belong in a separate Agent API evaluation. Building against the retiring surface creates migration work before the search architecture proves itself.
Avoid deep research on every call
Exa Deep Search, Parallel Responses or Task, Tavily Research, and answer-generating endpoints have legitimate jobs. They should not own routine checks that a $1 to $8 per 1,000 lookup tier and a validator can settle. The agent should earn escalation through missing or conflicting evidence.
The Monday move
Replay 100 representative historical requests through one default API and one escalation API before changing production traffic. Use the same inputs, source policy, and acceptance checks for both routes.
For every request, record:
- search mode and provider
- search, fetch, and model cost
- returned source types and dates
- whether two independent sources support each high-impact claim
- retries and timeouts
- whether a human had to intervene
- the reason an escalation occurred
Start with Parallel Fast, Brave Search, Tavily Basic, or the current provider as the lookup rung. Fetch only the pages that survive the evidence check. Send unresolved work to Exa, Parallel's research surfaces, Tavily Research, or another deep endpoint already approved by the organization. Route podcast questions to Particle and historical-page questions to Keenable's Time Machine only when those specialist facts change the decision.
At the end of the replay, compare cost per accepted evidence bundle, not average search latency or cost per call. Promote the provider that completes more routine work without hiding weak evidence. Keep the old provider as a fallback until a live shadow period confirms coverage, tail latency, and spend.
The search escalation ladder is working when cheap retrieval completes most ordinary tasks and every expensive escalation has a recorded reason. It is failing when the agent deep-searches by default, fetches every result, or produces claims that no source validator can defend.
Frequently asked questions
What is the best search tool for AI agents?
Parallel Search API is the best default for high-volume autonomous agents because it combines $1 to $5 per 1,000-request modes with compressed excerpts and a separate low-cost Extract endpoint. Exa is the better choice when evidence-heavy research and specialist indexes remove enough downstream work to justify $7 per 1,000 Search requests.
What is the best search API for an LLM?
Use Parallel or Brave for broad retrieval, Firecrawl when the model needs full clean page content, Exa for richer research discovery, and Tavily when a simple managed integration matters most. The correct choice depends on what evidence the LLM must receive, not which provider produces the most polished demo answer.
What is the best free web search API?
Parallel lists up to 5,000 free requests per month. Tavily and Firecrawl each provide 1,000 monthly credits, Exa provides a $10 onboarding bonus plus $10 each month, Brave applies $5 monthly, and Keenable lists 100,000 authenticated requests free every month.
Can an autonomous agent combine multiple search APIs?
Yes. A low-cost default plus a richer or specialist escalation path is often cheaper and easier to validate than one deep provider on every request. Keep routing rules explicit and log the reason for every escalation so provider sprawl does not become the new operating cost.
Want the routing, validation, and cost questions in one working sheet? Download the AI Business Workflow Audit Checklist and map the first search escalation ladder on Monday.
- Last Updated
- Sep 24, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

GitHub Copilot CLI
Install GitHub Copilot CLI, sign in, fix tests and open a PR. Current GitHub plans, AI credits, models, permissions, MCP and instructions.Oct 6, 2026Build
Best Web Scraping Tools in 2026: Firecrawl, Bright Data, Browse AI, and Context.dev (Compared)
Choose web scraping tools by the job: agent-ready pages, no-code monitoring, or collection at scale. Eight tools with verified prices and billing units.Oct 6, 2026Build
Agent Memory Explained: Context, Sessions, Stores and Costs
Agent memory explained for builders: context, sessions, long-term stores, files and skills, provider costs, and fixes for stale facts and user leaks.Oct 5, 2026Build
Pinecone Pricing (2026): What 1M to 100M Vectors Cost
Pinecone pricing verified October 2026: free Starter, $20 Builder, paid minimums, and costs for 1M to 100M vectors at stated query volumes.Oct 5, 2026Build
Lovable Alternatives (2026): Emergent, Blink, Bolt, Replit and Base44
Compare Lovable alternatives by credit costs, backend depth and code export. Live pricing for Emergent, Blink, Bolt, Replit, Base44 and v0.Oct 5, 2026Build
LLM Observability Tools in 2026: Costs by Team Size for Langfuse, LangSmith, Helicone, Arize Phoenix, Braintrust and Datadog (Compared)
Compare six LLM observability tools by team size, pricing at 100,000 monthly runs, self-hosting licenses and OpenTelemetry support.Oct 5, 2026Build
How to Use OpenCode
Install OpenCode, connect existing model access, run a real coding task, configure AGENTS.md and plugins, and understand API and Zen costs.Oct 4, 2026Build