Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.


Claude Opus 5.5 is the upgrade to test for most Opus 5 workloads: 1 million uncached input tokens plus 100,000 billed output tokens costs $6.00 instead of $7.50. The Claude Opus 5.5 vs Opus 5 decision still turns on five integration changes, because the cheaper model is not a drop-in replacement for every agent.
Claude Opus 5.5 vs Opus 5: Which One Should You Pick?
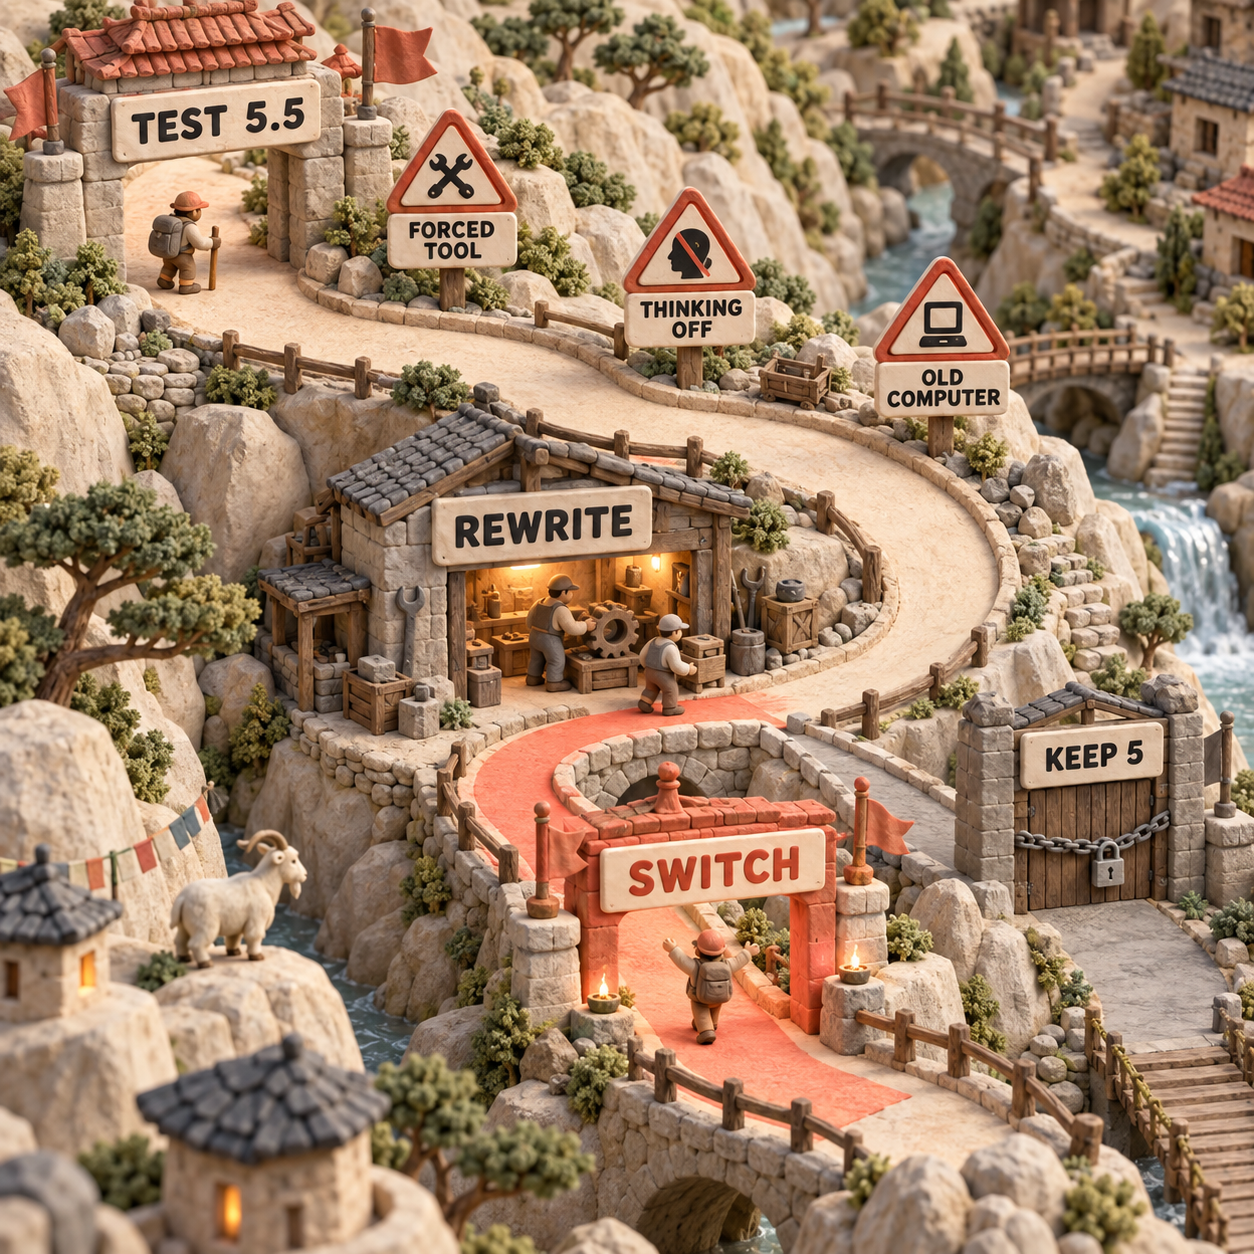
Pick Claude Opus 5.5 for new premium work and test it as the replacement for most existing Opus 5 routes. Keep Opus 5 temporarily when your integration disables thinking, forces a named tool, or still uses the earlier computer tool on the Claude API or Google Cloud. Those are code-path decisions, not small differences in model taste.
Claude Opus 5.5 wins for a funded founder whose coding agent spends enough to make cache reads and retries material. A mid-market CTO should also prefer it, but only after the platform team clears the request-shape changes. A senior operator running bounded extraction should first ask whether Claude Sonnet 5 already clears the acceptance bar at a lower rate. A solo technical builder should move difficult repository work to 5.5 and keep cheaper work off Opus entirely.
The decision flips back to Opus 5 when migration work is more expensive than the expected saving and the old route is already reliable. That is a temporary compatibility win, not a reason to start new development on the older model.
Anthropic released Opus 5.5 on September 22, 2026. Its own model guide now tells an undecided developer to start with Opus 5.5 for most workloads, while the older model remains useful as a rollback target during migration.
Opus 5.5 Cost vs Opus 5
Claude Opus 5.5 is cheaper at every identical standard token count. Prices verified against Anthropic's live pricing documentation on September 23, 2026 are $4 per million input tokens and $20 per million output tokens for 5.5, against $5 and $25 for Opus 5. That is a 20% list-rate cut. A cache read is reused prompt content; its rate falls from $0.50 to $0.20 per million, a 60% cut.
At a smaller unit, 1,000 uncached input tokens cost $0.004 on 5.5 versus $0.005 on 5. Output costs $0.020 versus $0.025 per 1,000 tokens. Neither model has a seat-month or fixed per-image crossover in this API comparison. The bill follows tokens, so 5.5 never becomes more expensive when the billed token shape stays identical.
The uncached worksheet is direct: Opus 5 costs $5 for input plus $2.50 for output. Opus 5.5 costs $4 plus $2. The warmed-cache worksheet charges 100,000 uncached input tokens, 900,000 cache-read tokens, and 100,000 output tokens. It deliberately excludes cache creation, tools, retries, batch discounts, fast mode, and data-residency multipliers.
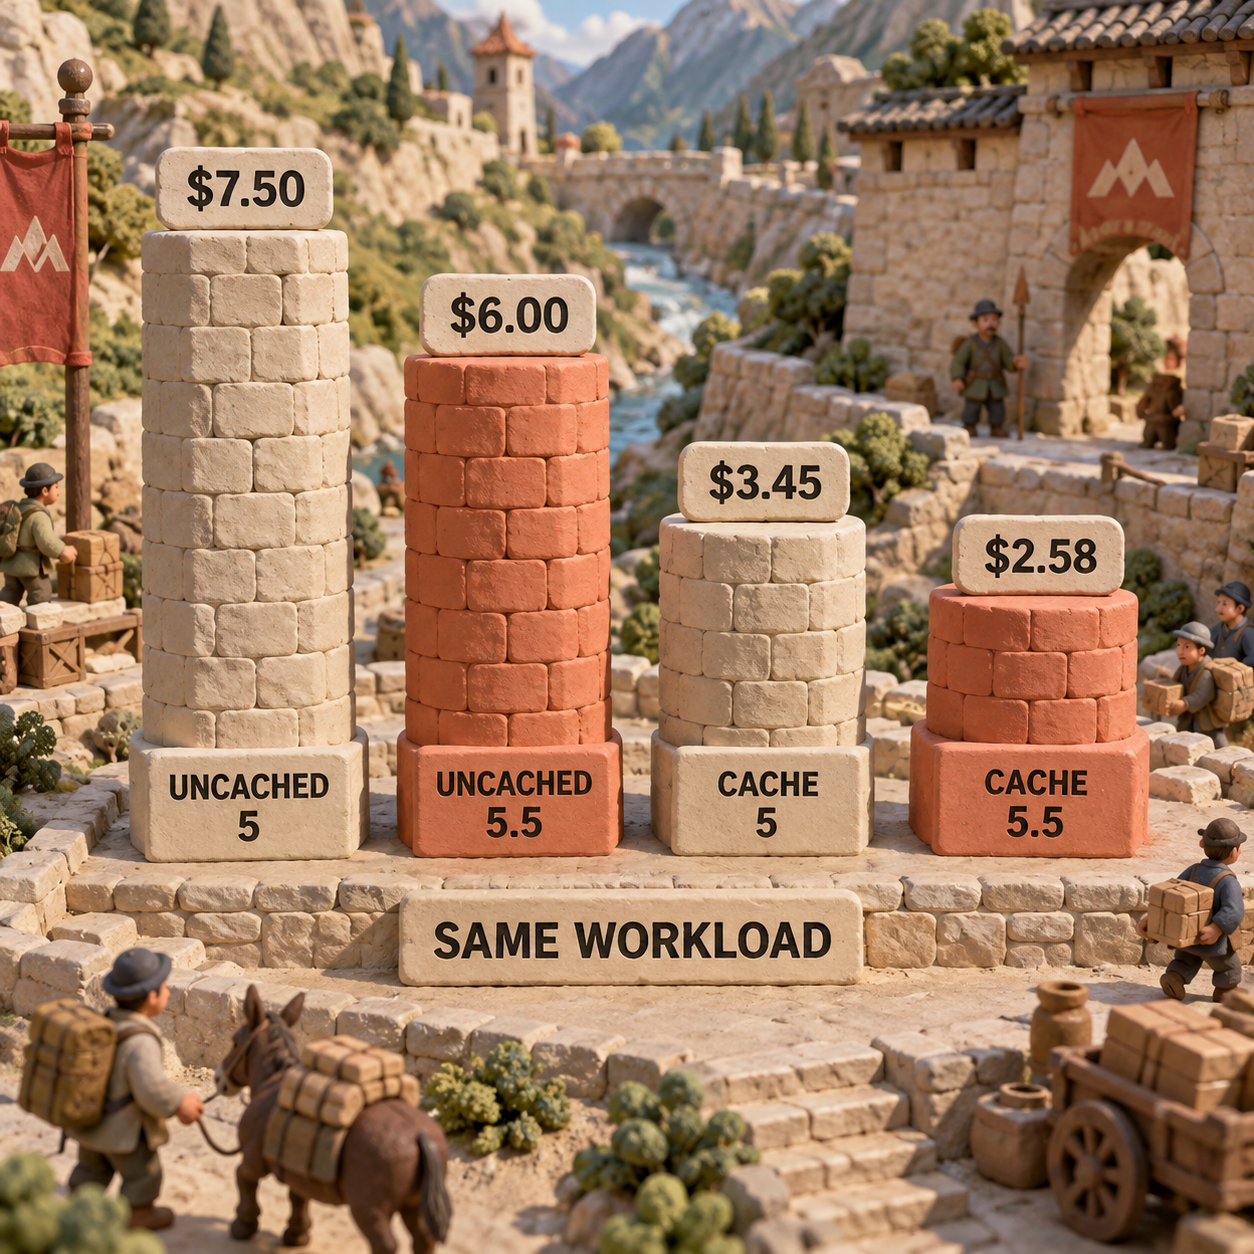
Anthropic's separate claim that 5.5 costs 40% less on typical workloads is a vendor measurement, not another list-price calculation. Anthropic says the model combines lower rates with fewer tokens per task at default settings. Keep that claim separate from the fixed-token worksheets rather than applying a 40% discount to every estimate.
The useful crossover is token behavior. On the uncached worksheet, 5.5 could produce 175,000 output tokens, 75% more than the 100,000-token Opus 5 baseline, before its bill reached the same $7.50. In the warmed-cache case, it could reach 143,500 output tokens, 43.5% more, before matching $3.45. If a migration crosses those limits without improving acceptance, the lower rate has stopped helping.
Winner on price: Claude Opus 5.5. Its rate advantage is unconditional at equal usage. Its workload advantage still has to survive measured token use and retries.
Opus 5.5 Coding: What the Published Evidence Supports
Claude Opus 5.5 has the stronger documented coding case, but no model trial was run for this comparison. No execution credential was available, so there is no claim here about a repository repair, extraction task, returned model ID, latency, or validation result produced in this run.
Claude Opus 5.5 vs Opus 5 Review: The Evidence Boundary
On Anthropic's launch evaluations, Opus 5.5 at its default medium effort scored 52.5% on CursorBench 4.0, a test of ambiguous multi-file coding tasks drawn from Cursor sessions, while Opus 5 at max scored 46.6%. Anthropic also reports output generation more than 30% faster. Those figures are useful reasons to evaluate, but the effort settings differ and the vendor ran the comparison.
AutomationBench offers a separately measured signal. Anthropic's launch footnote says Zapier ran and reported the benchmark: Opus 5.5 scored 40.0% and Opus 5 scored 26.9%. The test concerns connected-app workflows, not every codebase or business process, and it does not tell you how your permission model, tools, or validator will behave.
For a coding agent, define acceptance before the run: tests pass, the diff stays inside scope, and review finds no corrective work. For extraction, require an exact schema, source-grounded values, and a deterministic validator. Then record input tokens, cache tokens, output tokens, latency, tool calls, retries, and failures. A higher benchmark score does not pay the bill if your harness creates more rejected work.
Winner on documented coding evidence: Claude Opus 5.5. The confidence level is strong enough to justify a controlled evaluation, not a blind production flip.
Opus 5.5 API Changes That Can Break a Drop-In Switch
Five integration checks matter more than the model-string edit. Anthropic's current Opus 5.5 change documentation names four request-breaking changes and one response-shape change that can fail silently at the interface.
1. Thinking cannot be disabled
Opus 5.5 always uses adaptive thinking. A request with thinking:{"type":"disabled"} returns HTTP 400, as does a manual thinking budget using thinking:{"type":"enabled","budget_tokens":N}. Omit the field or send adaptive thinking and control depth with output_config.effort.
Opus 5 accepted disabled thinking at high effort or below. A stable low-latency path built around that switch therefore needs redesign, not just a new model ID.
2. Forced tool choice returns an error
Opus 5.5 rejects tool_choice set to any or to a named tool, again with HTTP 400. auto and none remain supported. For schema-valid output, Anthropic recommends strict tool use with auto or structured outputs.
This is a meaningful contract change. A prompt that tells the model to call a tool is not the same enforcement mechanism as an API-level forced choice. If a workflow relies on exactly one function firing, validate the replacement path before switching traffic.
3. Thinking blocks are bound to model and conversation
Thinking blocks are response records that preserve model reasoning across tool-use turns. Opus 5.5 can read blocks produced by Opus 5, so an append-only conversation can move forward without throwing away that earlier reasoning. The constraint is that 5.5 cannot read every model's blocks, and later edits to the system prompt, tools, or earlier messages can invalidate its own preserved thinking.
For API accounts created on or after August 31, 2026 at 00:00 UTC, replaying a bound block after such a prefix change returns HTTP 400 by default. Keep the history append-only. If your application edits old turns or swaps tool definitions in place, use Anthropic's documented binding controls and test the drop behavior explicitly.
4. Computer use differs by platform
On the Claude API and Google Cloud, Opus 5.5 rejects the earlier computer_20251124 tool and requires computer_toolset_20260801. The migration changes more than the type string: the agent loop must handle member tool_use blocks, batch actions, and toolset_name on results. Anthropic's computer-use documentation says Amazon Bedrock continues to accept the earlier tool on 5.5.
That platform split can make one multi-cloud deployment pass while another returns an error. Audit the provider and request body together.
5. Progress text can disappear without an error
Opus 5.5 returns short notes between tool calls as progress-update thinking blocks rather than ordinary text blocks. At the default display:"omitted", the thinking text is empty. An interface that used those text blocks for visible progress can go quiet even though requests and tool calls continue successfully.
Winner on integration compatibility: Claude Opus 5. Existing Opus 5 code has fewer changes. Opus 5.5 wins after the changes are made and validated.
Opus 5.5 Thinking: Recalibrate Effort, Tokens, and UI Behavior
The safest comparison sets effort explicitly because the defaults changed. Opus 5.5 defaults to medium; Opus 5 defaulted to high. Anthropic also says 5.5 tends to think more per turn at the same effort, especially at xhigh and max. A default-versus-default run measures the shipped experience. A high-versus-high run isolates more of the model difference.
The model has a 1 million-token context window and a 128,000-token maximum output according to Anthropic's model overview. Thinking and visible text share the response budget, so leave enough room for completion and record billed output rather than treating the effort label as a budget.
Opus 5.5 Usage vs Opus 5
Capture the full usage object, not just visible response length. At minimum, keep uncached input, cache creation, cache reads, output, latency, tool calls, retries, stop reason, and validator result. Separate defaults from matched effort, because mixing medium and high can make a cost win look like a pure capability win.
The older Opus 5 effort-dial analysis remains useful historical background for what the levels mean. The migration lesson is narrower: do not inherit an old level or an omitted setting without rerunning the workload.
Winner on spend control: split decision. Opus 5 offers the explicit ability to turn thinking off. Opus 5.5 offers the lower default and lower unit rates, but thinking is always present and must be measured.
Opus 5.5 Migration: What Switching Actually Costs
The migration cost is the work around the model call: request audits, agent-loop changes, preserved-context rules, stream rendering, evaluation, and rollback. A model-string replacement is sufficient only when the route already uses adaptive thinking, automatic tool choice, a supported computer toolset, append-only history, and type-aware stream parsing.
Do not switch yet if any of these conditions applies:
- A named tool must be forced at the API layer and the workflow cannot move to strict tools or structured output.
- Thinking must be disabled for the route's contract.
- A Claude API or Google Cloud computer agent still uses
computer_20251124and its loop cannot yet handle the toolset. - The application rewrites earlier messages or tool definitions while replaying preserved thinking blocks.
- There is no acceptance baseline, so a cheaper bill cannot be distinguished from lower-quality work.
Inventory every Opus 5 request shape
Search configuration and request builders for the model ID,
thinking,output_config.effort,tool_choice, preserved thinking blocks, and computer tool types. Check each cloud provider separately. Record which route owns the rollback.Run two matched-effort tasks
Use one bounded public-code repair with executable tests and one synthetic extraction with a deterministic schema validator. Send both models the same prompt, tools, context, explicit
higheffort, and explicit output limit. Save returned model IDs, complete usage, latency, validation results, and every failure.Compare defaults separately
Repeat with effort omitted. This isolates Opus 5.5 at its
mediumdefault from Opus 5 at itshighdefault and shows the production effect a simple model-ID change would create.Patch the incompatible paths
Remove disabled or manual-budget thinking, replace forced tool choice, migrate the earlier computer tool where required, preserve append-only history, and test progress rendering. Keep each change visible in review rather than hiding it inside the model upgrade.
Stage, measure, and promote
Route a bounded share of representative work to 5.5. Compare cost per accepted result, not price per token alone. Promote a task class only when acceptance holds or improves and total cost falls; keep Opus 5 as the rollback until the observation window closes.
A funded founder can run this harness before the next agent release. A CTO should make it a model-layer change with owners for API, observability, and product UI. A senior operator should add human review to irreversible actions regardless of the winner. A solo builder should keep the evaluation small, but still save the usage and validator result so the choice is evidence rather than feel.
Your Monday Move
Take one expensive, repeatable Opus 5 task next Monday and create a shadow route to claude-opus-5-5. Run both at explicit high effort first, then compare their changed defaults. Do not touch production until the forced-tool, thinking, computer, preserved-context, and progress-stream checks are green.
The final decision is simple: adopt 5.5 when the accepted result costs less and the integration contract still holds. Hold Opus 5 only for a named incompatibility or a measured regression. A vague preference for the familiar is not a production requirement.
Which version of Claude Opus is best?
Claude Opus 5.5 is the better starting point for new work because its standard rates and cache reads are lower and its published evaluations are stronger. Use Opus 5 as a temporary compatibility or rollback route when a breaking integration setting has not been migrated.
Is Claude Opus 5 better than GPT 5.6 Sol?
This pairwise migration comparison does not establish that. A cross-vendor decision needs the same harness, tools, effort controls, pricing, and acceptance rule on both vendors rather than a score copied from one launch page.
Is Claude Opus 5 better?
Opus 5 is not the better default than Opus 5.5 on price or Anthropic's published comparisons. It is the better temporary choice only where disabled thinking, forced tool selection, or an unchanged computer integration is mandatory.
Is there anything better than Claude Opus?
Anthropic positions Claude Fable 5.1 as the escalation model for demanding reasoning or long-horizon work that still fails Opus 5.5 evaluations at higher effort. It costs $10 per million input tokens and $50 per million output tokens, so it should solve a measured failure rather than replace Opus by default.
Why is Claude Opus so expensive?
Opus is Anthropic's premium work tier, so the bill is justified only when it prevents enough failed attempts, tool errors, or human review to beat a cheaper model's cost per accepted result. Opus 5.5 lowers that premium but does not remove the need to route simple work elsewhere.
Is Fable really better than Opus?
Not for every workload. Fable is an escalation path for a task that misses its acceptance bar on Opus 5.5; the higher unit price has to buy a measurable improvement on that task.
What is the price difference between Opus 5 and Fable 5?
Claude Opus 5 costs $5 per million input tokens and $25 per million output tokens. Claude Fable 5 costs $10 and $50, exactly twice those standard rates.
What's the difference between Opus 5 and Fable 5?
Opus 5 is the lower-cost premium work model, while Fable 5 is the higher-priced escalation tier for the hardest tasks. The practical difference is whether Fable clears an acceptance test that Opus misses by enough to cover the 2x token rates.
Does Opus 5 use more tokens?
There is no universal token ratio. Anthropic says Opus 5.5 uses fewer tokens per typical task, but it can think more per turn at the same effort and thinking cannot be disabled. Measure full billed usage on the same accepted workload.
Need a cleaner model shortlist before you spend a week on evaluations? Get the AI Tools Map for Business Owners.
- Last Updated
- Sep 23, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI
Is MiMo V2.6 Free
MiMo V2.6 Flash has a temporary free endpoint. Compare that offer with MIT model downloads, paid API access and desktop plans.Sep 22, 2026AI
Grok 4.7 vs Grok 4.6
Grok 4.7 starts at the same token price as 4.6. Compare access, coding evidence and task costs before moving your workflow.Sep 21, 2026AI
Specification Gaming in Production AI Agents
An AI editor sent 50 of 96 articles off topic. The measured costs, the rules that rewarded drift, and the controls that replaced them.Sep 21, 2026AI