How to Use Agentic CUDA Optimizer
Set up the CUDA optimizer, run a bounded kernel experiment, and check correctness, GPU time and model costs before trusting a speedup.


Run one small float32 matrix-multiplication kernel through a seven-attempt search, keep candidates only when every trusted case passes, and ship nothing until the saved winner repays the model calls, GPU time and review work. This guide is for Bertaye's Agentic CUDA Optimizer, not ByteDance and Tsinghua's CUDA Agent research system.
The short answer
Use Agentic CUDA Optimizer as a fenced experiment runner, not an autonomous proof machine. Pin the initial v0.0 commit, build its C++ test runner on the documented Windows stack, provide your own reference kernel and input cases, cap the search with --max-iterations 7, then audit history.json, summary.json and best.cu before a separate replay.
The optimizer can automate a useful loop: write a candidate, compile it, run it, reject it when outputs differ, time it when outputs pass, and feed the evidence into the next attempt. It cannot tell you that your reference is correct, that your cases cover production, or that a faster isolated kernel lowers the full GPU bill.
The repository arrived as commit 1e9464da54dfc651337a97c3643bfeefec712bc1 on September 24, 2026 at 19:41:43 UTC. Pinning that commit matters because this guide describes v0.0, not whatever changes next.
What the optimizer actually does
Think of it as a model shop with inspection gates. The model can redesign the small part on the workbench, the CUDA kernel, and adjust how that part is launched. The test runner controls the measuring equipment. A candidate reaches the display cabinet only after every supplied case produces an acceptable output.
Under the hood, a standalone C++ runner compiles CUDA source with NVRTC, launches it through the CUDA Driver API and saves the outputs. Python compares those outputs with the reference and selects candidates. Cases marked correctness must pass but do not affect the score. Cases marked performance both validate and contribute to the geometric-mean latency used for ranking.
By default, each timed case gets 10 warmup launches and 100 measured launches using CUDA events. Those numbers describe kernel timing, not job cost. Compilation, model calls, failed attempts, input generation, profiler replays and human review all sit outside that latency.
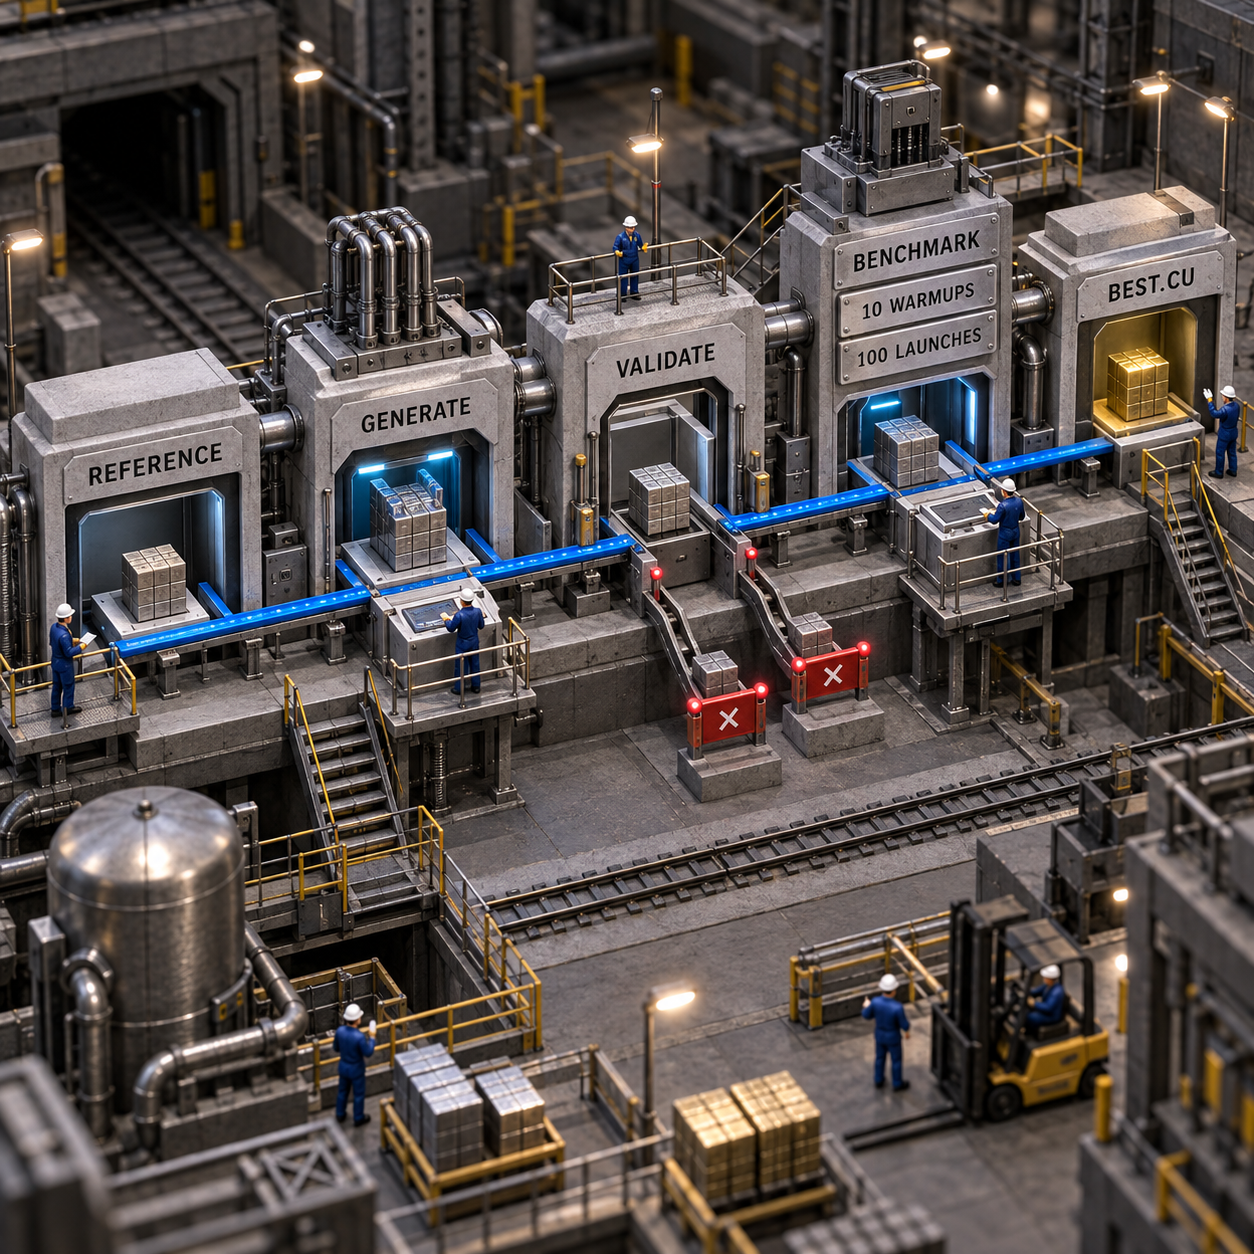
This separation is the reason to use the test runner instead of asking a general coding agent for one clever kernel in one prompt. The benefit is a recorded, bounded loop with explicit gates. It is not proof that LangGraph will find a better answer than a capable coding agent. The repository author made the same point in the launch discussion: the value is the fence around the steps.
Set up the pinned Windows build
Follow the documented Windows path first. The repository was developed with an RTX 3060 Laptop GPU and documents Visual Studio 2026 with C++ tools. Before compiling, confirm Python 3.12 or newer, CMake 3.24 or newer, a C++17 compiler, an NVIDIA driver and a compatible CUDA Toolkit.
python --version
cmake --version
where.exe cl
nvidia-smi
nvcc --version

git clone https://github.com/bertaye/agentic-cuda-optimizer.git
cd agentic-cuda-optimizer
git checkout --detach 1e9464da54dfc651337a97c3643bfeefec712bc1

python -m venv .venv
.venv\Scripts\python -m pip install -r optimizer_agent/requirements.txt
cmake -S cuda_test_harness -B cuda_test_harness/build -DCMAKE_BUILD_TYPE=Release
cmake --build cuda_test_harness/build --parallel

Set-Content .env 'OPENAI_API_KEY=your-key-here'
Stop if any prerequisite check fails. Fixing a toolchain while an agent is also changing kernels makes failures hard to attribute.
Two v0.0 details deserve attention:
- The README suggests
--config optimizer_agent/example.json, but that file is not present at the pinned commit. Use explicit flags or create and review your own configuration. - The public repository contains no license file, and GitHub reports no detected license. Public visibility is not a commercial licensing grant. Get permission or legal review before company use, redistribution or a paid product.
No other platform has a documented setup path in this version. A Linux environment was checked for this article, but it lacked the required CUDA and build tools, so that was a prerequisite audit, not a successful Linux test.
Finally, isolate the machine. If you let the optimizer create inputs, the generated Python executes locally without a sandbox. Generated CUDA also runs directly on the GPU. Use a disposable host or VM with narrow credentials, no production data, no unrelated secrets and no access to important file shares.
Design one experiment that can fail honestly
Start with one kernel whose contract you can state on a page. A row-major float32 matrix multiplication is a good pilot because its inputs, output and dimensions are explicit, while odd sizes expose edge handling that friendly square cases can miss.
Prepare three assets outside the optimizer's results directory:
reference.cu, a simple, reviewed implementation from a trusted source. Do not ask the same model to create the oracle and the candidate.initial.cu, the real baseline you would otherwise ship. This prevents a dramatic win over weak generated code from being mistaken for a business win.input_cases.json, with fixed, reproducible binary inputs and meaningful comparison tolerances for your numerical contract.
A bounded pilot could include one odd-shaped correctness case such as M=31, N=37, K=29, then two modest performance cases such as 256 by 256 by 256 and M=384, N=256, K=320. These are experiment-design suggestions, not repository benchmarks. Keep a fourth holdout shape and fresh values outside the optimizer so the final candidate faces a case it did not see during search.
Use nontrivial values, not all zeros or ones. Review every buffer size, argument order, scalar type and tolerance. The manifest must contain at least one performance case. Every case must pass, but only performance cases affect ranking.
Hash or copy the reference, inputs and test runner before the run. The optimizer should be free to change candidate source and per-case launch settings, not the definition of success.
Run exactly seven improvement attempts
The command below uses explicit inputs and the documented Windows interpreter path. It fixes the entry signature, supplies the independent reference and real baseline, and caps the improvement budget at seven attempts.
.venv\Scripts\python optimizer_agent\optimizer_agent.py `
  --description "Row-major float32 matrix multiplication C=MxN from A=MxK and B=KxN." `
  --signature 'extern "C" __global__ void matmul_f32(const float* a, const float* b, float* c, int m, int n, int k)' `
  --reference .\experiment\reference.cu `
  --initial-kernel .\experiment\initial.cu `
  --input-cases .\experiment\input_cases.json `
  --max-iterations 7
The default model is gpt-5-mini with medium reasoning effort, and its API use is billed to your account. Seven improvement attempts do not mean seven model calls or seven kernel launches. A proposal can use tool calls and correction retries, while each timed case alone defaults to 10 warmups and 100 measured launches.
Leave --use-nsight and --nvidia-research off for the first clean baseline. Nsight profiling adds replay work and requires Nsight Compute plus permission to read GPU performance counters. NVIDIA research adds model and retrieval work. Add one variable at a time after the basic loop is stable.
Before pressing Enter, open an experiment log and record:
- pinned commit and dirty-tree status
- GPU model, driver and CUDA Toolkit versions
- reference and case hashes
- start and finish timestamps
- total GPU wall-clock time
- model name, calls, tokens or other usage metadata available in saved response files
- valid candidates, rejected candidates and rejection reasons
- per-case latency for the baseline and winner
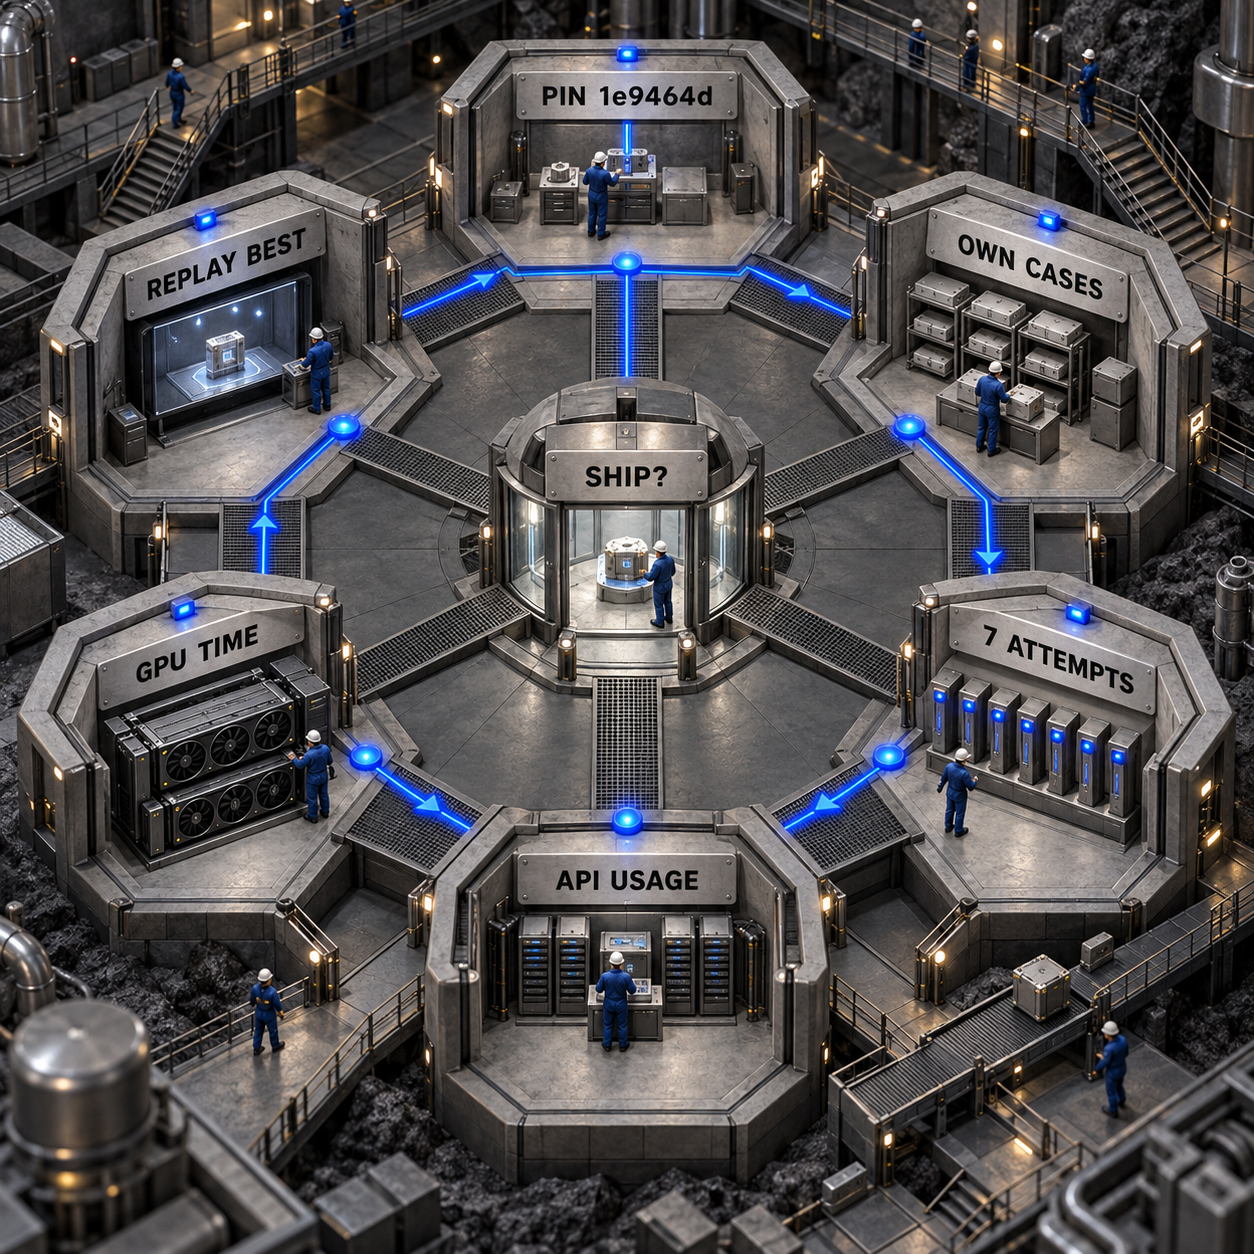
Keep the GPU otherwise idle while comparing timings. Background GPU work can turn a small apparent improvement into measurement noise.
Read the evidence, then replay the winner
Treat the result directory as an audit bundle, not a trophy folder. Each session lives under results/run-NNN/. Start with these files:
history.jsoncontains every evaluated attempt, case-level execution details, validation results, launch configuration and measured latency.summary.jsonnames the best iteration, per-case latency, available baseline speedups and the termination reason.best.cuis the fastest candidate that passed all supplied cases.best-case-N.jsonfiles are replay requests for the winning source on the supplied cases.model-*.jsonand tool-response files preserve the agent interaction. Inspect their usage metadata for API accounting becausesummary.jsondoes not total model spend.heatmap.pngandheatmap.svgshow timing history. They are navigation aids, not correctness evidence.
Count the rejected candidates as carefully as the valid ones. A run with six rejected proposals and one narrow winner tells you something different from a run where every candidate stayed valid. Review compiler failures, output mismatches and whether the winning source actually differs from its parent.
Next, replay each saved best-case-N.json through the test runner on the same idle GPU. Then test best.cu against the hidden shape and fresh values using an independent oracle. The supplied cases prove only that the candidate passed those cases. They do not prove general correctness, race freedom or safe behavior over every valid shape.
Reject the winner if any holdout fails, if repeated timing crosses the baseline within noise, or if the gain disappears inside the real application. A generated reference is not acceptable as the only oracle, and a win over the generated starting kernel is not a win over cuBLAS or another production baseline. The repository publishes no cuBLAS comparison.
Decide whether the speedup pays
Use full-job economics, not the isolated kernel score. The public repository has no subscription price, but it also has no commercial license grant. Your experiment still consumes engineer time, model API usage and GPU time.
A useful worksheet has three lines:
pilot cost = engineer setup and review + model charges + GPU wall-clock costsaved GPU hours per month = end-to-end milliseconds saved per invocation × monthly invocations ÷ 3,600,000payback months = pilot cost ÷ monthly gross GPU saving
Use the end-to-end milliseconds saved after integration, not the CUDA-event latency from summary.json. If the kernel runs several times per request, count measured invocations. If faster execution changes throughput, memory pressure or batching, remeasure the full workload instead of extending the kernel result by assumption.
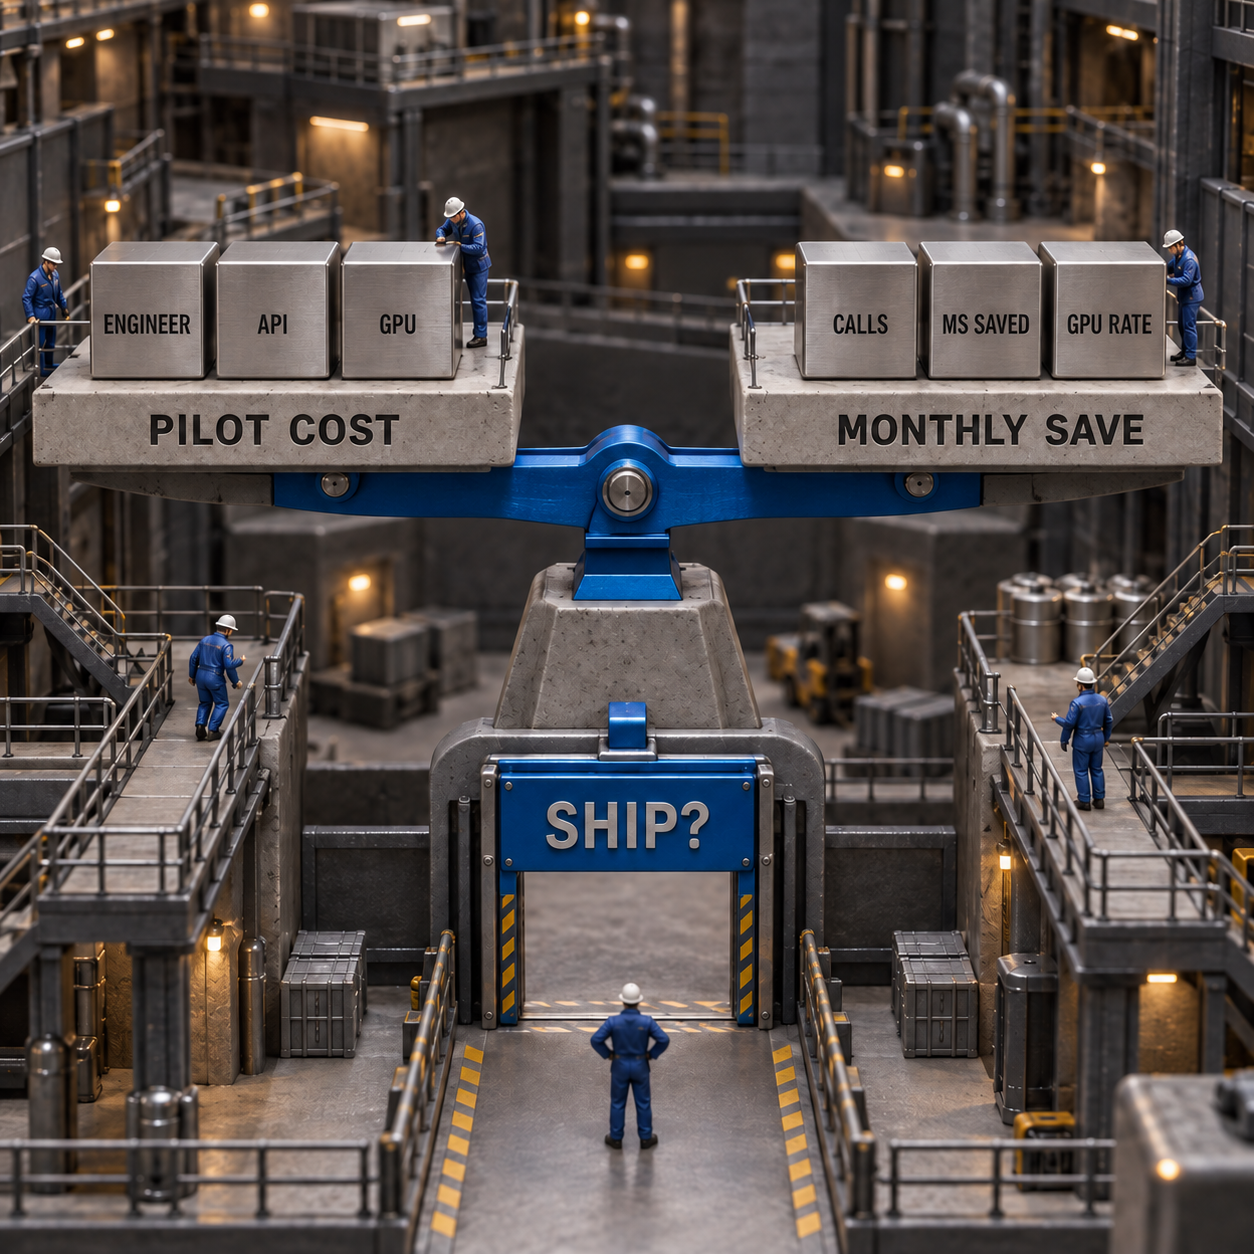
The human alternative is not cheap. Upwork's CUDA consultant page currently gives planning ranges of $500 to $1,200 for performance profiling and $2,500 to $4,500 for kernel tuning. Those are marketplace ranges, not quotes and not evidence that an agent replaces a specialist. They do show why a repeatable first-pass experiment can be valuable if it narrows the expensive expert work to candidates with clean evidence.
The go or no-go rule is blunt: ship to a controlled integration test only when the candidate passes independent cases, beats the baseline repeatedly, improves the real workload and has a payback window your team chose before the run.
Seven teams that can use this well
These use cases are ranked by who is most likely to turn a validated kernel gain into money or saved capacity.
If the workload is a full application, a mature vendor primitive or a moving collection of shapes, start elsewhere. This optimizer is explicitly experimental and aimed at individual kernels.
For a broader view of neighboring systems, the existing AI agents for GPU optimization comparison covers AKO, KernelAgent, AutoKernel, Apex and CUDA Agent. Bertaye's repository is a newer, separate project.
Two products worth building around it
1. Bounded CUDA optimization audit
This is the strongest opportunity. Sell a fixed-scope evidence package to teams with one costly CUDA kernel: environment capture, trusted-case intake, a seven-attempt run, independent replay, model and GPU cost accounting, and a go or no-go report.
Demand is small but unusually specific. DataForSEO reports about 30 US searches a month for cuda optimization and 20 for cuda kernel optimization, both with low paid-search competition. The same market has planning prices of $500 to $1,200 for profiling and $2,500 to $4,500 for tuning on Upwork. That combination points to a narrow expert service, not a mass self-serve app.
The smallest sellable version is a secure intake form, a disposable GPU runner, a locked case manifest, a run-cost collector and an HTML evidence report. Keep a human reviewer in the loop. The catch is trust: one incorrect winner can erase the value of many successful audits, and the repository's absent license means you need permission before basing a commercial service on its code.
2. GPU kernel regression gate
Build a controlled CI service that replays approved kernels on reserved hardware, checks saved outputs and blocks a release when latency or correctness drifts. GPU platform teams and CUDA consultancies would pay for a stable record across driver, toolkit and source changes.
DataForSEO reports about 10 US searches a month for gpu performance optimization. That is too little for an SEO-only business, but it is enough to validate the language buyers use. Distribution should come through consultancies, GPU vendors and internal platform teams.
An MVP needs a hardware queue, environment fingerprints, signed reference cases, repeated timing, thresholds and a compact diff against the last accepted run. The catch is variance: shared hosts, thermal state and driver changes can trigger false alarms unless the runner controls the machine and repeats measurements.
Limits that should change your decision
The honest take is that v0.0 is a useful experiment scaffold with a large trust burden.
- It optimizes individual CUDA kernels, not whole applications.
- Passing supplied cases does not establish general correctness.
- A generated reference is not an independent oracle.
- Performance gains depend on the workload and hardware.
- No cuBLAS or other vendor-library comparison is included.
- Default timing excludes compilation and profiler replay, so it is not total run cost.
- Generated input scripts execute locally without a sandbox.
- The documented build path is Windows; another platform needs its own verified setup record.
- The named example configuration is missing at the pinned commit.
- The repository does not establish commercial licensing rights.
The separate runner is worthwhile when you want explicit stages, persistent evidence and a repeatable budget. A general coding agent may be enough when an expert is already supervising the terminal, the tests are strong and the work is genuinely one-off. The runner earns its place only when the fence and audit trail reduce risk or repetition.
Frequently asked questions
How do you use Agentic CUDA Optimizer on a Mac?
The pinned repository documents a Windows build with an NVIDIA GPU and compatible CUDA stack, not a Mac setup. Use a remote or disposable NVIDIA machine that you can verify, and label that platform separately rather than translating the Windows commands by guesswork.
Is Agentic CUDA Optimizer the same as ByteDance CUDA Agent?
No. This guide covers Bertaye's agentic-cuda-optimizer, a LangGraph workflow plus a C++ CUDA test runner released in September 2026. ByteDance and Tsinghua's CUDA Agent is a separate research system and repository.
Which CUDA-Agent GitHub repository does this guide use?
It uses bertaye/agentic-cuda-optimizer pinned to commit 1e9464d. Search results also surface BytedTsinghua-SIA/CUDA-Agent, which is not the software configured here.
Does the optimizer use an NVIDIA CUDA Agent?
No separate NVIDIA agent is part of the documented loop. The project can optionally retrieve NVIDIA guidance with --nvidia-research and inspect Nsight Compute counters with --use-nsight, but candidate generation and orchestration remain in this repository's own workflow.
The Monday move is simple: assign one GPU engineer one low-risk float32 kernel, one disposable NVIDIA machine and one day to prepare the independent reference, cases and cost sheet. Run the seven-attempt pilot only after those gates are written down.
If you want a measured GPU experiment and its review path built into a production system, AI production systems is the matching place to start.
- Last Updated
- Sep 25, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Runpod Pricing (2026): Pods or Serverless by Paid Time
Calculate Runpod pricing for Pods, Serverless, storage and production inference, with a dated H100 worksheet and a billable-time break-even.Sep 25, 2026Build
How to Use Vercel Sandbox Drives
Keep an agent workspace across Vercel Sandbox runs. Create a Drive, mount it, restart safely, and understand writer, snapshot, and region limits.Sep 25, 2026Build
Firecrawl Alternatives
Compare Firecrawl alternatives for business AI pipelines by crawl support, Markdown and JSON output, migration work and cost per usable page.Sep 25, 2026Build
CodeRabbit Alternatives
Compare CodeRabbit alternatives by Git support, hosting, review limits and real team cost, with clear reasons to switch or stay.Sep 25, 2026Build
Greptile vs CodeRabbit
Compare Greptile and CodeRabbit on review limits, real team costs, Git support and the checks to run before buying.Sep 25, 2026Build
How to Use Perplexity Portable Computer
Set up Perplexity Portable Computer on a supported Windows PC, choose a local model, and test a recurring file task with clear cloud permissions.Sep 25, 2026Build
AgentRun Review
Test AgentRun's workflow beta on support tasks, inspect branching and escalation, and see when it earns its place beside your existing agent.Sep 24, 2026Build