How to Use Jev
Use Jev to route a support ticket, read its confidence scores, and test when your workflow should hand the decision to a person.

Jev can turn one messy support message into three things your software can use immediately: a queue, a severity score, and a probability that the ticket is urgent. The useful part is not merely that those answers are typed. It is that your code can inspect them, log them, and decide when not to trust them.
Start with one reversible job: route a ticket, but keep a human-review queue in the code. Jev guarantees the shape of its answer, not that billing is the right answer. That distinction is the difference between a demo and an operating workflow.
Start with one decision, not an autonomous support agent
Jev is a decision model, not a chatbot. You send it some text or structured JSON called the state, then ask questions whose possible answer shapes are fixed in advance. It returns values and probabilities rather than a written reply. TypeSafe calls this a System One model, meaning it is designed for fast, narrow judgments inside normal software.
Think of it as a semantic switchboard. An ordinary if statement can check an exact fact such as whether an invoice is overdue. Jev handles the fuzzy part, such as whether a customer's message sounds urgent, then hands control back to ordinary code.
For a first support workflow, give it one ticket and ask:
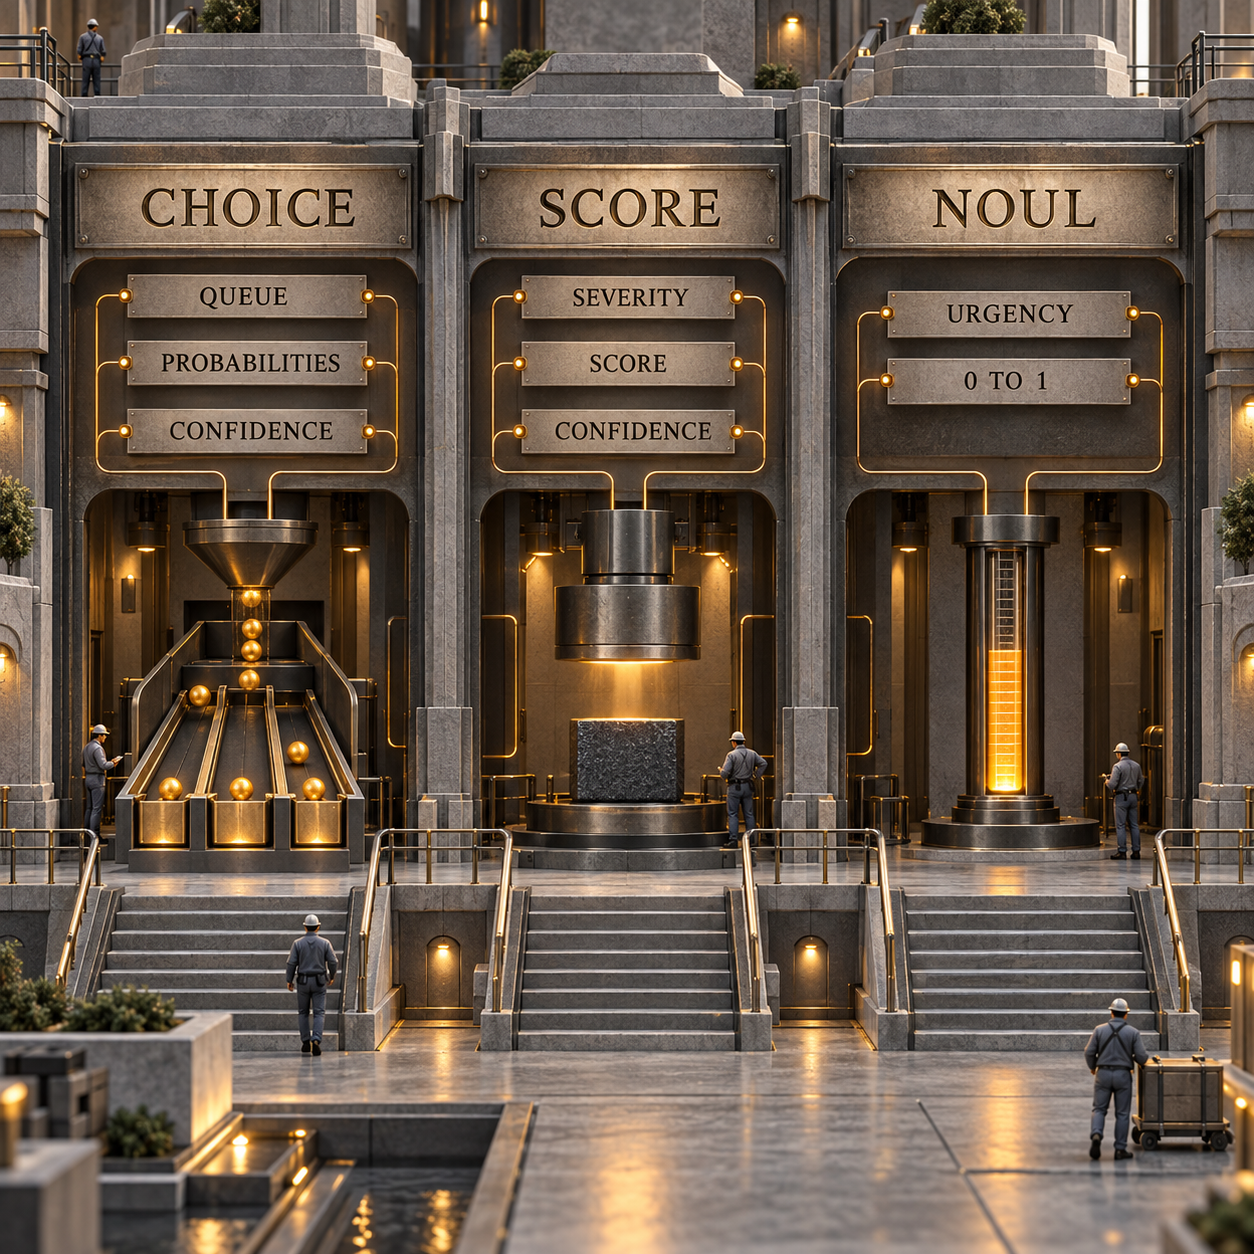
- Choice: Which fixed queue should receive this ticket?
- Score: Where does its severity sit on an ordered rubric?
- Noul: How likely is it that the customer is expressing urgency?
All three can travel in one request and are evaluated independently against the same state. Jev currently accepts text only, including strings and JSON structures made from text. It does not accept an attachment, image, audio clip, or video.
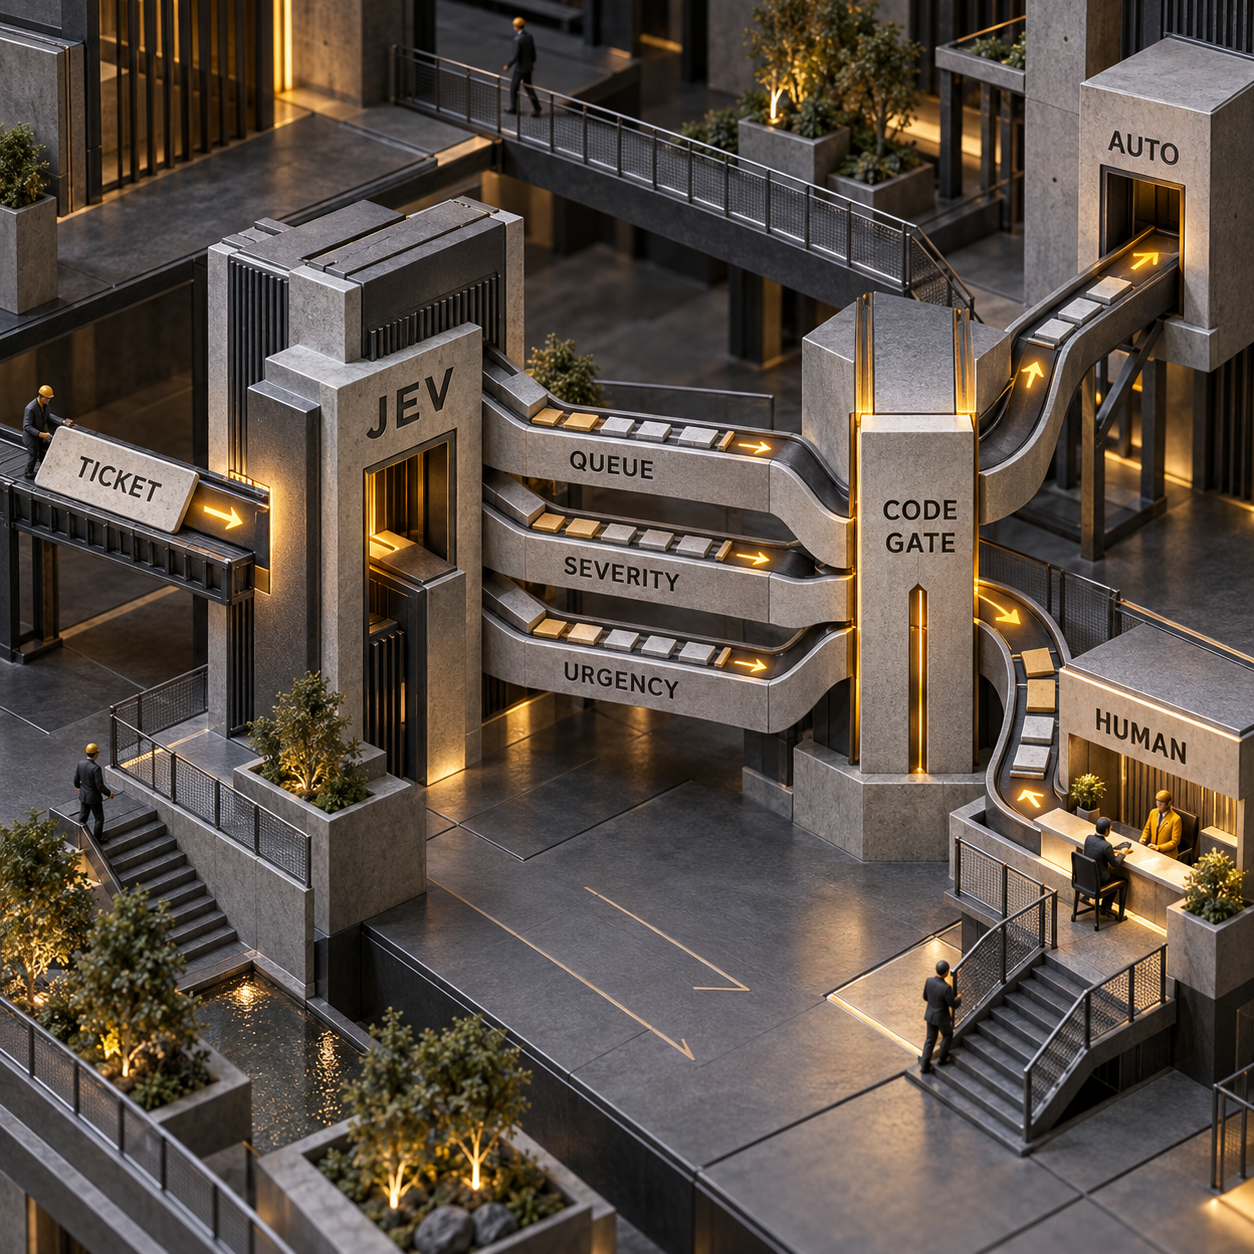
Choice, Score, and Noul are not three names for the same answer
Each primitive answers a different kind of question. Choosing the right one matters more than clever wording.
A queue is a Choice because billing, technical, sales, and other are alternatives. Severity is a Score because its levels form an ordered rubric. Urgency is a Noul when the question is simply whether the message expresses time pressure.
The full distributions matter. A Choice that assigns similar probabilities to billing and technical is telling you that the queue boundary is fuzzy. The single confidence field summarizes that spread for Choice and Score. With a Noul, a value near 0.5 is the ambiguous zone because the returned value already represents the yes probability.
Build the first ticket route
The access check comes first. TypeSafe released Jev in early access on September 15, 2026, and this publishing environment did not have a TypeSafe key. A request to the models endpoint without a key returned HTTP 403 with an authentication error. The workflow below is runnable with authorized access, but no result in this article is presented as an execution from this run.
Use Python 3.10 or newer, install typesafe-sdk, and set TYPESAFE_API_KEY in your environment. The SDK reads that variable and uses jev-latest by default. This example states the model explicitly so the request is easy to audit.
from time import perf_counter

from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

ticket = {
    "id": "T-001",
    "message": (
        "Our SSO connection stopped working after renewal. "
        "The invoice is paid, but the whole team is locked out."
    ),
}

started = perf_counter()
with TypeSafeClient() as client:
    response = client.system_one(
        model="jev-latest",
        state=ticket,
        questions={
            "queue": Choice(
                instructions="Which support queue should handle `message`?",
                criteria={
                    "billing": "Invoices, payments, refunds, or subscriptions",
                    "technical": "Bugs, outages, access, or integrations",
                    "sales": "Plans, pricing, upgrades, or a new account",
                    "other": "Anything that does not clearly fit the other queues",
                },
            ),
            "severity": Score(
                instructions="How severe is the customer impact in `message`?",
                criteria=[
                    "Minor inconvenience",
                    "One person is blocked",
                    "Several users are blocked",
                    "Security risk or data loss",
                ],
            ),
            "urgent": Noul(
                instructions="Does `message` express urgency or time pressure?",
            ),
        },
    )
latency_ms = round((perf_counter() - started) * 1000, 1)

queue = response.answers["queue"]
severity = response.answers["severity"]
urgent = response.answers["urgent"]

# These are conservative test gates for this reversible workflow,
# not universal thresholds. Tune them on labelled tickets.
needs_human = (
    queue.choice == "other"
    or queue.confidence < 0.75
    or severity.confidence < 0.70
    or 0.35 < urgent.noul < 0.65
)

record = {
    "ticket_id": ticket["id"],
    "model": response.model,
    "input_tokens": response.usage.input_tokens,
    "latency_ms": latency_ms,
    "queue": queue.choice,
    "queue_probabilities": queue.probabilities,
    "queue_confidence": queue.confidence,
    "severity": severity.score,
    "severity_confidence": severity.confidence,
    "urgency_probability": urgent.noul,
    "handoff": needs_human,
}
print(record)
The threshold choices above are intentionally local. Assigning the wrong support queue is usually reversible, but even that cost varies. A two-person startup may tolerate a misroute that a hospital help desk cannot. TypeSafe's own confidence guidance says the boundaries should follow the stakes and be tuned on your data.
There is another detail worth logging: jev-latest is an alias. At publication it points to jev-1.13.0, and the response's model field tells you which version actually answered. If a later version changes your results, a log without the resolved model ID cannot explain why.
The visible failure case is a valid answer with the wrong meaning
The sample ticket deliberately contains two strong signals. “Renewal” and “invoice” point toward billing, while “SSO” and “locked out” point toward technical support. Under the rubric in the code, a labelled test set might define technical as the correct queue because access failure is the immediate blocker.
Jev could still return a perfectly valid billing Choice. The JSON would parse. The field would exist. The value would be one of the allowed options. The answer would still be wrong against that label.
That failure exposes two separate controls:
- Runtime fallback: Send low-confidence,
other, and ambiguous Noul cases to a person. - Evaluation fallback: Compare every test decision with a human label, including high-confidence decisions. A threshold cannot catch a confidently wrong label.
Do not turn “type safe” into “accurate by construction.” Type safety protects the interface between the model and your code. Accuracy is a property you must measure for the exact tickets, labels, criteria, model version, and language you use.
An independent early email-routing test makes the point. On 1,565 German and English business emails, the practitioner reported Jev at 96.4% overall accuracy, behind two Gemini models. The same test found that Jev's errors clustered at lower confidence, which made selective human review useful. That is one practitioner's dataset, not a universal production result.
Run a 30-ticket workflow check before you route anything
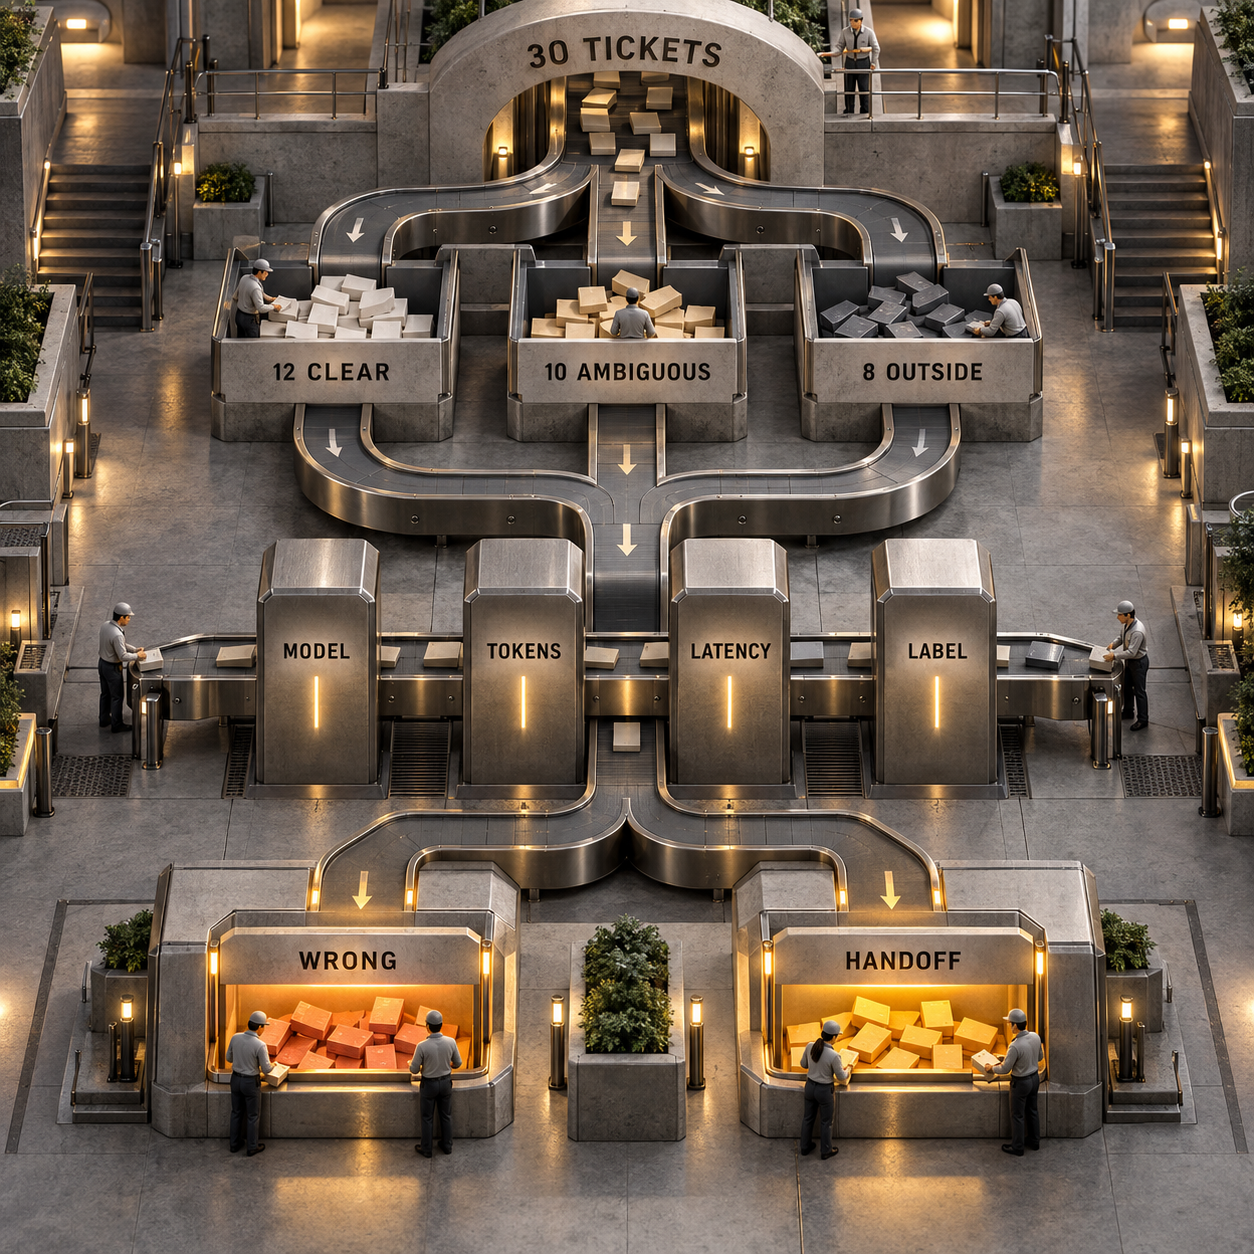
Thirty tickets cannot establish production accuracy. They can reveal a bad label set, missing other path, misleading instruction, response-field mistake, or fallback that never fires. Treat this as a small workflow check, not a benchmark.
Build the fixture before looking at Jev's answers:
Give every row a stable ticket ID, the expected queue, a short reason for that label, and whether a person should receive it. Then record the resolved model version, input tokens, client-measured latency, returned queue and probabilities, severity and its confidence, urgency probability, wrong-label flag, and actual handoff.
Review at least four slices separately:
- Wrong labels among cases your code would auto-route
- High-confidence wrong labels, because the runtime gate will miss them
- Handoff rate for clear cases, because excessive caution creates manual work
- Out-of-scope cases that failed to land in
other
If access is still waitlisted, keep the fixture and script ready. Do not fill the result columns with values copied from documentation or another person's test. The honest artifact is an access-blocked run sheet with executable code.
The cost math changes the classification line item, not the whole support stack
Jev 1.13 is priced at $0.042 per million input tokens, with output unmetered. At that rate, a hypothetical 500-input-token ticket costs $0.000021 in model input. One hundred thousand tickets of that size would cost $2.10.
That number is striking, but it is not a replacement price for customer support software. Zendesk starts at $19 per agent per month paid yearly, while Intercom starts at $29 per seat per month and charges from $0.99 per Fin outcome. Those products include inboxes, ticket storage, agent interfaces, reporting, and other operating machinery. Jev provides the decision signal only.
The budget assumption that changes is narrower: repeated semantic classification no longer needs to consume a costly generative-model call every time. The money and effort move to integration, labelled examples, monitoring, exception handling, and the people who take the handoffs. At ordinary inbox volume, the raw inference saving may be less valuable than knowing which tickets the model says it is unsure about.
There is a useful division of labour here. Jev can choose a route. A generative model can prepare language. For the reply side of that workflow, see how ChatGPT can prepare Zendesk replies from ticket history. Your application code should still enforce policy, permissions, and actions.
Seven workflows, ranked by who benefits most
These are possible applications of a constrained decision model, not reported outcomes.
Jev is strongest when the possible answers are known, the decision repeats often, and a wrong branch can be contained. It is a poor fit when the output must be a reply, explanation, calculation, precise date comparison, or long chain of reasoning.
Two products worth building
1. A confidence-gated support-routing retrofit
This is the strongest opportunity. Sell a thin routing layer to teams that already use a help desk but still sort tickets manually or maintain brittle keyword rules. It would read the ticket, apply the team's own queue rubric, write the selected queue and probabilities back to the help desk, and send uncertain or unmatched cases to a person.
The demand is specific enough to matter: customer service automation receives about 880 US searches a month, while help desk automation and customer support automation each receive about 260. Existing support platforms start around $19 to $29 per seat per month, so the pitch is not “replace your help desk.” It is “make one routing decision measurable inside the help desk you already pay for.”
The smallest sellable version needs one connector, four editable queue definitions, an other route, confidence bands, a review inbox, and a weekly wrong-label report. The catch is onboarding. Every customer uses different queue boundaries, and a generic schema becomes the product's failure mode. The moat is the evaluation and feedback loop, not the API call.
2. A shadow-mode routing QA console
Sell the safety layer before selling automation. A support lead uploads labelled tickets, runs a candidate question schema without changing live assignments, and receives confusion counts, high-confidence errors, handoff rates, version comparisons, and a list of cases that need better criteria.
The same 260 monthly searches for help desk automation show interest in the job, while a $129.46 CPC on customer support automation signals that vendors value this traffic commercially. The MVP can be a CSV importer, direct Jev call, side-by-side label review, and exportable decision log. It should support the 30-ticket check first, then larger private datasets.
The catch is that teams may expect statistical assurance from a polished dashboard. The product has to state what a small sample can and cannot prove, protect ticket data, and avoid presenting confidence as ground-truth accuracy. This is a good companion product to the routing retrofit, but weaker as a standalone business because evaluation is episodic.
Limits that should stop you
Do not use Jev when you need prose, a customer reply, code, or an explanation of reasoning. It is also the wrong place for arithmetic, counting, date comparisons, or deterministic eligibility rules that ordinary code can handle exactly.
Jev 1.13 is documented as weaker with literal traps, indirection, irrelevant context, adversarial content, contradictory instructions, and numeric precision. Its primary training language is English, with lower documented accuracy in other languages. Attachments need to be converted to text by another system before Jev can see them.
The context limit is 64,000 tokens for the whole request, with a second 32,000-token limit covering the state plus the longest question. Treat those as ceilings, not targets. The official guidance warns that irrelevant state can reduce accuracy, so retrieve only the policy and ticket details needed for the current questions.
The hard stop is consequence. A support label is reversible. A refund, account suspension, hiring decision, medical priority, or transfer of money is not just a label. Keep high-consequence action behind deterministic checks, confirmation, a qualified person, or a system designed and validated for that domain.
What to do on Monday
If you run support operations, export 30 recent tickets on Monday morning. Label 12 clear, 10 ambiguous, and 8 out-of-scope examples before anyone sees model output. Request early access, run the script in shadow mode when a key arrives, and review the confidently wrong cases before tuning a threshold. Do not connect the result to live routing until the human label, model version, and fallback outcome are all in the same log.
What Is Jev AI?
Jev is TypeSafe AI's decision model for structured software workflows. It reads text or structured text state and returns constrained Choice, Score, and Noul answers with probabilities rather than generating prose.
What Is Jev Short For?
TypeSafe says the name refers to William Stanley Jevons. The broader “System One” name refers to the fast, intuitive side of the System 1 and System 2 distinction.
How to Use Jev Video
Video results can help with orientation, but implementation should start from the current TypeSafe API and SDK documentation because request fields, model aliases, access, and limits can change. The direct workflow is: get an authorized key, send state plus typed questions, inspect the returned distributions, and keep the fallback in code.
If you want a confidence-gated support workflow built around your real queue rules and tickets, AI customer service development is the right place to start.
- Last Updated
- Sep 21, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
How to Make Claude Code Read AGENTS.md
Set up Claude Code's native AGENTS.md support, check which instruction file loads, and handle provider limits and existing CLAUDE.md files.Sep 19, 2026Build
How to Set Claude Code MCP Startup Timeout
Set the MCP startup wait for Claude Code jobs, distinguish connection waits from tool timeouts, and check required tools before work starts.Sep 17, 2026Build
How to Block AI Training Without Blocking Search
Use Cloudflare’s new training controls while keeping search access. Check migrated settings and separate crawler preferences from request blocking.Sep 16, 2026Build
Murmure Dictation Review
Review Murmure for offline dictation, custom vocabulary, hardware needs, and what changes when you connect a local or remote LLM.Sep 14, 2026Build
RenderIO FFmpeg API Pricing
Decode RenderIO command charges, chained jobs, download credits, runtime limits, and when an upgrade costs less than overage.Sep 14, 2026Build
Dictare AI Dictation Pricing
Dictare is free, local voice input for coding agents. Separate its software cost from speech-model setup, hardware, and your coding-agent plan.Sep 13, 2026Build
How to Test Claude Code Plugins With Evals
Run Claude Code plugin evals, compare results with a no-plugin baseline, and budget the repeated agent and judge calls before adding CI.Sep 12, 2026Build