How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.


MiMo-V2.6 can turn one checked prompt into a repeatable business workflow through Xiaomi's API. Start in Studio to prove the task, use Flash for the first production request, and switch models only when quality or latency data earns the extra cost.
The shortest path is simple: test a synthetic task in AI Studio, create the right kind of key, point an OpenAI-compatible client at Xiaomi's base URL, and inspect the returned JSON before you connect real customer data.
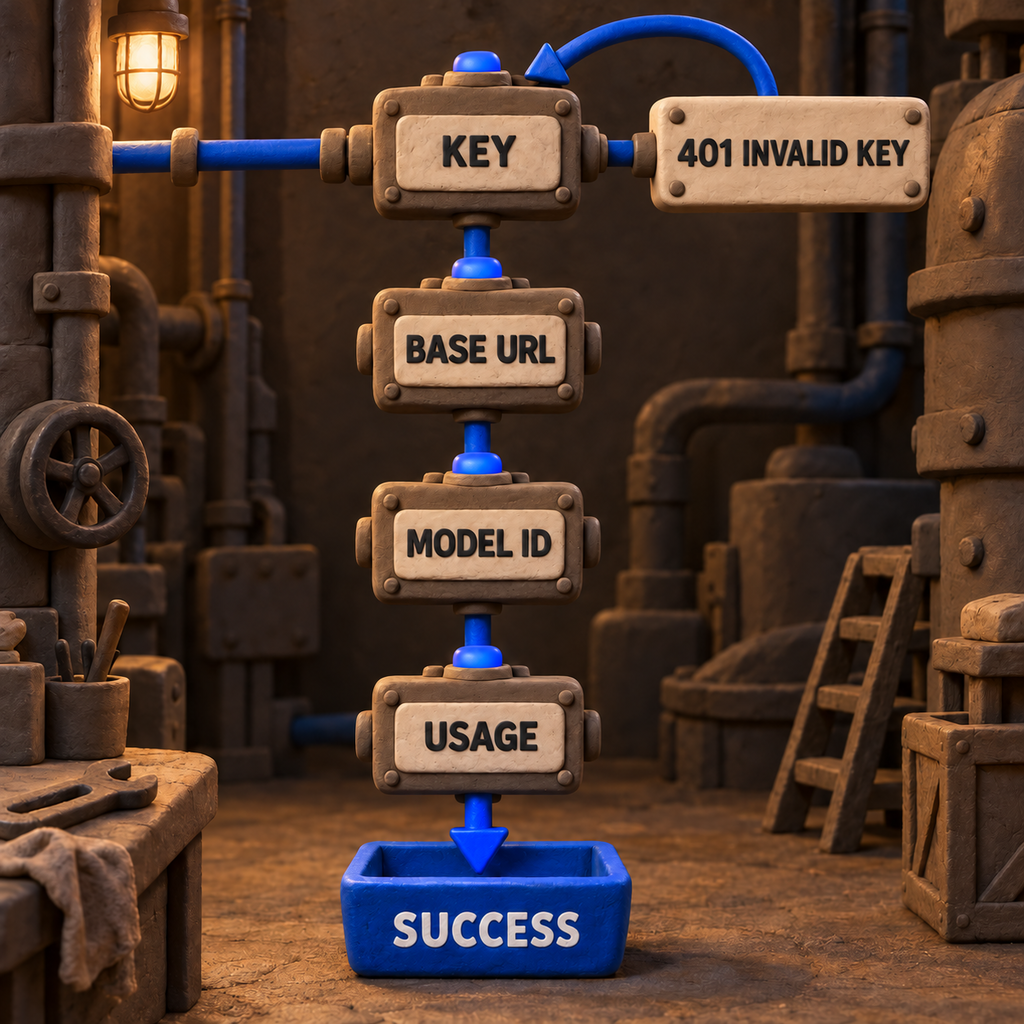
That order matters. It separates a prompt problem from an account problem. If the task does not work in Studio, changing Python will not save it. If it works in Studio but the API says the key is invalid, the likely issue is the credential lane, not the model.
What MiMo-V2.6 Actually Is
MiMo-V2.6 is a model series with two practical starting points. mimo-v2.6-flash is the low-cost default for frequent calls. mimo-v2.6-pro is the higher-priced choice for complex, long-horizon work. Both accept text, images, video, and audio, then return text. Both list a 1 million token context window, a 128,000 token maximum output, tool calling, streaming, structured output, web search, and context caching.
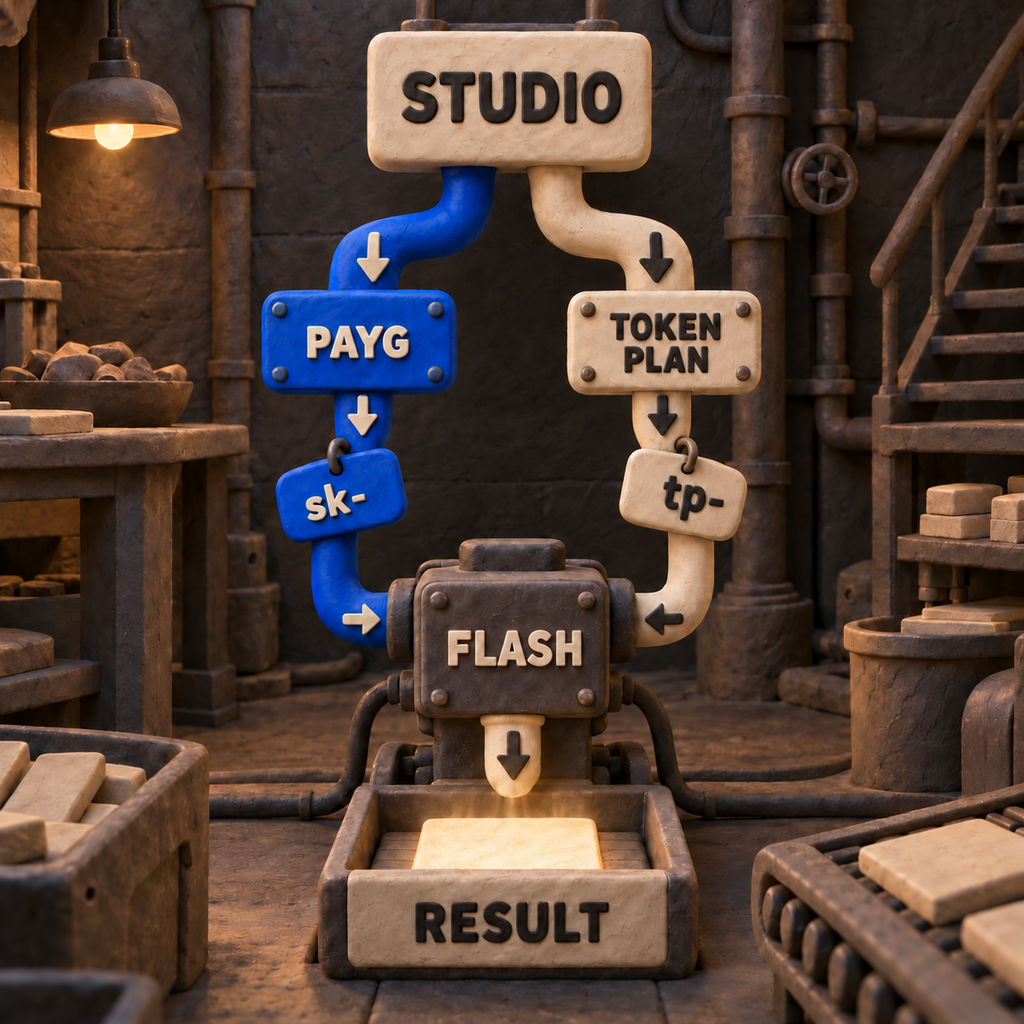
Think of the model as an engine and the access route as the fuel card. The engine can be the same while the card, meter, and filling station differ. A pay-as-you-go key will not spend Token Plan quota, and a Token Plan key will not authenticate against the pay-as-you-go base URL.
Xiaomi makes Pro and Flash available in AI Studio, MiMo Code, MiMo Desktop, its API platform, and OpenRouter. Studio is the useful first stop because it lets an operator judge the task before an engineer packages it.
The Setup That Gets a First Task Working
Use a harmless, representative task first. For support triage, do not paste a real customer's name, email, order history, or payment details. Use a synthetic ticket that has the same shape as the work:
Classify this synthetic support ticket as billing, access, bug, or other, then give one next action: My card was charged but my workspace balance did not update.
1. Check the task in Studio
Sign in with a Xiaomi account, open AI Studio, choose MiMo-V2.6-Flash, and submit the synthetic prompt. You are checking three things: the category is valid, the next action is operationally useful, and the response is consistent enough to turn into a schema later.
Do not tune for elegance yet. A useful first result might say billing and recommend checking payment settlement or escalating the balance mismatch. If the answer wanders, tighten the categories and require one next action. Studio is the rehearsal room, not the production system.
2. Choose the credential lane before creating a key
For a general business API workflow, pay-as-you-go is the clean default. Top up the MiMo console, create an ordinary key from API Keys in the sk- format, and use:
- Base URL:
https://api.xiaomimimo.com/v1 - Model:
mimo-v2.6-flash
Token Plan is a subscription product positioned for AI programming workloads. It issues a separate tp- key for individuals or ttp- key for teams, and uses:
- Base URL:
https://token-plan-cn.xiaomimimo.com/v1 - Model:
mimo-v2.6-flashormimo-v2.6-pro
The API shape is the same, but the key and base URL move together. Xiaomi explicitly says pay-as-you-go balance and Token Plan quota are not interoperable. For the full access terms, see Is MiMo V2.6 Free.
3. Make the smallest useful Python request
The following request follows Xiaomi's OpenAI-compatible example but removes the stale December 2025 system date from the official sample. It uses a neutral task, reads the key from the environment, and prints the full response so you can preserve the returned model ID, usage, and content.
import os
import time
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["MIMO_API_KEY"],
    base_url="https://api.xiaomimimo.com/v1",
)

started = time.perf_counter()
response = client.chat.completions.create(
    model="mimo-v2.6-flash",
    messages=[{
        "role": "user",
        "content": (
            "Classify this synthetic support ticket as billing, access, "
            "bug, or other, then give one next action: My card was charged "
            "but my workspace balance did not update."
        ),
    }],
    max_completion_tokens=120,
    stream=False,
    extra_body={"thinking": {"type": "disabled"}},
)

print(f"latency_seconds={time.perf_counter() - started:.3f}")
print(response.model_dump_json(indent=2))
Install the current OpenAI Python package, export MIMO_API_KEY, and run the file. If you bought Token Plan, change both the key and base_url. Do not change only one.
What was and was not verified here
This sample is unexecuted because the publishing environment had no authorized MiMo account or key. A credential-free probe did reach https://api.xiaomimimo.com/v1/chat/completions. It returned HTTP 401 with invalid_key and the message Invalid API Key in 0.067 seconds. That is a recoverable setup failure: supply a valid key from the matching account lane.
Authentication failed before inference, so there is no honest model ID, token usage, or completion to report. A successful run should preserve the full response JSON, the client-measured latency, and a redacted copy of the request. That gives you enough evidence to compare models and investigate billing without logging the key or customer data.
Pick Flash, Pro, or UltraSpeed by the Job
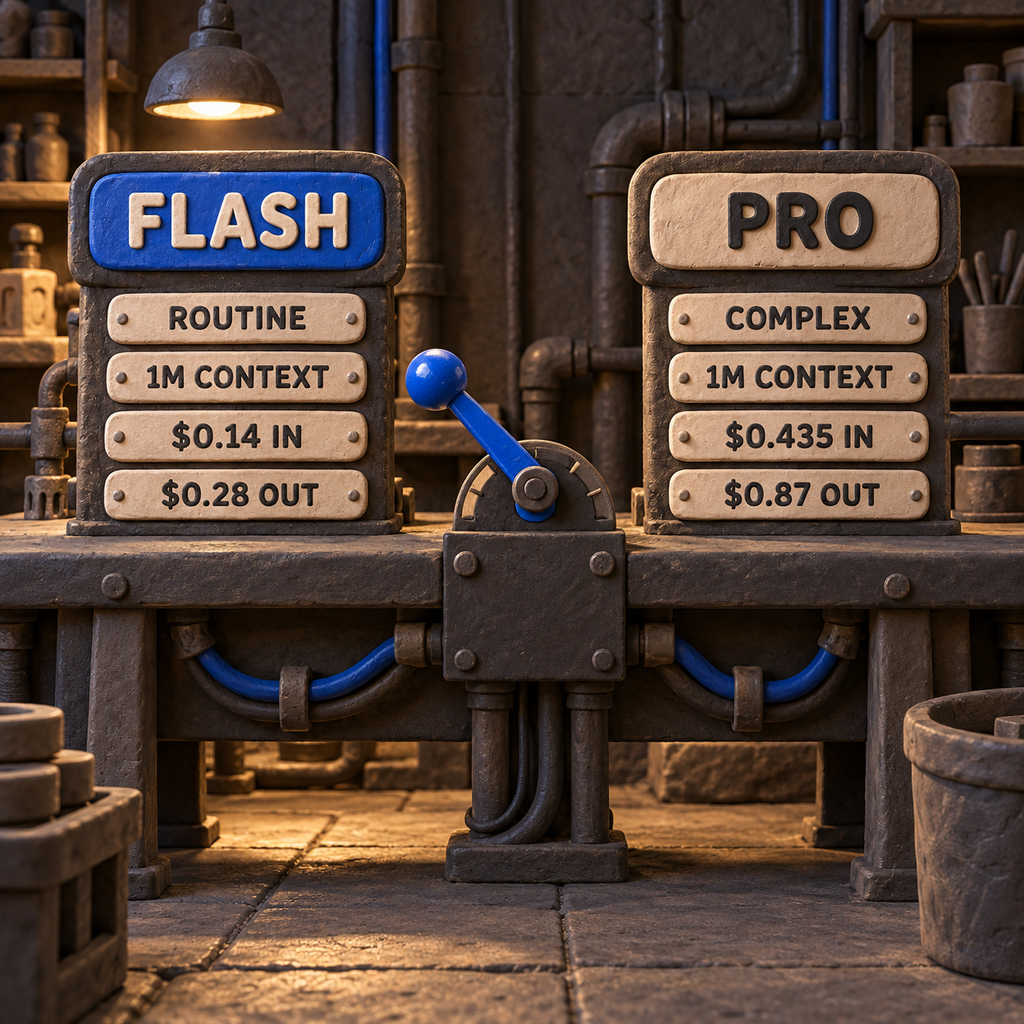
Start with Flash. It has the same listed input modalities, context window, maximum output, and platform rate limits as Pro, but its token prices are lower. Move a task to Pro after a small evaluation set shows that better decisions justify the difference.
Xiaomi says UltraSpeed can produce output up to 20 times faster than Pro at the same quality. Its uncached input and output prices are also 10 times Pro's rates. That is a sensible trade only when response time has measurable business value.
The model bill can be tiny for short classification jobs. Assume one ticket consumes 1,000 uncached input tokens and 200 output tokens. At the published rates, 10,000 tickets would cost about $1.96 on Flash, $6.09 on Pro, or $60.90 on Pro-UltraSpeed. Flash batch processing would cut that assumed model bill to about $0.98.
Those figures are arithmetic scenarios, not a usage result. They exclude retries, web search, storage, monitoring, engineering, and human review. Xiaomi bills overseas web search separately at $5 per 1,000 calls. The budget line that breaks is not support payroll by itself. It is the assumption that every first-pass classification needs a seat in another application or a human touch before routing.
Seven Business Workflows Worth Testing
These are ranked by the clarity of the input, the value of a structured answer, and how safely a team can measure the result before handing the model more control.
1. Support triage for a high-volume queue
A support operations lead could send each new ticket, plus a scrubbed screenshot when needed, to Flash. The model classifies the issue, proposes one next action, and returns text that the routing system converts into fields. The payoff is faster first-pass routing at a model cost that can remain below a dollar per several thousand short tickets. Human agents still own refunds, account changes, and ambiguous cases.
2. Repository maintenance for a software team
An engineering manager could give a coding system a bug report, relevant repository context, test commands, and tool access. Flash handles frequent exploration; Pro takes the cases that fail an evaluation threshold. The payoff is not generic code generation. It is fewer paid assistant seats for a narrow workflow, plus a log of every request and tool action. The catch is that the surrounding system, sandbox, tests, and code review carry more risk than the model call.
3. Long document-pack analysis
An operations analyst could combine extracted contract text, policy pages, and scanned-page images, then ask for exceptions in a fixed schema. The 1 million token context window makes large evidence packs possible, while structured output gives downstream software a predictable shape. The payoff is a shorter first review. It is not legal judgment, and every cited exception still needs a link back to its source page.
4. Visual quality checks for commerce
An ecommerce team could send a product image with its listing text and ask whether visible color, pack count, and claims agree. Flash returns text for a rules engine to accept or queue. The payoff is catching obvious mismatches before publication. The model does not return an edited image, so a separate image pipeline is still required.
5. Recorded-call and screen evidence review
A customer success team could provide audio, a screen recording, and a rubric, then request a text summary of commitments, unresolved blockers, and follow-ups. The native audio and video inputs reduce the number of separate models in the first prototype. The payoff is one review queue instead of separate transcription and visual-check queues. Consent, retention, and sensitive-data rules must be settled first.
6. Desktop research and office-work pilot
An operator who is not ready to build could start in MiMo Desktop, which now includes Pro, Flash, and UltraSpeed. They can test whether the model handles a real research or document task before asking engineering for an integration. The payoff is a cheaper discovery phase. Desktop success does not prove that an automated API workflow will be reliable at volume.
7. Overnight backlog processing
A marketplace or compliance team could send non-urgent classification work through the batch API. Xiaomi prices Flash and Pro batch input and output at half their real-time rates; UltraSpeed is not available there. The payoff is direct and measurable when completion time is flexible. Anything that affects a customer while they wait belongs on the real-time route.
Three Products You Could Build
Best opportunity: a vertical agentic coding assistant
Build a coding agent for one expensive, neglected stack, such as internal Java migration checks or test repair in a regulated repository. Buyers are engineering teams that find general assistants broad but hard to govern.
Demand is visible: agentic ai coding assistant receives about 2,900 US searches a month, carries transactional intent and a $19.04 CPC, and rose 200% year over year in the keyword dataset. GitHub currently lists Copilot Business at $19 per seat per month and Enterprise at $39. That creates a clear buyer benchmark.
The smallest sellable version connects one repository, one issue queue, a sandbox, and a test runner. Use Flash for exploration, promote failed or high-risk cases to Pro, and show the customer cost, latency, patches, and test evidence per task. The moat is the stack-specific evaluation set and controls, not a chat box.
The catch is a crowded market and real security work. A wrapper with no proprietary tests, workflow knowledge, or approval boundary will be copied quickly. This is still the strongest opportunity because the query has the highest qualified demand, transactional intent, and a price anchor buyers already understand.
An open-model coding gateway
Build a routing layer for teams that want an open-source-model option without teaching every developer about model IDs, key types, context limits, and fallbacks. The buyer gets one internal endpoint, policy controls, and per-task comparisons between Flash and Pro.
open source ai coding assistant receives about 1,600 US searches a month, with commercial intent, $2.94 CPC, and 1,977% yearly growth in the suggestion data. The MVP needs authentication, a provider adapter, cost and latency logs, a small coding evaluation, and a basic admin view.
The catch is that an open-source model and a hosted API are different buying decisions. The gateway needs clear data-handling terms and a self-hosted path or another defensible governance feature. Otherwise customers can call Xiaomi directly.
A multimodal document and attachment triage desk
Build an intake product for support, claims, or operations teams that receive long text, screenshots, audio notes, and short videos. It converts files into supported inputs, asks Flash for a structured text decision, and sends low-confidence cases to people.
ai document analysis receives about 1,000 US searches a month. The query has a $10.44 CPC and a top-of-page bid range of $3.23 to $19.87, evidence that vendors value the lead even though the keyword trend is currently down. The MVP is one upload path, one schema, a review queue, and source-linked evidence.
The catch is trust. MiMo's output is text, not a verified decision, and a 1 million token window does not guarantee that every detail receives equal attention. A narrow document class and mandatory human review beat a universal analyzer.
Where MiMo-V2.6 Does Not Solve the Problem
The API gives you a capable engine, not an operating system for your business. It does not define your taxonomy, clean sensitive data, create approval rules, run evaluations, or decide what happens when an answer is uncertain. Those are product and operations jobs.
Do not start with UltraSpeed because it sounds better. Start with Flash and record the evidence. Do not send every file merely because the context window is large. Keep the smallest relevant context and retain source references. Do not confuse structured output with truth. A valid JSON object can still contain a bad decision.
If you use thinking mode across multiple tool calls, Xiaomi recommends carrying prior reasoning_content forward in the message history. If you drop it, you are changing the context the model sees. If you use the web-search capability, budget it separately from tokens.
For a direct model comparison, use MiMo V2.6 Pro vs Flash. The practical rule is still Flash first, Pro after evaluation, UltraSpeed only after latency has a price.
Troubleshooting in the Right Order
- Invalid key: confirm whether the key begins with
sk-,tp-, orttp-. Pair it with the correct base URL. Never print it to logs. - No useful answer in Studio: revise the task, categories, and output requirement before touching the integration.
- Wrong model selection: use the exact lowercase ID
mimo-v2.6-flashormimo-v2.6-pro. - Traffic stalls at scale: compare observed load with the listed 100 requests per minute and 10 million tokens per minute for Pro and Flash.
- Unexpected date behavior: remove the stale December 2025 system date from Xiaomi's current sample. Supply a current date only if the task needs one.
- Tool-call continuity breaks: retain
reasoning_contentacross turns when thinking mode is active, as Xiaomi recommends. - Costs look wrong: separate pay-as-you-go balance, Token Plan credits, token charges, and the independently billed web-search service.
The Monday Move
On Monday, a support operations lead should take 20 fictional tickets, define four categories and one safe next action for each, and test them in Studio with Flash. On Tuesday, an engineer can run the same set through the paid API, save redacted requests and full responses, and compare agreement, latency, and token use. Only then should the team connect a real queue, with a human-review branch left on.
How to use Xiaomi MiMo?
Start in AI Studio with a synthetic version of the job. For an API workflow, create a Xiaomi account, choose pay-as-you-go or Token Plan, create that lane's key, use its matching base URL, and call mimo-v2.6-flash through the OpenAI-compatible or Anthropic-compatible API.
Is Xiaomi MiMo free?
Some Xiaomi surfaces may offer trials or free access, but the production API has published pay-as-you-go prices and paid Token Plans. Read Is MiMo V2.6 Free for the access breakdown.
How much is MiMo per month?
Individual Token Plans list $6, $16, $50, and $100 monthly tiers. Team plans list $16, $50, or $100 per seat per month. Pay-as-you-go has no fixed monthly fee in the published pricing; it draws from a prepaid balance according to token use.
Is Xiaomi MiMo good for coding?
It is designed for coding and agent workflows, and Xiaomi publishes strong benchmark and product examples. The business answer depends on your repository. Run a fixed set of issues and tests against Flash and Pro, then compare accepted patches, latency, and cost.
Is MiMo worth using?
Yes, it is worth a controlled evaluation when low token prices, multimodal input, long context, or an open-source model option matter. It is not worth a rushed rollout without task-specific tests, data rules, and a human fallback.
If you want one of these API workflows built with evaluation, monitoring, and a safe handoff to people, see AI production systems.
- Last Updated
- Sep 22, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI
GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI
Is MiMo V2.6 Free
MiMo V2.6 Flash has a temporary free endpoint. Compare that offer with MIT model downloads, paid API access and desktop plans.Sep 22, 2026AI
Grok 4.7 vs Grok 4.6
Grok 4.7 starts at the same token price as 4.6. Compare access, coding evidence and task costs before moving your workflow.Sep 21, 2026AI
Specification Gaming in Production AI Agents
An AI editor sent 50 of 96 articles off topic. The measured costs, the rules that rewarded drift, and the controls that replaced them.Sep 21, 2026AI