Is Claude API Build Eval Free
See what Claude API build-eval charges for, how cases and repeats multiply usage, and how to price a pilot before a full run.




No: the Claude API build-eval workflow is public, but the evaluation it orchestrates is not automatically free. If you are asking “is Claude API build eval free,” separate the free instructions from the billable work: 24 cases × 3 repetitions × 2 model variants is 144 application executions before any optional judge or retry calls. No funded application pilot was available for this verification, so 144 is arithmetic, not a measured dollar total.
Is Claude API Build Eval Free?
The workflow files are free to read; an executed evaluation can consume paid model usage in three different places. Claude Code may draw from a subscription allowance or a metered account, the application under test calls its own model provider, and an optional model judge makes another set of calls. A deterministic local grader avoids the third bill, but not the application calls.
That distinction matters because build-eval is not a pool of free evaluation credits. It is a guided Claude Code workflow for constructing an evaluation around the application you already have. It helps identify the entry point, assemble cases, choose a grader, write or adapt a runner, and produce reviewable results. The public implementation is available in Anthropic's skills repository, but the calls made by the resulting runner follow the billing rules of the account and provider they use.
The safe answer is therefore conditional: designing the eval can be free; executing it is free only when no billable calls occur or all usage fits inside an allowance you already pay for. Even then, “free” describes the marginal invoice, not unlimited capacity.
What Changed on September 28 and 29
Anthropic turned eval construction and iterative optimization into two explicit Claude Code workflows. The September 28, 2026 guide introduced /claude-api build-eval for creating an evaluation and /claude-api hillclimb for improving an application against it. The implementation landed publicly on September 29 at 02:20:03 UTC in commit 8a1541c4.
build-eval starts from one application flow. It reads the existing entry point, asks where representative cases should come from, proposes the cheapest grader that measures the output correctly, and requires clear approval of both the inputs and the grading method. The result is code and evidence in your repository, including a runner, results.jsonl, traces, and a report.
hillclimb comes later. It splits cases into train and held-out test sets, changes one allowed surface at a time, runs the evaluation again, and reverts changes that regress or improve only the train split. That can improve prompts, model selection, effort, tools, or application wrapper code, but each attempted variant means more executions.
The durable change is not “evals are now free.” It is that Claude Code can assemble a disciplined, auditable evaluation workflow without forcing a separate framework. The payment model underneath that workflow did not disappear.
Claude Build Eval Cost Has Four Billing Surfaces
A useful budget keeps four surfaces separate because only one of them is plainly free. Collapsing them into one “Claude cost” makes it impossible to explain where the money went.
- The public workflow. The guide and skill files are public. Reading them, reviewing the generated local files, and running a local deterministic check do not create Claude API token charges by themselves.
- Claude Code orchestration. Claude Code reads the repository, interviews you, writes the runner, and helps inspect results. Subscribers consume plan allowance; API-authenticated sessions consume metered tokens. The session cost shown to API users is an estimate, while subscription users see plan usage instead, as Anthropic's Claude Code cost documentation explains. The current plan and authentication details live in the site's Claude Code pricing guide.
- The application under test. The runner should call the existing application entry point rather than reconstructing a simplified model request. Every support ticket, retry, tool loop, and repetition therefore consumes the provider and account the application already uses.
- The grader. A fixed label, schema check, unit test, or end-state assertion can run locally. Open-ended answers may need a pointwise or pairwise model judge, which adds its own input, output, cache, and possible tool usage.
The first place to save money is not a cheaper judge. It is choosing a programmatic grader whenever the output has a constrained correct shape. A support router that must return one queue from a fixed list can be checked with code. Asking another model whether billing equals billing spends money to answer a deterministic question.
Use a model judge when the property genuinely needs judgment, such as whether an escalation summary preserves the customer's urgency without inventing facts. Even then, keep application and judge usage in separate fields. A cheap judge can hide an expensive application run, and the reverse is also true.
The Numbers: 24 Cases Become 144 Application Executions
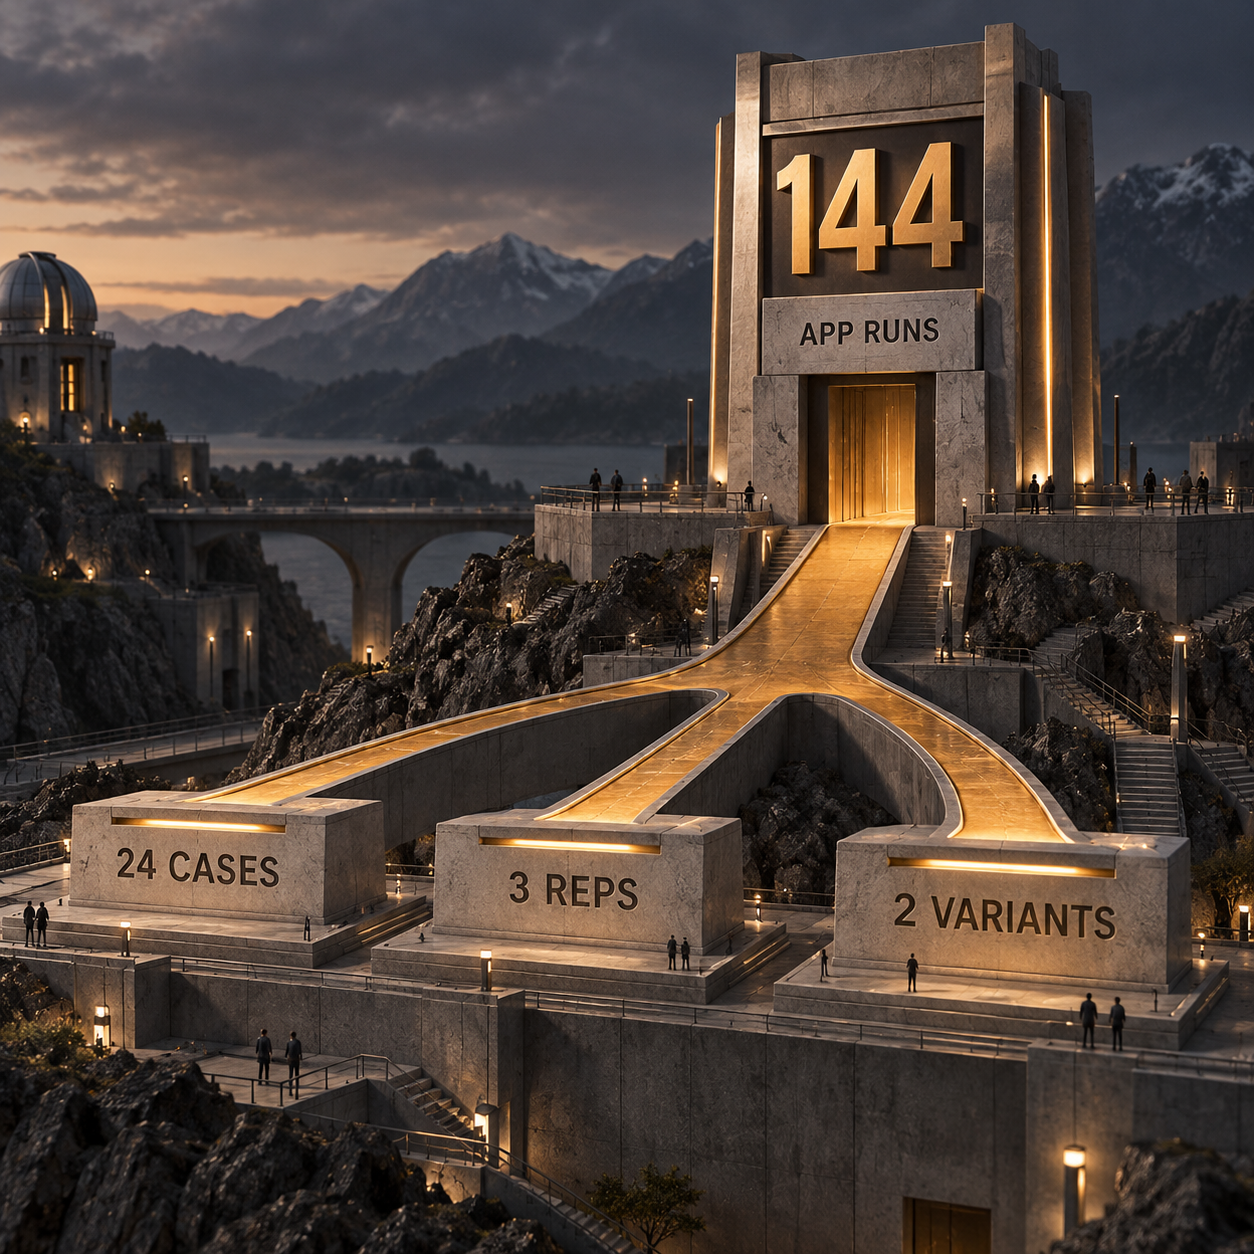
Case count is only the first multiplier. Anthropic's launch guide shows an inbox-routing example with 24 inputs. If you compare 2 model variants and repeat each case 3 times, the application execution count is:
24 cases × 3 repetitions × 2 variants = 144 application executions
That is the execution floor for this design, before a model grades anything and before a failed request retries. Repetitions matter because a model can produce different answers for the same input. Variants matter because a comparison needs outputs from both configurations.
The grader changes the next multiplier:
- Programmatic grader: 0 model-judge calls. The run remains 144 application executions.
- Pairwise judge: 72 judge calls if one call compares the two variants for each case and repetition, because 24 × 3 = 72 pairs.
- Pointwise judge: 144 judge calls if every application output is graded separately. That makes 288 model calls in total, 144 application plus 144 judge, before retries or Claude Code's orchestration usage.
Hillclimbing adds another dimension because each round runs a new candidate. A loop that tries several patches can spend several full evaluation passes even when every losing patch is reverted. Set a round ceiling and a spend ceiling before optimizing. “Stop when the score improves” is not a budget because noisy scores can keep the loop searching.
Claude API Eval Pricing Starts With Measured Usage
A case has no fixed price, so the only defensible estimate starts with a paid pilot's actual usage fields. One ticket may be a single short classification call. Another may trigger a long context, several tools, retries, and a judge. Pricing both as “one eval case” hides the difference that drives the invoice.
Anthropic's direct API rate card was verified on September 29, 2026. Prices below are per million tokens:
Source: Anthropic's live Claude API pricing page. Use the provider's own rate card for Amazon Bedrock or Google Cloud rather than copying these direct API prices.
For each pilot row, calculate:
application fresh input + application output + application cache writes + application cache reads + judge fresh input + judge output + judge cache writes + judge cache reads + paid server-side tools
Multiply each token bucket by the rate for the model that produced it. Do not collapse cache tokens into fresh input. The generic shortcut says a 5-minute cache write costs 1.25 times input and a read costs 0.1 times input, but the current card has important read exceptions: Fable 5.1 is 0.025 times its input rate and Opus 5.5 is 0.05 times. A copied 0.1 multiplier would overstate both.
The same discipline applies to the judge. If the application uses Sonnet 5.5 and the judge uses Haiku 4.5, price each from its own usage and rate. If the application is on a contracted cloud rate, use that contract. If a server-side tool charges per operation, add it separately. Client-side tools still expand the model context and therefore the token bill.
No measured dollar figure appears here because this publication run had no application entry point, provider account, or approved funded pilot. Inventing a token count would produce a neat number and a useless budget. The rate table is verified; the run total must wait for measured usage.
Claude Code Build Eval: Price a Five-Ticket Pilot First
The smallest useful move is a five-ticket pilot through the existing support-router entry point, followed by a row-level usage inspection. Five is not enough to certify production quality. It is enough to prove that the runner, grader, trace, and cost accounting are wired correctly before multiplying the mistake across a full suite.
Use five synthetic tickets that exercise different routing behavior without copying customer data:
- A customer cannot open the billing portal.
- A card appears to have been charged twice.
- A customer asks whether an annual plan is refundable.
- A production outage needs an urgent escalation.
- An enterprise buyer asks for a contract amendment.
Those cases are a proposed pilot set, not a reported test. They should enter the same function, endpoint, or script the production router uses, with external side effects isolated. If the live flow can send email, change a database, or page an engineer, replace only that side effect with a test fixture. Keep the prompt assembly, model call, tools, retries, and response parsing production-equivalent or the pilot prices the wrong system.
Confirm the entry point and billing identity
Record the application function or endpoint, model, provider, account, prompt, tools, and output shape. Also record how Claude Code itself is authenticated. This separates plan allowance from application API usage before either starts.
Approve the five inputs and the grader
Review every synthetic ticket and approve the expected route. For a fixed queue label, use a programmatic grader. Add a model judge only for a property that code cannot check, and never let the model under test judge itself.
Run one funded pilot
Run 5 cases × 1 repetition × 1 application variant, which is 5 application executions. The released workflow requires a clear yes before the first paid pass. If there is no approved budget, stop here with a runnable dry setup rather than claiming a price.
Inspect the row, not the console headline
Open
results.jsonland a trace. Confirm that successful rows carry a non-emptymodelandusage, that the entry point exposesstop_reason, and that application and judge usage are distinguishable. Cache-write and cache-read fields must be preserved instead of folded into input. A zero that should not be zero is a runner bug, not a free call.Price and approve the full shape
Calculate the five rows at the actual provider rates, report the minimum, median, and maximum per case, then multiply the approved case and repetition counts. Add the chosen grader shape, retries, and hillclimb ceiling. Present that formula before asking for approval of the full run.
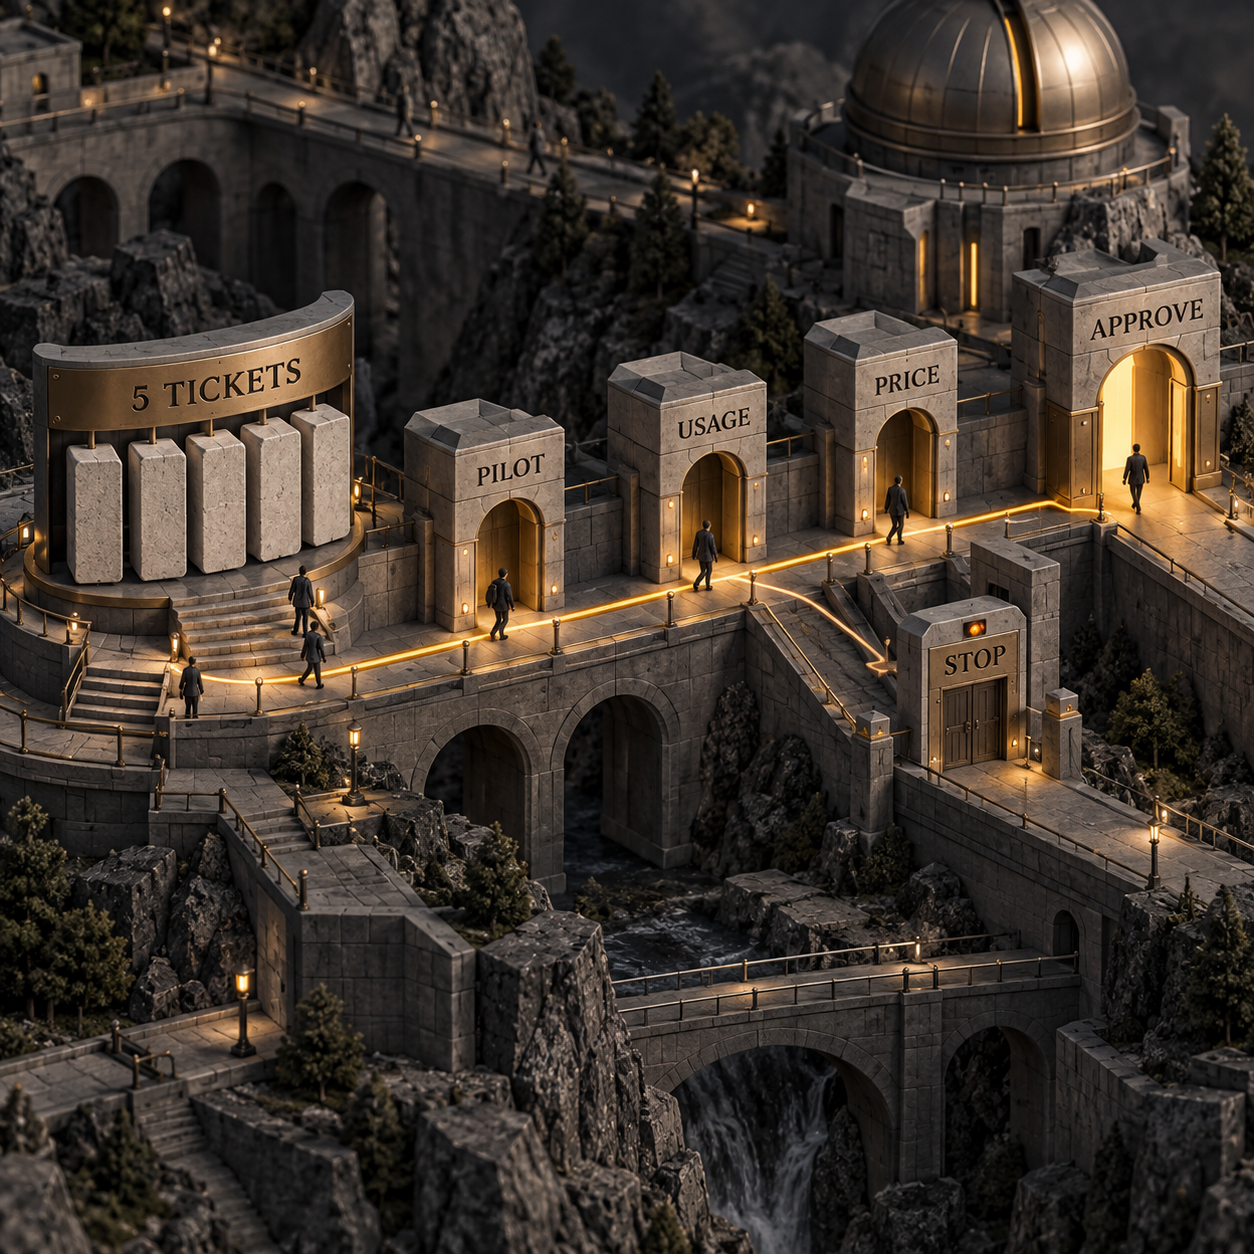
This ordering follows the released implementation: measure one funded pilot, inspect its usage, and only then estimate the suite. Historical averages are not a substitute because cache state, tool loops, effort, retries, and output length belong to this application, not an average one.
What It Means for Builders, Operators, and Buyers
Builders should make cost observable at the application boundary. If the entry point hides model, usage, or stop_reason, add those fields to its final event before writing the full runner. Preserve provider-native cache fields and attach judge usage separately. The wall every team hits is a polished report backed by incomplete rows: once the full run finishes, missing token buckets are often impossible to reconstruct.
Operators should own the multiplication and the approval gate. Ask for cases, repetitions, variants, grader calls, retry policy, and maximum hillclimb rounds on one page. A budget with only “24 cases” is incomplete. A budget with 144 application executions, the grader shape, measured per-case usage, and a stop ceiling is reviewable.
Buyers should ask which layer a quoted price includes. Does it include Claude Code orchestration, the application model, the judge, cloud-provider markup, tool charges, retries, and optimization rounds? A vendor can honestly quote a cheap judge while excluding the application runs that dominate spend. Require the pilot rows and formula, not just a total.
Who Should Act Now, Wait, or Stay on the Plugin Path
Act now if the application has one stable entry point, a decision you need to make, and five representative cases you can safely review. A prompt migration, model change, routing-policy revision, or tool change is a good target because the evaluation can compare a concrete before and after.
Wait if the runner cannot call production logic safely. First isolate database writes, outbound messages, destructive tools, and mutable external state. Also wait if nobody can approve the inputs or grader. More executions cannot rescue an evaluation that measures the wrong task.
Stay with the native plugin path if the question is whether a Claude Code plugin adds value. That workflow compares WITH-plugin and W/OUT-plugin sessions by design. The site's guide to testing Claude Code plugins with evals covers that separate control. Application build-eval is for the app entry point, not for replacing the plugin control with a generic benchmark.
You are unaffected if you already have a trusted runner and grader. Reuse them. The public implementation explicitly favors adapting existing pieces over replacing them with a new framework. The useful addition may be the approval discipline, usage capture, or hillclimb loop rather than a new test stack.
What Is Overhyped
The workflow reduces setup friction; it does not make evaluation automatic, objective, or free. Claude can propose cases, but a person still has to decide whether they represent production. It can propose a grader, but a person still has to verify that an oracle passes, a null answer fails, and a model judge is not rewarding style over correctness.
Hillclimbing is also not a free optimizer. It deliberately runs more variants, reads failures, proposes patches, and evaluates again. The held-out split protects against one kind of overfitting, but it does not remove the need for enough cases, enough repetitions, or a spend ceiling.
The report is evidence only when its rows are complete. A beautiful report.html beside empty usage fields cannot answer the cost question. A dollar total derived from assumed token counts is not better. The defensible deliverable before a funded pilot is an execution plan and current rate card, with the measured total left blank.
The Monday Move
Give one owner a bounded pilot, not an open-ended instruction to “build evals.” On Monday, choose the support router's existing entry point, write the five synthetic tickets above, and use a fixed-label programmatic grader. Review the inputs and expected routes with the operator who owns support policy.
Then ask for approval to run exactly 5 application executions. Inspect results.jsonl, one trace, every usage bucket, and stop_reason. Price those rows at the actual provider rate. Only after that should you propose the 24-case, 3-repetition, 2-variant shape and its judge, retry, and hillclimb ceilings.
The decision rule is blunt: no complete pilot usage, no full-run budget approval.
- Last Updated
- Sep 29, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

How to Use Shopify WebMCP Checkout
Use Shopify WebMCP checkout tools to read and update a checkout, handle payment handoffs, and submit only after the buyer confirms.Sep 29, 2026Build
How to Use Cloudflare cf CLI
Install Cloudflare's cf CLI, authenticate, find commands, and test a Worker workflow with JSON output and the right Wrangler fallback.Sep 29, 2026Build
Krisp Review
Krisp reviewed for business calls: noise cancellation, routing, pricing, and the checks that show when your meeting app is enough.Sep 29, 2026Build
SaneBox Pricing
Compare SaneBox pricing by email accounts, features and billing term, with the full upfront bill and a clear rule for when to upgrade.Sep 29, 2026Build
Marblism Pricing (2026): Budget Tasks, Not Seats
Calculate Marblism pricing from fixed task charges, shared hours, billing terms, and exactly what stops when the allowance runs out.Sep 28, 2026Build
Fyxer Pricing
See Fyxer pricing for one or several inboxes, the real annual team bill, and the time its drafts must save to earn the subscription.Sep 28, 2026Build
Is Cloudflare Worker Previews Free
Check Worker Previews' free-plan limits, Workers usage and separate storage or agent costs before budgeting branch tests.Sep 28, 2026Build