Mistral Large 4: Pricing, Open Weights, and When to Use It
Mistral Large 4: verified API prices, the launch offer, claimed benchmarks, and when to test the preview or wait for self-hosting.
Mistral Large 4 is worth a hosted pilot for security and document-heavy work, but buyers who require self-hosting should wait for the weights Mistral promises by the end of October 2026. Its announced API price is $1.36 per million input tokens and $4.18 per million output tokens; the current 50% launch offer lowers those to $0.68 and $2.09. Keep an adequate cheaper model in place and judge Large 4 by the cost of accepted work.
Release, pricing and deployment documentation verified on 7 October 2026. The launch specification and benchmark claims below come from Mistral's announcement; current charges come from its version-specific API price sheet. The document budget is an explicit calculation, not measured spending or a claim that this model has been tested here.
Mistral Large 4: What Changed on 6 October
Mistral shipped a hosted public preview on 6 October 2026, with downloadable weights still promised for later. That changes your evaluation shortlist now. It does not yet give an enterprise buyer a model they can download and run inside their own infrastructure. Mistral's stated target is the end of October, with more architecture and post-training details accompanying the weights. Source: launch announcement.
As the announcement states it, Mistral Large 4 has 1T total parameters and 49B active parameters, with a hybrid instruct-and-reasoning Mixture-of-Experts architecture and multimodal input. Parameters are the numerical values the model learns; a Mixture-of-Experts, or MoE, activates selected parts of the model for each token rather than using every parameter for every step. Hybrid instruction and reasoning means ordinary instruction-following and more extended problem-solving belong to the same model. Multimodal input brings visual material into the workflow, which matters for charts, engineering drawings and evidence inside documents. These are the announcement's specifications, not a hardware-sizing guide. Source: Mistral's model description.
The confirmed route today is Mistral Studio and its preview API, the developer platform associated with La Plateforme. Use mistral-large-4-0 to identify this version in an evaluation. The version card also lists the shorter mistral-large-4 name and support for chat completions, structured outputs, function calling and document question-answering. Structured output lets an application request a defined response shape; function calling lets it request an action from a tool your application exposes.
The launch announcement directs readers to Studio. It does not establish that this exact preview model is selectable in Le Chat or Vibe. A consumer subscription and a version-specific developer endpoint answer different buying questions, so use the API route when you need a reproducible model evaluation.
There is a specification discrepancy to keep visible: the current version card lists 1.05T total and 52B active parameters, while the announcement says 1T and 49B. Those are two vendor descriptions, not a reason to silently substitute one for the other. The launch figures above are explicitly attributed to the announcement; the final architecture and deployment requirements need checking again when the weights arrive. Source: current version card.
Mistral Large 4 Price: List Rates and the Launch Offer
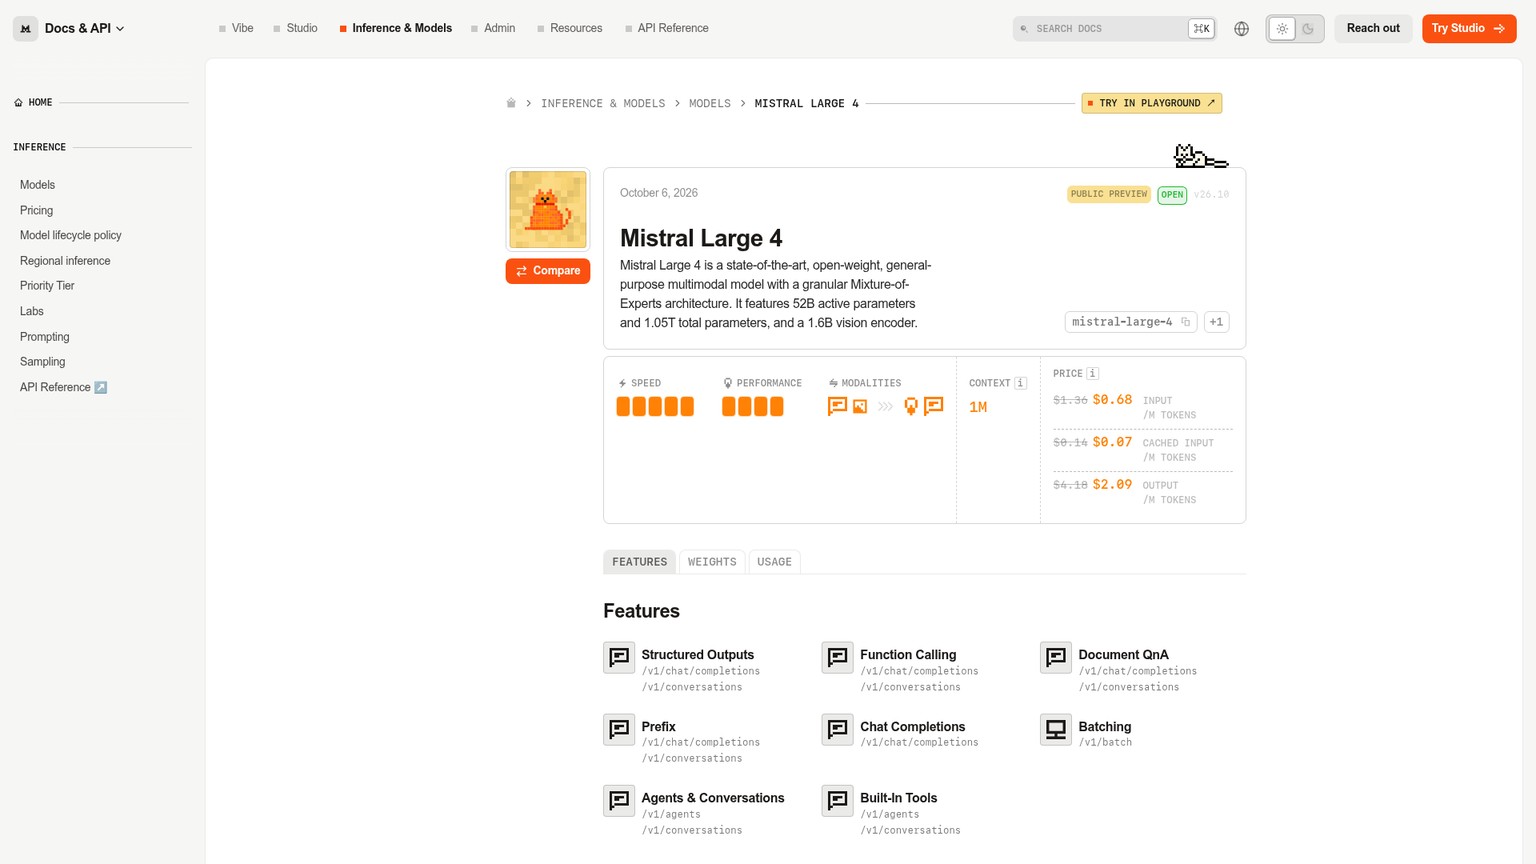
Budget continuing work at $1.36 input and $4.18 output per million tokens; use the lower rate for an eligible launch pilot. Tokens are the units the model processes: input includes your instructions and supplied material, while output is the generated material charged by the service. The two sides have different prices, so a single blended number can conceal an expensive answer-heavy workload.
Mistral's announcement carries the list rates. Its current Standard price sheet, with regional inference switched off, marks Large 4 as a sale and strikes through the original rates. All figures here are US dollars per million tokens. Sources: announcement, API pricing.
The same sheet lists cached input at $0.14 normally and $0.07 during the sale. Cached input is previously processed material that qualifies for reuse at the lower charge. A document being submitted for the first time should stay in your fresh-input estimate. Source: API pricing.
The Offer Has a Duration, but No Published Calendar Cutoff
Mistral states a 50% launch discount for two weeks. Its release changelog supplies that duration; the model card and price sheet supply the discounted dollars. The public documents checked for this guide do not give an exact calendar expiry, cutoff time or timezone. An authenticated console price was unavailable because the pricing screen required login. There is no verified date to print as the offer's last day: confirm it in your own console before scheduling work around the promotion.
For a procurement forecast, use the original rates and treat the offer as temporary. That avoids turning a cheap evaluation month into an understated ongoing budget.
Also avoid applying the generic $0.50 input and $1.50 output example on Mistral's public pricing page to Large 4. Those figures match the Mistral Large 3 row in the version-specific sheet. Model family names do not identify a current version's price. Our Mistral pricing guide carries the full model list and the separate subscription options.
A Document Month Costs $48.10 at List Price
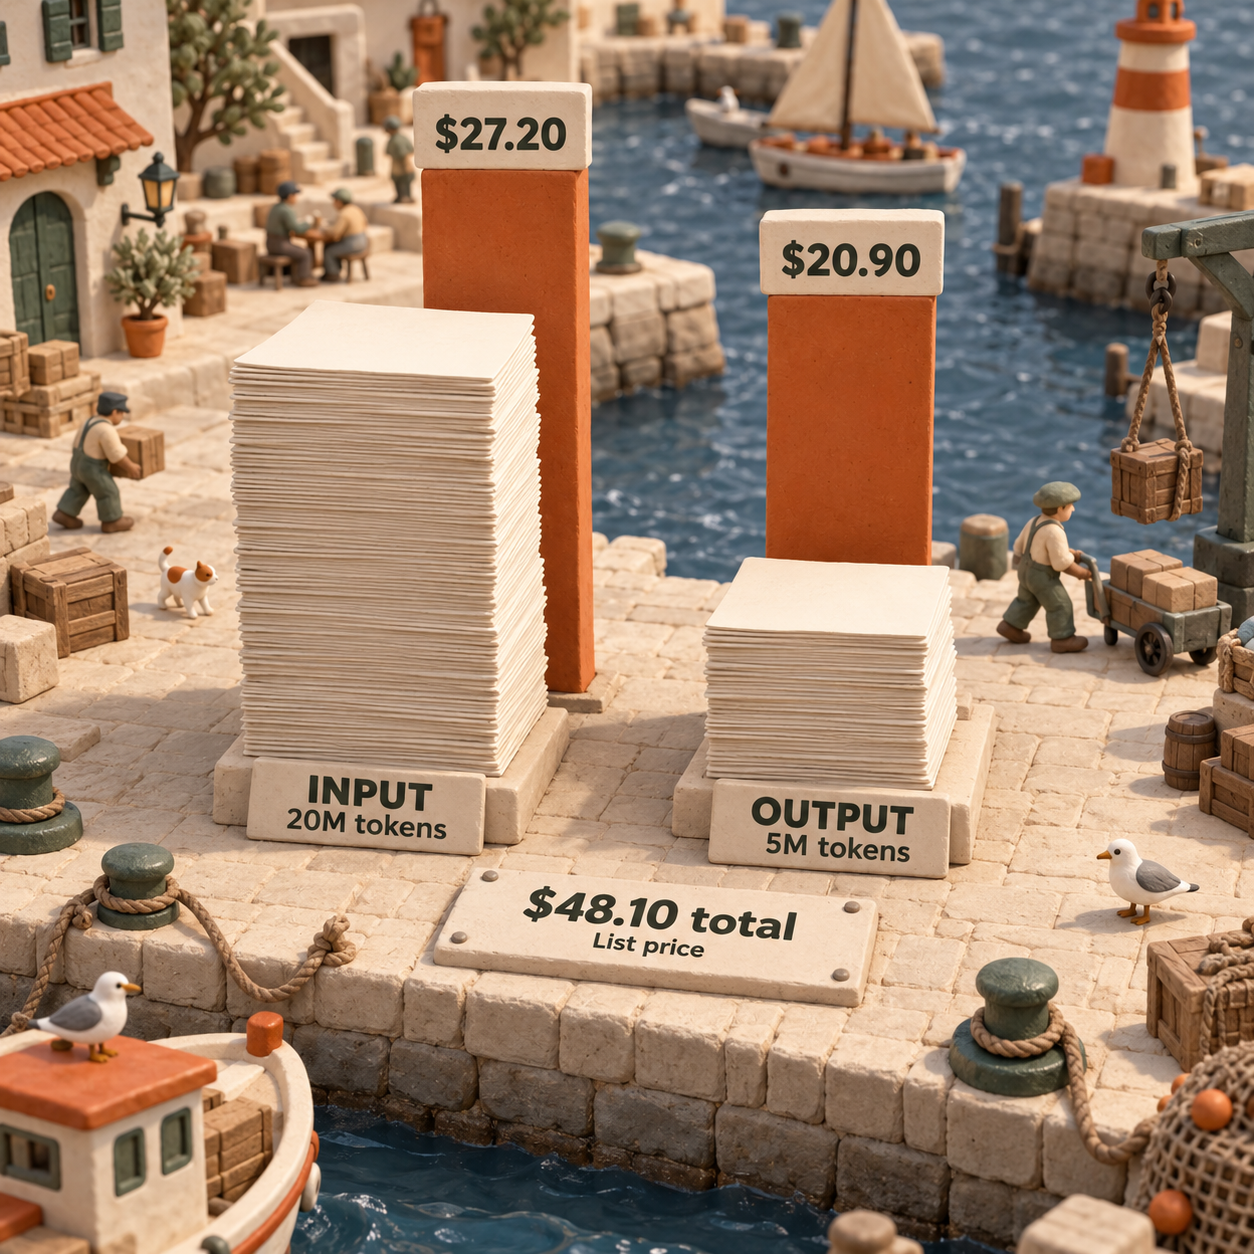
A stated workload of 1,000 document-review jobs costs $48.10 in Large 4 model charges at list rates. Assume each job averages 20,000 fresh input tokens and 5,000 billed output tokens, including every model call counted toward that job. The month therefore processes 20 million input tokens and 5 million output tokens. This is an illustrative usage budget, not a conversion from page counts or a measured deployment.
The calculation is:
- Input: 20 × $1.36 = $27.20.
- Output: 5 × $4.18 = $20.90.
- Total: $27.20 + $20.90 = $48.10.
While the launch offer applies, the same fixed volume costs 20 × $0.68 + 5 × $2.09 = $24.05. These estimates exclude tax, credits, document-processing and tool charges, and any extra model usage beyond the stated token totals. The inputs come from Mistral's price sheet; the arithmetic is ours.
Output is only 20% of this example's token volume but about 43% of its list-price bill. A workflow that generates long investigations or repeatedly rewrites a report can change the total faster than its input size suggests. Count the usage returned by the service across the whole task, rather than budgeting only the final paragraph the user sees.
The Cheaper Model Sets the Adoption Hurdle
Mistral Small 4 costs $6 for the same fixed token volume, using its listed $0.15 input and $0.60 output rates: 20 × $0.15 + 5 × $0.60. That is a price baseline, not a claim that the models complete the same tasks equally well. Large 4's list-price premium is $42.10 per month; during the promotion, it is $18.05. Source: current model rates.
If a founder internally values reviewer time at $60 an hour, or $1 a minute, Large 4 needs to save 42.1 minutes of correction work over the month to offset the list-price model premium in this example. That is the crossover to measure. The assumed labor value is yours to replace, and actual token consumption can differ between models.
The same point holds for engineering leads: a larger model earns its route through fewer rejected answers, less correction work or a required deployment boundary. A low token price alone does not establish low cost per accepted result, and a launch discount should not decide the permanent architecture.
What the Benchmarks Establish
Mistral's results justify an evaluation shortlist; they do not establish a winner for your workload. A benchmark is a defined set of tasks run under particular conditions. Coding-agent scores involve tools and execution environments, not just a model answering a short prompt. Visual grounding measures locating something in an image. Those distinctions decide whether a result is relevant to your application.
The following are Mistral's own claims in its 6 October announcement, including scores it attributes to external benchmark systems. They are not results produced by this site, and percentages from different tests are not interchangeable.
Source for all table entries: Mistral's launch evaluation. Elo is a comparative rating, not a percentage of jobs completed correctly. Likewise, a security benchmark score is not a guarantee that an agent will resist every malicious document it encounters.
For professional work, Mistral claims leading open-model performance on Harvey's Legal Agent benchmark, and highlights Vals.ai Finance Agent v2 and FinWorkBench, also called Finch, for finance and spreadsheet work. It also claims open-model leadership on SciCode-Verified, a scientific-programming evaluation. These are useful reasons to choose legal, financial or scientific cases for a pilot. They do not replace checking each answer against the supplied evidence. Source: Mistral's domain evaluations.
One Independent Read: Artificial Analysis, 6 October 2026
Artificial Analysis published its own evaluation on 6 October 2026, reporting 38 on its Intelligence Index and 50 on its Cyber Index for Mistral Large 4 Preview. It calculated $1.13 per Intelligence Index task at standard pricing, falling to $0.57 with the launch discount. Those are that benchmarker's measured-task costs, not the price of one customer document or one API call. Source: Artificial Analysis's dated report.
The independent result supports treating this as a credible specialist candidate, while its cost-per-task finding makes output consumption worth measuring. It does not provide an automatic migration verdict. There is no site-run ranking against GPT-6 or Claude here: the decision below rests on verified deployment terms, stated prices and acceptance checks you can apply to your own work.
Mistral Large 4 Review: Who Should Test It This Month
Test Large 4 when a named failure in your current route matters enough to pay for a better accepted result. Leave successful inexpensive routes alone. That gives builders, operators and enterprise buyers different reasons to act, even though they are looking at the same release.
Builders: Add a Route for the Difficult Cases
A funded founder should pilot one difficult workflow before changing the default model. For example, a document assistant may handle ordinary field extraction cheaply but struggle when evidence spans charts, footnotes and conflicting exhibits. Put that subset into the evaluation and measure whether Large 4 reduces corrections. Its multimodal and tool-use claims make the question reasonable; only your acceptance results decide the route.
A solo technical builder whose existing model already returns acceptable classifications has little reason to switch. Keep the smaller route and retain Large 4 as a candidate for a task that fails it. For agent-model alternatives, the compact coding models guide gives a narrower starting point than replacing every call with a new flagship.
Operators: Security and Evidence-Heavy Documents Come First
A security lead has a concrete reason to test authorized defensive work. Mistral names malware analysis, vulnerability prioritization and detection-rule writing, alongside vulnerability reproduction and patching. A useful pilot asks whether the proposed patch addresses the supplied issue and whether the resulting detection rule matches the evidence. Keep the allowed actions explicit and review the output before it changes operational systems. Source: Mistral's cybersecurity section.
For a legal operations lead, use an approved document set and score whether an answer identifies the controlling passage, preserves exceptions and distinguishes evidence from inference. For a finance operator, score whether the answer uses the right period, reproduces the calculation and traces each input to the source document. A polished memorandum with the wrong clause or period is rejected work, regardless of the benchmark behind the model.
Mistral also names engineering drawings, manufacturing, geospatial imagery and scientific programming. These are separate evaluation tracks: identifying a component in a technical drawing, finding an object in satellite imagery and implementing a scientific routine need different acceptance criteria. The release makes them candidates; it does not prove one general score transfers to all three. Source: Mistral's capability deep-dive.
Enterprise Buyers: Verify the EU Boundary You Are Buying
EU data-location requirements are a reason to shortlist Mistral, then verify the exact service boundary. Mistral says the public preview runs on its own European datacenter infrastructure. Its general regional-inference documentation separately says the global endpoint does not commit to a specific processing location. Those statements should not be flattened into a universal guarantee for every Mistral request. Sources: preview infrastructure, regional inference.
The regional route is api.eu.mistral.ai. Check that the required model is actually available there, because regional model availability varies. Its region table describes datacenters in EU and EFTA countries; EFTA is the separate European Free Trade Association. A strictly EU-only requirement therefore needs confirmation of the permitted processing locations. Mistral lists a 10% surcharge on standard list pricing for regional inference; do not assume it stacks with the launch promotion without confirming the applicable quote. It also says regional endpoints do not provide Agents, Batch or the Files API, and function calling is the only supported regional tool. Source: regional features and pricing.
That matters for a CTO planning a document agent: the global model card's feature list does not establish that the same managed workflow runs through the regional endpoint. Request-and-response processing geography also does not regionalize every account, billing or usage record, and it is separate from zero data retention. Verify the processing, storage and tool dependencies your particular system needs before moving regulated material.
What Changes When the Weights Arrive
Weights would add deployment control, with a new infrastructure and operating-cost decision. Open weights are the downloadable numerical model files. They can create a path to running inference under your own policies instead of depending entirely on a hosted endpoint, subject to the actual license and supported software. Mistral's stated release target remains the end of October 2026; the announcement does not promise a particular day. Source: release plan.
For an enterprise buyer, the useful change is the possibility of choosing the execution environment, access boundary and operating procedures. That can matter when a hosted-service policy or availability change would interrupt a critical workflow. It also moves responsibility for capacity, upgrades, monitoring and failure recovery toward whoever operates the deployment.
49B active parameters does not make this a 49B-sized download or memory plan. Active parameters describe the computation selected for a token. The total weights still have to be stored and made available to the serving system. The eventual weight format, supported runtimes, hardware arrangement and concurrency requirements determine what self-hosting actually needs. No precise hardware recommendation or hosting price follows from the launch headline.
Build the future comparison around infrastructure cost divided by successfully completed work, plus operational labor and the value of the required control. A lightly used deployment can carry idle capacity costs; a busy one can spread them across more tasks. Neither situation establishes that self-hosting will be cheaper than the API.
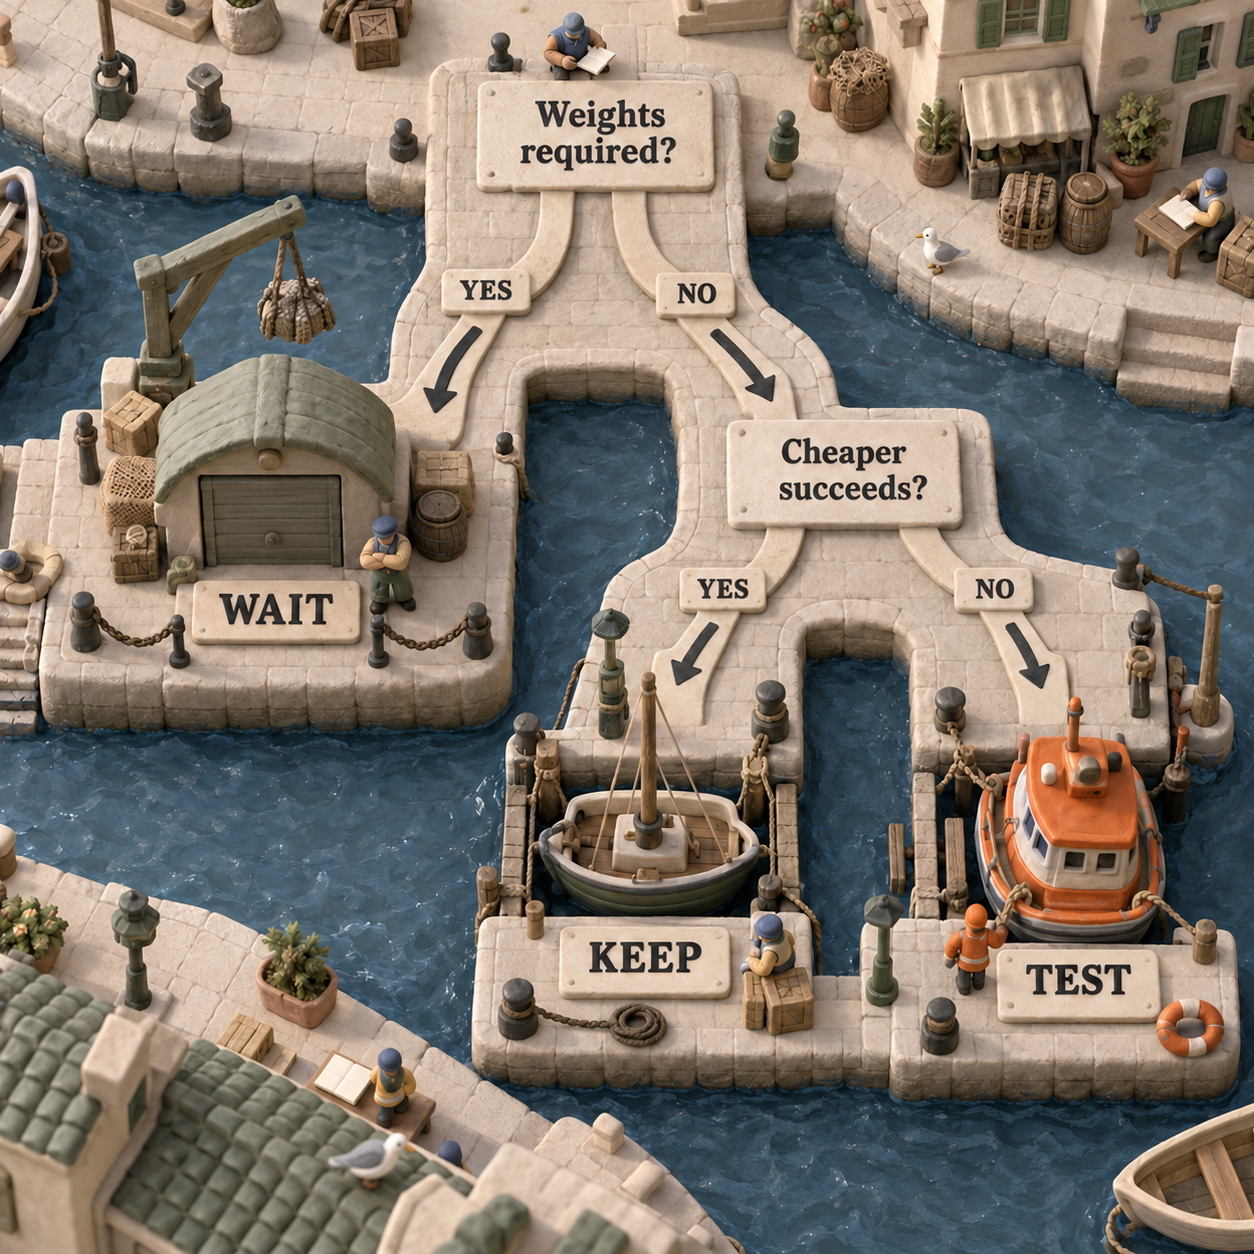
If downloadable weights are mandatory for procurement, wait for the artifact, its license and a deployment you can validate. You can prepare the evaluation set and integration boundary now. The hosted preview can answer capability questions only where your data policy permits using it; it cannot satisfy an on-premises requirement by promise alone.
What Is Overhyped
The overreach is treating three separate milestones as one: preview access, a future weights release and a production deployment. They answer different questions. Today's API lets you evaluate the preview. The promised weights may enable another operating model. A deployable, licensed, supportable system still needs its own verification.
An open-weight description does not establish a particular open-source license or unrestricted commercial rights. Check the terms supplied with the actual Large 4 release rather than importing a license from an earlier Mistral model.
The benchmark charts also do not establish universal superiority. Security refusals, tool access, execution environments and task definitions can affect scores. A legal benchmark does not certify legal advice; a spreadsheet benchmark does not settle whether your reporting workflow preserves the right evidence. Use the relevant claim to select a test, then score the deliverable you need.
Expanded cybersecurity access is another boundary. Mistral says cybersecurity leaders, vetted partners and state authorities receive reduced moderation and expanded cyber capabilities during red-teaming. That does not promise every public-preview customer the same access. Evaluate the permissions and behavior available to your account. Source: preview access description.
Finally, the sale rate can make the pilot look cheaper than the sustained route. A temporary model-price saving says little about migration effort, reviewer time or future self-hosting economics. Keep those decisions grounded in the permanent rates and the actual operating boundary.
Your Next Move: A Bounded Pilot
Next week, an engineering lead should route a small, approved evaluation set to mistral-large-4-0 and keep production traffic on the current accepted route. An enterprise buyer requiring weights should prepare the same cases and wait to approve a self-hosted deployment until the promised artifact and terms exist.
Choose representative cases and define acceptance
A suggested starting set is 50 representative cases, including difficult examples your current route gets wrong. This is a practical pilot size, not a statistical guarantee. Define correctness, required evidence and allowed actions before seeing outputs. For legal and finance work, have a qualified reviewer score the source grounding and calculations.
Use the version-specific model and the permitted endpoint
Try the hosted preview in Mistral Studio, or call the documented chat-completions API with
mistral-large-4-0. Hold the supplied evidence and tool budget consistent across candidates. Check regional model and feature availability first if geography is a requirement.Measure accepted work and forecast the ongoing bill
Record accepted results, corrections, total input and billed output, latency, tool usage and reviewer time. Apply list rates to the forecast. Keep the route only if the gain pays for its premium or supplies a required capability or control. Recheck the model, license and operating cost when the weights actually arrive.
For a basic global-endpoint smoke check, with your own Mistral API key already set in MISTRAL_API_KEY, the documented chat-completions route is:
curl https://api.mistral.ai/v1/chat/completions \
  -H "Authorization: Bearer $MISTRAL_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "mistral-large-4-0",
    "messages": [
      {"role": "user", "content": "Explain the difference between input and output tokens in two sentences."}
    ]
  }'
That checks connectivity and model selection, not document quality or regional compliance. The adoption decision comes from the approved workload and its accepted results.
Get practical model and workflow decisions in the newsletter.
- Last Updated
- Oct 7, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Lindy AI Review (Verified October 2026)
Lindy AI review: current plans, credit costs, email and meeting setup, integration limits, and when Gumloop, n8n or Marblism fits better.Oct 7, 2026AI
Mistral Pricing (2026): API Costs and Vibe Seats
Mistral API rates, Le Chat and Vibe plans, free limits, EU hosting costs and a worked monthly bill. Verified October 2026.Oct 6, 2026AI
Claude Skills
Use Claude Skills across the apps, Claude Code and API. Build a weekly client-report skill file by file, then install and share it.Oct 6, 2026AI
AI Employee: What It Does, Costs, and How to Start
What AI employees can do, current prices for six tools, and how to pick one role, keep human review and measure a 30-day pilot.Oct 6, 2026AI
Wispr Flow Alternatives (2026): VoiceOS, Superwhisper, Aqua Voice, Willow and Monologue
Compare VoiceOS, Superwhisper, Aqua Voice, Willow and Monologue by work task, current price, offline privacy, team controls and coding-agent input.Oct 5, 2026AI
AI Agent Examples: 13 Small Business Jobs and What They Cost
13 AI agent examples for small businesses: what runs the job, what a person checks, and current prices from Tidio, Vida, MindStudio and more.Oct 5, 2026AI
Claude API Pricing (2026): Model Rates and Three App Budgets
Claude API model, cache, batch and tool costs, verified October 2026. Three app budgets and when Pro or Max costs less for personal work.Oct 4, 2026AI