OpenAI API Pricing (2026): GPT-6.1 Sol and Three App Budgets
OpenAI API rates verified October 2026, with GPT-6.1 Sol, Luna and Astra budgets plus voice, images, search and container costs.



OpenAI API pricing makes GPT-6.1 Sol the sensible starting point for a small team's coding agent: $2 per million input tokens, $0.10 cached input and $10 output. In the illustrative monthly budgets below, routing focused support and batch summaries to GPT-6 Luna while keeping coding on Sol costs $159.40 for the specified API usage. Choose GPT-6 Astra when the work it saves justifies its higher bill.
Verified against OpenAI's live API pricing page on 3 October 2026. All vendor rates below come from that page. The workload volumes are explicit assumptions, and the arithmetic is calculated from those rates.
OpenAI API is the usage-billed interface your application calls. Its bill depends on what goes into the model, what comes out, and which paid tools the application uses.
OpenAI API Pricing: Current Model Rates
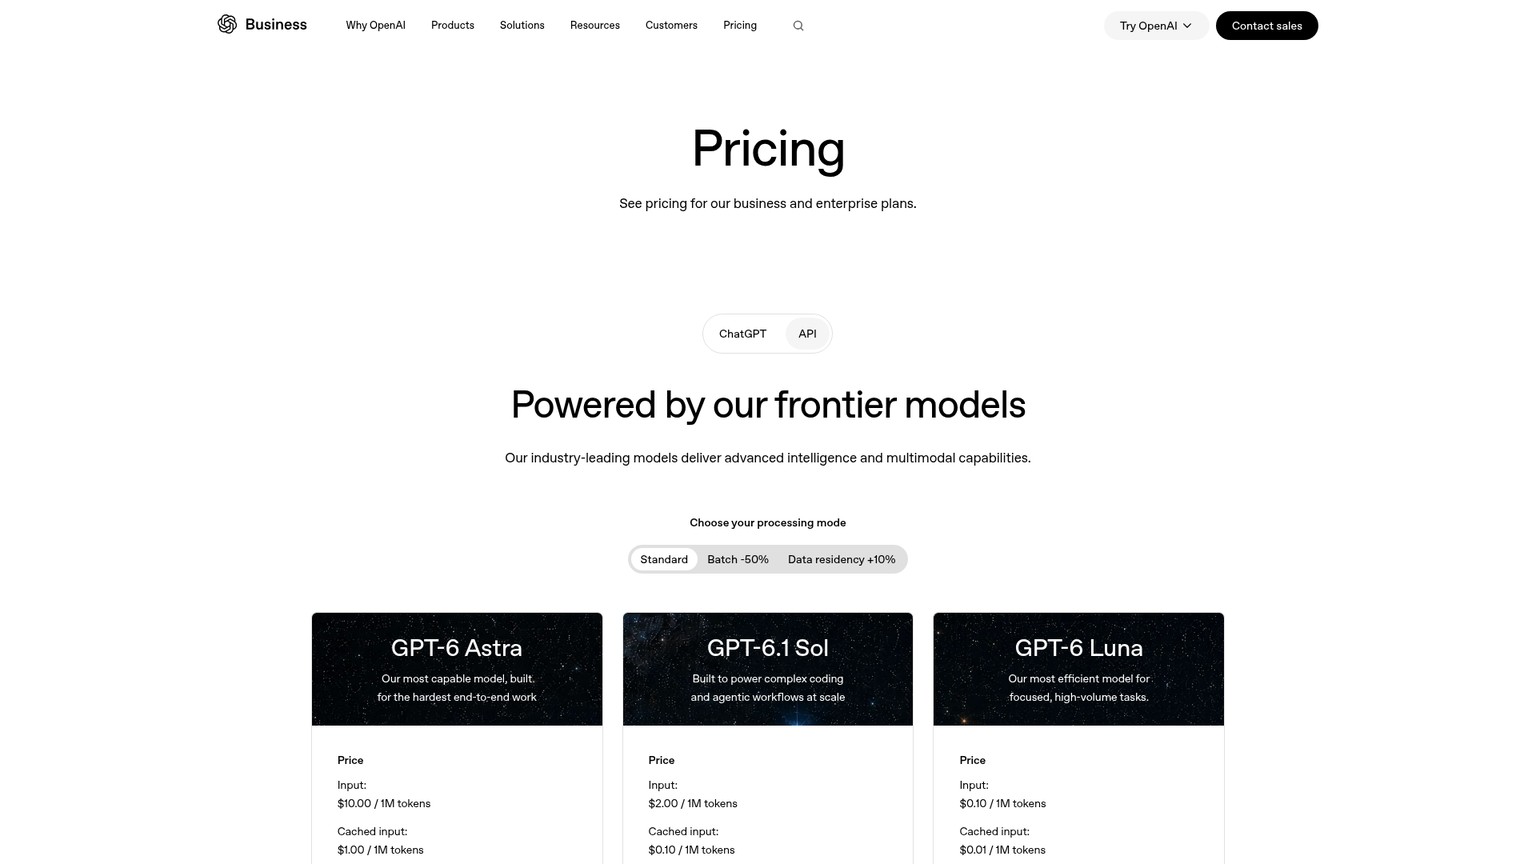
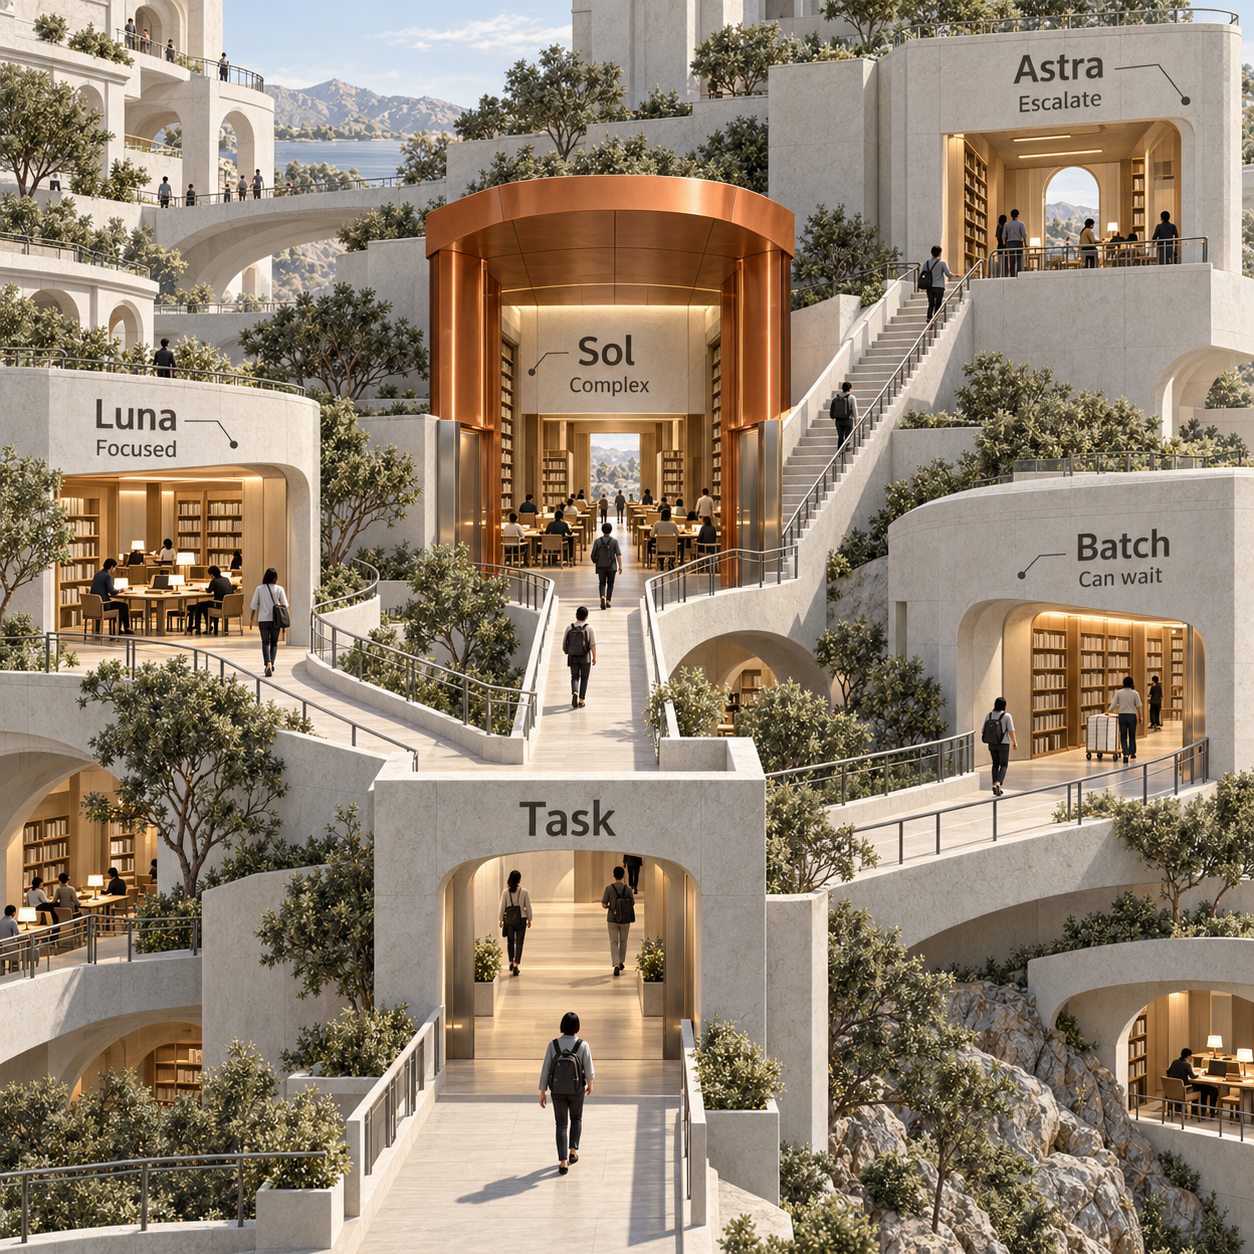
GPT-6.1 Sol costs $2 input, $0.10 cached input and $10 output per million tokens. OpenAI positions it for complex coding and agentic workflows, while GPT-6 Luna targets focused, high-volume work and GPT-6 Astra targets the hardest end-to-end tasks.
The following is the complete set of models featured on the retrieved API pricing tab, rather than a historical model catalog. Token rows are USD per 1M tokens. Time rows explicitly show minutes and seconds. The three flagship text rates are Standard processing prices for context lengths under 272K, the amount of material carried in an individual request. That condition is a pricing boundary, not a statement about the models' maximum context.
Source: OpenAI API pricing, verified October 2026. “Not listed” means the source does not provide that rate; it does not mean a free output allowance. “Not split” means the displayed price is time-based rather than separated into token directions.
GPT-6 Sol is not listed in this page's API price rows. Its name is distinct from GPT-6.1 Sol, so this snapshot does not assign the older model a price or silently give it the newer model's rates. Models and meters absent from this source, including embedding rates, are outside this price sheet.
Which Model Should a Small Team Default To?
Start a coding agent or general-purpose app on GPT-6.1 Sol, then earn each change with completed-work results. That recommendation follows the vendor's positioning and the budget arithmetic, not an independently measured performance ranking.
Sol's uncached input and output rates are one-fifth of Astra's. Its cached-input rate is one-tenth. For a small team still discovering how much context an agent needs, that makes Sol a practical baseline: you can assess the work before paying Astra's premium across every request.
Use Luna for a narrow job with a clear acceptance check. A support classifier that selects a known category or a summarizer whose output can be checked against its source is a better candidate than an open-ended coding task. These are suggested deployment patterns, not claims that either model has passed your checks. Luna's low rate stops being useful when failed work creates more cost than the tokens save.
Keep Astra available for work whose failures are expensive. In the coding example below, choosing Astra over Sol adds $410 per month at identical billed usage. The upgrade pays back when it avoids more than that amount of rework. A high price alone does not establish that it will.
For a team already using GPT-6 Sol, preserve its existing budget until you can compare actual billed usage and accepted results with GPT-6.1 Sol. This page offers no price row from which to compute an older-Sol migration saving.
What Does One Million Tokens Cost?
There is no single price for one million OpenAI tokens. A token is a unit of material processed by the model. Input is the material sent in; output is the generated material billed back. Cached input is reused input that the API bills at the lower cached rate.
One million uncached input tokens plus one million output tokens costs $60 on Astra, $12 on Sol or $0.60 on Luna. That is two million billed tokens. One million total tokens split equally between uncached input and output costs $30, $6 or $0.30 respectively.
To calculate a text-model bill, separate fresh input from cached input:
Token cost = fresh input / 1M × input rate + cached input / 1M × cached rate + output / 1M × output rate.
If your usage record gives total input and cached input, fresh input is total input minus cached input. Charging the full input count at the fresh rate and then adding cached input again double-counts it.
On Sol, cached input is 95% cheaper than uncached input. But one million output tokens still costs as much as 100 million cached input tokens. A large cache saving does not justify unlimited generated material. Count the billed output across the whole agent task, rather than budgeting only the final answer a user sees.
OpenAI API Pricing Calculator: Three Monthly Workloads
The three workloads cost $159.40 per month under the suggested routing. This is a planning example for a small app operator, not a measured production bill or a promise that the models produce equally good results.
Each individual request is assumed to fall under the source's under-272K Standard-price condition. Cached volumes mean actual billed cache hits. Output volumes include all billed output across all calls. Tool activity is included where stated; subscription fees, hosting and other unspecified meters are outside these totals. The inputs are the current OpenAI rates.
Support Bot: $13.90 on Luna
Assume 10,000 conversations per month. Across each conversation's calls, budget 1,000 fresh input tokens, 4,000 cached input tokens and 500 output tokens. Monthly totals are 10M fresh input, 40M cached input and 5M output. Assume another 1,000 web-search calls during the month.
On Luna, the tokens cost:
10 × $0.10 + 40 × $0.01 + 5 × $0.50 = $3.90.
The search calls add $10, bringing the total to $13.90, or $1.39 per 1,000 conversations. With the same usage, Sol costs $74 in tokens plus $10 search, or $84. Astra costs $390 in tokens plus $10 search, or $400.
Luna is the economical candidate if the bot handles a bounded support job and its answers pass your acceptance checks. This bill assumes the reusable material qualifies for cached billing. With no cache hits, all 50M input tokens are fresh: Luna's token subtotal becomes $7.50 and its total becomes $17.50. That is the sensitivity to record before treating an expected cache hit as a saving.
Coding Agent: $140 on Sol
Assume 1,000 coding tasks per month. Across all turns of each task, budget 15,000 fresh input tokens, 100,000 cached input tokens and 5,000 output tokens. The month therefore uses 15M fresh input, 100M cached input and 5M output. A task can contain multiple requests; these are task totals.
Also assume 2,000 web-search calls and 1,000 container sessions, each using 1 GB and the source's 20-minute session unit.
Sol's token bill is:
15 × $2 + 100 × $0.10 + 5 × $10 = $90.
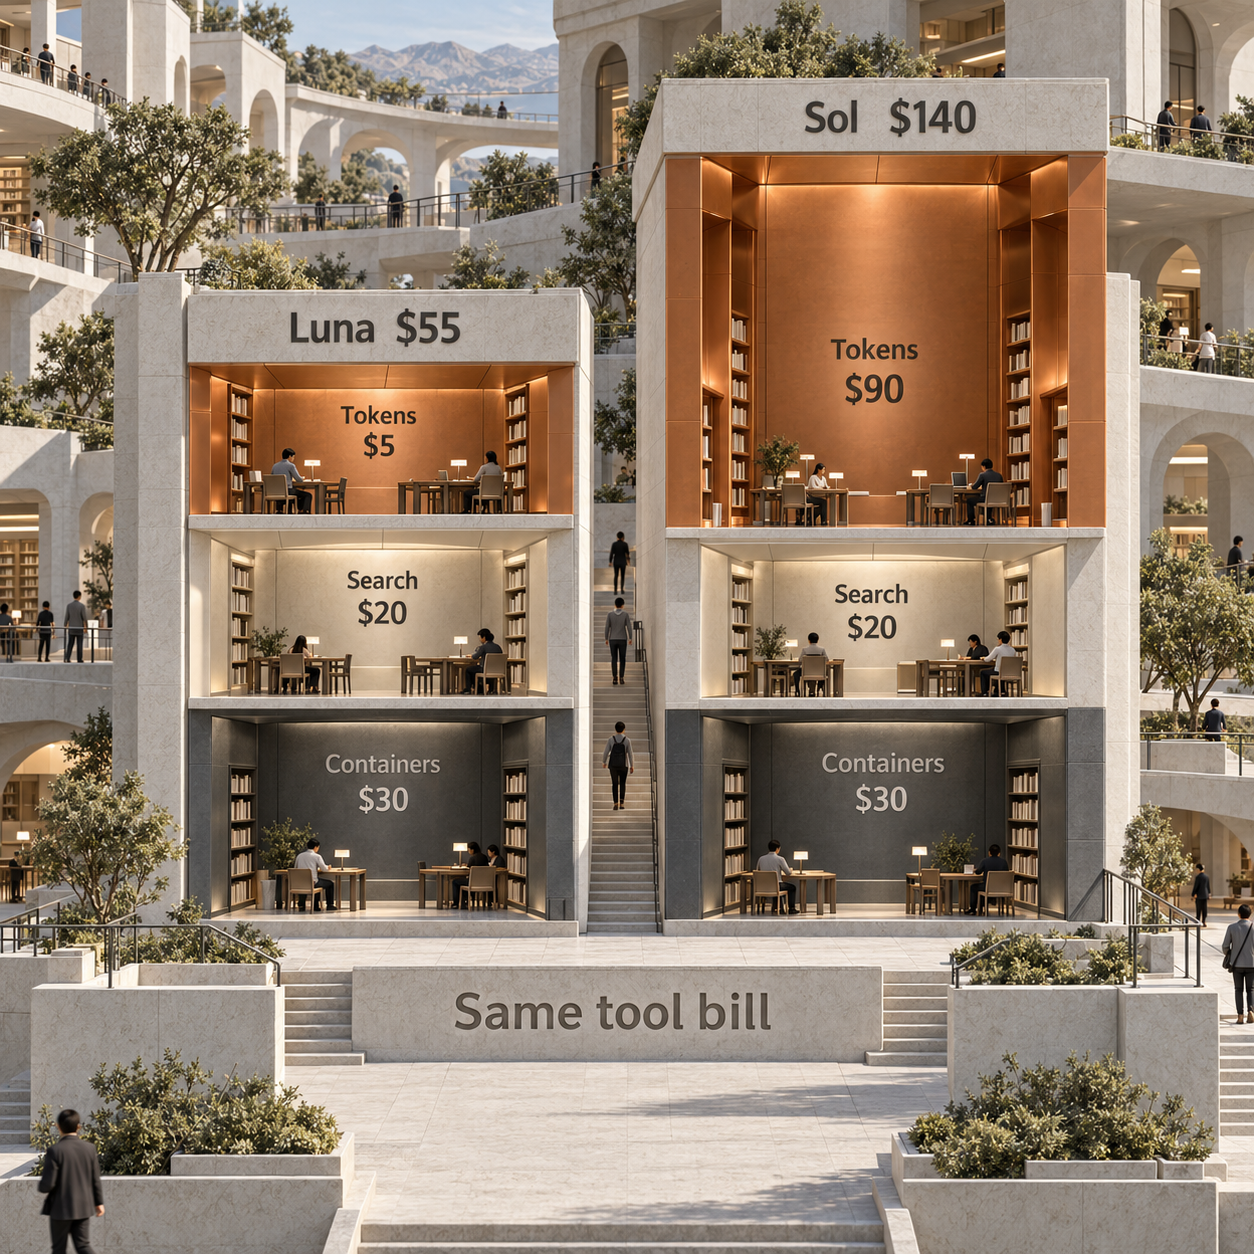
Search costs $20, and containers cost 1,000 × $0.03 = $30. The total is $140 per month, or $0.14 per task.
At identical billed volumes, Astra costs $500 in tokens plus the same $50 in tools, totaling $550. Luna costs $5 in tokens plus $50 in tools, totaling $55.
The cheaper model does not remove the tool bill. Switching from Sol to Luna saves $85 per month in this example. If the resulting coding work creates more than $85 of additional rework, the saving disappears. Moving to Astra requires the opposite evidence: enough avoided rework to justify its $410 premium. That is the decision rule a token-only comparison cannot supply.
Batch Summarizer: $5.50 on Luna
Assume 20,000 documents per month, each with 4,000 uncached input tokens and 300 output tokens. That produces 80M input and 6M output tokens. There are no assumed cache hits or tool charges, and the summaries can be processed asynchronously over the Batch API's 24-hour window.
Luna's Standard token cost would be 80 × $0.10 + 6 × $0.50 = $11. Applying the source's 50% Batch discount gives $5.50 per month, or $0.275 per 1,000 summaries.
The same Batch volumes cost $110 on Sol and $550 on Astra. Use the cheaper model when the summaries meet the required standard; move individual difficult documents to a stronger model when their correction cost warrants it. A customer waiting for an immediate reply is a different workload and should not be budgeted as asynchronous Batch work.
The Combined Monthly Budget
The suggested route totals $13.90 Luna support + $140 Sol coding + $5.50 Luna Batch summaries = $159.40.
Using Sol for all three costs $334. Using Astra for all three costs $1,500. Using Luna for all three costs $74.40, provided its work is acceptable. These comparisons hold billed token and tool volumes constant; they do not assume the models take the same number of attempts in practice.
For an app operator, that distinction decides the bill. A model needing more turns can consume more input, output, search calls and sessions. Compare cost per accepted conversation, completed coding task or usable summary before applying the lowest rate to the entire product.
OpenAI Batch API Pricing and Data Residency
Batch reduces the listed input and output charges by 50%; data residency adds a displayed 10% premium. OpenAI's pricing page shows these processing choices separately from Standard rates.
Batch runs work asynchronously over 24 hours. It fits overnight document summaries, categorization and other jobs whose deadline permits that window. The worked summarizer applies the discount to fresh input and output only, so it makes no assumption about a discounted cached meter or tool fee.
For a model-token subtotal of $90, applying the residency premium produces $99, an extra $9. That example does not establish whether search or containers receive the same treatment, or how residency combines with other modes. The pricing tab does not give enough detail to calculate those combinations here.
The page also describes Fast mode and Flex processing. Fast is a pay-as-you-go speed option; Flex trades lower cost for slower responses and occasional unavailability. It does not supply exact rates for either on this tab, so neither receives an invented multiplier in these budgets.
Tools Can Set the Cost Floor
Count search calls and container sessions separately from model tokens. A token estimate can be correct while the monthly budget remains too low because a task invokes additional paid resources.
OpenAI Web Search API Pricing
Web search costs $10 per 1,000 calls, and the page says search content tokens are free. That is $0.01 per call: 100 calls cost $1; 10,000 cost $100. The model's separately billed work still belongs in your token totals. Source: OpenAI API pricing.
In the support example, 1,000 searches cost more than the entire Luna token subtotal. Make search frequency a deliberate product choice. A reply that genuinely needs current information can justify a search; a reply using an already supplied support policy should not automatically inherit a search budget.
Containers: The Session Is the Billing Unit
Containers, execution environments used alongside models, cost $0.03 for 1 GB or $1.92 for 64 GB, per 20-minute session per container. The pricing page dates that session billing to March 31, 2026, which has passed in this October snapshot. Its older “Now” wording is not a reason to assume one permanent fee per container. Source: OpenAI API pricing.
The coding example deliberately assumes 1,000 one-GB sessions. It does not claim that every coding task consumes exactly one session. Count your sessions as their own meter, especially when tasks use several containers or span more session units.
At the listed 64-GB rate, those 1,000 sessions would cost $1,920. Keeping the same Sol tokens and search calls would raise the coding month from $140 to $2,030. The larger container's session fee is 64 times the smaller one's. No intermediate-size price is supplied on this page, so none is interpolated here.
OpenAI Realtime API Pricing
GPT-Realtime-2.1 uses different prices for audio, text and image input. Audio tokens are a voice billing meter; they should not be treated as text tokens or converted to minutes with an unsupported rule.
One million uncached audio input tokens plus one million audio output tokens costs $32 + $64 = $96 on GPT-Realtime-2.1. The same token volumes cost $10 + $20 = $30 on GPT-Realtime-2.1 mini. Text and image inputs use their own rows in the table. Source: OpenAI API pricing.
For time-based work, GPT-Live-1 is the conversation model, GPT-Live-Transcribe handles live speech-to-text, GPT-Transcribe handles asynchronous transcription, and GPT-Realtime-Translate handles realtime translation. Using the displayed minute rates, 1,000 minutes costs $50, $17, $4.50 or $34 respectively. Those are different jobs, not interchangeable voice plans. The page gives no conversion that turns the Realtime audio-token example into an equivalent number of minutes.
OpenAI Image API Pricing
GPT-Image-2.5 Sunburst and GPT-Image-2.5 Flare have the same listed token rates. Both charge $8 for image input, $2 for cached image input and $30 for image output per million tokens; text prompts cost $5 input or $1.25 cached input. OpenAI positions Sunburst around editing precision and Flare around everyday generation speed. Source: OpenAI API pricing.
An assumed one million generated image tokens plus one million uncached text-prompt tokens costs $30 + $5 = $35 on either model. That does not mean one million images. The pricing page says images are converted to tokens but does not establish one fixed token count per generated image for this calculation.
Budget image work from its actual billed image and text meters. Avoid promising a fixed per-image charge from a per-token row, or selecting between these models on a price difference this page does not show.
Subscriptions, Free Access and Other Billing Questions
A ChatGPT subscription does not pay your application's API bill. OpenAI explicitly separates API billing from ChatGPT Plus, Business, Enterprise and Edu. Use the ChatGPT pricing guide for the subscription decision, and budget app usage separately.
OpenAI Codex API Pricing
Codex is OpenAI's coding product; the relevant distinction is how you pay for its use. When budgeting separately billed API activity, use the model, token and tool meters above. Product-plan allowances are a different purchase. The Codex pricing guide covers that subscription decision.
Buying a seat for a developer does not turn the support bot, automated coding workload or batch summarizer into prepaid app usage. Keep product subscription spending and the application's metered API spending as separate budget lines.
OpenAI API Pricing Free Tier
The retrieved pricing page lists no general free API token allowance. It explicitly says Playground usage, the browser interface for trying requests, is billed like regular API usage. Do not budget experimentation as free merely because it happens outside your app.
Someone using only a free ChatGPT experience may never need to buy API usage. Once your app makes paid API requests, that free-app choice is no basis for a free production budget.
This source does not state a universal API student discount, an API refund policy, credit expiry or an annual token-price commitment. Those omissions are not proof that no account-specific offer or separate policy exists. They mean this pricing snapshot cannot promise one. In particular, do not import a subscription's refund or annual-billing terms into an API budget.
Set Next Week's Budget From Completed Work
Start with Sol and measure the entire task before optimizing the model rate. Your next budget should use observed billed usage rather than the number of words in the final reply.
Record a baseline
For representative work, record fresh input, cached input, billed output, searches and container sessions across every turn. Keep the task's acceptance result alongside its cost.
Move bounded work where it fits
Try Luna for focused tasks whose results can be checked. Put work that can wait into Batch. Retain the route only when the output meets its acceptance criteria.
Price the upgrade against rework
For difficult tasks, compare Astra's additional API cost with the value of corrections it avoids. Use the actual attempts and tool usage, not an assumption that every model consumes identical tokens.
OpenAI's pricing FAQ says monthly budget enforcement can be delayed and you remain responsible for overage. Treat the configured budget as a spending control with that stated limitation, and monitor actual usage. For project structure and recovery workflows, see the API budget controls guide.
Frequently Asked Questions
How much does OpenAI cost?
OpenAI API usage is metered by model, tokens and tools. For Standard requests under the stated context boundary, Sol is $2 input, $0.10 cached input and $10 output per million tokens. There is no single app-wide monthly price on this API price sheet.
Is ChatGPT API cheaper than ChatGPT Plus?
It depends on usage and what you need. An app's API bill can be small, but it buys metered application requests rather than the subscription product experience. OpenAI states that API usage is billed separately from ChatGPT subscriptions.
What are the pricing and cost comparisons for different LLM APIs?
Normalize input, cached input, output, tool use and successful completion before comparing providers. The like-for-like OpenAI coding scenario here costs $55 on Luna, $140 on Sol and $550 on Astra, with quality held as an acceptance condition. This snapshot contains no verified prices for other providers.
Is it worth paying for OpenAI?
It is worth paying when accepted work saves more than API usage and resulting rework cost. Start the coding workload on Sol; upgrade to Astra when its additional cost is justified by avoided corrections, and use Luna where its work passes the same required checks.
Is it worth to pay $20 for ChatGPT?
Pay for a ChatGPT subscription when its features and the time it saves justify the fee. It does not purchase the app usage calculated here, so that API spending remains a separate decision.
Is OpenAI API free or paid?
The page lists paid model and tool usage and no general free API allowance. It also says Playground requests are billed like regular API requests. A free ChatGPT experience does not establish free API usage.
Is OpenAI API expensive?
The job and its tool activity decide. The hypothetical support month costs $13.90 on Luna, while the Sol coding month costs $140. Both figures depend on the stated billed volumes; a small token rate does not remove search or container charges.
What are the best free AI APIs?
No general free OpenAI API allowance is listed on this pricing page. Luna is a low-cost paid option for focused tasks whose outputs pass your checks. A provider's free API allowance needs its own current verification before it belongs in a production budget.
How much is 1 million tokens OpenAI?
For one million uncached input tokens, Astra costs $10, Sol $2 and Luna $0.10. For one million output tokens, they cost $50, $10 and $0.50. One million input plus one million output is two million billed tokens, totaling $60, $12 or $0.60.
Does OpenAI offer an API student discount?
No universal API student discount is stated on the pricing page verified for this article. Do not count a student offer for another OpenAI product as API credit unless its own terms explicitly provide that benefit.
What is OpenAI's API refund policy?
The verified pricing page does not state an API refund policy. This article therefore does not promise refunds or apply ChatGPT subscription rules to API purchases.
Has OpenAI API pricing changed in 2026?
The current page explicitly dates per-20-minute container-session billing to March 31, 2026. It does not provide a historical model-price series, so this October snapshot does not claim when model-token prices changed or quote earlier prices.
Map the tasks and acceptance checks before choosing another plan. Get the AI business workflow audit checklist when you join the newsletter.
- Last Updated
- Oct 3, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Pi Coding Agent
Set up Pi 1.0, connect your existing model account, add AGENTS.md and complete a first task. Includes provider pricing and honest limits.Oct 3, 2026Build
Best No Code AI Agent Builder in 2026: MindStudio, Gumloop and n8n (8 Compared)
Compare eight no-code AI agent builders by job, entry price, billing unit, integrations and the point where API setup or code becomes necessary.Oct 1, 2026Build
Lovable Pricing (2026): What a Month of Credits Costs
Lovable costs $25/month for Pro or $50 for Business. See annual fees, credit top-ups, expiry, Cloud, app AI and a worked internal-tool budget.Oct 1, 2026Build
How to Set Up Codex Security After DevDay
Set up Codex Security Cloud, PR review, and the CLI. Current team costs, real Gogs findings, SARIF in CI, and the checks you still need.Sep 30, 2026Build
LearnWorlds Pricing (2026): When Pro Costs Less
Calculate LearnWorlds pricing for AI-built business training, including credits, learners, enrollment fees, and the point where an upgrade pays.Sep 30, 2026Build
ChatGPT Space vs Notion
Compare ChatGPT Space and Notion for shared documents, project databases, agents, permissions, pricing, and the launch limits that affect a switch.Sep 30, 2026Build
How to Use Kitesurf WebMCP
Connect an agent to Kitesurf, discover WebMCP tools, and run a checked task. See the setup and the limits that need a fallback.Sep 30, 2026Build