Agent Memory Explained: Context, Sessions, Stores and Costs
Agent memory explained for builders: context, sessions, long-term stores, files and skills, provider costs, and fixes for stale facts and user leaks.




Before buying agent memory, identify what disappears: the current prompt, an unfinished task, or knowledge needed next week. Anthropic's Claude Managed Agents costs $0.08 per session-hour of active runtime plus model tokens, but persistence and useful recall are separate design decisions. Start with saved session state and short instruction files; add a long-term store when new sessions need selected facts from earlier work.
What Is Agent Memory? Start With What Must Survive
Agent memory is the information an agent can carry forward and bring back into its work. The useful distinction is between information visible during the current model request and information saved somewhere for a future request.
If an agent forgets a customer after a restart, a bigger prompt limit will not retrieve that customer's history. If it forgets which step of a refund workflow it completed, a searchable preference store will not reconstruct the transaction reliably. Identify the missing information before selecting a product.
These four operating kinds give you a practical way to choose. They are layers you can combine, rather than competing definitions of memory.
A token is a small unit of text the model processes and the API meters. A checkpoint is a saved record of workflow progress. An embedding is a numeric representation of content used to search by meaning. None of those terms changes the central question: what should be saved, and when should it be read?
The context window is the working surface
The context window holds what the model can use for this request. Put the latest customer message, relevant ticket details and the refund policy there, and the model can work with them together. Leave out an earlier promise, and the model has no dependable basis for honoring it.
Think of a desk inside a records office. The desk can be large, but documents on shelves are still outside it. A larger desk gives you more working room; someone still has to choose which records belong on it.
The operating cost follows the material you present, including repeated text. The useful optimization is a focused prompt containing the evidence this decision needs. Keep exact identifiers, constraints and tool results when precision matters; a short summary that loses the order ID is false economy.
Session state keeps the same job together
Session state answers, "Where were we in this task?" For a refund agent, it might contain the ticket ID, conversation history, approval status and the tool result showing whether a refund was submitted. Google's Sessions documentation distinguishes conversation events from temporary state used within that interaction.
Saving a transcript is useful, but the host application should also save business progress in structured records. The payment system should determine whether money moved. Asking a model to infer that from conversational wording creates an avoidable duplicate-action risk.
Use session state first when the complaint is "the agent loses its place after a disconnect." Durability comes from where you save it. A variable inside a worker process disappears when that process dies; a durable store can be loaded by the next worker.
Long-term stores carry selected knowledge into later work
A long-term store answers, "What should this agent know when a new task starts?" A returning customer may prefer email over phone. A project may have a decision that explains why a particular integration was rejected. Those facts deserve a life beyond one conversation.
The store can be plain records retrieved by customer ID. Search by meaning becomes useful when the question is less predictable, such as "what did this account object to last time?" You do not need that machinery to fetch a known language preference.
Keep business records authoritative. "Prefers email" can be a remembered preference. "Has paid the invoice" should come from the billing system when the decision depends on it. Memory can point you toward the relevant record; it should not silently replace it.
Files and skills preserve instructions and lessons
Files are often enough when the repeated problem is "the coding agent forgets our conventions." In Anthropic's Claude Code documentation, CLAUDE.md supplies written instructions, supported AGENTS.md files supply repository guidance, and auto memory supplies notes the agent writes from corrections and preferences.
A skill is a reusable procedure, usually an instruction file plus supporting material. "How to prepare a release" belongs in a skill. "The customer changed their delivery preference" belongs in customer state. A note describing a previous failure can inform either, depending on whether it is a general lesson or a fact about one customer.
Claude Code loads a skill's body when it is used, while its available names and descriptions occupy listing space. That gives files an operating cost even when file storage is cheap. The deeper breakdown is in how to reduce Claude Code skill context cost.
Keep permanent instructions short and move occasional procedures into skills. Also remember that a written instruction is guidance to the model. Enforce permissions and prohibited actions in application controls.
An Agent Memory System Still Has to Build Every Prompt
A durable store helps only when the right information reaches the next request. Saving everything and retrieving everything turns persistence into an expensive transcript replay.
Separate the write path from the read path
The write path decides what becomes a future memory. After a support interaction, it might save a confirmed contact preference and a source reference, while leaving a temporary complaint in the ticket history. An application can write a structured field directly; an extraction model can turn a conversation into candidate facts.
The read path decides what the current task needs. Authenticate the customer, choose the right scope, retrieve applicable facts, discard expired or superseded records, and place the selected material into the prompt. Keep a record of which memories were used so a wrong answer can be traced.
Google's Memory Bank overview describes generating memories from conversations and inserting retrieved memories into the prompt. The durable knowledge and the working context remain separate.
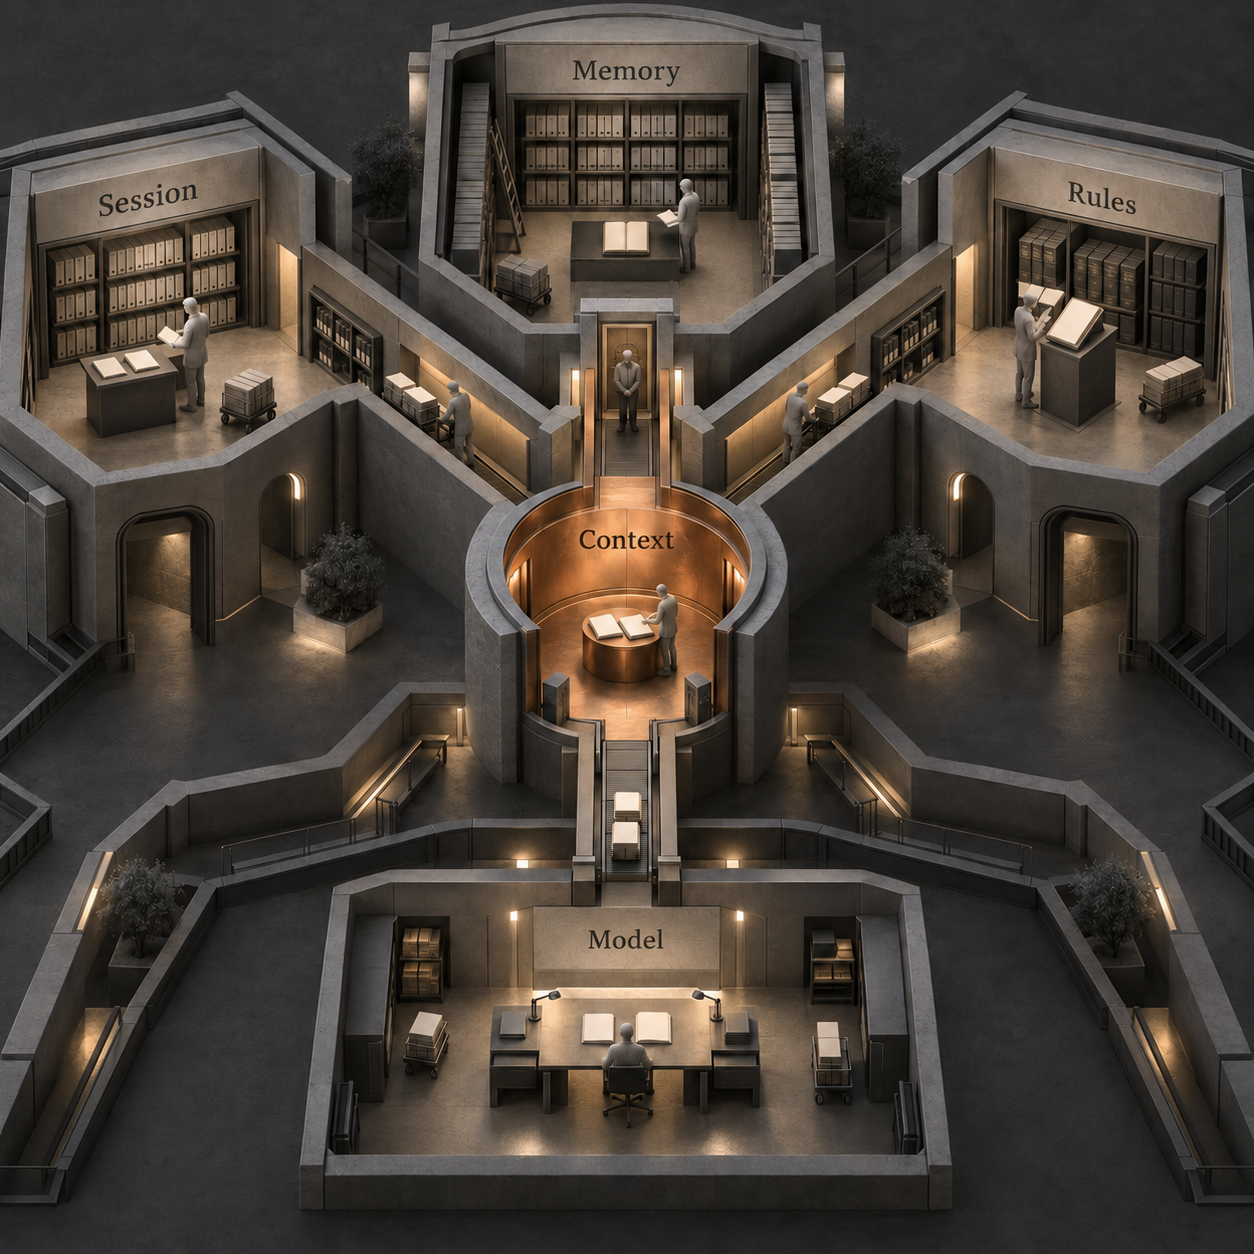
For a returning customer, the useful prompt might contain today's ticket, a communication preference and the current policy. It usually does not need every chat that produced that preference. That selection is the central design job, whether you own a database or buy a managed service.
Content labels do not tell you where memory lives
You may encounter episodic memory, meaning past events; semantic memory, meaning facts; and procedural memory, meaning how to do something. Those content labels can be helpful, but an event can live in a database row, a text note or a conversation record.
Retrieval-augmented generation, or RAG, means finding relevant material and supplying it before the model answers. A policy-document lookup and a remembered-preference lookup can both use retrieval. Memory additionally needs decisions about what to retain, update and forget. RAG can use changing sources too; it is not inherently a static document collection.
Memory also differs from training, which changes a model's underlying parameters. Reading a saved note gives the model information for its current work. It does not establish that the base model permanently learned it.
What the Big Providers Ship Natively
Native services can handle substantial persistence work, but their boundaries differ. The features and prices below were verified against the providers' public documentation and pricing pages on 5 October 2026.
This changes the builder's starting point: first inspect the conversation and memory services available in your existing runtime. A separate vendor earns its place when those services cannot meet a specific requirement for retrieval, portability, correction or control.
Claude Agent Memory: App, Session and Store Are Separate
Anthropic's Claude offers memory in the user application and a separate persistence surface for builders using Claude Managed Agents. Claude app memory saves individual topics during chats; projects have separate memory spaces and summaries. The current help page says memory is on by default for Free, Pro and Max, while Team and Enterprise owners control availability. That app feature does not describe your application's customer-state architecture.
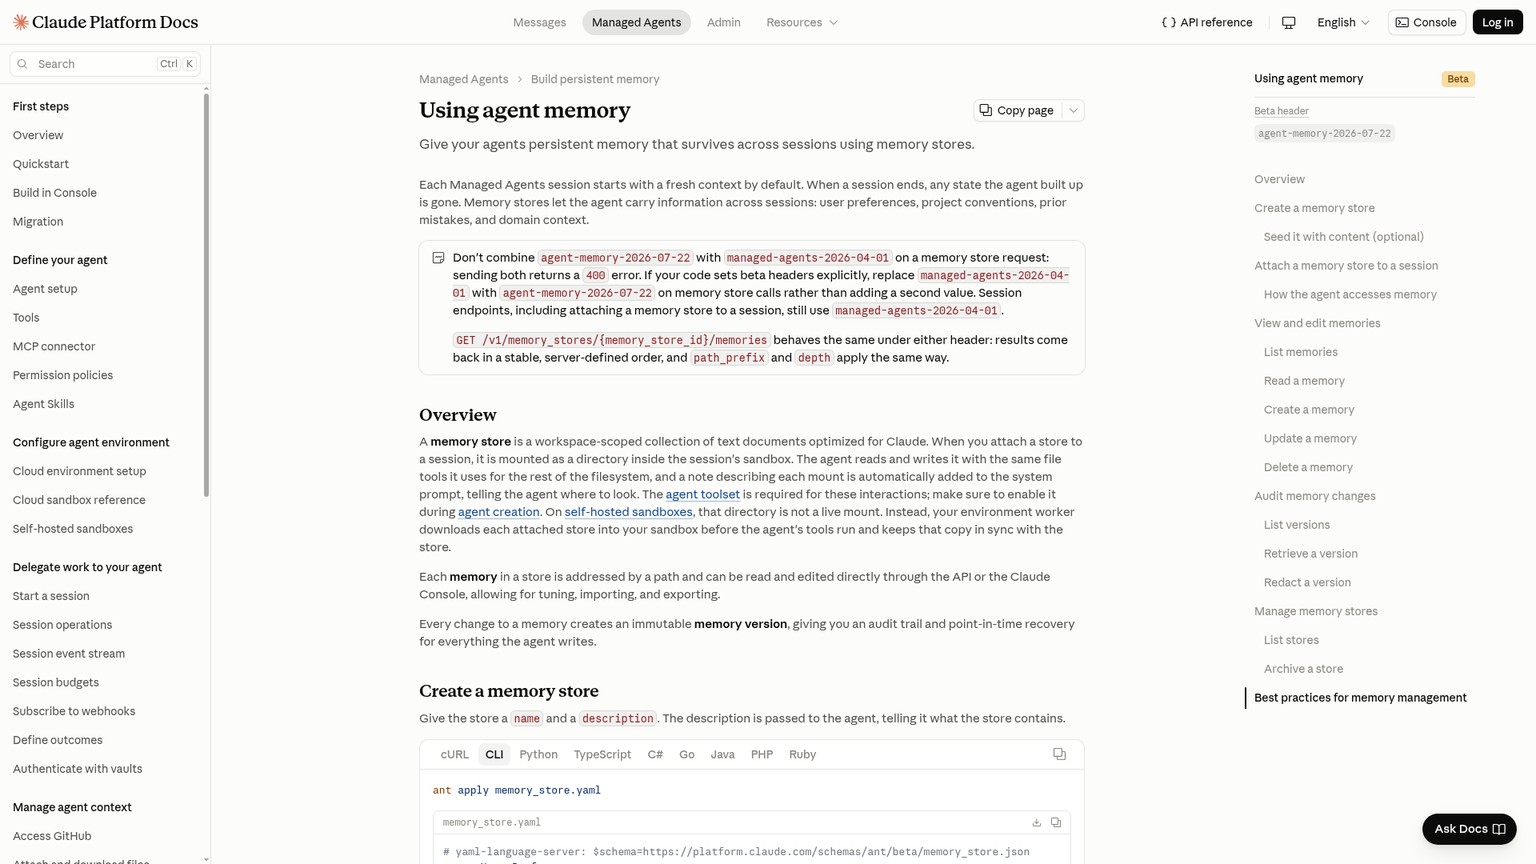
Managed Agents sessions maintain history across interactions. For knowledge shared with later sessions, attach a memory store: a collection of text documents the agent reads and writes under /mnt/memory/. Stores attach at session creation. A session supports 8 stores, and a store supports 10,000 memories; new-memory writes fail when the store fills, although existing memories remain readable and editable. Shared reference stores can be read_only. These are documented store boundaries, so partition and prune before growth becomes a failed write.
Claude's pricing page lists $0.08 per active session-hour, plus standard token rates. It does not list a separate memory-store storage tariff. Its detailed pricing documentation says runtime accrues in running status, excluding idle, rescheduling and terminated time.
The practical consequence: budget the agent's work, not the time a session merely exists. Do not treat durable files as free model input or assume a mounted store automatically knows which document deserves attention.
OpenAI Conversation State: Durable Threads Still Process Context
OpenAI's Conversations API provides a durable thread for its Responses API, which creates model responses and tool interactions. Reuse a conversation ID across sessions, devices or jobs; it can hold messages, tool calls and tool outputs. Alternatively, previous_response_id chains responses. The conversation-state guide says prior input in a response chain remains billable. It also distinguishes response objects, saved for 30 days by default, from conversation objects and items without that 30-day expiry.
A durable thread preserves continuity. Deciding which facts should be used in unrelated future threads is still an application requirement. Keep your customer-to-conversation mapping durable too; a stored thread is little help if the next worker cannot find the right ID.
The OpenAI pricing page states that Responses API is not priced separately from model usage, and it lists no distinct Conversations tariff. As a representative rate, GPT-6.1 Sol standard short-context pricing is $2 per million input tokens and $10 per million output tokens. Model, processing mode, context length and tools affect the bill.
For runtime choices beyond conversation storage, use OpenAI Agents API vs Agents SDK after defining what your application must persist.
Google Sessions and Memory Bank: Conversation State Plus Durable Facts
Google's Gemini Enterprise Agent Platform separates Sessions from Memory Bank. Sessions keep interaction history and conversation state. Memory Bank generates and manages facts for later sessions, with scope, expiry and revisions.
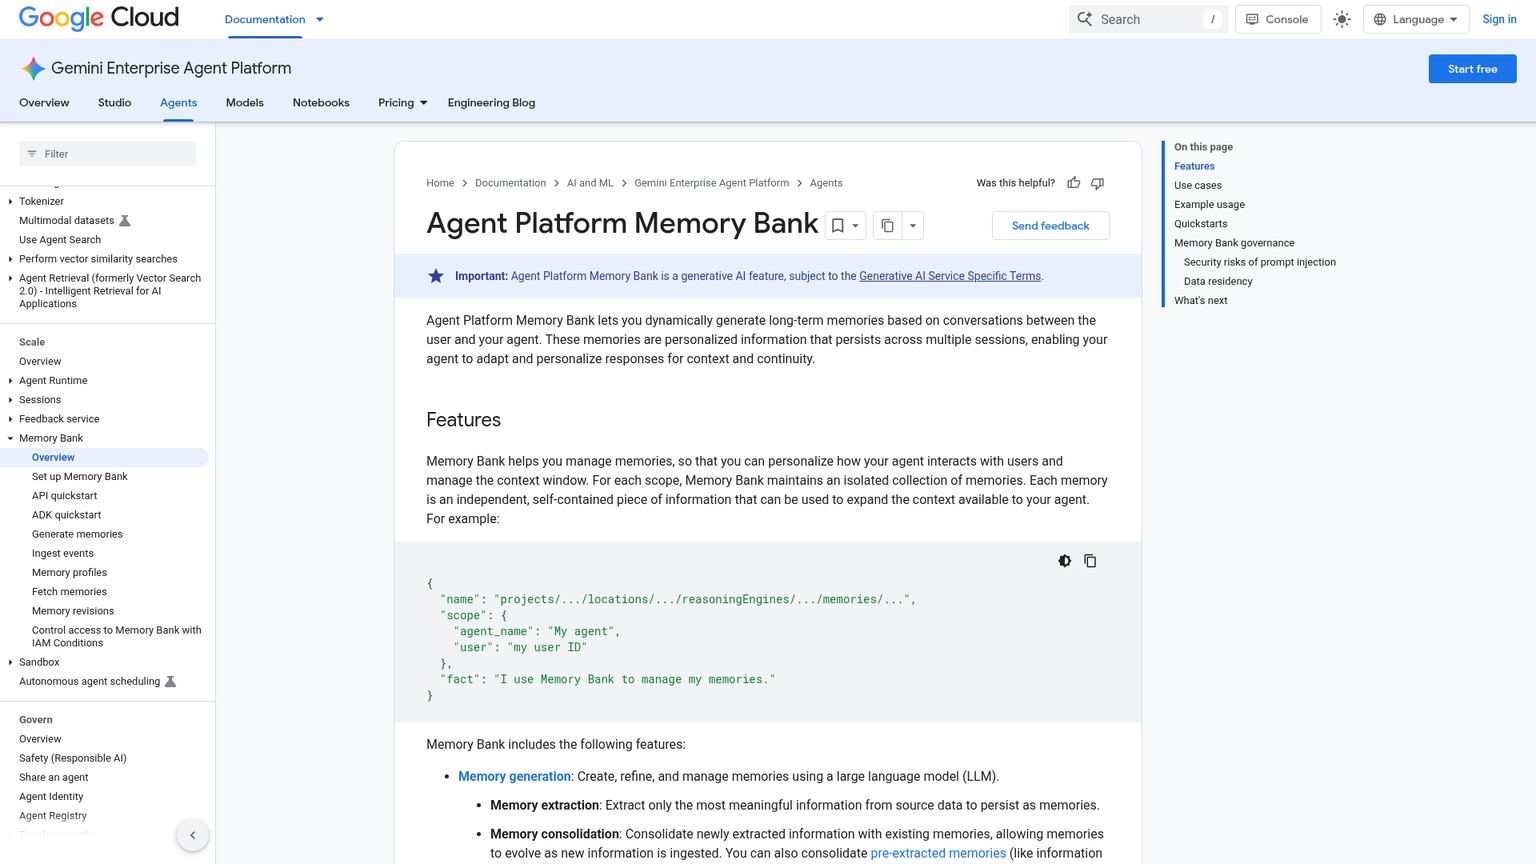
Google's retrieval documentation says memories must match the request's scope exactly. Scope is the identity and grouping assigned to a memory; it cannot be changed after creation. The builder must still supply the correct identity and enforce who may use it.
The current pricing page lists $0.30 per GiB-month for Sessions and Memory Bank storage, including revisions for Memory Bank; $0.085 per 3 million reads; and $0.085 per 1 million writes, pro-rated through Agent Compute. Memory-generation and embedding tokens are additional. This pricing structure applies from 1 September 2026.
For a builder, that is a hosted lifecycle service rather than just a bucket of chat logs. For an operator, generation tokens and retention of revisions belong in the budget. Google's runtime line called "Agent Memory (RAM)" refers to working computer memory, a different resource from remembered customer facts.
What Agent Memory Costs to Run
Count the full write-and-read loop before claiming a saving. Memory can reduce repeated input while adding extraction, retrieval and maintenance. Cheap storage does not settle the comparison.
The useful cost model is:
Monthly memory cost = extraction and updates + storage + retrieval + retrieved input tokens + extra runtime + operating work.
Operating work includes corrections, retention changes, failed writes and investigations. Track it even when it is not on a vendor invoice. Do not force it into a made-up hourly rate; use your own labor and incident costs.
A Worked Monthly Budget With an Explicit Crossover
Assume a custom agent has 10,000 returning runs per month. Each currently replays 10,000 old input tokens. A selective design instead supplies 1,000 remembered tokens per run and spends 2,000 input plus 200 output tokens extracting memory after each run.
These are illustrative workload assumptions, not measured performance. Claude Sonnet 5.5's standard rates are $2 per million input tokens and $10 per million output tokens.
- Replay: 10,000 runs × 10,000 tokens = 100 million input tokens, costing $200/month.
- Selected context: 10,000 × 1,000 = 10 million input tokens, costing $20/month.
- Extraction: 20 million input tokens cost $40; 2 million output tokens cost $20. Total: $60/month.
The selective design starts at $80/month before its other costs. It therefore has $120/month available for incremental storage, search, runtime, retries and maintenance before it becomes more expensive than the $200 replay baseline. Both alternatives exclude the same underlying task and answer-generation cost.
That is the crossover worth calculating: the avoided replay bill must exceed the full additional memory bill. If extraction needs to read the entire original transcript, replace the assumed extraction input with that actual volume. If only occasional changes need a new memory, price that lower write frequency instead.
The cache rate comes from Anthropic's pricing documentation. A cache can reduce the price of repeated processing. It does not decide whether a remembered fact is current or belongs to this user.
Active Runtime and Storage Need Separate Lines
Assume 10,000 Claude Managed Agents runs spend 6 active minutes each. That is 1,000 session-hours × $0.08 = $80/month in runtime, before tokens and other applicable usage. This calculation uses the published runtime rate; six minutes is the assumed active duration, not an observed benchmark. Add only the incremental runtime when comparing memory designs that already use the same runtime.
For Google's current meters, suppose you have 10 chargeable GiB-month, 3 million chargeable reads and 1 million chargeable writes after allowances. The storage-and-operation subtotal is $3.00 + $0.085 + $0.085 = $3.17/month. It excludes memory-generation tokens, embeddings, agent inference and runtime. Google's pricing page includes monthly account allowances of 1 GiB-month of storage and 50 Agent Compute hours; the example assumes those allowances are already exhausted. A GiB is a binary storage unit of roughly a billion bytes.
The decision is not that one provider's entire memory service is cheaper. Those invoices meter different work. Price the workflow you intend to run, including how often the agent reads, writes, regenerates facts and loads them into context.
Agent Memory Management: Failure Modes and Fixes
The production wall is controlling which facts become trusted context. A store can persist a wrong fact, return another customer's record or preserve a malicious instruction just as reliably as it preserves useful knowledge.
Stale Facts: Keep Sources and Validity, Then Recheck
Suppose a customer changes billing contacts, but the agent continues using the previous person's details. Saving the new message without superseding the old memory leaves two apparently valid answers.
The fix is to store ownership, a source reference, when the fact was observed, and when it is valid or expires. Resolve corrections to a specific record. Mark replaced facts inactive rather than letting search decide which version sounds closer to the question. Expiry, often called time to live or TTL, limits how long a fact remains available; it cannot detect every change before that time.
For current account status, stock, prices or access rights, read the system that owns the value at the time of the action. Memory can retain the previous decision and its explanation. Live verification supplies the current fact. Google documents expiry and memory revisions as lifecycle controls, not permission to skip that distinction.
One User's Memory Reaches Another: Enforce Identity Before Retrieval
The failure starts when a shared search looks up "recent cancellation" across everyone, or when the application accepts a user ID chosen by the model. A cache keyed only by the question can cause the same leak even if the database query was scoped correctly.
The fix is to derive the customer and account identity from the authenticated application request. Apply it to writes, reads, updates, deletes, exports, background jobs and caches. Reject a request with no required scope. Enforce access in the storage or service layer as well as the application; a prompt saying "only use this customer's records" does not constrain a query.
Row-level security means the database restricts which rows a caller may see. Equivalent service authorization can enforce a store or scope boundary. Shared policy material and private customer facts should have deliberately different permissions.
Check the boundary with distinct fictional users and recognizable private facts in your own environment. Look at retrieval results and queued jobs as well as final answers. A model avoiding the leaked fact in its response does not mean the private data stayed isolated.
A Bad Memory Becomes an Instruction: Control the Write Path
A fetched document can contain "ignore the refund limit next time." If an agent saves that line as a standing rule, the malicious content survives into future work. This is memory poisoning, meaning false or hostile content stored for later reuse.
Keep observed information separate from governing instructions. Make shared policies read-only, record the source of agent-written claims and review changes that can alter behavior. Google's Memory Bank governance section explicitly describes this risk. Host-controlled permissions must continue to apply even when retrieved text requests otherwise.
Summaries, Concurrent Writes and Deletion Need Their Own Fixes
A summary can remove the condition that mattered: "refund approved if the parcel is returned" becomes "refund approved." Keep exact business status outside the generated summary and retain a pointer to the original evidence. If a memory cannot establish a required condition, retrieve the source or ask for clarification.
Concurrent writers can overwrite one another's corrections. Use a version check before updating, then reload on conflict. Anthropic exposes a content_sha256 precondition for this purpose.
Over-retrieval has a different fix: define a context budget and prioritize applicable, authorized facts. More retrieved text creates more tokens and can preserve contradictions. Exact fields should use exact lookups; broad search should earn its place.
Deletion must follow the derived data. Remove or invalidate dependent summaries, search entries, caches and retained history according to your retention policy. Anthropic's memory version documentation says deleting a live memory does not delete retained versions; historical content has a separate redaction path.
Which Agent Memory Systems Do You Need?
Act when a specific piece of information must survive a specific boundary. You can improve continuity without buying a new service for every kind of forgetting.
For builders, start with a durable session record if unfinished jobs lose their place. Add a small per-user record when later sessions need predictable preferences. Add semantic search only when the useful facts cannot be selected reliably by known keys. Files and skills are the direct route for repeated project instructions and procedures.
For operators, act now when state loss produces repeated work, stale answers or duplicated actions. Record loaded tokens, write frequency and retrieval results alongside corrections. Wait on automatic long-term extraction when no one owns expiry and deletion; first identify the facts that should survive.
For buyers, ask a vendor where state lives, how you inspect and correct it, which boundaries it survives, and how access is enforced. A managed product is useful when it removes lifecycle work your team would otherwise operate. Portability, deletion and your workload's bill should drive the purchase.
You are unaffected if a stateless job receives all necessary current inputs and no later task needs its history. Keeping an audit log can still be valuable, but it does not require automatically injecting that log into future prompts.
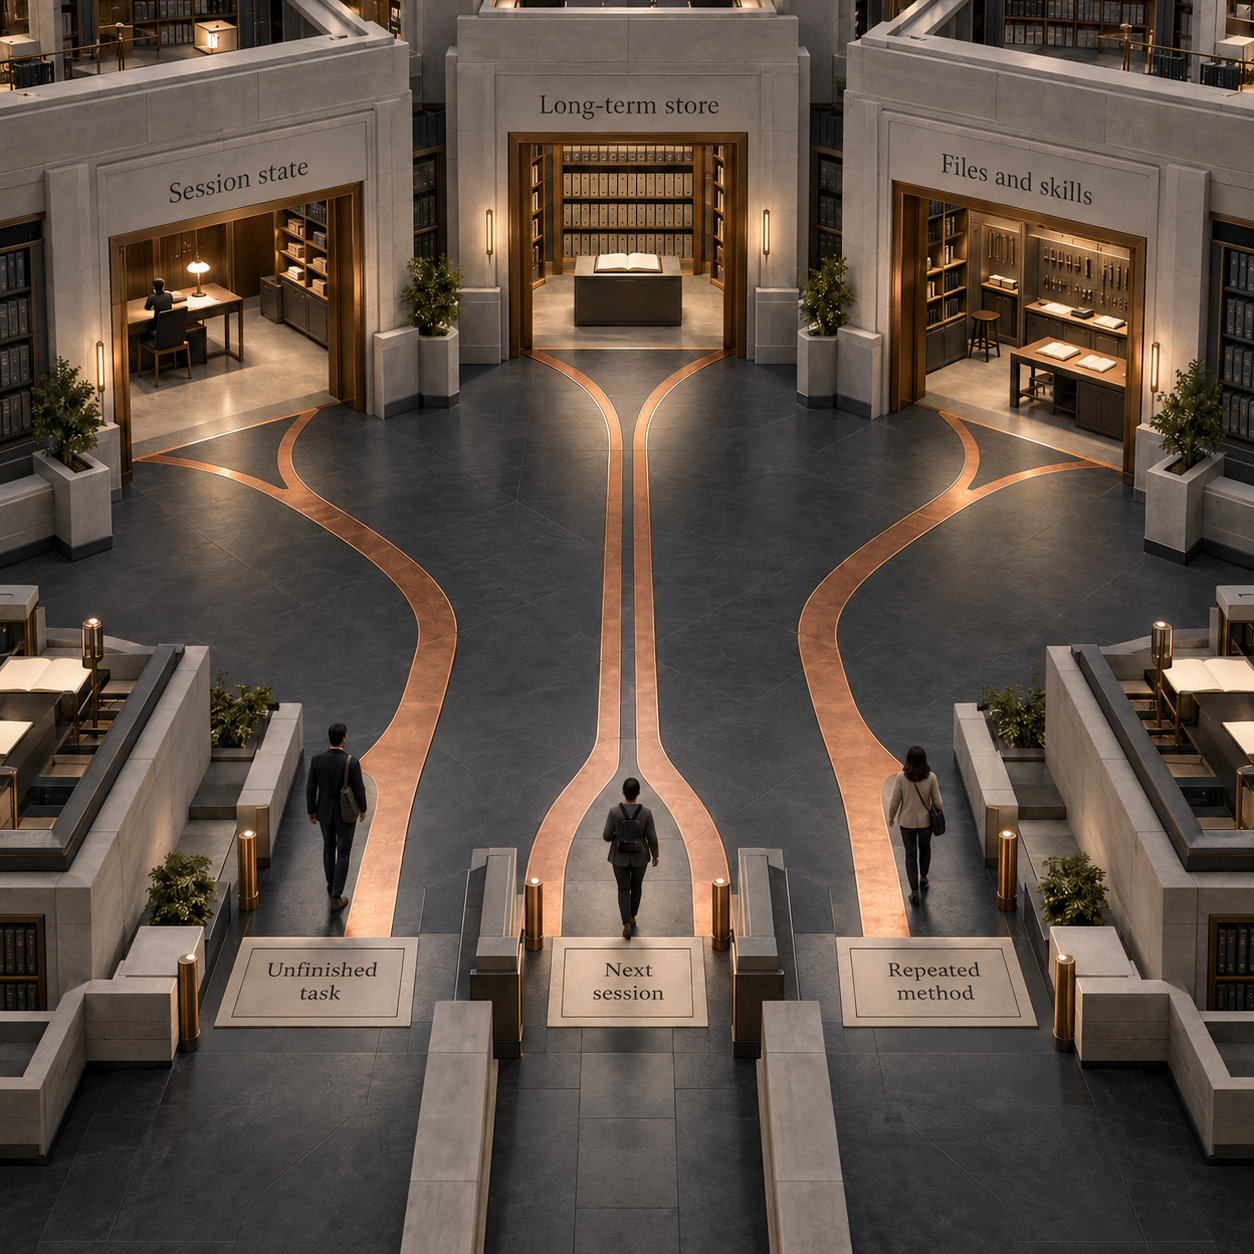
The choice flips when the small solution reaches a named wall. A customer preference field works until you need relevant events from a long history. A session transcript works until every new request must sift through unrelated prior tasks. A runbook works until the missing knowledge is changing customer state rather than a stable procedure.
AI Agent Memory Tools: Where Mem0, Zep and Letta Fit
Mem0 is a memory integration that extracts facts from submitted messages and retrieves them for a chosen user. Its quickstart shows add with user_id, search with a matching filter, and passing returned memories to the model. That last step is the integration boundary: persisted facts still need to be supplied to the agent that answers.
Use that description to understand the architecture. It does not establish that Mem0 is the best purchase for your workload.
Zep builds a Context Graph, a network of facts, relationships and their sources over time. Its own documentation describes timestamps for when facts become valid or invalid. It also states that source provenance does not guarantee correctness. A changing account relationship is a use case for this structure; the source still needs to be trustworthy.
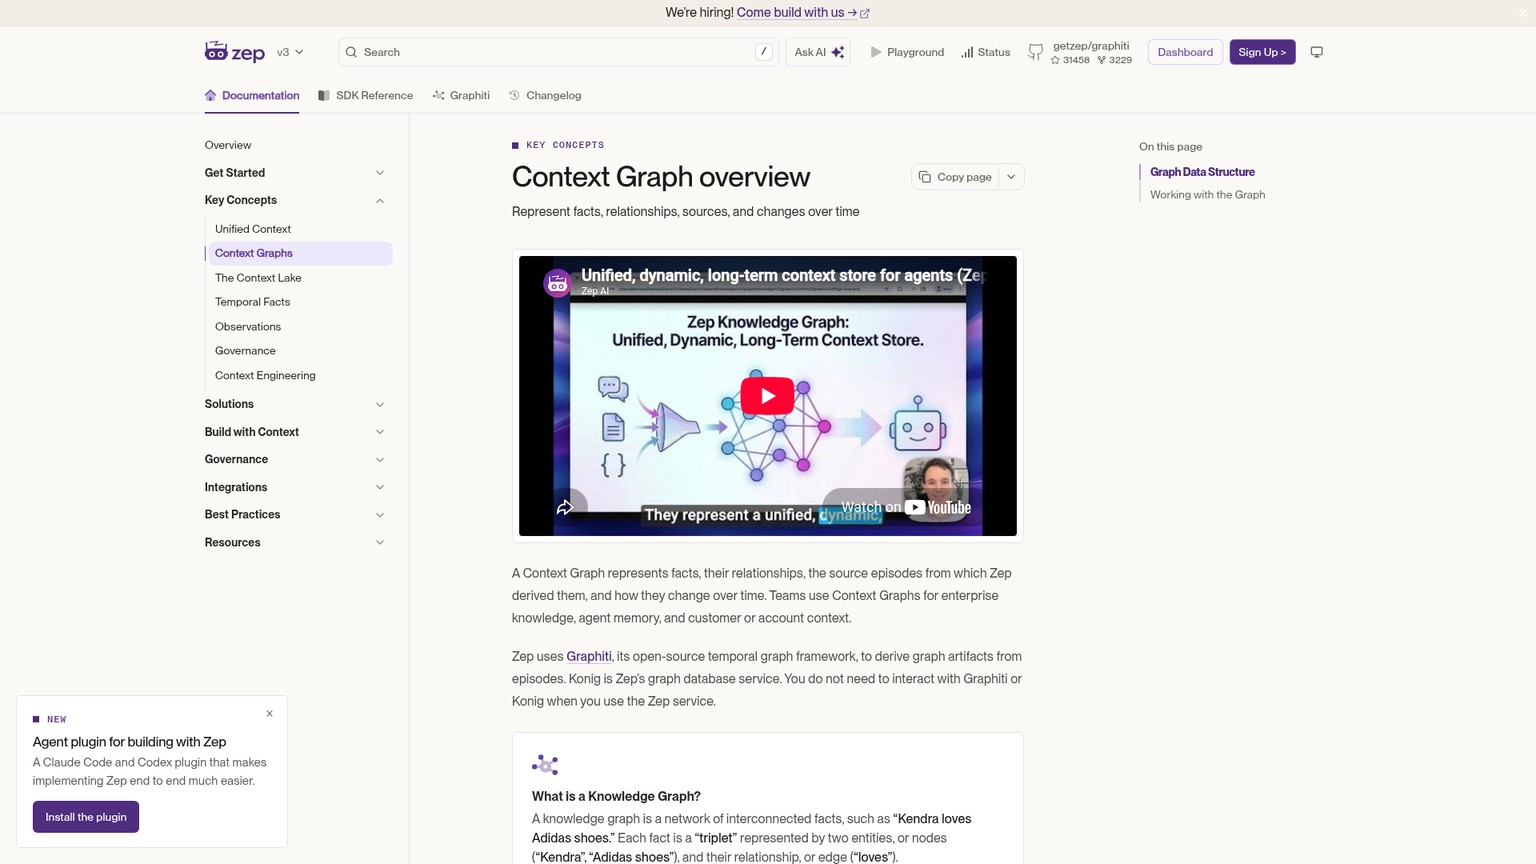
A graph describes how information connects. It does not remove the builder's responsibility for which records a caller may reach.
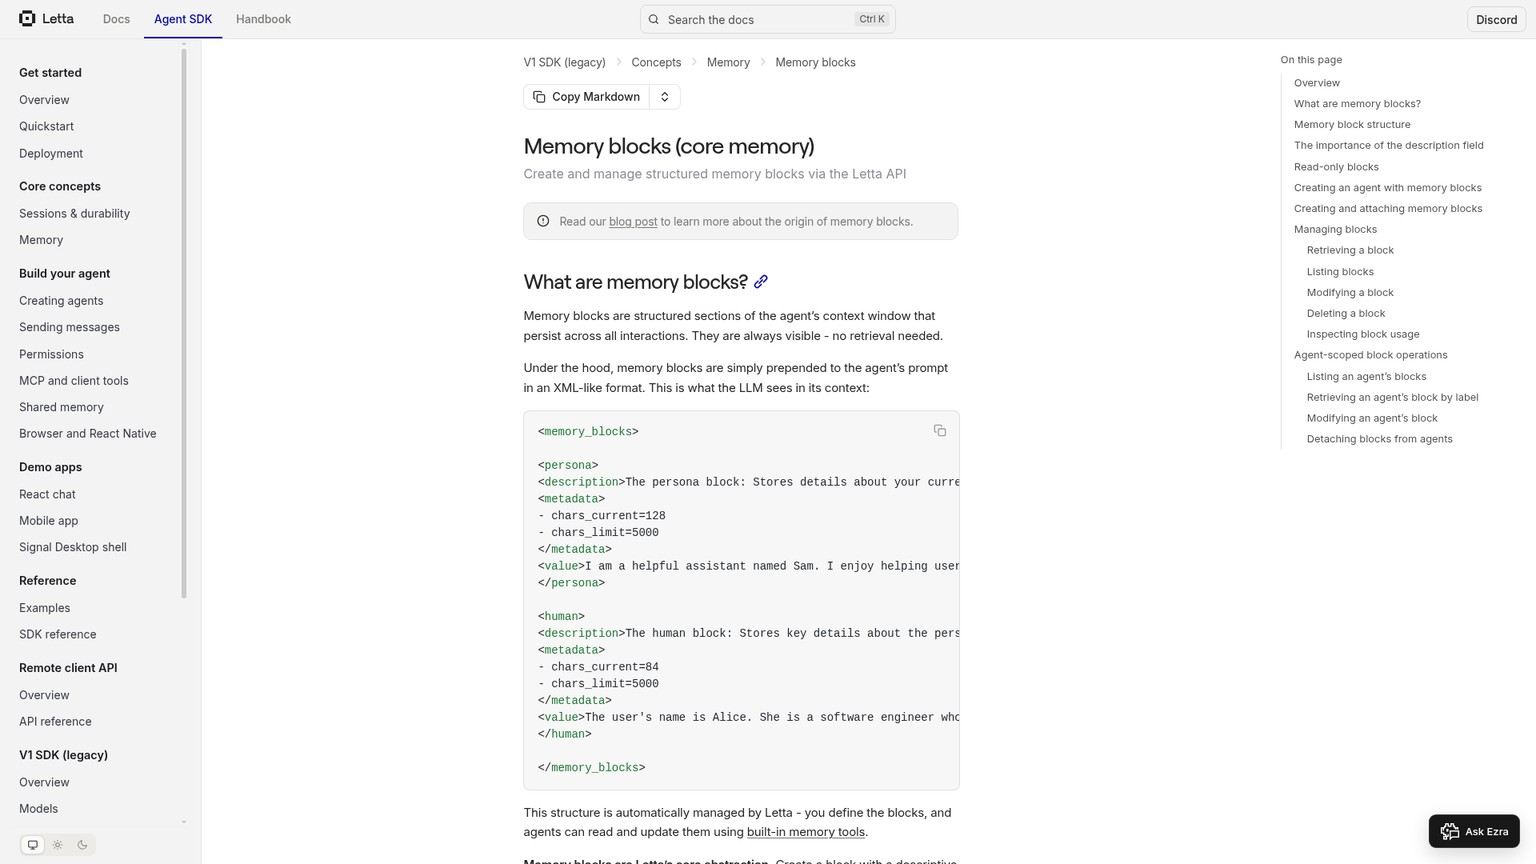
Letta offers memory blocks, persistent sections prepended to an agent's prompt. Its memory-block documentation says blocks are always visible without retrieval and can be read-only. A stable working profile can fit that model. The tradeoff follows directly: always-visible content occupies context, so keep those blocks focused.
For product picks, deployment choices and plan comparisons, go to Best Persistent Memory Systems for AI Agents 2026. Choose the needed layer here, then compare tools against that requirement.
What's Overhyped About Agent Memory?
"The agent remembers everything" is an incomplete product promise. The useful questions are whether a fact survives, whether it is returned for the right task, and whether it remains correct and authorized when used.
A larger context window gives you room to present more material. It does not choose the right customer record. A vector store searches by meaning; it does not inherently determine that an old preference was revoked. An agent-written note preserves an assertion; it does not prove the assertion.
More automatic writing can also create more operating work. Saving every complaint as a lasting preference teaches the agent a distorted customer profile. Repeated extraction can cost more than retrieving a structured field. A collection of short, inspectable and correct facts can be more useful than a huge searchable history.
The strongest buying claim is narrower: the product handles a particular persistence and retrieval lifecycle you need, with controls and costs you can explain. Buy that outcome when it is worth the operating work saved.
The Monday Move: Fix One Forgetting Failure
Pick one recurring workflow and write down exactly what the next run needs. For a support agent, start with an unfinished ticket, a returning customer's contact preference and the procedure for issuing a refund.
Assign each item to its home
Put ticket progress in session and business state, the verified contact preference in a per-user record, and the refund procedure in an instruction file or skill. Keep current payment status in the payment system.
Define who may read and change it
Resolve identity in the host application, enforce scope on every operation and cache, and keep shared procedures read-only for ordinary task sessions.
Build correction and forgetting alongside persistence
Record sources and validity. Give the operator a specific record to correct and a deletion path covering its derived copies and retained versions.
Measure the boundary and the bill
In your own environment, check restart continuity, changed facts and isolated users. Record model tokens, writes, reads, active runtime and correction work. Buy additional memory infrastructure when a named requirement exceeds this small design.
What are the agent memory types?
For production decisions, separate the context window, session state, long-term stores, and files or skills. Episodic, semantic and procedural describe the content: past events, facts, and instructions. They do not prescribe a database or vendor.
What is an agent memory skill?
A skill is a reusable procedure the agent can read and apply. It can preserve a method across sessions; learning and updating customer facts needs a separate write and read lifecycle.
What is AI agent memory architecture?
It combines a write path for useful information with a read path that selects authorized, current material for a model request. Persistence, identity, correction, expiry and the context budget all belong in that architecture.
Can you give agent memory examples?
An unfinished refund ticket needs session state. A returning customer's verified language preference needs a durable record. A refund runbook belongs in a skill or instruction file. Each reaches the context window when the current request needs it.
Get more practical guides to building and operating agents in the newsletter.
- Last Updated
- Oct 5, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Pinecone Pricing (2026): What 1M to 100M Vectors Cost
Pinecone pricing verified October 2026: free Starter, $20 Builder, paid minimums, and costs for 1M to 100M vectors at stated query volumes.Oct 5, 2026Build
Lovable Alternatives (2026): Emergent, Blink, Bolt, Replit and Base44
Compare Lovable alternatives by credit costs, backend depth and code export. Live pricing for Emergent, Blink, Bolt, Replit, Base44 and v0.Oct 5, 2026Build
LLM Observability Tools in 2026: Costs by Team Size for Langfuse, LangSmith, Helicone, Arize Phoenix, Braintrust and Datadog (Compared)
Compare six LLM observability tools by team size, pricing at 100,000 monthly runs, self-hosting licenses and OpenTelemetry support.Oct 5, 2026Build
How to Use OpenCode
Install OpenCode, connect existing model access, run a real coding task, configure AGENTS.md and plugins, and understand API and Zen costs.Oct 4, 2026Build
Netlify Pricing (2026): What a Month Costs in Credits
Netlify's current Free, Personal and Pro prices, credit rates, and monthly budgets for a marketing site, Next.js app and 10-site agency.Oct 4, 2026Build
Softr Review (Verified October 2026)
Softr review for client portals and internal tools: current monthly and annual prices, user and record limits, AI features, and the plan to choose.Oct 4, 2026Build
Claude Code Alternatives: Pi, Codex CLI, OpenCode and Gemini CLI (2026)
Compare Pi, Codex CLI, OpenCode and Gemini CLI with Claude Code: current plans, monthly model costs, open-source limits and switching advice.Oct 4, 2026Build