LLM Observability Tools in 2026: Costs by Team Size for Langfuse, LangSmith, Helicone, Arize Phoenix, Braintrust and Datadog (Compared)
Compare six LLM observability tools by team size, pricing at 100,000 monthly runs, self-hosting licenses and OpenTelemetry support.


Langfuse, a tracing and evaluation platform, is the best default for a small production team: the worked 100,000-run workload below costs $69.80/month on Core before model and evaluator compute. The right LLM observability tools change when you need evaluation-led releases, a gateway, private hosting or incident context in an existing Datadog stack.
Best LLM Observability Tools at a Glance
Start with Langfuse for a shared production dashboard, LangSmith for a LangChain-centered improvement loop, Helicone for gateway-led request monitoring, Arize Phoenix for an operated private deployment, Braintrust for evaluation-led release decisions, and Datadog Agent Observability for production incidents that cross the application stack. Team size matters most when the platform charges for every person who needs to inspect a failure.
A trace is the record of one application run. A span is one operation inside that record, such as a model call, retrieval or tool invocation. An evaluation, often shortened to an eval, checks whether the result met a rule or quality standard. You need all three to explain an agent that returned a plausible answer after taking the wrong action.
Pricing verified against each vendor's own live pricing page on 5 October 2026. Dollar amounts are USD. Entry prices exclude additional usage and model-provider charges unless explicitly included. These products were compared through current pricing and documentation; no hands-on performance ranking is claimed.
Sources: Langfuse pricing, LangSmith pricing, Helicone pricing, Arize pricing, Braintrust pricing, and Datadog pricing.
The important distinction is the unit after “plus.” A platform that bills for an application trace sees a different volume from one that bills for every model call, observation, score or gigabyte. Estimate the record your application emits before comparing the subscriptions.
What 100,000 Agent Runs Cost Each Month
A five-person team running the same agent can face a $69.80 Langfuse bill or a $645 LangSmith bill under the assumptions below. Neither number is a quality score. The difference comes from event accounting, included volume and seat charges.
Use this explicitly modeled production workload:
- 100,000 complete agent runs per month, with one trace per run.
- Five observed operations per run: a root workflow, two model calls, one retrieval and one tool call.
- 200,000 model calls and 500,000 observed operations in total.
- 10,000 externally computed code-evaluation scores, one on each sampled run. Extra model calls or evaluator traces are outside this scenario.
- Five users needing dashboard access.
- 5 GB of processed data in Braintrust, and separately 5 GB of metered storage in Helicone. These are independent assumptions because the vendors' byte meters are not interchangeable.
This resembles a support agent that reads a request, retrieves an order, calls an order-management tool and asks a model to prepare the final response. The numbers are budgeting assumptions, not measurements from a deployed application. An agent that retries, branches or runs evaluators inside the platform will emit a different record.
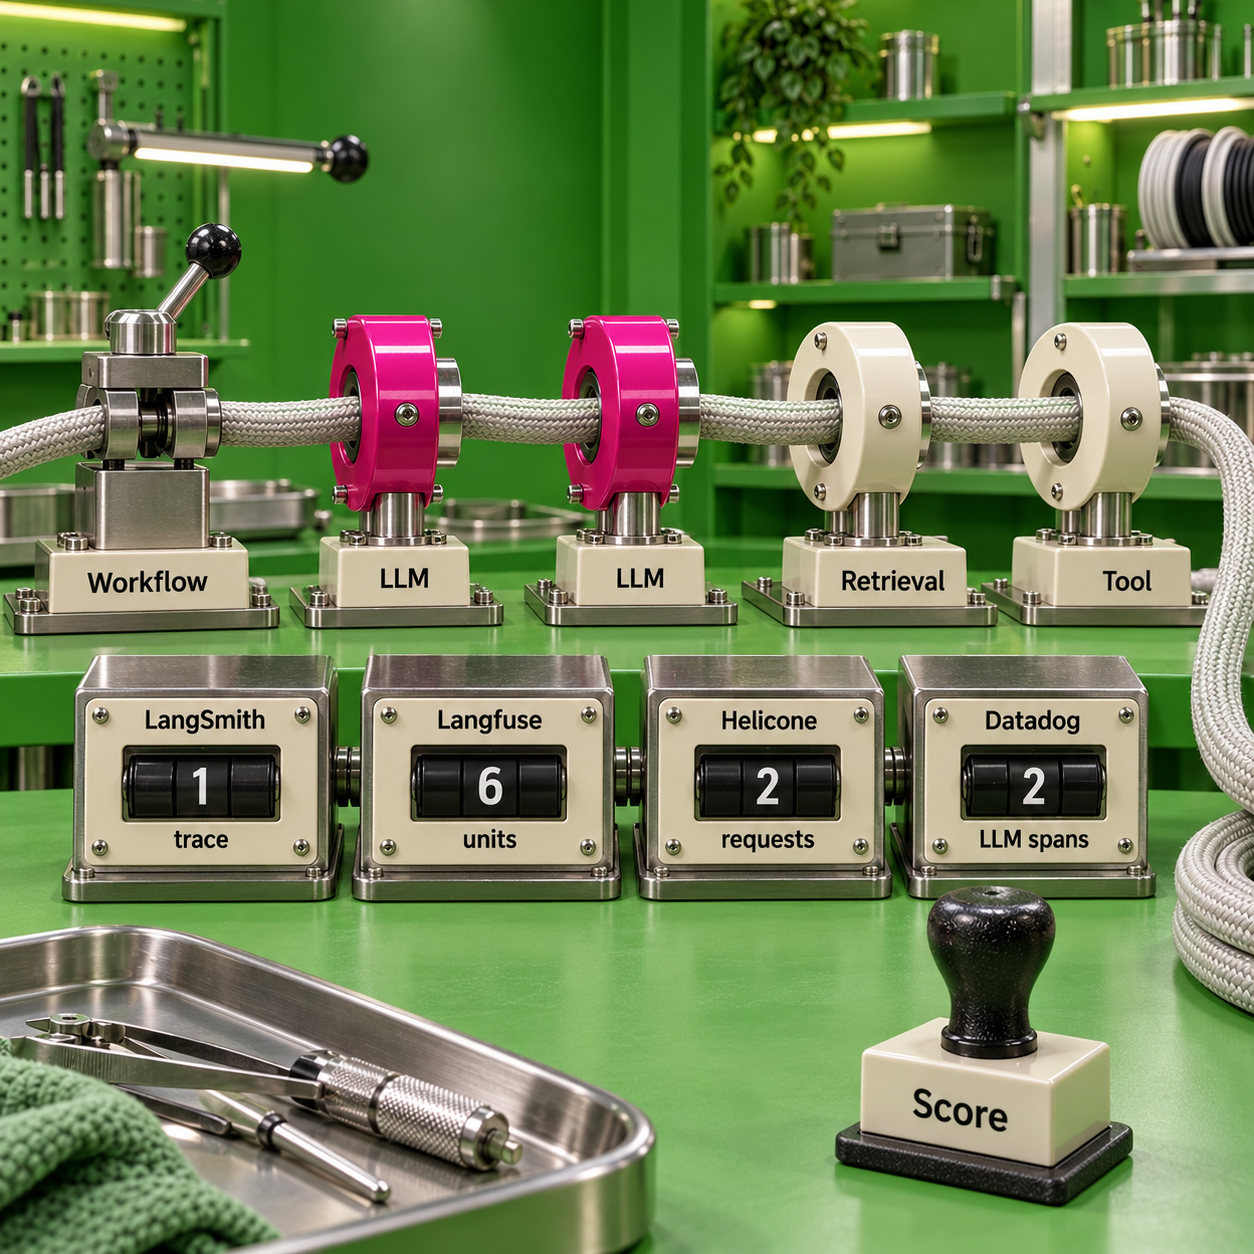
These are calculated from the live vendor rates linked above. LangSmith's total uses the current pricing tooltip's $0.005 per base trace, with 10,000 traces included across the organization. Helicone's range preserves a discrepancy on its own page: the plan table includes 1 GB free, but its calculator charges storage from the first gigabyte. Phoenix has no license-based volume charge; the cost of running its infrastructure needs your deployment's actual sizing.
Do not use these totals as a blanket quote for an agent with longer traces. If your workflow grows from two model calls to a repeated reasoning loop, Datadog and Helicone see more model operations. If you add observations and stored scores, Langfuse sees more units. If you send larger documents with the same trace count, Braintrust sees more processed bytes. The agent token tracking comparison goes deeper on attributing provider spend to a customer or feature.
How These Were Picked
The ranking starts with the purchase a small production team can defend, then moves to tools whose value depends on a particular operating model. A team of developers and an AI lead needs to debug bad outcomes, track customer cost and turn failures into release checks. A product that solves only one of those jobs can still be the right specialist.
Each recommendation turns on five criteria:
- An understandable meter. The buyer can identify whether the bill follows traces, operations, people, scores or data volume, including the free allowance and the next limit.
- A useful production record. A failed answer can be connected to the model, retrieval and tool operations that produced it.
- An improvement workflow. The record can inform an evaluation, dataset, experiment or review decision instead of remaining an isolated log.
- An honest deployment boundary. Free self-hosting, a commercial enterprise license and a customer-owned data plane are described separately.
- Documented instrumentation. OpenTelemetry support is assessed from the vendor's current integration instructions, including the protocol and field mapping where stated.
Six products make this shortlist because they cover distinct choices: a broadly useful tracing platform, a framework-centered development workflow, a gateway, a private local-first platform, an evaluation platform and an operations suite. A broader catalog would add choices without improving this particular budget and ownership decision. This comparison makes no claims about measured ingestion speed, interface usability, uptime or evaluation accuracy.
“Free” is evaluated as a usable allowance, not a promise that the bill stays zero. Braintrust Starter and LangSmith Developer can accrue usage charges. Phoenix's license fee can be zero while database maintenance and on-call work remain material. The right free tier is the one whose limits match the experiment you are trying to finish.
The Six Tools, Ranked by Production Fit
1. Langfuse: Best Default for a Small Production Team
Langfuse gives a small production team shared tracing, token and cost tracking, prompt management and evaluation without a seat charge on Core. A SaaS support assistant can attach a customer, workflow and release to its model calls, then inspect the expensive failures alongside successful runs. Its main budgeting wall is the number of stored records: one agent execution can create a trace, multiple observations and scores. Pick this if you want the trace and the cost record together, with a credible route to self-hosting later.
Best for: A small or growing product group that needs developers and an AI lead to inspect the same production runs
Standout: Unlimited Core users, trace-level cost context and an MIT-licensed self-hosted core
Pricing: Core starts at $29/month; paid Cloud plans add usage billed in units
Free trial: The free Hobby plan needs no credit card; it is an ongoing allowance rather than a timed trial
Every Current Tier and the Limit That Changes the Choice
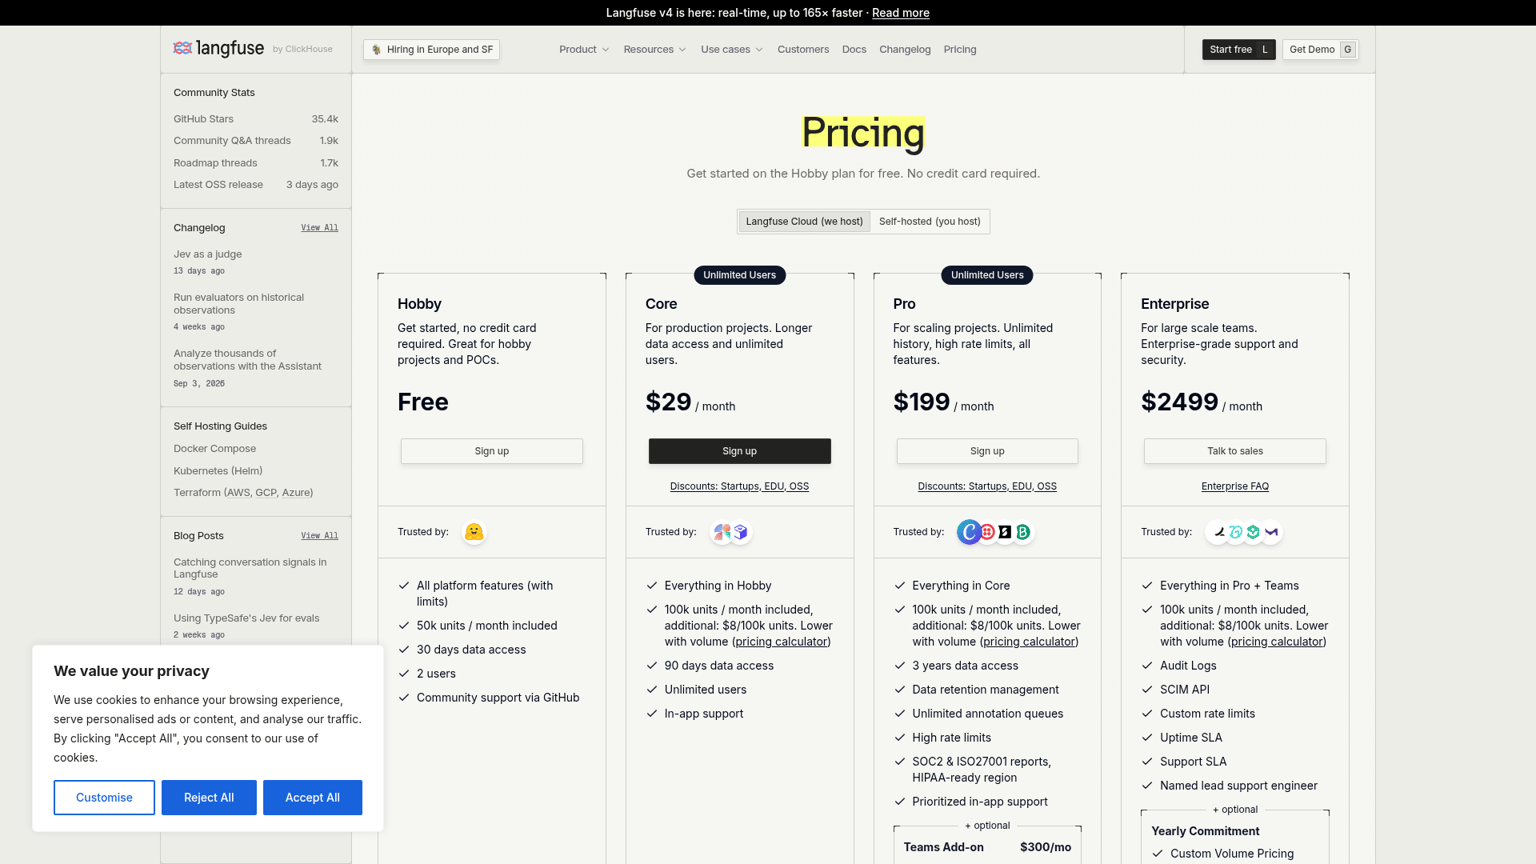
The live pricing page lists Hobby at $0, with 50,000 units/month, two users and 30 days of data access. Core is $29/month, with 100,000 units, unlimited users and 90 days of data access. Pro is $199/month, with the same included units, three years of data access, retention management and higher rate limits. Pro's optional Teams add-on costs $300/month and adds enterprise SSO, enforcement and finer access controls. Enterprise is $2,499/month, with 100,000 included units, audit logs, SCIM and contractual service commitments; yearly commitments can introduce custom volume pricing.
Paid Cloud usage is graduated. The band from 100,000 to one million units costs $8 per 100,000; the band from one million to ten million costs $7 per 100,000; the band from ten million to fifty million costs $6.50 per 100,000. Lower rates apply to the units in their band. The first lower band does not retroactively become cheaper when you cross a boundary.
Core's ingestion limit is 4,000 requests/minute, while Pro lists 20,000 requests/minute. Those are ingestion requests, not the billable-unit definition. A batch can carry multiple stored events. Check both the monthly unit budget and the traffic burst your exporter creates.
Langfuse Trace: Count the Observations and Scores Too
A Langfuse trace is a run record, but the billing formula is traces + observations + scores. For the modeled workload, 100,000 + 500,000 + 10,000 = 610,000 units. Core therefore costs $29 + 5.1 × $8 = $69.80/month. The same stored volume on Pro costs $239.80/month.
That formula changes the instrumentation discussion. A retrieval operation and a refund-tool operation are valuable evidence, even though they increase records. Removing them to lower the bill can leave you unable to explain the failure. Prefer a deliberate sampling policy for low-value successful runs while keeping the evidence you need to diagnose expensive or harmful outcomes.
Hosting, License and OpenTelemetry
Self-hosted Open Source has no license fee under MIT, unlimited usage and the core tracing, evaluation, dataset and prompt-management APIs. Self-hosted Enterprise is commercially licensed and custom-priced. Its current pricing page says Langfuse enterprise pricing is additive to the relevant ClickHouse commercial plan. A cloud subscription and an enterprise self-hosting quote are different purchases.
The OpenTelemetry documentation supports OTLP over HTTP/JSON or HTTP/protobuf, with no gRPC support stated. The base endpoint is /api/public/otel, authenticated with the project's public and secret keys through Basic auth. Direct ingestion into the current v4 path needs the x-langfuse-ingestion-version: 4 header for real-time handling; the docs warn of a delay of up to ten minutes without it. User, session, release and other trace attributes also need propagation to the spans you want to filter and aggregate.
That is a meaningful integration wall for a platform group already exporting gRPC to a Collector. The Collector can receive one protocol and export another, but the final hop to Langfuse must match the documented HTTP endpoint and attribute mapping. An accepted payload with missing customer metadata is not a finished integration.
Langfuse Python: Start with the Documented SDK Path
The vendor recommends its own SDK for Python because it manages the Langfuse fields, propagation and export. Follow the current tracing quickstart, set the project credentials and LANGFUSE_HOST for the chosen region or your own deployment, and wrap the whole business operation in the current observation context. Keep retrieval and tool work inside that context so the trace preserves the cause of a bad response.
Use provider-reported usage where possible. Langfuse cost tracking prioritizes ingested cost over inferred model pricing, and Project Settings > Models accepts custom definitions. That matters when your provider contract uses a negotiated rate or an internal model has no public price. A displayed estimate needs to match the commercial rate you intend to manage.
Langfuse LangChain: Keep the Whole Request in One Context
The LangChain integration uses a callback handler supplied through the invocation's callbacks. Give the surrounding request a trace context, then include the chain beneath it. The documentation also calls out queued background events: short-lived processes must flush or shut down the exporter before exit. In JavaScript serverless environments, await the background callbacks as the guide specifies.
A practical first rollout is small enough to inspect manually:
Create one production tracing project
Choose the Cloud region or self-hosted address, create project keys and configure the host from the current quickstart. Keep production records distinguishable from development records.
Trace one complete business operation
Instrument the request root, model calls, retrieval and tools. Attach customer, workflow, release and outcome metadata to the appropriate spans; verify the required trace attributes propagate.
Check cost against the provider response
Open a completed trace and confirm model identity, usage and cost. Set custom model pricing when an inferred public rate does not reflect your agreement.
Store a score and inspect the meter
Score a known example, verify it attaches to the intended run, then compare trace, observation and score counts with the Usage Management dashboard. Flush the exporter before a short-lived worker exits.
- Core lets every relevant reviewer join without another subscription seat
- The record can combine model calls, tools, retrieval, cost and evaluation scores
- Ingested costs and custom model definitions handle negotiated or private pricing
- MIT core self-hosting gives you an infrastructure-owned deployment option
- Traces, observations and stored scores all consume the Cloud allowance
- Pro and its Teams add-on can raise the fixed fee before usage changes
- The OTel receiver requires HTTP export and correct attribute propagation
2. LangSmith: Best for a LangChain-Centered Improvement Loop
LangSmith is a tracing and evaluation platform for a group that already develops and reviews agents through LangChain or LangGraph, while also documenting instrumentation for other frameworks. A development lead can connect a production failure to a dataset, online or offline evaluation, human review and a prompt revision. The purchasing wall is seats plus traces: inviting more reviewers raises the subscription, while trace volume adds its own charge. Pick this if that development and evaluation workflow is valuable enough to justify a paid seat for every reviewer.
Best for: A development group already organizing agent improvement around LangChain or LangGraph
Standout: Tracing, datasets, annotation queues and online/offline evaluation in the same product
Pricing: Plus $39/seat/month, then trace and other product usage
Free trial: Developer is an ongoing free allowance for one user, with usage charges beyond the included traces
Every Current Tier and the Shared Trace Allowance
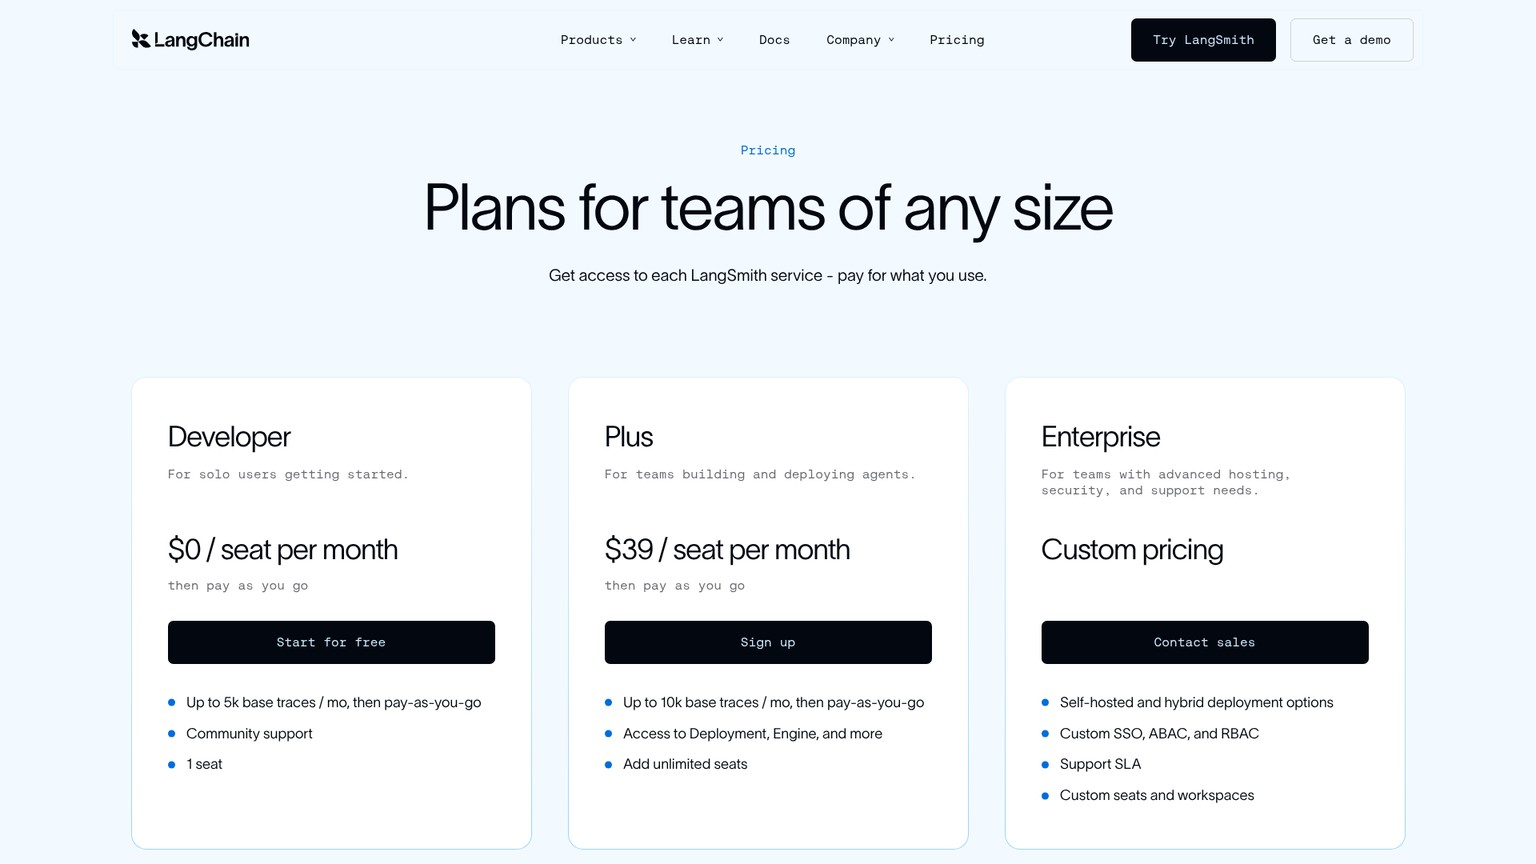
Developer costs $0 per seat/month, supports one seat, and includes 5,000 base traces/month before pay-as-you-go usage. Plus costs $39 per seat/month, permits additional paid seats and includes 10,000 base traces per month in total. The pricing calculator explicitly treats that allowance as shared across the organization. Enterprise is custom-priced and provides the hybrid and self-hosted options, security controls and support arrangements.
The current page's pricing tooltip lists 0.005 LangChain Standard Units per base trace, and 0.0025 per extended-trace upgrade. One LSU equals $1, so those rates are $0.005 per base trace and $0.0025 for the upgrade. Base retention is 14 days; extended retention is 180 days. An old remembered per-trace number is the wrong input for a budget verified today.
For five Plus seats and 100,000 base traces, the bill is $195 in seats + $450 in additional traces = $645/month. If you upgrade 10,000 traces to extended retention, add $25, giving $670 before evaluator compute or other product usage. The upgrade preserves the record for longer; it is not a free side effect of buying Plus.
Tuned Evaluators have another published meter: 0.015 LSU per successful Perceived Error evaluation run. The page's tooltip says a Tuned Evaluator that adds feedback also upgrades the trace to extended retention. Deployment, Engine, Fleet and Sandboxes have separate usage rules. A buyer using only observability should keep the budget scoped to that service rather than treating the seat as an all-inclusive agent runtime.
Why the Seat Count Changes the Recommendation
A group of five developers inspecting traces is different from five developers plus a wider product and quality review. At the same 100,000 base traces, fifteen Plus seats cost $1,035/month, because the seat portion becomes $585 while the additional-trace portion remains $450. More seats do not multiply the shared free trace allowance.
The money can be justified when each reviewer regularly turns traces into corrected prompts, datasets or release decisions. It is harder to justify when most users only need occasional access to a cost dashboard. Decide who must review the raw records, who can work from an exported result and which workflow makes the subscription productive.
Commercial Self-Hosting and OpenTelemetry
Self-hosted LangSmith is an Enterprise add-on requiring a commercial license key. The installation includes frontend and backend services plus ClickHouse, PostgreSQL and Redis; the guide recommends external storage services for production. It is an operated enterprise installation, not a free server license inferred from an open-source framework.
Its OpenTelemetry guide describes traces from compatible applications, standard attribute mappings and Collector fanout, where one span stream is routed to more than one backend. LangChain and LangGraph users can enable the integrated path with LANGSMITH_OTEL_ENABLED=true alongside tracing. A standard HTTP exporter uses the base endpoint https://api.smith.langchain.com/otel, with x-api-key authentication and an optional Langsmith-Project header.
Pay attention to the endpoint form. The shared OTLP base variable lets the HTTP exporter append /v1/traces; a signal-specific traces variable carries the full path. Adding the signal path to both creates an incorrect URL. Check the same trace in the chosen project and confirm its model, inputs, outputs and parent-child structure before treating OTel export as complete.
- LangChain and LangGraph have a documented integrated tracing path
- Datasets, annotation queues and online/offline evals support an explicit improvement workflow
- OTel ingestion and Collector fanout support applications beyond one framework
- Enterprise offers a licensed route to operate the backend in your infrastructure
- Every Plus reviewer costs $39/month, including invited users counted as seats
- The included trace allowance is shared rather than granted per seat
- Longer trace retention and specialized evaluator usage add separate charges
3. Helicone: Best When the Gateway Is the Purchase
Helicone combines request observability with an AI gateway, a service that forwards model requests while applying routing and related controls. A small application that primarily needs to inspect provider requests, manage fallbacks and group model spend can get useful records at that boundary. Its wall is the difference between the gateway and the whole agent: a model request record still needs application context to explain retrieval and business tools. Pick this if the gateway is already part of your design and request monitoring is the immediate job.
Best for: A product group buying request monitoring together with gateway behavior
Standout: An OpenAI-compatible gateway, with a separate asynchronous logging path
Pricing: Pro $79/month, plus graduated logged-request and storage charges
Free trial: Hobby is free; Pro and Team show a 7-day free trial
Every Current Tier, Including Burst Limits
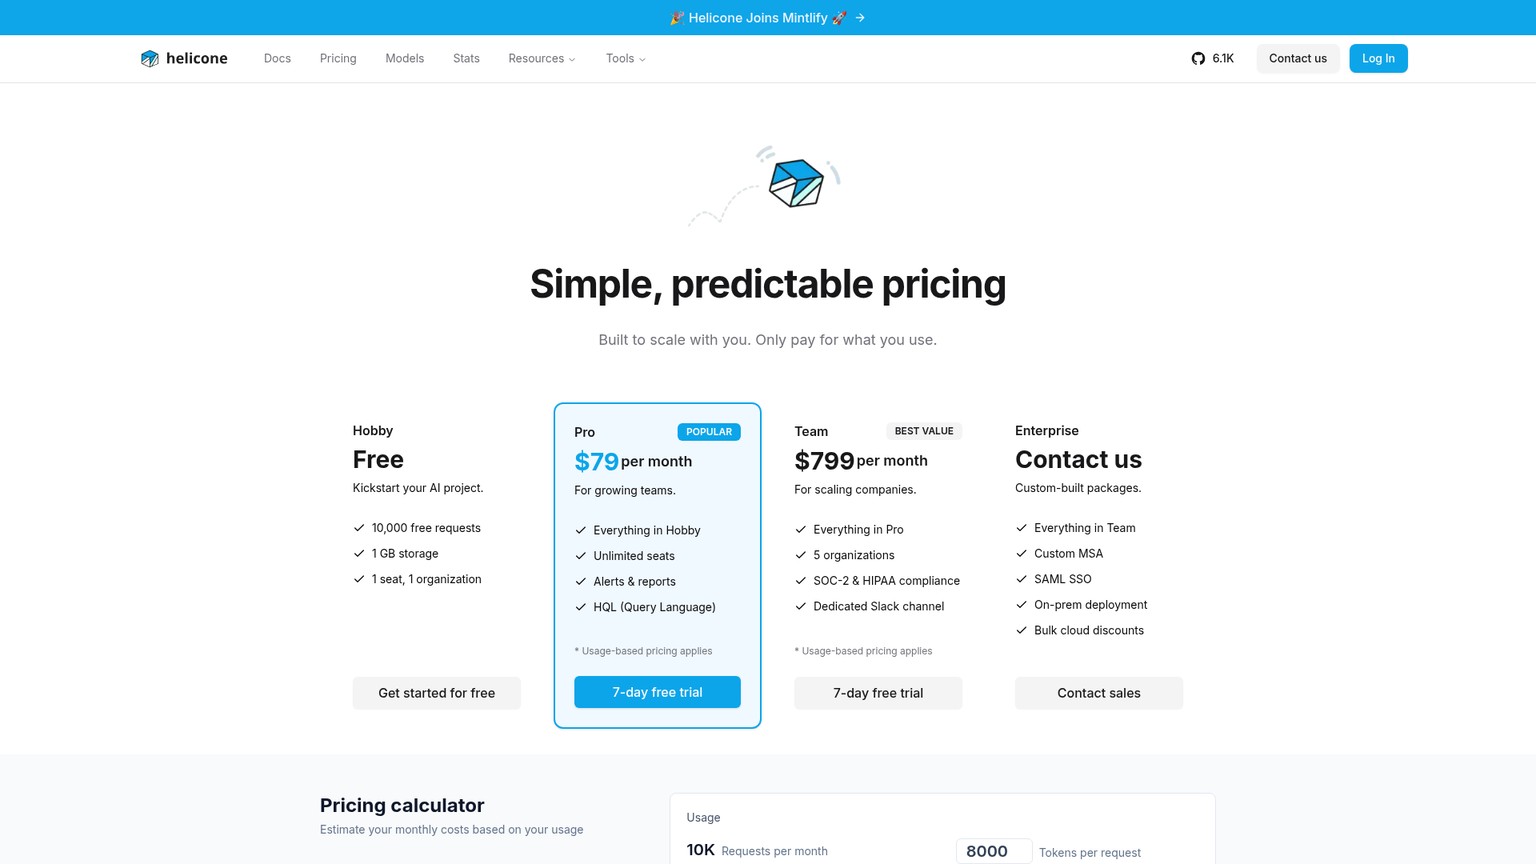
The current pricing page lists Hobby at $0, with 10,000 requests/month, 1 GB storage, one seat, one organization and seven days of retention. Pro is $79/month, adds unlimited seats, alerts, reports and HQL, its query language, and retains data for one month. Team is $799/month, adds five organizations, three months of retention, a dedicated Slack channel and the listed compliance offering. Enterprise is custom-priced, with SAML SSO, on-prem deployment and custom contract options.
The paid plan table includes 10,000 free requests and 1 GB free storage, followed by usage charges. Hobby's published ingestion limit is 10 logs/minute, compared with 1,000 on Pro, 15,000 on Team and 30,000 on Enterprise. The monthly allowance may look adequate while a burst already exceeds the ingestion limit. A queue-driven document job that flushes many records together needs a throughput check as well as a monthly count.
The Pro-to-Team jump is $720/month before usage. Buy it for the organizational, retention and support requirements it addresses. A growing request count alone does not mean that jump is the next unavoidable fee.
The Request Charge and the Storage Discrepancy
The pricing page's live calculator uses graduated request rates: the first 10,000 are free, the next 20,000 cost $0.0007 each, the next 60,000 cost $0.00035 each, and requests from 90,001 through 250,000 cost $0.000175 each. Later published bands fall to $0.0000875, $0.00004375 and $0.00002 per request as volume grows. These inputs come from Helicone's own calculator, not another vendor's comparison.
At 200,000 logged model requests, the request component is $14 + $21 + $19.25 = $54.25. Adding Pro gives $133.25 before storage. Count both model calls in the sample agent; labeling the application as 100,000 “requests” would undercount this meter.
The calculator's storage bands start at $3.25/GB for the first 30 GB, then $2/GB, $1.25/GB, $0.75/GB and $0.50/GB in its larger bands. But the calculator charges that first band from zero, despite the plan table's advertised free gigabyte. With 5 GB metered storage, applying the allowance produces $13 in storage; following the calculator produces $16.25. That makes the illustrative Pro total $146.25-$149.50.
Gateway, Async and the Documented OTel Boundary
The gateway quickstart uses an OpenAI-compatible client pointing at https://ai-gateway.helicone.ai, with automatic logging and fallbacks. You can also bring your own provider keys. Model-provider spend is separate from the observability subscription and logged-request charges.
The Proxy versus Async guide gives the architectural tradeoff directly. Proxy integration places Helicone on the request path and offers gateway features such as caching, retry controls and custom rate limits. Async logging sits off that critical path, but does not provide the same proxy controls. Choose between forwarding the work and observing it in the background before comparing setup effort.
For OpenTelemetry, Helicone documents an OpenLLMetry Async integration. Its current examples use @helicone/async and helicone-async loggers. That is evidence for the documented integration path; the cited guide does not provide a generic OTLP Collector receiver configuration. If your requirement is “change only the Collector exporter,” validate that specific route instead of treating an OTel-related integration as a drop-in OTLP backend.
Self-hosting supports manual installation, Docker Compose, Kubernetes and cloud deployment. The repository's license is Apache 2.0. Dedicated support and enterprise services remain a separate discussion. For a small team, the recurring cost of operating the stack can outweigh the telemetry bill even when the software license is free.
A rollout should answer an application question, not stop at a visible request. Attach the workflow and customer identifiers, send a known model call, inspect the record, and confirm that a session links the calls you intended to group. Then run the same check with a retry or failed response. A gateway view becomes useful production evidence when you can tell which business operation caused the extra model work.
- Pro includes unlimited seats for a shared request-monitoring workflow
- The gateway and async paths let you choose the request-path tradeoff
- Graduated request charges can be calculated from the vendor's live page
- Apache 2.0 and documented deployment options support self-hosting
- Model requests are a different unit from complete agent runs
- The published storage allowance and calculator need reconciliation
- Async logging does not carry the gateway's caching, retries or rate-limit controls
- A generic Collector-to-OTLP ingestion route is not established by the cited integration guide
4. Arize Phoenix: Best for Private Tracing with an Infrastructure Owner
Arize Phoenix is a local-first tracing, evaluation and experimentation platform that you can run in your own infrastructure without a license fee. A platform engineer investigating a retrieval assistant can inspect model calls, retrieved context and tool work, then collect failures into a dataset and compare a revised application. Its wall is ownership: someone must operate the service and understand the license boundary. Pick this if a private, controllable tracing and evaluation deployment matters enough to assign an infrastructure owner.
Best for: A technical group that wants to operate its tracing and evaluation backend
Standout: OTLP traces and OpenInference instrumentation, with local datasets and experiments
Pricing: Phoenix self-hosting has no license fee; no paid Phoenix tier is published on the current Arize pricing page
Free trial: Self-hosted Phoenix is free to use within its license; Arize AX has a separate free plan
Phoenix Is Not the $50 AX Plan
The current Arize pricing page prices AX, while describing Phoenix separately as its local-first platform. AX Free includes 25,000 trace spans/month, 1 GB/month ingestion, 15-day retention and unlimited users and evals. AX Pro costs $50/month, with 50,000 spans, 10 GB/month ingestion, 30-day retention and unlimited users and evals. AX Enterprise is custom-priced, with custom volume and retention and SaaS or self-hosted deployment.
There is no published paid Phoenix instance price or Phoenix overage schedule on that page. Calling Phoenix “$50/month” would merge two products. If you want a managed Arize purchase, assess AX with its own span and byte limits; if you want Phoenix, budget the infrastructure you will operate.
In the modeled application, 500,000 spans are ten times AX Pro's included span volume. The public page does not publish an overage rate for that case, so the useful answer is a quote rather than an extrapolated price. At five spans per run, AX Free's span allowance corresponds to 5,000 runs, and Pro's to 10,000, assuming the byte and other limits also fit.
For self-hosted Phoenix, the software license fee stays zero at the modeled volume. That is not a claim that 500,000 stored spans cost nothing to retain. Choose a storage policy, estimate your payload size, include backups and assign a person to handle upgrades and recovery. “We already operate this infrastructure” and “we need a new private platform” produce different total costs.
License: Read the Backend's Terms
The Phoenix backend's current repository license is Elastic License 2.0. It permits use subject to its restrictions and prohibits offering substantial product functionality to third parties as a hosted or managed service. It also restricts bypassing license-key functionality and removing licensing notices. That is a different permission model from Langfuse's MIT core and Helicone's Apache 2.0 license.
Use this distinction in procurement language. “Code is available,” “free for our deployment” and “permissive license for repackaging as a service” are different claims. The article's recommendation concerns operating Phoenix for your application's tracing and evaluation; it does not assume rights to resell Phoenix as a hosted product.
The self-hosting guide states that Phoenix has no license fees, usage limits or feature gates for self-hosting and can run fully air-gapped. It documents terminal, Docker/Compose, Kubernetes/Helm and cloud deployment choices. A private installation still needs a configuration and recovery plan appropriate to the data it stores.
OpenTelemetry and the Evaluation Workflow
Phoenix accepts OTLP traces and is built around OpenTelemetry and OpenInference instrumentation. Its documented record includes model calls, retrieval, tools and custom logic. Evaluations can use model-based judges, code checks or human labels. Datasets and experiments let you rerun different application versions against the same inputs, while prompt tools support versioning and replay.
The tracing setup guide offers phoenix.otel for Python and @arizeai/phoenix-otel for TypeScript, plus project and session organization. A Collector-based group should verify the same actual semantic fields in Phoenix that it uses elsewhere. Preserving a trace ID is useful; preserving which operation retrieved the wrong context is what makes it actionable.
For a retrieval assistant, start with a known failure: the model produced a confident answer from an irrelevant document. Inspect whether the retrieval span contains the evidence needed to distinguish a search problem from an answer-generation problem. Preserve that input and expected behavior in a dataset, change one retrieval or prompt setting, and compare the result. A repeatable example is the bridge between observing a problem and preventing its return.
- Self-hosting has no software license fee or usage ceiling stated in the guide
- The documentation supports an air-gapped deployment
- OTLP and OpenInference connect tracing to common instrumentation paths
- Datasets, experiments and multiple evaluation types support regression work
- ELv2 has restrictions that a permissive-license shorthand would hide
- Your organization owns infrastructure, retention, upgrades and recovery
- Paid AX limits and prices do not describe a paid Phoenix subscription
5. Braintrust: Best When Evaluations Decide Releases
Braintrust is an evaluation and observability platform for a group that makes release decisions from scored examples, datasets and experiments. A product AI lead comparing a prompt revision can inspect traces and decide whether the new output passed the same checks as the old version. Its budgeting wall is processed data plus scores, with model compute and longer retention layered on top. Pick this if the evaluation workflow has an owner and changes what you release; start with Starter when its limits and features fit.
Best for: An AI product group with maintained evaluation datasets and release criteria
Standout: Unlimited Starter users, projects, datasets, playgrounds and experiments
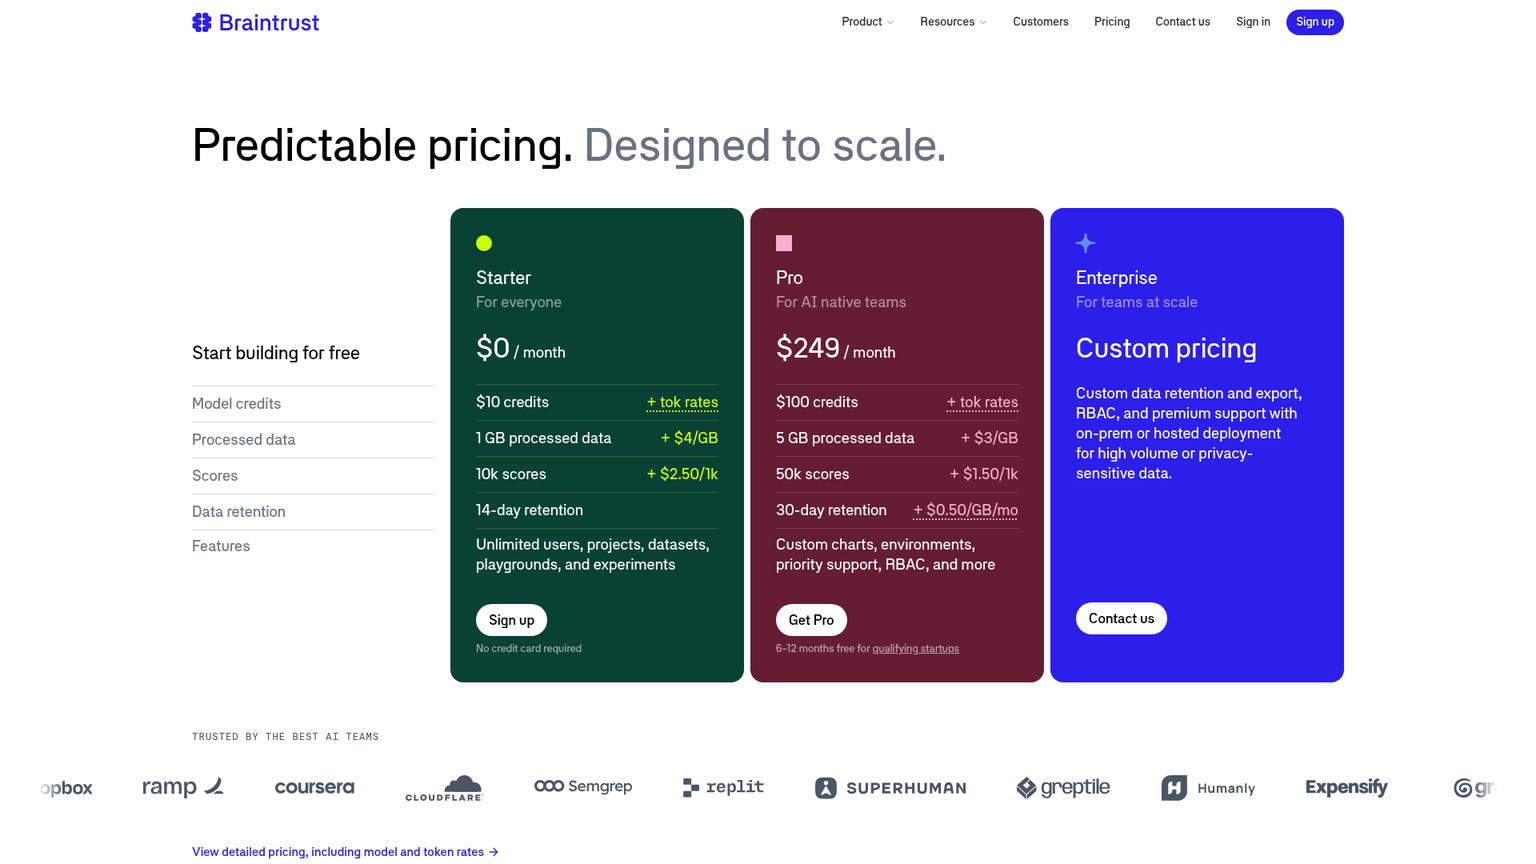
Pricing: Starter has a $0 platform fee with paid usage; Pro costs $249/month plus usage
Free trial: Starter is an ongoing free allowance with no credit card required to begin
Every Current Tier and Both Usage Meters
Starter has a $0 monthly platform fee, 1 GB processed data/month, then $4/GB; 10,000 scores/month, then $2.50 per 1,000; 14-day retention; and $10 in monthly model credits. Users, projects, datasets, playgrounds and experiments are unlimited. A group can therefore need a shared evaluation workspace without immediately needing Pro.
Pro costs $249/month, with 5 GB processed data, then $3/GB; 50,000 scores, then $1.50 per 1,000; 30-day retention, with extra retention billed at $0.50/GB/month; and $100 in monthly model credits. It adds custom charts, environments, role-based access controls and priority support. Enterprise is custom-priced, with custom retention and export, support and on-prem or hosted deployment arrangements.
A score is an evaluated output, whether produced by a model judge, an automated evaluation or a custom code scorer. The charge for storing or processing that score is distinct from the compute that produced it. The included model credits have their own scope; they are not a refund against every application's provider invoice.
At the modeled 5 GB and 10,000 scores, Starter's bill is $16 in data overage and no score overage. Pro is $249 before any extra usage. If your immediate need is a shared dataset, experiments and traces within the free plan's feature limits, the $249 upgrade needs a feature or retention reason.
When the Lower Usage Rates Start to Matter
At 100,000 scores/month with the same 5 GB processed data, Starter costs $241, while Pro costs $324, before model usage and retention extensions. Pro's lower unit rate does not automatically overcome its fixed fee.
Under that same byte assumption, the usage-only break-even is 183,000 scores/month, where both plans reach $448.50. That calculation excludes the different model credits, retention and capabilities, which may justify an earlier upgrade. It is a budgeting threshold, not a recommendation to delay useful access controls.
The operational question is which checks earn their cost. A support workflow may need a deterministic tool-argument check on every run and a model-based answer-quality review on a sample. Those checks have different purposes and different compute costs. Maintain a known dataset for releases, then sample production to discover failures the dataset did not anticipate.
Avoid treating a high average score as a complete release decision. Group examples by workflow and outcome so an improvement on easy answers cannot hide a regression on the difficult action your customers care about. That is editorial evaluation practice, not a claim that any platform automatically supplies a correct rubric.
OTel Ingestion and Commercial Data-Plane Hosting
The OpenTelemetry integration documents an OTLP trace exporter, a Braintrust span processor, a logs exporter and Collector forwarding for logs. The base API endpoint is https://api.braintrust.dev/otel; authentication and the x-bt-parent=project_id:... header target the intended project. Signal-specific endpoints include the trace or log path. The separate @braintrust/otel package supports the documented JavaScript integration.
Use the integration's field-mapping instructions to verify inputs, outputs and metadata after ingestion. The fact that a log line and an application span are both accepted does not make them equivalent evaluation records. Confirm which object will become the input to the experiment you intend to run.
The deployment plans reserve BYOC and self-hosting for Enterprise. This is a commercial platform purchase, not an open-source backend license. More specifically, the architecture guide keeps the control plane, including UI, authentication and management metadata, in Braintrust's SaaS. The data plane, where traces, datasets and other AI data live, can run in your own cloud account. The browser communicates directly with that data plane.
That distinction decides some procurement choices. Owning where prompts and outputs reside can satisfy a data-location requirement while leaving a dependency on the vendor's control plane. An organization that requires every product component offline should compare that architecture with Phoenix's documented air-gapped option before signing.
- Starter supports a shared evaluation workspace without seat fees
- Processed-data and score allowances make separate budget components visible
- Pro provides a clear feature upgrade for charts, environments, access and retention
- Documented OTel paths can accept an existing instrumentation stream
- Large payloads and score volume are separate sources of usage charges
- Pro's lower unit rates do not always offset the $249 subscription
- Model-judge compute and longer retention require their own budget
- Self-hosted data storage does not move the SaaS control plane into your infrastructure
6. Datadog Agent Observability: Best for an Existing Operations Stack
Datadog Agent Observability is the current vendor name for the product commonly searched as Datadog LLM Observability, and its strongest fit is a group already investigating application incidents in Datadog. A support-agent timeout may originate in a model call, a slow service or a user-session problem. The platform's value is connecting the agent record to that wider operational context. Its wall is the commitment and retention decision, plus the cost of any surrounding Datadog products you need. Pick this if the people responsible for the incident already work in Datadog and the shared context changes the investigation.
Best for: An SRE or platform group linking AI failures to application and infrastructure incidents
Standout: Billing for LLM spans rather than every retrieval, tool or workflow operation
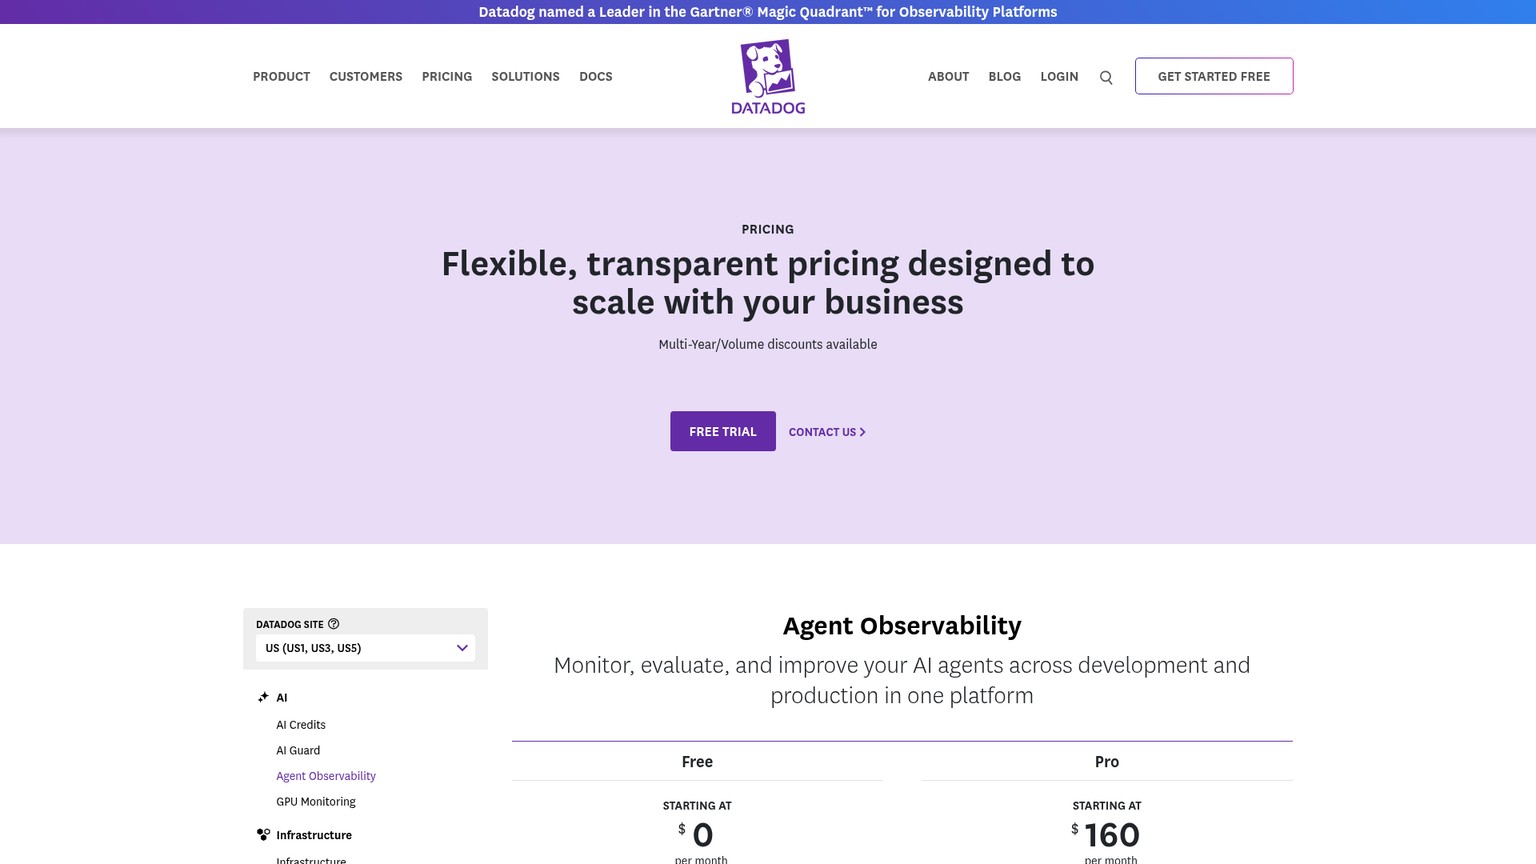
Pricing: Pro $160/month on an annual commitment, $200 month-to-month or $240 on-demand, then additional LLM spans
Free trial: Free includes 40,000 LLM spans/month; the pricing page also offers trial signup
Datadog LLM Observability Pricing
The current pricing page lists Free at $0, with 40,000 LLM spans/month, 15-day trace retention, unlimited context and evals, and full feature access. Pro includes 100,000 LLM spans/month, also with 15-day trace retention. The base price is $160/month billed annually, $200 month-to-month or $240 on-demand.
Additional LLM spans cost $3.50 per 10,000 on the annual rate, $4.20 month-to-month, or $5 on-demand. For 200,000 LLM spans, the modeled totals are $195, $242 and $290, respectively. Compare commitments explicitly: the annual-rate headline is not the month-to-month bill.
The billable unit is a model call, not every operation in the trace. The vendor says tool, retrieval and surrounding workflow spans are not billed as LLM spans. At two model calls per run, the Free allowance corresponds to 20,000 complete runs, subject to the rest of the plan's conditions. More tool instrumentation need not mean more billable LLM spans, while a reasoning loop that repeatedly calls the model does.
Extended retention is available, but the public page does not provide an extended-retention tariff for this comparison. Get that requirement priced when you need to investigate older incidents. A fully instrumented record that has already expired cannot support a later customer dispute.
Datadog AI Observability and the Existing Operations Stack
Agent Observability is a standalone purchase; the vendor says other Datadog subscriptions are not required. Its pricing page also describes the additional value of correlating with APM, infrastructure monitoring and Real User Monitoring when you use those products. A greenfield buyer should budget them separately rather than assuming the observability subscription buys the rest of Datadog.
The product includes datasets, experiments, evaluations, annotations and dashboards across its published tiers. Its cost view breaks usage down by provider, model and prompt identity or version, with costs available on traces and spans. That gives the incident owner a way to distinguish a traffic increase from a change in the model work performed by the application.
A platform lead should make the correlation concrete in a proof of fit. Start with a failed agent run and follow the request to the service responsible for the tool response. Check that the trace identity survives the boundary and that the operator can distinguish model latency from time spent elsewhere. This is the workflow you are buying; a standalone spend graph would not establish its value.
SaaS Licensing and OpenTelemetry
Datadog supplies this product as a commercial SaaS service under its subscription agreement. Its terms identify the MSA as governing the hosted service. The current product pricing page offers no self-hosted Agent Observability backend. Running a Datadog Agent or OTel Collector yourself does not mean you host the storage, interface and evaluation platform.
The OpenTelemetry guide accepts traces following GenAI semantic conventions 1.37 or later, or supported OpenInference conventions. It documents direct ingestion without requiring the Datadog Agent or Agent Observability SDK. The shown exporter uses OTLP/HTTP protobuf, with dd-api-key and dd-otlp-source=llmobs headers.
External evaluations have a specific integration detail: for OTel spans, the docs require the source:otel tag and decimal-string trace and span IDs. Native OTel IDs are hexadecimal, so they need conversion before submission. Validate one evaluation against a known trace instead of assuming that compatible tracing also makes evaluation attachment automatic.
- Only LLM spans drive the published volume meter; tool and retrieval spans are excluded
- Existing Datadog operators can connect agent records to wider production context
- Free and Pro include the listed evaluation and experimentation features
- Direct OTel ingestion is documented without requiring a Datadog Agent
- The lowest advertised rate requires an annual commitment
- Included trace retention is 15 days on both published tiers
- Other Datadog services remain separate purchases
- The product is a hosted commercial backend rather than a self-hosted observability server
Who Should Pick What by Team Size
Choose by who must act on the records, then by which meter grows with the application. Headcount is a budget input, not a substitute for knowing whether the owner is a developer, AI product lead or incident responder.
One or two developers: Start with the free allowance that lets you finish the first production review. Langfuse Hobby fits a shared view for two people, although its 50,000 units shrink quickly when one run emits several operations. LangSmith Developer fits one user. Braintrust Starter is attractive when a maintained dataset and scored release check are already the goal. Phoenix fits when you consciously choose to operate the backend.
Three to ten people: Langfuse Core is the default when several developers and a product owner need routine access. Braintrust Starter can be less expensive when its data, score, retention and feature limits fit an evaluation-first workflow. Helicone Pro earns its fee when the gateway and request-monitoring functions are part of the purchase. LangSmith Plus earns its seat cost when reviewers actively use its development loop.
A larger cross-functional review group: Count every paid LangSmith user before adding a quality, product or support function to the workspace. Unlimited-user plans can keep the subscription stable while participation grows. That still leaves trace, byte and score volume to manage. The decision flips when a platform's specific workflow saves more review effort or prevents more repeated failures than the subscription difference costs.
An SRE or platform group already in Datadog: Prefer Datadog when an agent incident must be investigated together with services and user sessions. Existing ownership and trace context can make a separate specialized console less useful. Its lower LLM-only volume meter also deserves attention when the agent has many non-model operations.
A private-hosting requirement: Phoenix and Langfuse have materially different license and deployment choices; Helicone adds an Apache-licensed option. LangSmith and Braintrust self-hosting involve commercial enterprise arrangements. Braintrust's customer-owned data plane still uses the vendor's control plane. Decide what must stay within your infrastructure before deciding which tier is cheap.
The explicit rule is simple: pay for the workflow that changes a production decision, then forecast the records and people that workflow creates. If you cannot name that decision, begin with a narrower rollout.
OpenTelemetry Support: Check the Path and the Fields
OpenTelemetry support is useful only when your application's important fields survive ingestion. OTel is a standard instrumentation system; OTLP is the protocol used to send its telemetry. A span stream can travel successfully while the backend misses model identity, usage, customer context or the relationship between a tool and its caller.
The documented paths differ. Langfuse accepts HTTP JSON or protobuf at its OTLP endpoint and states that gRPC is unsupported. LangSmith accepts OTel tracing with mapped GenAI, OpenInference and other attributes, and documents Collector fanout. Phoenix accepts OTLP and uses OpenInference instrumentation. Braintrust documents trace, span-processor and log ingestion paths. Datadog specifies supported GenAI or OpenInference conventions. Helicone documents its OpenLLMetry async integration; its cited guide does not establish a generic Collector OTLP receiver.
For a proof of fit, preserve one representative run across the whole path. Confirm its parent-child relationships, model name, tokens, cost, input/output policy and release metadata. If two services participate, check that context crosses the boundary. If the platform groups conversations into sessions, verify the session identifier rather than assuming a common trace ID covers the entire conversation.
Check the endpoint variable carefully. A shared base endpoint and a signal-specific traces endpoint are different configuration forms. Use the vendor's region, authentication and path instructions. Then check the record in the destination project; a successful HTTP response establishes acceptance, not correct business attribution.
Finally, count duplicate export paths. A framework callback and a separate auto-instrumentation library may observe the same model call. Before declaring a cost spike, check whether you added model work or recorded it twice. The failure analysis comparison helps connect the resulting trace to a concrete debugging question.
The Ones to Avoid
Avoid the wrong purchase for the job, even when the product belongs on the shortlist. These are specific mismatches with the documented billing or operating model.
- LangSmith Plus for a shared cost screen alone: The modeled five-person workload costs $645 before retention upgrades and evaluation compute. Pay that when its improvement workflow is part of the job; a larger reviewer list should have a clear purpose.
- Braintrust Pro for light evaluation usage that fits Starter: The modeled Starter bill is $16 versus $249 on Pro. Buy the feature, retention or support upgrade deliberately.
- “Phoenix at $50” procurement estimates: That price belongs to AX Pro. At the sample volume, AX's public span allowance is insufficient and no overage tariff is published. Phoenix's operated infrastructure has a different budget.
- Helicone Hobby for a burst-heavy production worker: A 10,000-request monthly allowance does not remove the published 10-logs/minute ingestion limit. Verify the traffic shape before relying on the free tier.
- Datadog's annual headline for a monthly-budget approval: $160 is the annual-rate base; the month-to-month base is $200, and the modeled monthly-rate total is $242.
- Any self-hosting option without an owner: A free license does not assign responsibility for backup recovery, upgrades or data access. A commercial “self-hosted data plane” also does not automatically move the whole product into your environment.
A precise-looking cost chart with missing usage is a poor budget control. Compare a known request's provider usage with the stored record, and reconcile the aggregate to the bill you actually pay. An observation platform explains spend; a stopping policy has to affect the application's next action.
The Monday Move: Make a Failed Run a Release Test
Instrument one valuable workflow and make one known failure repeatable before expanding the rollout. A support assistant that retries an order lookup, selects the wrong document or drafts an unsupported refund is a useful candidate because the owner can state the expected behavior.
Name the workflow owner, the release identifier and the business outcome. Capture the complete run, inspect its model and tool operations, and verify the usage fields. Check what happens when the exporter is slow or a short-lived worker exits. The first adoption test is whether the records arrive with enough context to answer the owner's question.
Next, put the known failure into a dataset with a clear expected result. The expected result might be “do not promise a refund without the tool's approval” or “cite the retrieved policy that applies to this customer.” Use a code check where the rule is deterministic and a reviewed quality rubric where judgment is necessary. Preserve the input and rule so a prompt or model change faces the same test later.
Make the release gate explicit. A passing average should not conceal a failure on the action you are trying to protect. Review the outcome for the named difficult case and inspect the trace when it fails. Then sample production to find new cases that need to join the dataset.
Before the next subscription decision, record your actual trace count, operations per trace, model calls, stored scores, processed or retained bytes, reviewers and retention need. Recalculate the bill using those numbers. The useful output of the first week is a corrected workflow and a defensible budget, with a named person responsible for each.
Frequently Asked Questions
What's the best tool for AI observability?
Langfuse is the default for a small production group that needs shared tracing and costs. Braintrust fits evaluation-led release decisions, Phoenix fits an owned private backend, and Datadog fits an existing operations workflow. The owner and deployment boundary decide which specialist should replace the default.
What are the observability metrics used in LLMs?
Track token and provider cost, latency, errors, retries, retrieval and tool outcomes, and evaluation results. Group them by customer, workflow and release. Cost per successful business outcome is more useful than total tokens when failed runs and retries consume meaningful spend.
What are the top 3 observability tools?
For the three production roles in this comparison, choose Langfuse for general shared tracing, Braintrust for evaluation-led product work, and Datadog for operations context. That is a role-based shortlist, not a claim of measured superiority across every feature or deployment.
What are some open source tools for LLM observability?
Langfuse's core is MIT-licensed and Helicone's repository is Apache 2.0. Phoenix is available for free self-hosting, but its backend uses Elastic License 2.0 with hosted-service restrictions. Check the actual backend license instead of treating every product described as open source as permissively licensed.
What are LLM observability tools?
They record how a large language model application ran, including model calls, tools, retrieval, timing, usage and output checks. The useful result is an explainable failed run that can guide a fix and become a repeatable release test.
How much does Langfuse cost?
Verified on 5 October 2026: Hobby is free, Core is $29/month, Pro is $199/month and Enterprise is $2,499/month. The optional Pro Teams add-on is $300/month. Paid plans add usage for traces, observations and scores; the modeled 610,000-unit workload costs $69.80 on Core.
Can I use Langfuse for free?
Yes. Hobby includes 50,000 units per month, two users and 30 days of data access. You can also self-host the MIT-licensed core without a software license fee, while paying for and operating the infrastructure yourself. Commercial enterprise features have separate terms.
What are the alternatives to Langfuse?
LangSmith fits a LangChain or LangGraph improvement loop; Helicone fits gateway-led request monitoring; Phoenix fits a private backend; Braintrust fits datasets and evaluation-led releases; Datadog fits agent incidents within an existing operations stack. Compare the actual meter and retention requirement before changing platforms.
Can Langfuse be run locally?
Yes. Langfuse documents Docker-based self-hosting and provides deployment guides for the MIT-licensed core. A local start does not supply production backups, availability or upgrade ownership. Define those requirements if the installation will become the production tracing service.
Get the AI Business Workflow Audit Checklist to identify the workflow, owner, outcome and control point before expanding your production tooling.
- Last Updated
- Oct 5, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

How to Use OpenCode
Install OpenCode, connect existing model access, run a real coding task, configure AGENTS.md and plugins, and understand API and Zen costs.Oct 4, 2026Build
Netlify Pricing (2026): What a Month Costs in Credits
Netlify's current Free, Personal and Pro prices, credit rates, and monthly budgets for a marketing site, Next.js app and 10-site agency.Oct 4, 2026Build
Softr Review (Verified October 2026)
Softr review for client portals and internal tools: current monthly and annual prices, user and record limits, AI features, and the plan to choose.Oct 4, 2026Build
Claude Code Alternatives: Pi, Codex CLI, OpenCode and Gemini CLI (2026)
Compare Pi, Codex CLI, OpenCode and Gemini CLI with Claude Code: current plans, monthly model costs, open-source limits and switching advice.Oct 4, 2026Build
MCP Gateway: What It Does, When You Need One, and Costs
What an MCP gateway controls, when a small team needs one, and the costs of Cloudflare, Docker, and Lasso options.Oct 4, 2026Build
OpenAI API Pricing (2026): GPT-6.1 Sol and Three App Budgets
OpenAI API rates verified October 2026, with GPT-6.1 Sol, Luna and Astra budgets plus voice, images, search and container costs.Oct 3, 2026Build
Pi Coding Agent
Set up Pi 1.0, connect your existing model account, add AGENTS.md and complete a first task. Includes provider pricing and honest limits.Oct 3, 2026Build