AI for Marketing Agencies
Run a seven-handoff AI delivery system for campaign drafts, approvals, and sourced client reports, with current costs for five and 20 clients.





For a five-person shop, AI for marketing agencies should begin as one controlled delivery loop, not another shelf of apps: the modeled baseline is $338.86 a month for five clients once five ChatGPT Business seats, Make, GPT-6 Sol API usage, and 3.75 hours of human editing are counted. Start with an approved brief, stop at client approval, then build the monthly report only from checked CSV totals.
Who This Is For
This playbook is for a five-person marketing agency with an owner-strategist, an account lead, a performance marketer, a copy or design generalist, and an operations owner. You already have a project manager, cloud documents, ad accounts, and spreadsheets. Your Tuesday is not short of software. It is full of repeated handoffs: an approved brief becomes a message matrix, the matrix becomes channel drafts, comments come back from the client, campaign exports arrive with different columns, and somebody turns those exports into a monthly story. The opportunity is to make that route controlled and repeatable without letting one client's facts, voice, or data appear in another client's work.
AI for Marketing Agencies Is a Delivery System, Not a Tool List
The right first stack is one governed model workspace for people, one automation layer for state changes, and one metered model connection for repeatable machine work. The workspace holds context and review. The automation layer moves approved artifacts and records status. The API handles structured draft and report calls that you can meter separately.
ChatGPT Business is the human workspace in this design. It costs $20 per user per month on annual billing, or $25 month-to-month, so five seats cost $100 or $125 a month. Business data is not used to train OpenAI models by default, but that protection does not replace your client contract, access policy, or judgment about what belongs in a model.
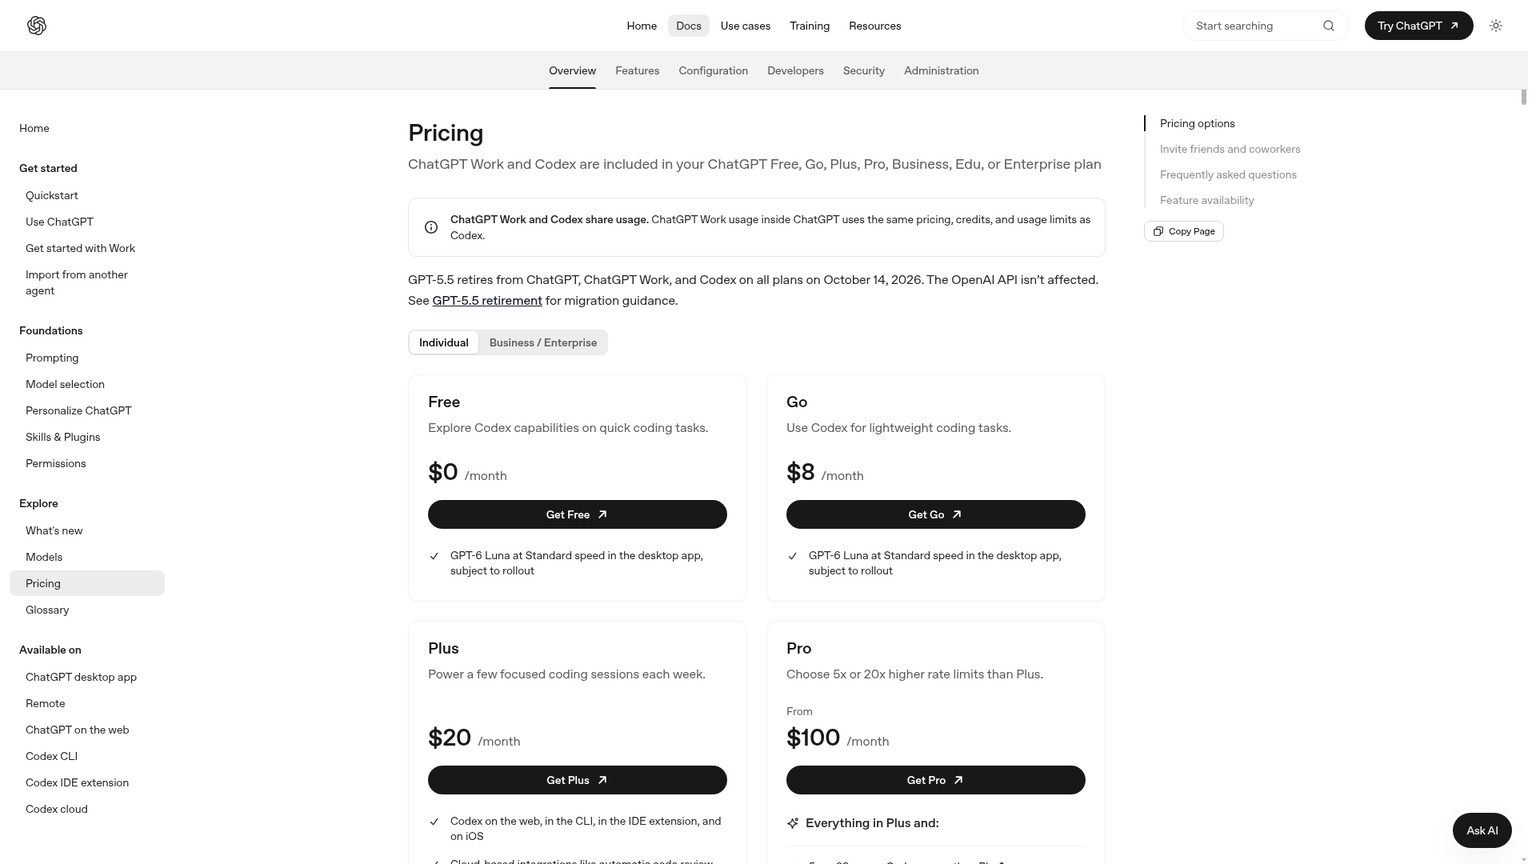
Create one project per client. A project lets its chats use the same files, instructions, and connected sources, and OpenAI's project guidance recommends separate projects for unrelated work. Treat that as context hygiene, not as proof of legal or technical tenant isolation.
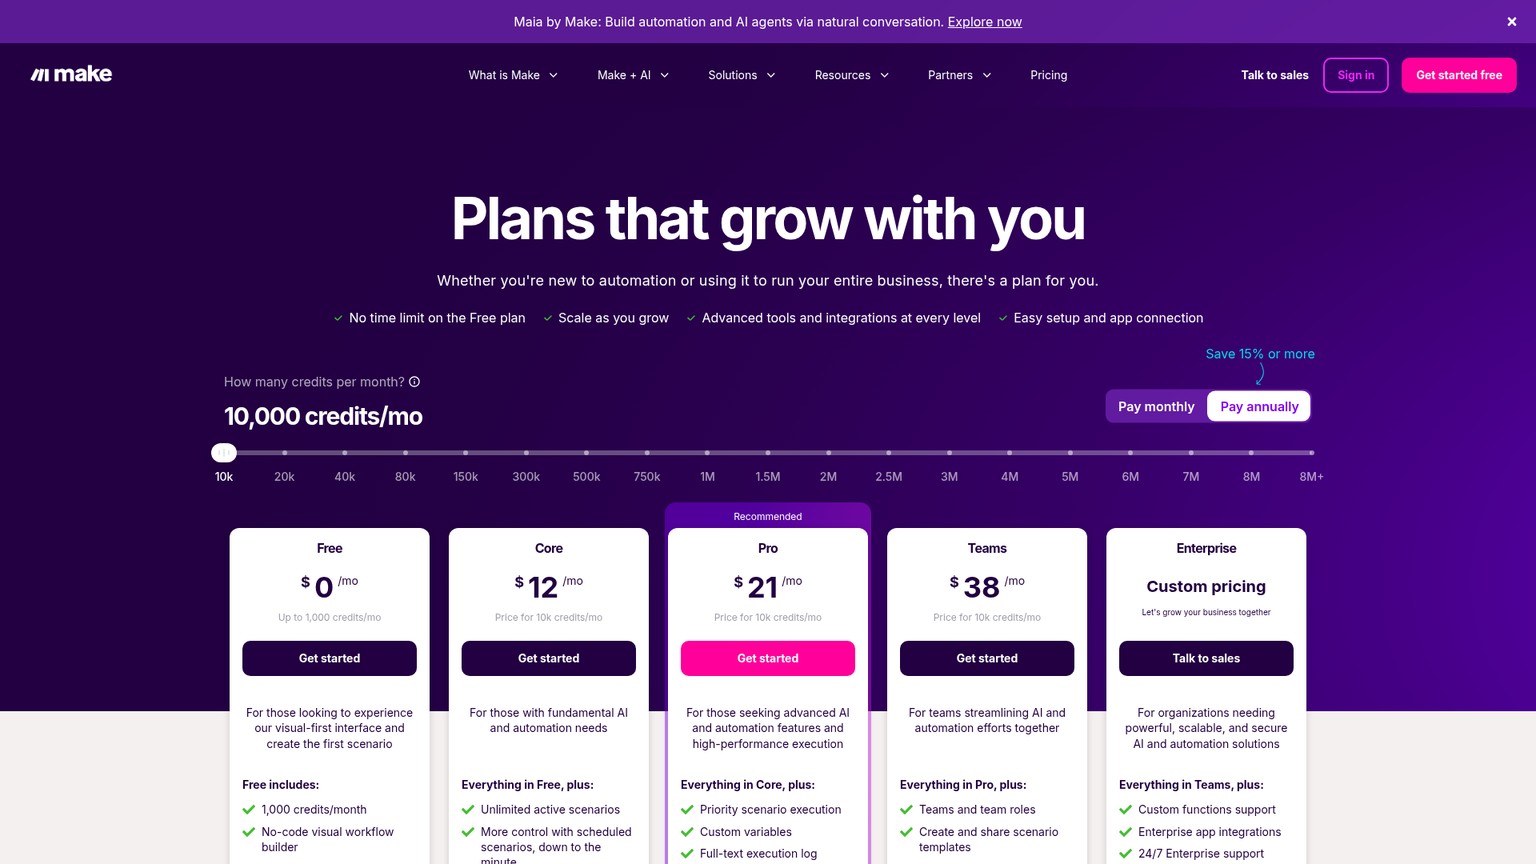
Make is the automation layer. On monthly billing, Core is $12, Pro is $21, and Teams is $38 for 10,000 credits. Most module actions use one credit, while some advanced actions using Make's AI Provider use more, so an agency should cost scenarios from the execution log rather than count boxes on the canvas.
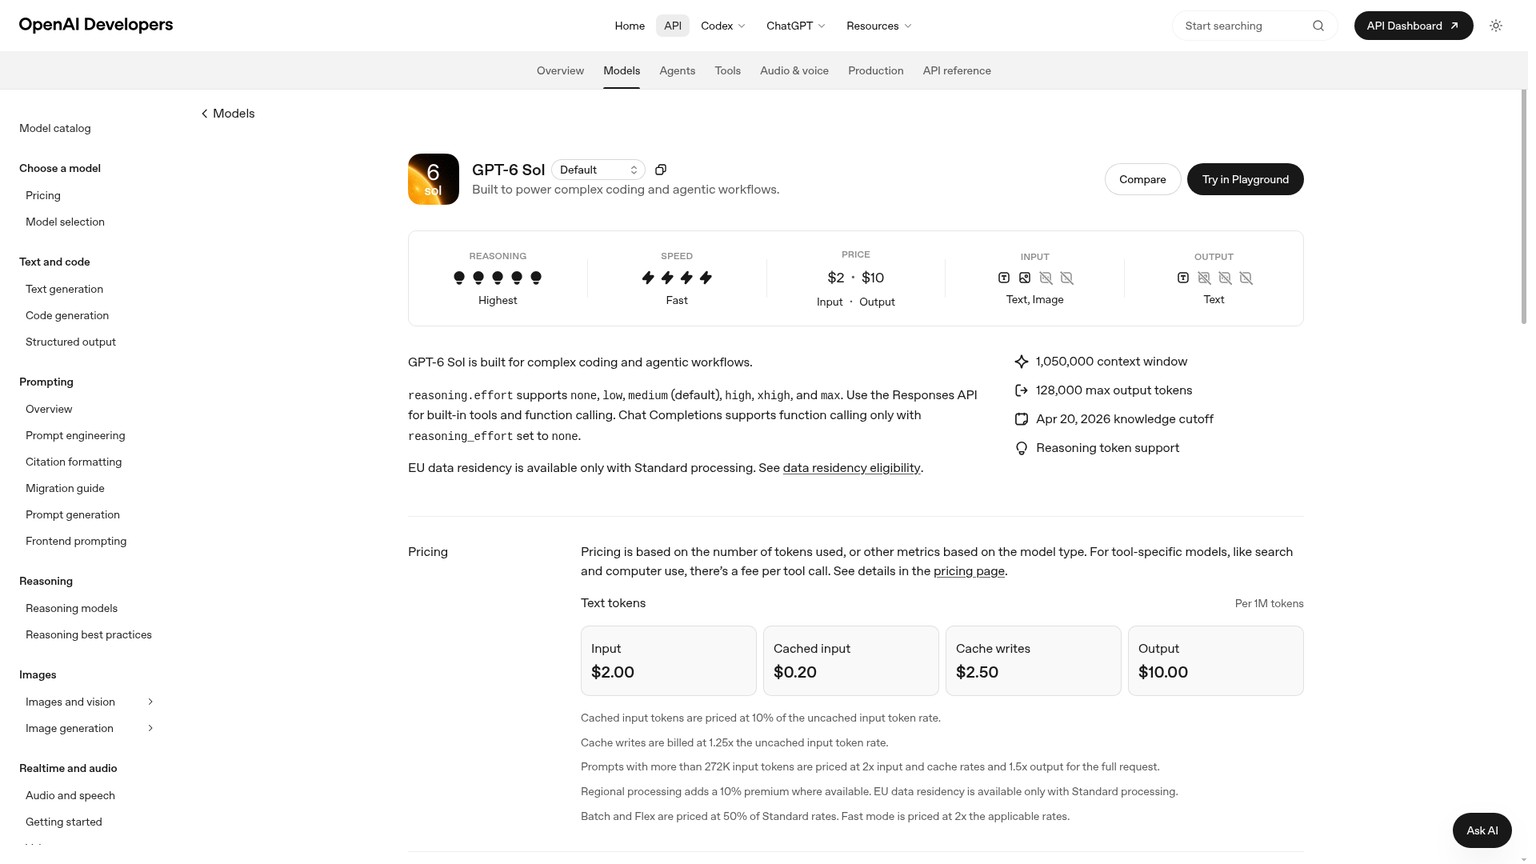
GPT-6 Sol is the metered model for automated drafts in this cost model. Standard short-context pricing is $2 per million input tokens and $10 per million output tokens. ChatGPT workspace membership and Platform API access are separate access and billing boundaries, so buying five Business seats does not cover the API calls that Make sends.
The broader AI marketing-tool guide covers specialist choices, while the AI marketing-agent guide explains when an agent deserves its own budget. For this workflow, do not add a specialist until a measured review bottleneck earns another bill.
Pricing and plan limits in this playbook were verified against the live vendor pages on September 25, 2026.
The Decision Table
The seven handoffs below share subscriptions. A line marked "included" is not another charge; it uses the workspace or automation plan already counted.
Setup effort means low for one saved template, medium for a controlled schema with validation, and high for a cross-tool route with error handling. It does not estimate hours.
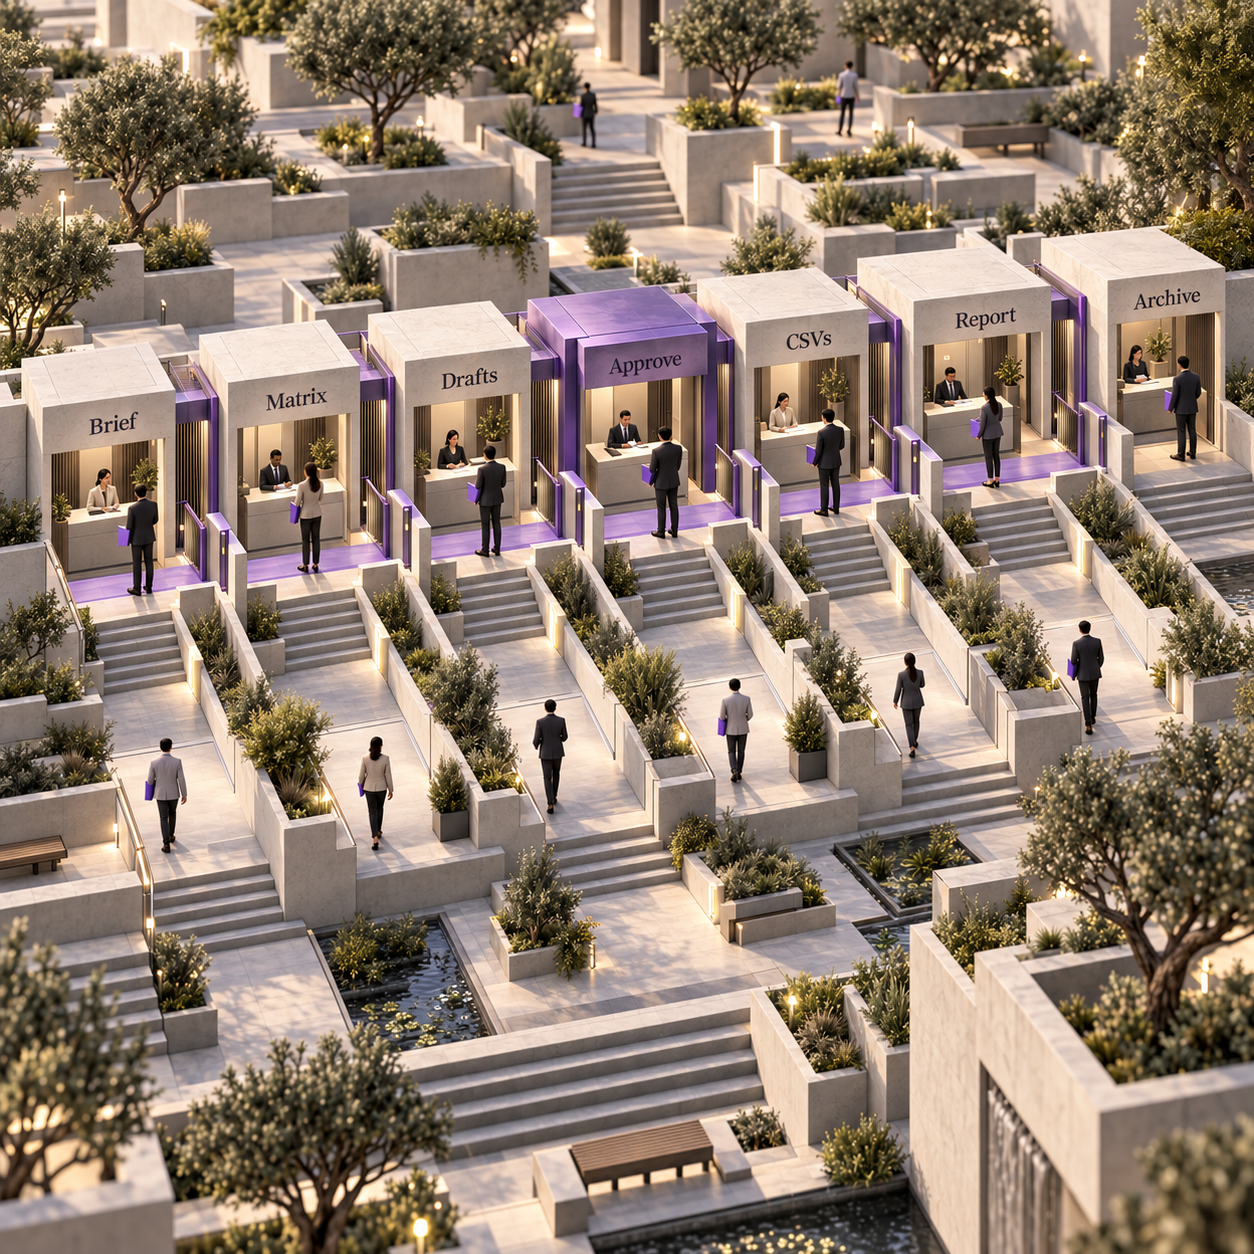
Build Agency Workflow Automation Around Seven Stopping Conditions
Automation is safe when it moves state, not when it invents permission. Every handoff needs a named input, a named output, one accountable owner, and a condition that stops the next step.
1. Freeze One Approved Brief Inside One Client Project
The first job is not generation. It is turning a loose client brief into a source pack the rest of the month can trust.
Tool and cost: ChatGPT Business, inside the shared five-seat workspace that costs $100 a month on annual billing.
Setup: Create a project named with the client ID, not only the brand name. Add project instructions that state the audience, offer, approved proof, prohibited claims, required disclaimers, voice rules, channels, and output format. Upload only the approved brief, the current voice guide, a claims register, and the agreed deliverables.
Input: The client-approved brief and approved reference material.
Output: A frozen source pack with a version date, source IDs, open questions, and a visible APPROVED status.
Owner: The account director.
Stopping condition: Every required field is present, unresolved questions are assigned, and the client or accountable account owner has approved the pack. If proof for a proposed claim is missing, the workflow stops here.
The wall: A project organizes context, but it does not make careless uploads safe. Do not copy a previous client's chat, voice guide, audience file, or performance export into this project just because the structure looks similar.
2. Build the AI Campaign Workflow From an Approved Brief
The message matrix is the highest-leverage artifact because it forces one strategic decision before the model produces dozens of variants. It should be a compact grid of audience, problem, desired change, proof, offer, objection, call to action, prohibited claim, and source ID.
Tool and cost: ChatGPT Business, included in the shared workspace.
Setup: Save one matrix template in the client project. Instruct the model to use only the frozen pack, leave a cell blank when evidence is missing, and place a source ID beside every proof statement. Ask for disagreements and missing evidence as a separate list, not as invented copy.
Input: The approved source pack.
Output: One reviewable message matrix and an exception list.
Owner: The strategist.
Stopping condition: The strategist accepts one primary message, every proof statement maps to a source, and the client approves the message direction before channel drafts begin.
The wall: A fluent matrix can hide a weak strategy. The model tends to smooth over contradictions and turn aspirations into facts. The strategist must reject any differentiation the source pack cannot support.
3. Turn the Matrix Into Draft Assets, Never Published Assets
Once the message is approved, structured generation is worth automating. The same matrix can produce paid-social variants, search-ad concepts, landing-page modules, email copy, and a creative brief without asking five people to reconstruct the strategy.
Tool and cost: GPT-6 Sol called through Make. Under this article's workload assumptions and retry reserve, the modeled API cost is about $0.37 per client per month.
Setup: Give each requested asset an asset ID, channel, audience, objective, allowed source IDs, length constraint, and output fields. Require the response to return the asset ID, draft, source IDs used, and open questions. Write the output into a draft location, never directly into an ad account, email platform, or live page.
Input: The approved matrix plus the channel specification.
Output: A versioned draft pack with source references and exceptions.
Owner: The copy lead or channel lead.
Stopping condition: Every draft uses the approved message, every factual claim has an allowed source ID, and the pack is marked READY_FOR_INTERNAL_REVIEW.
The wall: More variants can create more review work. Stop generating when the set covers the planned hypotheses. Do not use the model to manufacture fresh offers, customer quotes, performance claims, or legal language.
4. Route Revisions to One Client Approval Record
Make should move the approved internal draft to the client and return structured feedback to the correct asset. It should not decide whether the feedback is strategically sound.
Tool and cost: Make Core at $12 a month for a single automation owner, or Make Teams at $38 when several staff need team roles and shared scenario templates.
Setup: Trigger only when the internal status changes to ready for client review. Create an approval task in the agency's existing project system, attach an immutable draft link, and collect one of three responses: approve, request a specific change, or return for strategy. Write the response, reviewer, timestamp, asset ID, and client ID back to the record.
Input: The internally approved draft pack.
Output: An approval record or a revision request tied to exact asset IDs.
Owner: The project manager.
Stopping condition: The client approval is recorded against the final version. A vague comment, conflicting reviewer instruction, or missing approver returns to the account lead.
The wall: Unbounded revision loops burn credits and hide scope creep. Set a retry ceiling and route anything beyond it to the account lead. Do not automate publishing from a comment or an email reply.
5. Normalize Campaign CSVs Before Asking for a Story
The reporting workflow should calculate first and write second. Export files from each approved source, map them into one schema, and make a spreadsheet or deterministic transformation compute the totals.
Tool and cost: Make plus the agency's existing spreadsheet, included in the selected Make plan.
Setup: Require client ID, source platform, account ID, reporting period, timezone, currency, campaign ID, metric name, metric definition, and source filename. Keep raw files unchanged. Transform copies into a normalized table, then calculate totals and variances outside the language model.
Input: Campaign CSVs from the agreed source systems.
Output: A normalized evidence table, reconciliation sheet, and source ledger.
Owner: The performance marketer.
Stopping condition: Periods align, currencies and timezones are explicit, row counts are recorded, and every total reconciles to the source export. A mismatch stops the report.
The wall: Platforms can use the same word for different measures. A conversion, lead, or attributed sale is not comparable until its definition and attribution window match the client agreement. Do not ask a model to resolve that ambiguity.
6. Make AI Client Reporting Traceable to CSV Rows
The model's reporting job is explanation, not arithmetic. Give it the checked summary table, the source ledger, prior approved decisions, and a strict instruction to cite a source ID beside every number.
Tool and cost: GPT-6 Sol through Make, included in the modeled API line.
Setup: Fix the report structure: executive readout, changes since last period, channel findings, decisions, risks, and next actions. Require each numeric sentence to carry the reporting period and source ID. Require causal explanations to be labeled as hypotheses unless the supplied evidence supports them.
Input: The reconciled summary table and source ledger, never loose exports from several clients.
Output: A sourced report draft plus a list of unsupported explanations.
Owner: The account lead.
Stopping condition: Every reported total has been checked against the CSV, every period is correct, every recommendation has an owner, and unsupported causal language has been removed or labeled.
The wall: A language model can transpose values, omit a qualifier, or turn correlation into causation. The account lead must compare every number with the ledger and must not accept a polished explanation as proof.
7. Archive the Run Without Building a Cross-Client Memory Pool
The last handoff makes the next month reproducible. Save the approved brief version, matrix, generated assets, client comments, final approvals, raw and normalized CSVs, report, prompt version, actual model bill, Make credits, retries, corrections, and review minutes.
Tool and cost: Make plus existing storage, included in the selected Make plan.
Setup: Use a client-specific path and a run ID. Give the archive an access owner and retention rule. Move only sanitized, generic process lessons into an agency-wide playbook.
Input: The complete approved run record.
Output: A client-scoped evidence pack and a short operations note.
Owner: The operations owner.
Stopping condition: The record is complete, permissions are checked, and any reusable lesson has been stripped of client names, figures, copy, and confidential context.
The wall: A shared prompt library can become a quiet leakage channel. Reuse structure, validation rules, and empty templates. Do not reuse client language or performance data.
What Five and 20 Client Accounts Cost
This is a cost model, not a benchmark. It uses the live vendor prices above and explicit workload assumptions so you can replace every assumption with your own observed usage.
The model assumes five staff seats, 62,000 input tokens and 20,000 output tokens per client each month, a 15% retry reserve, 45 Make module actions per client before that reserve, and 45 minutes of human editing per client at a modeled $60 loaded hourly rate. Existing project-management, storage, analytics, ad-platform, and design-software bills are excluded.
Five Client Accounts
- Seats: Five ChatGPT Business seats on annual billing, $100 a month.
- Model usage: GPT-6 Sol after the 15% retry reserve, $1.86 a month.
- Automation: 260 modeled Make credits. Core supplies 10,000 credits for $12 a month, leaving capacity for actual workflow variation.
- Retries: Already included in the token and credit estimates as the 15% reserve.
- Brand limits: Jasper is not in the baseline. Pro's two Brand Voices cannot represent five distinct client brands; Business requires a custom quote.
- Human editing: 3.75 hours at $60, or $225 a month.
- Modeled total: $338.86 a month, or $67.77 per client.
Twenty Client Accounts
- Seats: The same five ChatGPT Business seats, $100 a month.
- Model usage: GPT-6 Sol after the 15% retry reserve, $7.45 a month.
- Automation: 1,040 modeled Make credits. Teams supplies 10,000 credits for $38 a month and adds shared templates and team roles.
- Retries: Already included in the token and credit estimates as the 15% reserve.
- Brand limits: Jasper is not in the baseline. Pro's two Brand Voices cannot represent 20 distinct client brands; Business requires a custom quote.
- Human editing: 15 hours at $60, or $900 a month.
- Modeled total: $1,045.45 a month, or $52.27 per client.
The 20-client plan changes because several operators need controlled collaboration, not because 1,040 modeled credits require it. Make warns that some AI Provider actions consume more than one credit, so replace the assumption with execution-log usage after the pilot. Choosing month-to-month ChatGPT Business instead of annual billing adds $25 to either agency total.
Jasper is the optional brand-governance layer, not the baseline. Jasper Pro costs $59 a month when billed yearly or $69 monthly, but it includes one seat, two Brand Voices, five Knowledge assets, and three Audiences. One Pro account therefore does not cover five distinct client brands, much less 20.
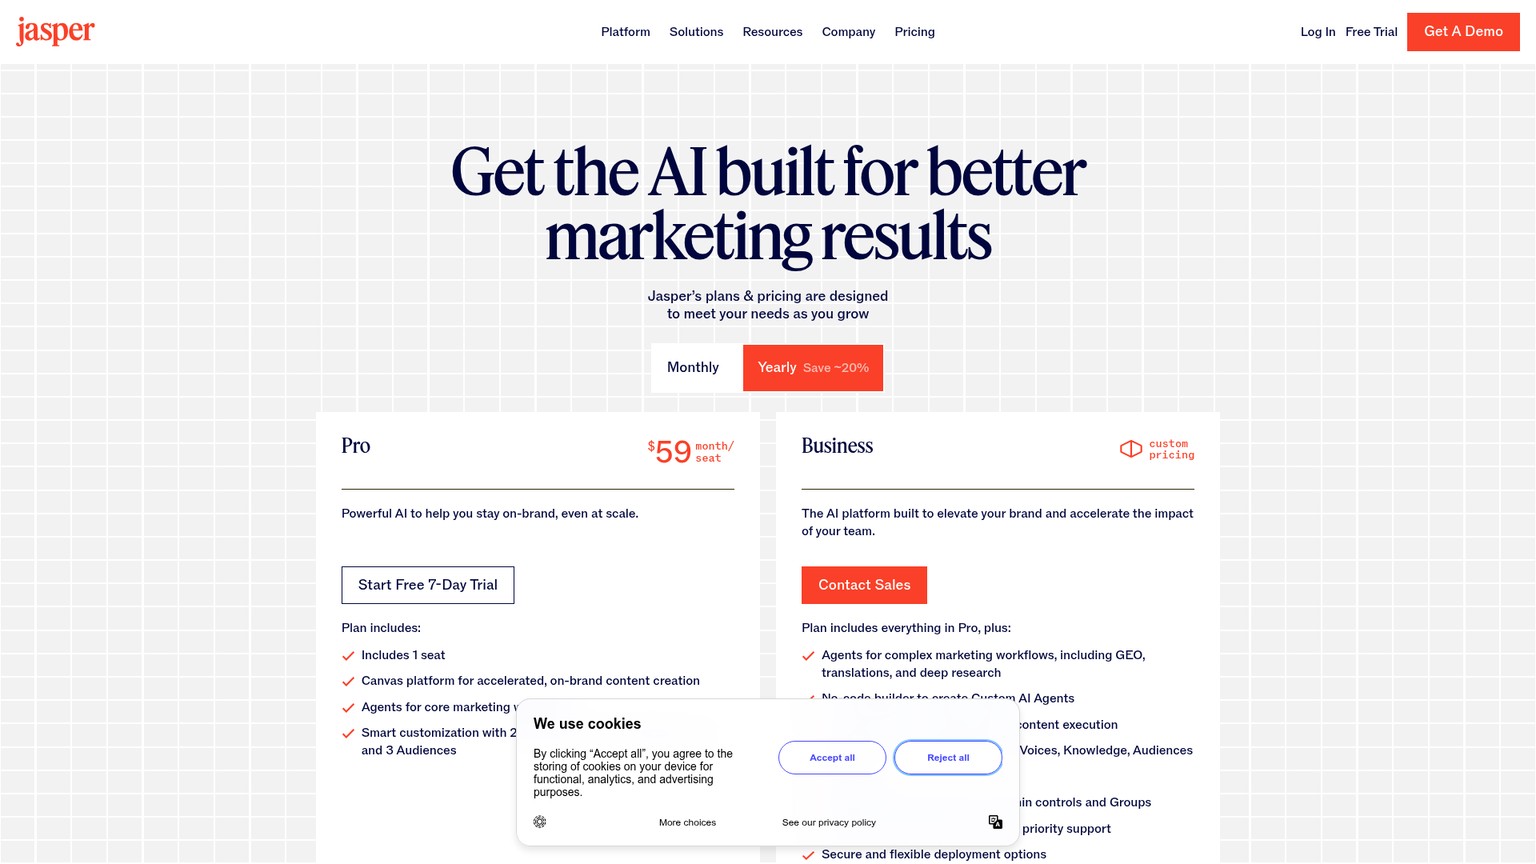
Jasper Business offers custom pricing with unlimited Brand Voices, Knowledge assets, and Audiences, plus API access and admin controls. Ask for a quote only after measuring the hours spent correcting brand voice and claim rules. At the modeled $60 labor rate, a monthly quote of Q must remove more than Q ÷ 60 genuine review hours to break even. That is a decision formula, not a prediction that Jasper will save those hours.
Why Agency Reporting AI Needs a Source Ledger
A monthly report becomes defensible when every number has an address. The source ledger should record a source ID, client ID, platform, account, filename, reporting period, timezone, currency, metric definition, transformation, and final checked value. The narrative then points back to those fields.
Keep three layers separate:
- Raw evidence: untouched CSV exports stored under the client and run ID.
- Checked calculation: normalized rows and spreadsheet formulas that produce the totals.
- Narrative: model-written explanations, decisions, risks, and actions based only on the checked calculation.
If the narrative says conversions rose, the report should identify the period, metric definition, and source. If it says a creative caused the rise, that is a causal claim and needs evidence beyond two adjacent numbers. Otherwise it should be written as a hypothesis to test next month.
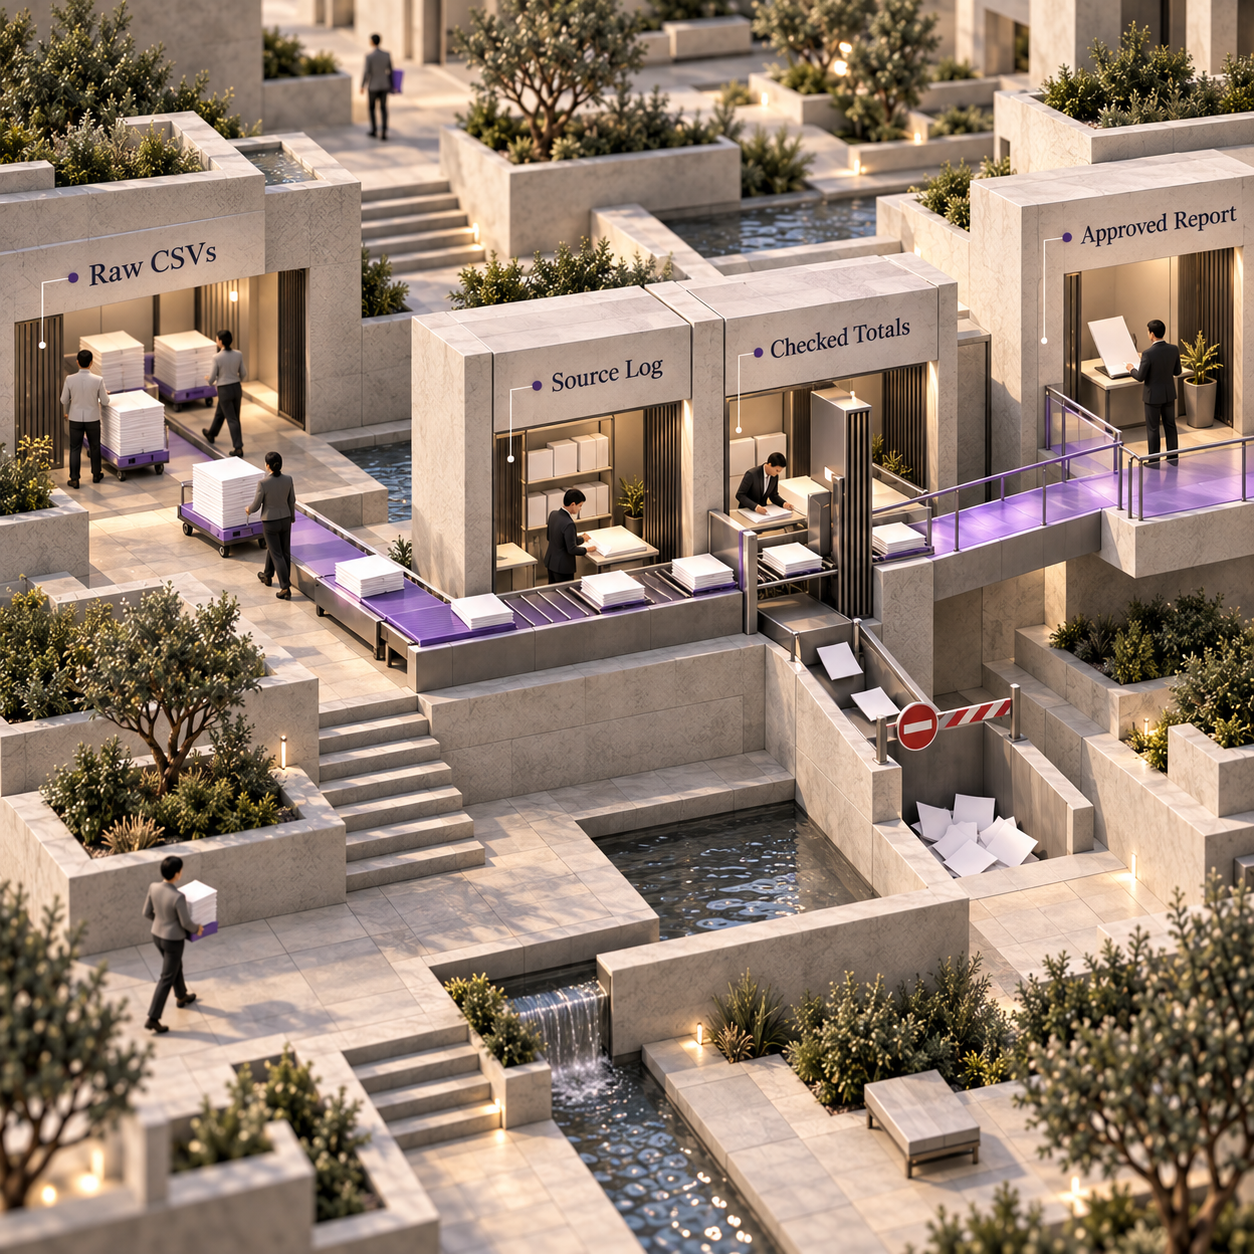
This design also makes corrections cheaper. When a total changes, repair the normalized table, regenerate only the affected narrative, and preserve the previous version. Do not rewrite the whole report from a fresh pile of exports.
Prove It With Two Synthetic Clients Before Live Data
The proof exercise is prospective. It has not been run, so it carries no speed, quality, or savings claim.
Create two fictitious clients with clearly different offers, voices, and canary phrases. For example, give Cedar Lane Software the harmless phrase "purple compass" and Harbor Field Furniture the phrase "copper kite." Build one synthetic campaign brief and one synthetic source-CSV set for each, with known spreadsheet totals.
Run the campaign path separately
Create a separate project and run ID for each synthetic client. Generate the message matrix and draft assets, then save every output rather than copying only the best draft into a presentation.
Route a revision and an approval
Send a structured change request for one asset in each account. Confirm that Make returns the comment to the correct asset ID and records the final approval.
Generate both monthly reports
Normalize each synthetic CSV set, calculate the totals outside the model, and ask the model to write only from that client's checked ledger.
Check truth and separation
Compare every reported total with its CSV. Search Cedar Lane outputs for "copper kite" and Harbor Field outputs for "purple compass"; any cross-client appearance fails the run.
Record observed cost and review
Log actual review minutes, Make credits, API charges, retries, rejected claims, saved assets, approval records, and final reports. Replace the worksheet assumptions only with these observed values.
Pass the pilot only when every number matches its source, no canary crosses clients, every asset has an approval record, and the bill and review time are recorded. If it fails, repair the handoff that failed. Do not average the failure into an agency-wide productivity claim.
Client Data and Compliance
Do not paste passwords, API keys, authentication cookies, raw customer contact lists, payment data, health information, legal files, unpublished acquisition figures, or another client's records into a general chat. Do not upload any dataset the client has not authorized your agency and the selected vendor to process.
ChatGPT Business says business data is not used for model training by default, but training policy is only one part of the decision. Retention, connected apps, user permissions, data location, subcontractors, deletion, and the client agreement still matter. A separate project reduces context mistakes; it does not grant permission or satisfy every regulatory duty.
Use synthetic data for setup. Minimize live fields, redact identifiers where possible, give each person only the access needed for their role, and keep credentials in the systems designed to store them. Anything involving a regulated claim, a customer record, spend authorization, contract language, or public publishing keeps a named human approver.
The Monday Plan
Do only these three things this week. A larger rollout before these work will create more places to debug.
Freeze one brief
Pick one low-risk campaign. Put its approved offer, audience, proof, prohibited claims, and deliverables into one client project with source IDs.
Build one approval route
Use Make to move one internally approved draft into the existing client-review system and write the decision back to the same asset ID.
Run one synthetic report
Use a synthetic CSV, calculate the totals outside the model, generate the narrative from the checked ledger, and record review time, credits, API cost, retries, and errors.
Frequently Asked Questions
What are the best AI tools for marketing agencies?
Start with one governed model workspace, one automation layer, and the document, approval, and analytics systems you already own. Add a specialist such as Jasper only after measured brand-review work justifies its limits and price.
Is it legal to use AI for marketing?
It can be, but AI does not suspend privacy, intellectual-property, advertising, consumer-protection, contract, or sector rules. Get permission for client data, substantiate claims, and keep an accountable person on approval.
Is there an AI tool for marketing?
Yes, but no single tool should own the full client-delivery loop. A model workspace can reason and draft, while automation records state and moves approved work between existing systems.
How is AI being used in advertising agencies?
The strongest uses are brief normalization, message matrices, controlled asset drafts, revision routing, data cleanup, and sourced report narratives. Strategy, factual claims, budget decisions, and publication should remain human approvals.
Will AI replace marketing jobs?
AI is more likely to remove or compress repeatable tasks than eliminate every accountable role. Client trust, positioning, taste, evidence, negotiation, and final responsibility still need people.
What type of AI is used in marketing?
Generative models create or summarize material, predictive systems estimate outcomes or scores, and automation moves data and tasks between systems. This playbook uses generation for drafts and narrative, deterministic calculations for totals, and automation for handoffs.
Can I use AI for marketing?
Yes. Begin with synthetic or low-risk data, define what the model may produce, and put a human stop before any client-facing or public action.
What is the 30% rule for AI?
It is an informal phrase used inconsistently, sometimes for the share automated and sometimes for the share kept human. Ignore the percentage and name the specific gates where claims, money, privacy, strategy, and publishing require judgment.
What are the 5 main AI tools?
There is no universal five-tool set. For agency delivery, think in five categories: model workspace, automation layer, source-of-truth documents, approval system, and an optional specialist for a measured bottleneck.
Get the AI Business Workflow Audit Checklist
Map the repeated work, data handoffs, and approval bottlenecks before adding another AI subscription.
- Last Updated
- Sep 25, 2026
- Category
- Playbooks
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
AI for Consultants
A practical AI workflow for consulting discovery, cited research, spreadsheet analysis, proposals, and follow-up, with solo and five-person costs.Sep 25, 2026Playbooks
AI for Pilates Studios
A costed AI playbook for Pilates studio trial follow-up, attendance, waitlists, class capacity, weekly admin, and human review.Sep 12, 2026Playbooks
AI for Bookkeeping Client Onboarding
A costed onboarding workflow for bookkeeping firms, with portal setup, AI-drafted welcomes, human approval gates, and a three-step Monday plan.Sep 11, 2026Playbooks
AI Tools for Lawyers
Seven law-firm workflows with live tool prices, no-code setup steps, monthly cost math, data boundaries, and the human checks that stay.Sep 4, 2026Playbooks
AI for Property Managers
A costed AI playbook for tenant messages, maintenance, leasing, inspections, lease review, owner reports, and the human checks that stay.Sep 4, 2026Playbooks
Dental Office Automation With AI
A costed dental AI playbook for phones, notes, recall, insurance, treatment presentation, HIPAA, and the human checks that stay.Sep 2, 2026Playbooks