Claude API Pricing (2026): Model Rates and Three App Budgets
Claude API model, cache, batch and tool costs, verified October 2026. Three app budgets and when Pro or Max costs less for personal work.


Claude API pricing starts at $1 per million input tokens and $5 per million output tokens for Claude Haiku 4.5, the cheapest of Anthropic's four latest models. Start there for a bounded task, move to Claude Sonnet 5.5 when quality requires it, and reserve Claude Opus 5.5 or Claude Fable 5.1 for failures worth their premium. A Pro or Max subscription can be cheaper for personal work, but it does not replace the API bill for your app.
Prices verified against Anthropic's live pricing page and Claude Platform pricing documentation on 4 October 2026. All rates below are in US dollars. The three budgets are calculated examples with stated assumptions, not measured production results or claims that every model gives equally good answers.
Claude API Pricing: Current Model Costs
Haiku is the price floor among the four latest models; Sonnet is the next step when your quality check rejects Haiku's work. MTok means one million tokens, the pieces of text a model processes. Input is what you send; output is what it generates.
The table covers the latest models and every legacy model shown on the public pricing page. Each cache cell lists read / five-minute write, in that order. Everything is priced per MTok, verified October 2026.
Source: Claude's public model rate card. The detailed documentation also contains additional and historical model rows; a listed price alone is insufficient reason to choose an older model for a new app.
The legacy comparison matters for an existing integration. Opus 5.5 costs 20% less for identical fresh input and output counts than Opus 5, while Sonnet 5.5 retains Sonnet 5's prices. Fable 5.1 keeps Fable 5's input/output rates but lowers cache reads from $1 to $0.25. Those are rate comparisons, not promises of a smaller bill if your agent starts consuming more tokens. Official rates.
Claude API Token Pricing: Count Each Category Once
The bill depends on which tokens are fresh, written to cache, read from cache, or generated. A cache is stored prompt content that can be reused instead of processing the same material as fresh input on every call.
Anthropic API Pricing: What the Bill Measures
Calculate the token bill by adding these four amounts:
- Fresh input tokens divided by one million, multiplied by the input rate.
- Cache-write tokens divided by one million, multiplied by the relevant write rate.
- Cache-read tokens divided by one million, multiplied by the read rate.
- Output tokens divided by one million, multiplied by the output rate.
Then add applicable tool and runtime charges. Keep those token categories separate: a cached read is not also fresh input. Include the conversation history, tool definitions and tool results that the model processes, rather than budgeting only for the user's latest sentence. Anthropic documents these billing categories and tool overhead.
Output deserves its own budget. Sonnet 5.5's $10 output rate is five times its $2 fresh-input rate. If your product needs a short decision, asking for an essay adds cost without improving that product outcome. Caching the prompt does not discount the generated answer.
Cache Duration Changes the Write Price
The cheap read comes after a paid write. A five-minute write costs 1.25 times the model's fresh-input price; a one-hour write costs twice that price. The one-hour write rates are Haiku $2, Sonnet $4, Opus $8 and Fable $20 per MTok. Reads retain the rates in the table. Cache pricing.
For a reusable one-MTok Sonnet prefix, two uncached uses cost $4. A five-minute write followed by one read costs $2.50 + $0.20 = $2.70. The write premium pays back on the first reuse. With a one-hour cache, a write and two reads cost $4 + $0.40 = $4.40, versus $6 for three fresh uses.
Pick the duration that your request pattern can reuse. A static policy prompt repeated in a busy service is a good candidate. Frequently rewritten instructions or infrequent calls require more writes, so a budget that assumes every request is a cheap read will be wrong.
The Cheapest Claude Model That Does the Job
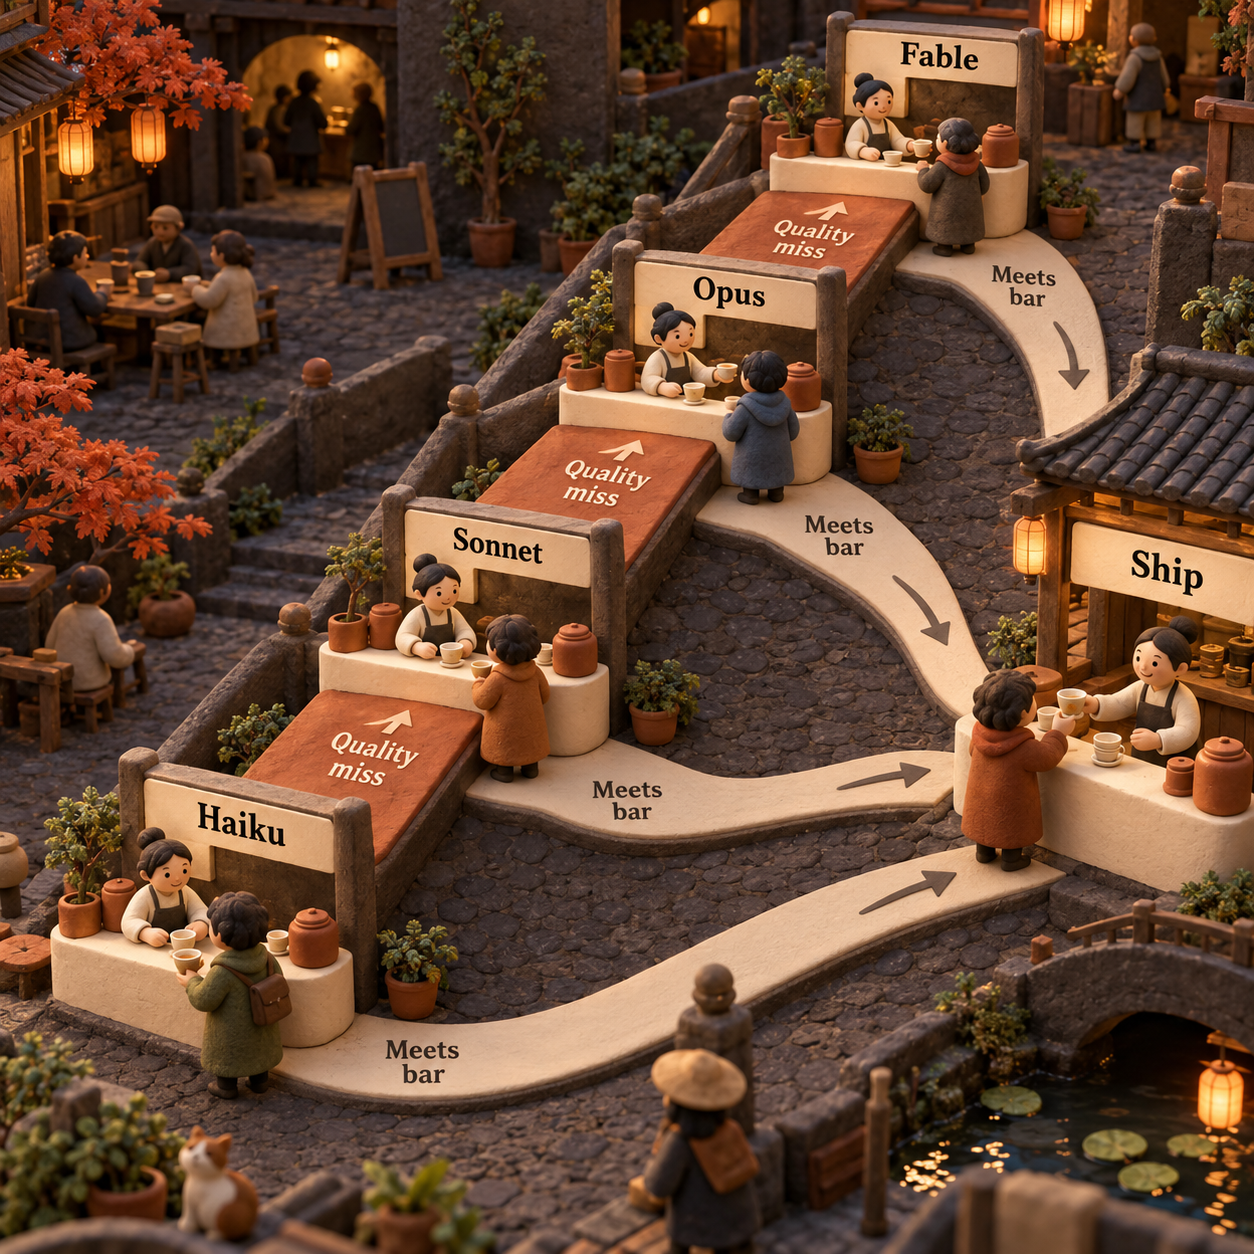
Choose the lowest-cost model that passes a defined quality bar on your task. Compare correct classifications, accepted answers or completed jobs. A lower token rate is useful only when the result remains usable.
Claude Haiku API Pricing: Start With Bounded Work
Claude Haiku 4.5 is the lowest-priced latest model at $1 input/$5 output per MTok. Start by evaluating it for routing tickets, extracting a few fields, or classifying text into a fixed set of labels. Anthropic positions it as its fastest economical model. Model pricing.
The limit is your acceptance bar. A cheap classifier that repeatedly sends work to the wrong queue can cost more through correction than it saves in tokens. Skip Haiku as the default when your evaluation already shows that failure.
Claude Sonnet API Pricing: Pay More When It Improves Acceptance
Claude Sonnet 5.5 costs $2/$10, twice Haiku's fresh-token rates. It is the sensible next candidate for coding, customer answers with judgment, or agent work that needs more than a bounded classification. The vendor positions it for a balance of speed and intelligence; that positioning is a starting hypothesis for your evaluation. Official positioning and rates.
For identical fresh-token counts, Sonnet must justify a larger bill through better outcomes. Keep the evaluation focused on the mistakes that matter to your business, rather than upgrading because an answer sounds more elaborate.
Claude Opus API Pricing: Reserve the Premium for Hard Cases
Claude Opus 5.5 costs $4/$20, while Claude Fable 5.1 costs $10/$50. Anthropic positions Opus for long-running coding and knowledge work and Fable for demanding reasoning and long-horizon agents. Neither is an economical default for a task that Haiku or Sonnet already completes acceptably. Current model rates.
At identical fresh input/output counts, the Haiku, Sonnet, Opus and Fable token bills have a 1:2:4:10 ratio. Cached workloads can change that relationship. Require evidence that the more expensive model reduces failed jobs or human correction enough to cover the difference.
Claude API Pricing Calculator: Three Workloads
Price the workload before choosing the model. These examples hold token counts constant so the price difference is visible. Your production estimate should use the counts each model actually produces, including retries. Totals exclude tax, your application infrastructure and standalone code-execution charges.
1. A Founder's Ticket Classifier: $150 or $75 on Haiku
Assume 100,000 classifications per month, each using 1,000 fresh input tokens and 100 output tokens. There is no caching, search or agent runtime in this example.
Monthly usage is 100 million input tokens and 10 million output tokens. Haiku's calculation is:
100 × $1 + 10 × $5 = $150 per month, or $1.50 per 1,000 decisions.
On the same counts, Sonnet costs $300, Opus $600, and Fable $1,500. If the decisions can wait for asynchronous batch processing, the 50% token discount makes those totals $75, $150, $300 and $750, respectively. Haiku batch works out to $0.75 per 1,000 decisions. Rates and batch discount.
For a founder sorting an overnight backlog, evaluate Haiku with batch first. For a live customer interaction, latency requirements may rule out batch. A Sonnet upgrade doubles the standard token bill here, so pay for it when the classification quality needs it.
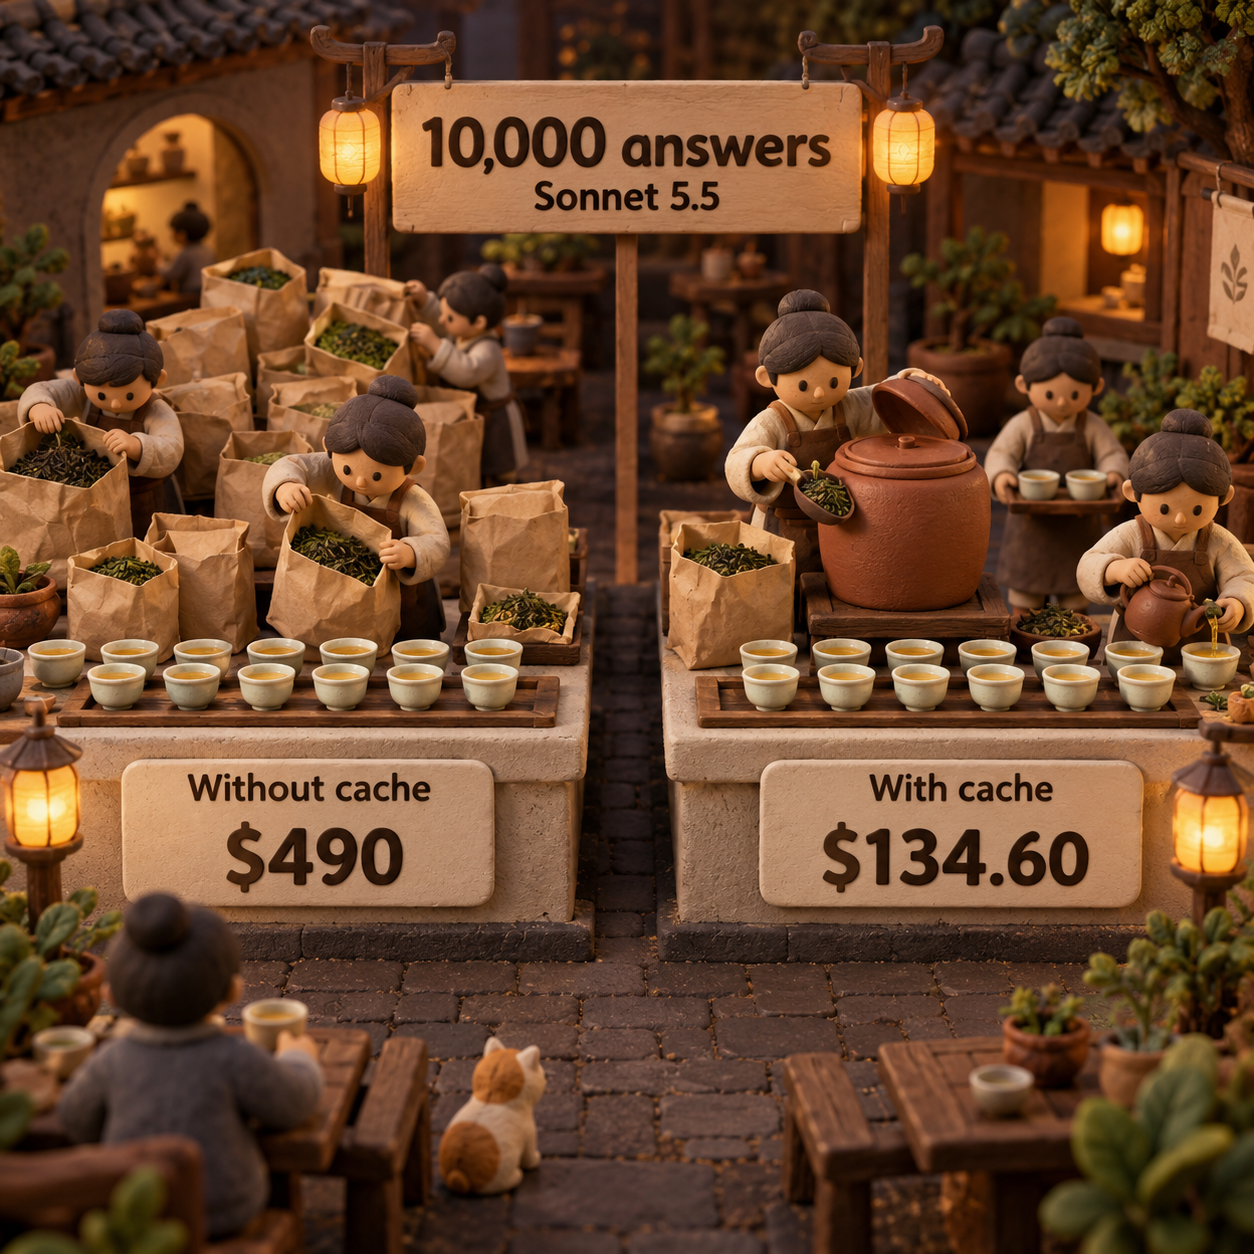
2. A CTO's Policy Assistant: $134.60 on Cached Sonnet
Assume 10,000 answers per month. Each uses an unchanged 20,000-token policy prefix, 2,000 fresh input tokens and 500 output tokens.
To include cache creation honestly, group those calls into 100 separate cache lifetimes with 100 requests each. Each group finishes within the five-minute validity period. Every group pays for one prefix write and 99 reads.
That produces 2 million cache-write tokens, 198 million cache-read tokens, 20 million fresh input tokens and 5 million output tokens. At Sonnet rates:
- Fresh input: 20 × $2 = $40.
- Cache writes: 2 × $2.50 = $5.
- Cache reads: 198 × $0.20 = $39.60.
- Output: 5 × $10 = $50.
Total: $134.60 per month, or $13.46 per 1,000 answers. Without caching, 220 million fresh input tokens plus the same output cost $490. Under these assumptions, caching saves $355.40. Official cache and token rates.
The same cached workload costs $67.30 on Haiku, $229.60 on Opus, or $524.50 on Fable. Sonnet and Opus each charge exactly $39.60 for the cache reads because both read rates are $0.20. Opus's remaining premium comes from fresh input, writes and output.
That changes the CTO's decision: Opus adds $95 to this Sonnet budget, rather than doubling the whole bill. Upgrade only if its accepted answers justify that difference. If requests are farther apart or the policy changes, increase the write count before using this estimate.
3. An Operator's Managed Agent: $460 on Opus
Assume 1,000 sessions per month, each consuming 50,000 fresh input tokens, 10,000 output tokens, 30 minutes of running time, and two web searches. The input assumption includes all processed history and tool content; caching is disabled.
With Opus 5.5, the monthly calculation is:
- Input: 50 million × $4 per million = $200.
- Output: 10 million × $20 per million = $200.
- Active runtime: 500 session-hours × $0.08 = $40.
- Search: 2,000 searches × $10 per 1,000 = $20.
Total: $460 per month, or $0.46 per session. The same assumptions cost $160 on Haiku, $260 on Sonnet, or $1,060 on Fable. These are alternatives to evaluate, not equivalent-quality guarantees. Managed Agents and tool rates.
For supported US-only inference, the Opus token subtotal becomes $400 × 1.1; runtime and search remain $60. Total: $500. Opus fast mode instead produces $860. Combining fast mode and US-only inference produces $940, calculated as $400 × 2 × 1.1 + $60.
Batch, US-Only Inference, and Fast Mode
Use batch for work that can wait; buy geography or speed when your application requires it. These modifiers change different parts of the decision.
Batch saves 50% on input and output. Sonnet's batch rates are $1/$5; Opus's are $2/$10. Prompt caching can combine with the batch discount. Managed Agents sessions do not support batch, so the third workload cannot simply be halved. Batch and session pricing.
US-only inference costs 1.1 times standard token pricing on supported models. The docs apply it to fresh input, output, cache writes and cache reads, not just the fresh-input column. The option applies to Claude 4.6 and later; do not assume it applies to Haiku 4.5. Global routing uses standard rates. Data-residency pricing.
Opus 5.5 fast mode costs twice the standard rate: $8 input and $40 output per MTok. It stacks with caching and supported US-only pricing, but is unavailable with batch. Use it when reduced waiting improves a user-facing outcome enough to justify the premium. Fast-mode pricing.
Two migration details also affect estimates. Claude 4.6 and later have their full one-million-token context window at standard rates, so an old long-context surcharge should not be copied into a current budget. The docs also say Claude 4.7 and later use a tokenizer that produces approximately 30% more tokens for the same text, with the difference depending on content. Count your actual requests; do not automatically add that estimate to the example budgets above. Context and tokenizer notes.
Tool Charges and the Code Execution Allowance
An agent can incur several meters in the same session. A token estimate is incomplete when the application also buys hosted runtime or searches.
Claude Managed Agents costs $0.08 per active session-hour, plus tokens. Running time is charged; idle, rescheduling and terminated time is excluded. Leaving a session open is therefore different from leaving it running. Runtime metering.
Web search costs $10 per 1,000 searches, plus the tokens used to process requests and search content. A search counts once regardless of how many results it returns. Web fetch has no separate tool fee, but retrieved content still consumes tokens. A search-heavy research agent needs both the search count and the resulting input volume in its forecast. Search and fetch pricing.
Code execution's public pricing card advertises 50 free hours daily per organization, then $0.05 per additional hour per container. That is the current statement on claude.com/pricing.
The worked totals above include no standalone code execution. Once your billable container-hours are known, multiply them by $0.05. The docs also say that including files can incur execution-time billing even if the tool is not called, because files are preloaded into the container.
Claude API Pricing vs Subscription
A subscription can win for eligible personal work; a customer-facing app still needs its own API budget. Claude Pro and Claude Max are plans for using Claude's product surfaces, including Claude Code, the coding agent. They do not turn your API integration into an included subscription allowance.
Claude Subscription Pricing: Monthly Versus Annual
Pro is $20 monthly or $200 paid upfront for a year. Max starts at $100 monthly. Pro's annual card displays $17 per month; the exact annual payment divided by twelve is $16.67. Max offers choices of 5x or 20x Pro capacity, with monthly billing. Current plan cards.
Ten $20 payments equal the $200 annual price. Annual Pro becomes cheaper after ten paid months and saves $40 across a full year. For a short project, monthly avoids paying for unused months. Published consumer refund conditions do not make an annual payment a flexible monthly balance.
Capacity remains a condition. Personal-plan usage depends on model, conversation length and features, with session and weekly limits. The pricing page promises no fixed number of tasks. Paid plans can also use usage credits billed at API rates, so additional metered usage belongs in the comparison.
Claude Code API Pricing: A Conditional Break-Even
For personal coding work with the third workload's 50,000 Opus input and 10,000 output tokens, the token-only API cost is $0.40 per task. This comparison excludes Managed Agents runtime and search, which are separate API services.
At that token shape, 50 tasks equal Pro's $20 monthly fee; 250 tasks equal the entry Max price of $100. These are arithmetic crossovers, not promised subscription task counts. Above the crossover, a plan costs less only if it covers the model and work you need and its allowance is sufficient. Below it, the meter can be cheaper for occasional use.
Fable needs a separate check: the Pro comparison labels Fable as usage credits. Do not assume a $20 Pro payment includes all the Fable tokens that your API workflow would consume. Plan model access.
Use Is Claude Free? for the consumer-plan decision and Claude Code pricing for the coding subscription choices. Keep the production app's bill separate from the subscription you use to build it.
Free Access, Student Offers, and Refunds
The Free app and initial API test credits are different offers. Neither is a standing free production API plan.
Claude API Key Pricing: Access Is Different From Usage
The rate card lists token and feature charges, not a separate price for the key itself. The docs say new users receive a small amount of free API credits, but publish no fixed amount or recurring free-token allowance. Budget paid usage after any test credits are exhausted. API pricing FAQ.
Claude Free costs $0 and supports ordinary chat, web search, file creation and code execution inside the app. The comparison excludes Claude Code, Opus and Fable from Free. Someone who only needs occasional app-based help, fits its allowance and needs no paid feature may never need to pay. That does not describe a developer serving customers through an API. Free-plan comparison.
Student Offers and Refund Policy
The public pricing page describes an institution-wide Education offer for students, faculty and staff, including dedicated API credits. Neither pricing page publishes a fixed individual student API discount. Do not subtract an assumed student coupon from a production estimate.
For consumer subscriptions, payments are generally non-refundable except where the terms or local law provide otherwise. The pricing FAQ describes an in-app request within the 14-day withdrawal period for EEA and UK customers, and Apple handles App Store refunds. Published refund policy.
Those consumer rules do not establish an API-credit refund promise. The two rate cards also do not state an API prepaid-credit expiration period. Confirm the applicable purchase terms before funding a large balance.
Frequently Asked Questions
How much does a Claude Code subscription cost compared to the API?
Pro costs $20 monthly or $200 annually upfront; Max starts at $100 monthly. API use is metered. At the example's $0.40 Opus token cost, 50 tasks equal $20, but a subscription wins only if its model access and allowance cover your personal work. Plan pricing.
What is the price of the GPT API?
Anthropic's rate card does not establish a GPT API price. Keep different providers' quotes separate and compare the same input, output, cache and tool workload before deciding; a Claude rate is not a GPT quote.
What is the price of Claude Opus?
Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens. Cache reads are $0.20 and five-minute writes are $5. Legacy Opus 5 is $5/$25 for input/output, so 5.5's fresh-token rates are 20% lower. Sonnet 5.5 keeps Sonnet 5's $2/$10 rates. Official model rates.
Is the Claude API key free?
No separate key fee is listed on the rate card, but requests consume billable usage. Any initial test credits are limited credits, not a permanent free API plan. API pricing.
How to get Claude opus API key for free?
The docs mention a small amount of initial API test credits, without a promised amount. They do not promise recurring free Opus API access, and the $0 Claude app plan excludes Opus. Test-credit statement, Free-plan model access.
How is the Claude API billed?
The docs describe actual usage billed in US dollars. Add fresh input, output, cache writes and cache reads at the chosen model's rates, then applicable search, runtime or execution charges. Billing details.
Do I need to pay to use Claude API?
Yes, for usage beyond any initial test credits. The Free app does not provide a recurring production API allowance. API trial and billing FAQ.
Can I use my Claude subscription as an API?
A Pro or Max subscription does not replace separately metered API access for your app. The pricing page distinguishes included Claude Code usage from the pay-as-you-go API-credit route. Plans and API pricing.
What are the key differences between the Claude API and the Claude Pro subscription?
The API supplies metered model access for integrations and agents. Pro supplies personal Claude and Claude Code access within the plan's allowance, at $20 monthly or $200 annually. Choose according to where the work runs, then compare eligible personal-use costs. Official pricing.
Claude AI pricing for students
Students can use the $0 Free app. Anthropic's pricing page describes an institution-wide Education offer, including API credits, but does not publish a fixed individual student API discount. Student and Education pricing.
Does Claude offer refunds?
The consumer-plan pricing FAQ says payments are generally non-refundable, with exceptions under its terms or local law. It describes an in-app request within the 14-day EEA/UK withdrawal period. This consumer statement does not establish a refund promise for API credits. Refund policy.
Set Your App's Budget This Week
Start with one representative task and an acceptance rule. The useful number is the cost of an accepted result, including failed attempts, rather than the price of a single impressive response.
Measure the complete request
Count the input your app actually sends, including history and tools, plus output. Record cache reads and writes separately, and count searches and active hosted runtime when applicable.
Price the cheapest acceptable model
Evaluate Haiku first for bounded work, then Sonnet if it misses your quality bar. Escalate difficult jobs to Opus or Fable only when the improvement justifies the extra spend.
Match billing features to the workload
Cache unchanged context, batch work that can wait, and keep geography or speed premiums explicit. For standalone code execution, resolve the allowance discrepancy before adding an overage estimate.
Map each job to a suitable tool and budget with the AI Tools Map for Business Owners.
- Last Updated
- Oct 4, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Best AI Code Review Tools for Small Teams in 2026: CodeRabbit, Greptile, Cursor Bugbot, Codex, Claude Code and Codex Security
Compare six AI code reviewers: live prices for five developers, noise controls, GitHub and GitLab support, retention and one PR reviewed by three bots.Oct 2, 2026AI
Best AI Email Assistants in 2026: Fyxer, SaneBox, Superhuman, Shortwave, Gemini and Copilot (Compared)
Compare Fyxer, SaneBox, Superhuman, Shortwave and native Gmail/Outlook AI by job, live prices, setup time and mail storage.Oct 2, 2026AI
Granola Alternatives: Circleback, MeetGeek, Claap, Krisp, Otter, Fireflies and Fathom (Compared)
Compare Granola alternatives by Windows support, bot-free capture, team sharing, CRM integrations, languages and verified per-seat prices.Oct 1, 2026AI
Gamma Pricing (2026): Plans, Credits and Team Costs
Gamma Free, Plus, Pro and Ultra prices verified October 2026. Compare credits, exports, annual billing and solo or team costs.Oct 1, 2026AI
Wispr Flow Pricing (2026): Free Caps and Team Costs
Wispr Flow costs for 1, 5 and 20 people, monthly vs annual billing, free word limits, education discounts and cheaper dictation alternatives.Oct 1, 2026AI
How to Use Muse for Small Business
Set up Meta’s Muse for Small Business, connect Shopify and social accounts, and run a weekly review with approval rules and published pricing.Oct 1, 2026AI
Gemini 4 Argon Explained: Access, Cost and When to Switch
Gemini 4 Argon has restricted access and an undated price step. Compare official rates, published benchmarks and when to evaluate it.Oct 1, 2026AI