Gemini 3.8 Flash TTS Pricing
Price Gemini 3.8 Flash TTS by audio minute, compare Flash-Lite and service tiers, and budget the January 2027 increase.



Gemini 3.8 Flash TTS pricing starts at $0.0135 per generated minute on Standard, while Flash-Lite costs $0.009 per minute. Those are calculated output-only rates through December 31, 2026; Google is scheduled to double them on January 1, 2027, so a production budget should carry both numbers now.
Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS launched on September 23, 2026. I verified every rate below against Google's live Gemini Developer API pricing page on September 24, 2026, then converted Google's documented 25 audio tokens per second into generated minutes and hours.
Gemini 3.8 Flash TTS Pricing at a Glance
The cheapest route is Flash-Lite on Batch or Flex at $0.0045 per generated minute through December 31, 2026. The sensible default for an interactive production workflow is Flash-Lite Standard at $0.009 per minute. Pay for full Flash when fidelity, difficult pronunciation, dialect coverage, or acting direction matters enough to justify the difference.
Every duration figure in the table is a calculation, not a measured invoice. It covers generated audio output only. Your bill can also contain text-input tokens, cache reads, and cache storage.
Gemini 3.8 TTS Cost per Minute and Hour
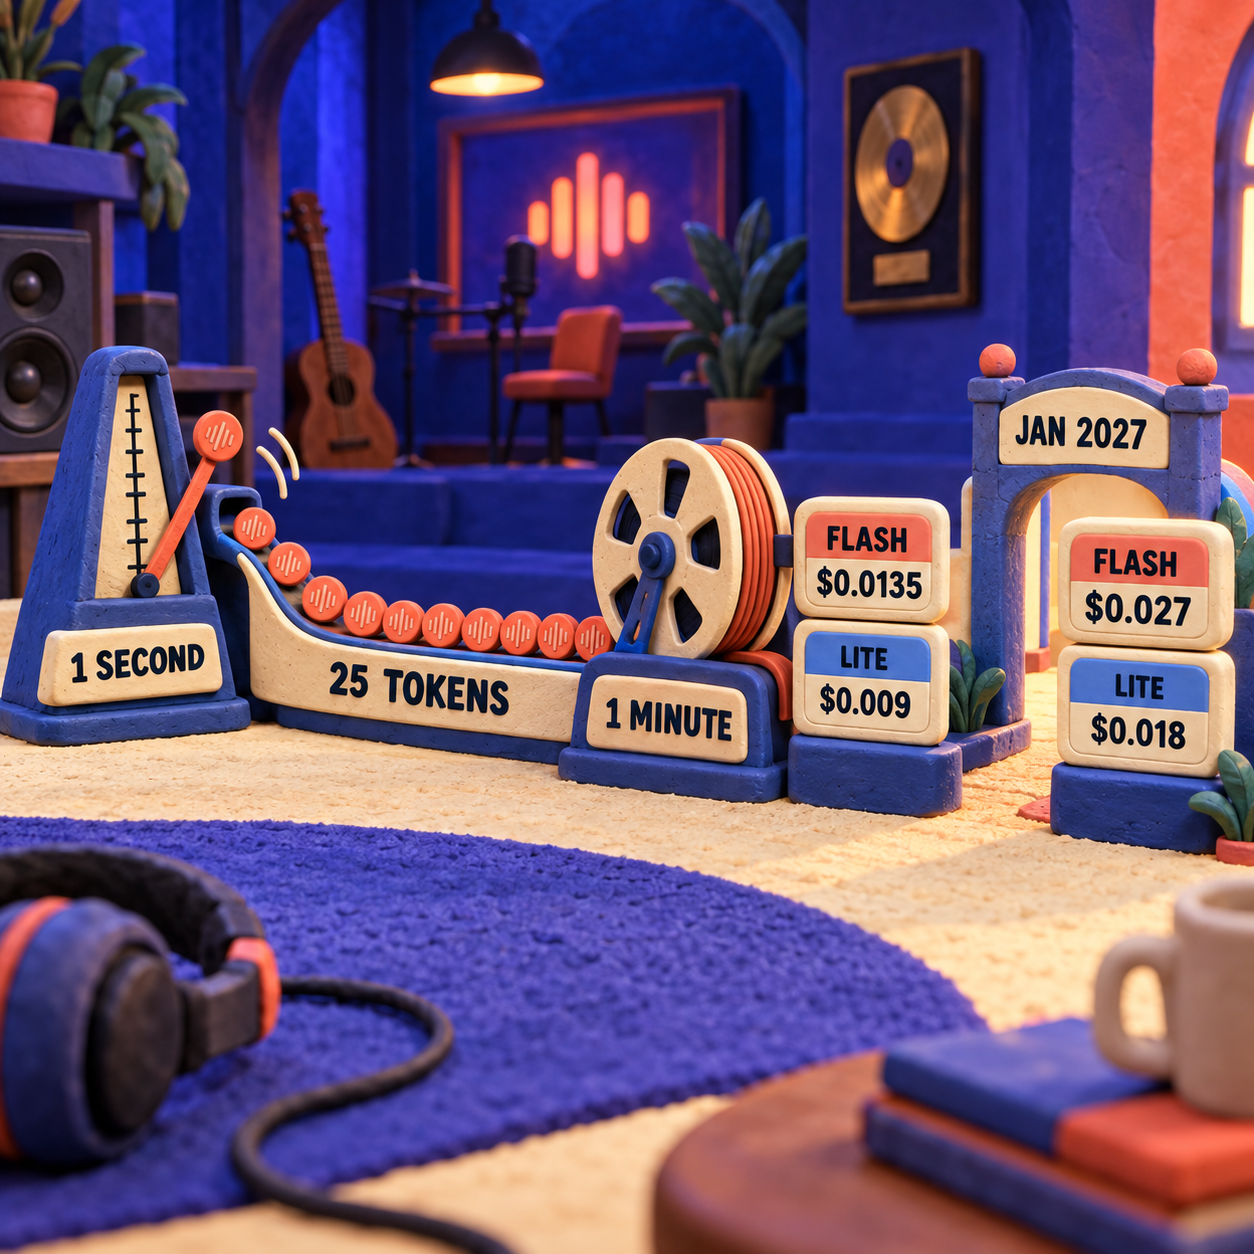
The duration math is simple once the billing unit is visible: Google counts 25 audio tokens per second, so one generated minute is 1,500 audio tokens and one generated hour is 90,000 audio tokens.
For Flash Standard through December 31:
- One minute: 1,500 divided by 1,000,000, multiplied by $9.00 = $0.0135.
- One hour: 90,000 divided by 1,000,000, multiplied by $9.00 = $0.81.
- One thousand generated hours: $0.81 multiplied by 1,000 = $810.
For Flash-Lite Standard, replace the $9.00 audio rate with $6.00. That produces $0.009 per minute, $0.54 per hour, and $540 per 1,000 hours. From January 1, 2027, the same workloads become $0.018 per minute, $1.08 per hour, and $1,080 per 1,000 hours.
The reproducible worksheet is:
- Audio output: generated seconds multiplied by 25, divided by 1,000,000, multiplied by the audio-output rate.
- Text input: the actual input-token count returned by the request, divided by 1,000,000, multiplied by the text-input rate.
- Cache reads: actual cached-input tokens, divided by 1,000,000, multiplied by the cache-read rate.
- Cache storage: cached tokens multiplied by storage hours, divided by 1,000,000, multiplied by the storage rate.
Do not estimate text tokens from audio duration. Record the input count that the API returns. If the usage record shows exactly 1,000,000 text-input tokens alongside 100 generated hours on Standard, Flash costs $81.50 now: $81 of audio plus $0.50 of text. Flash-Lite costs $54.50. From January 1, those totals become $163 and $109.
That distinction matters because a short script can create a slow, pause-heavy performance, while a dense script can be read quickly. Google meters the script and the resulting audio separately.
Gemini Flash-Lite TTS Pricing: When Lite Wins
Flash-Lite wins when the voice is a production component, not the main performance. Google's TTS model guide positions it for high-volume production, read-aloud features, voice-agent cascades, voice replication, and everyday single-speaker speech. It supports 101 languages and uses the same API schema as full Flash.
Full Flash is the creative tier. Google positions it for maximum fidelity, nuanced acting, difficult pronunciation, regional dialects, complex multi-speaker dialogue, and stable long-form narration across 130 languages. Its Standard output costs $0.27 more per generated hour than Lite through December 31, then $0.54 more from January 1.
The decision rule is audible failure, not prestige. Run the same approved script and voice direction through Lite first. If a pronunciation, dialect, character performance, or long scene misses the craft bar, change the model parameter and rerun that segment on Flash. Because the prompting structure is shared, you do not need two production systems.
- Raw generated-audio cost is low enough to audition whole chapters, courses, or localization batches.
- Flash and Flash-Lite share a schema, which makes selective escalation practical.
- Both models support Standard, Batch, Flex, and Priority consumption options.
- The rate card separates text, audio, cache reads, and storage instead of hiding them in credits.
- Google's public page does not state a fixed TTS-specific free allowance.
- Every listed paid TTS rate is scheduled to double on January 1, 2027.
- Flex is sheddable and can fail when capacity is tight.
- Token cost does not include the human listening, editing, mastering, and rights review needed for shipped audio.
Pick Standard, Batch, Flex, or Priority
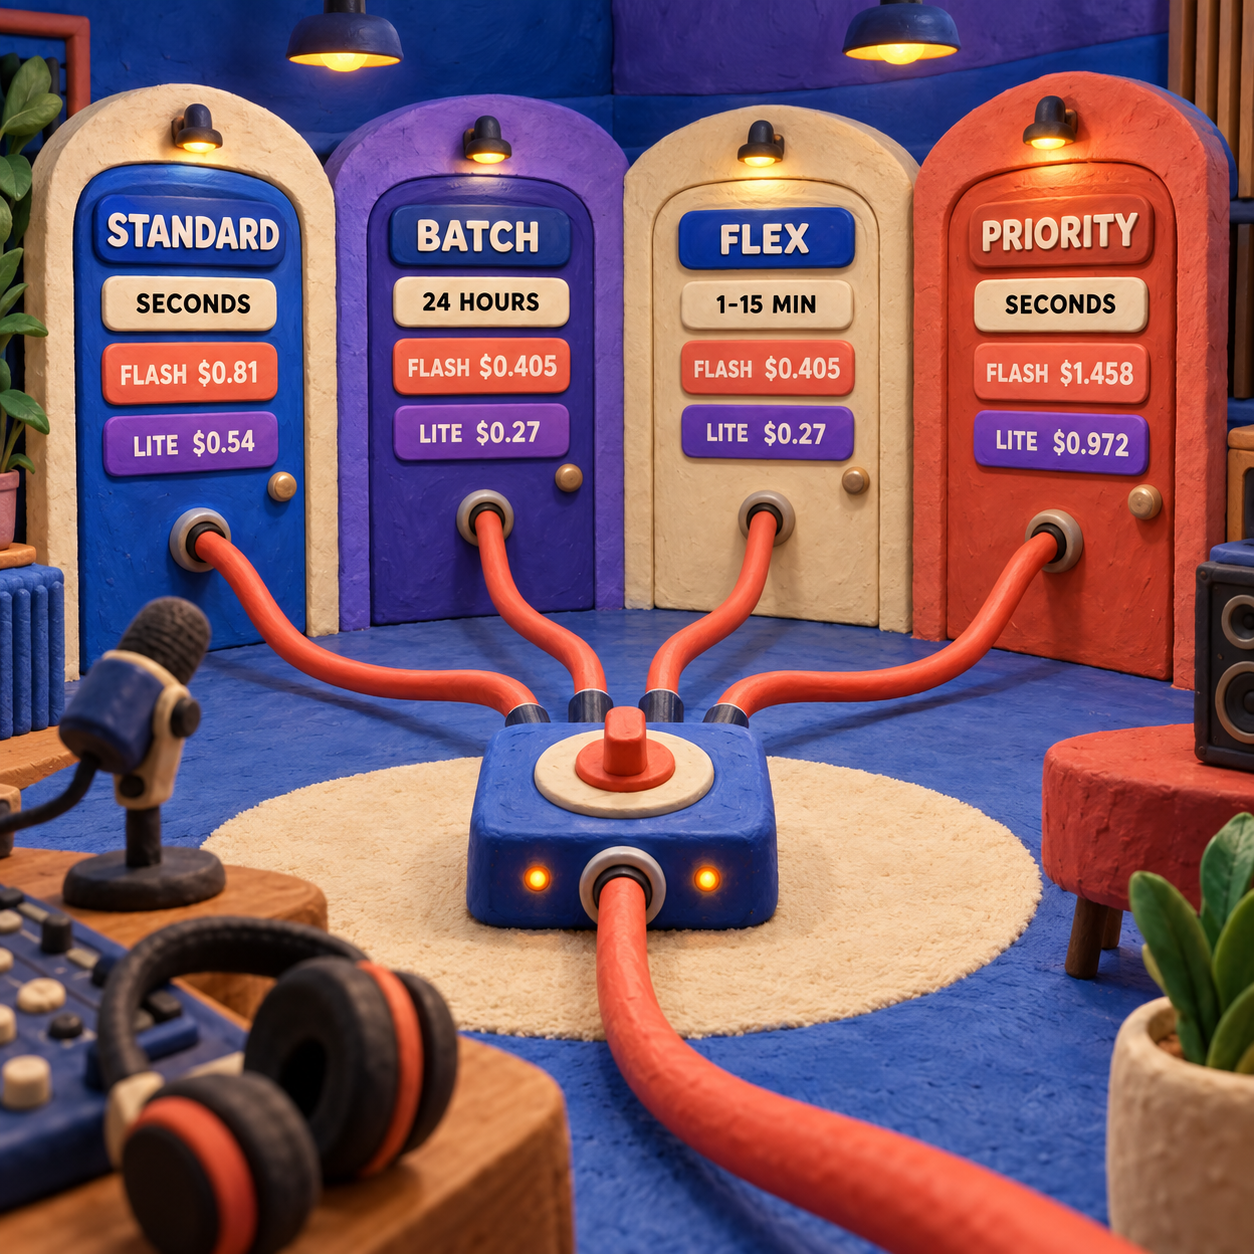
Choose the service tier by deadline and failure tolerance. The tier changes how the same model request is scheduled and billed.
Standard is the default for day-to-day production. It is synchronous, normally returns in seconds to minutes, and carries the full rate. Use it for an editor auditioning lines, a designer iterating voice direction, or an application that needs a response while the user is still present.
Batch is the cheapest reliable route for a queue you can leave overnight. It costs half the Standard rate, runs asynchronously, and has a target turnaround of up to 24 hours. A publisher rendering a completed audiobook or a learning platform regenerating a catalog should start here.
Flex costs the same as Batch but stays synchronous. Google targets 1 to 15 minutes and uses best-effort, sheddable capacity. A request can receive a capacity error, and Google will not silently upgrade it to Standard. Flex fits a background workflow whose next step needs the response but can retry later.
Priority is for the moment a delayed voice response damages the product. It routes synchronous traffic through higher-criticality capacity. If Priority limits are exceeded, Google can downgrade the request to Standard and bill it at the Standard rate. On today's TTS card, Priority is 1.8 times Standard, so Flash-Lite rises from $0.54 to $0.972 per output hour and Flash rises from $0.81 to $1.458.
Text Input, Audio Output, and Cache Storage Are Separate
The audio line dominates most TTS invoices, but it is not the whole voice-generation invoice.
Gemini TTS API Cost: The Four-Part Invoice
Text input is your transcript. Both models use the same Standard input rate: $0.50 per 1 million tokens through December 31, then $1.00. Batch and Flex halve that rate. Priority raises it to $0.90 now and $1.80 from January 1.
Audio output is the generated performance. This is where Flash and Flash-Lite diverge: Standard is $9 versus $6 per 1 million audio tokens now, then $18 versus $12.
Cache reads charge when you reuse cached input. Standard is $0.125 per 1 million cached tokens now; Batch is $0.0625, Flex is $0.025, and Priority is $0.225. Each doubles in January.
Cache storage is time-based. Every service tier lists $0.50 per 1 million cached token-hours through December 31 and $1.00 from January 1. Caching 8,000 tokens for 24 hours therefore costs $0.096 now. A Standard read of that cached block adds $0.001. From January, those two amounts become $0.192 and $0.002.
Caching is useful when a substantial instruction or pronunciation context repeats. It is not automatically economical for a short, unique script. Price the storage duration and expected cache hits before treating the lower read rate as a saving.
There is no monthly or annual TTS subscription in this rate card. Paid API usage is metered, so there is no annual discount to earn and no included monthly allowance to overrun. The lock-in risk sits elsewhere: unused Gemini API prepay credits expire after one year and are generally non-refundable.
Gemini TTS Free Tier: What Google Documents
Google lists text input, audio output, and context caching as free of charge in the free-tier column for both Gemini 3.8 TTS models. It does not publish a TTS-specific token allowance or a guaranteed number of free audio minutes on the pricing page.
That makes the free tier useful for voice auditions, prompt-shape checks, and small prototypes, but unsafe as the capacity plan for a production launch. Google says active limits depend on the project's usage tier, appear inside AI Studio, update with account status, and are not guaranteed. Check the project rather than copying a quota from a blog post.
The privacy tradeoff also changes with billing. Google's pricing page says free-tier content may be used to improve its products, while paid-tier content is not used for that purpose under the linked terms. A client voice, unreleased script, or sensitive training module belongs in that decision before it enters the tool.
Who never needs to pay? A designer who only auditions a few voices and remains within the project's live limits may stay free. Anyone promising delivery volume, throughput, or confidential production work should budget the paid tier instead of treating an unspecified allowance as infrastructure.
The Same Voice Brief, Costed Before and After
A 100-hour single-narrator training library is the cleanest way to see the model decision. On Standard through December 31, the calculated output subtotal is $54 on Flash-Lite and $81 on Flash. From January 1, it becomes $108 and $162. Text input, caching, and any regenerated takes sit on top.
The first pass should use Flash-Lite because most routine narration does not need the flagship model on every line. The revision pass should promote only the material that fails a named craft check: a regional name pronounced badly, an emotional scene that reads flat, a multi-speaker exchange that loses separation, or long-form audio whose voice or room tone drifts.
Lock one representative brief
Choose a script that contains the hard material your production will face: names, numbers, pauses, emotional turns, and more than one speaker where relevant. Keep the transcript identical across models.
Direct the performance correctly
Gemini 3.8 TTS treats transcript text as words to recite. Put sustained direction in structured speech metadata and reserve inline tags for point-in-time vocal events, so an instruction is not spoken aloud by mistake.
Audition Flash-Lite first
Generate a controlled pilot, then save the returned input-token usage and the actual audio duration. This article did not generate a sample, so its duration figures remain calculated output-only costs rather than measured invoice claims.
Escalate only failed segments
Keep acceptable Lite output. Switch the model parameter to Flash for the passages that miss pronunciation, dialect, acting, speaker separation, or long-form consistency.
Choose the queue
Use Standard while a human is directing. Send an approved backlog to Batch, choose Flex only with retry handling, and buy Priority only when waiting breaks the user experience.
Do Not Confuse TTS With Gemini Live or Text-Only Flash
Gemini 3.8 Flash TTS accepts text and returns an audio performance. The general gemini-3.8-flash model is a different endpoint with a different rate card, so the text model's familiar input and output prices do not belong in a TTS estimate. The broader Gemini pricing breakdown covers how consumer plans and Developer API billing stay separate, while the Gemini 3 review covers the general model family.
Gemini Live is different again. Google's speech guide describes TTS as exact recitation with controlled style and sound, while Live handles interactive, unstructured audio and multimodal conversation. A narrated course, audiobook, or approved ad script is TTS. A voice agent that listens, reasons, calls a tool, and keeps a caller engaged is a Live workflow with a different cost model. The Gemini 3.8 Live workflow analysis explains that operating decision.
This distinction prevents the most expensive spreadsheet error: using a cheap text-token figure to budget generated speech, or using the TTS output rate to budget a persistent live session.
Gemini TTS Versus ElevenLabs and Deepgram
Gemini is cheaper on raw generated duration than two common API shortlists at the introductory Standard rates, but the meters are not identical and price does not establish voice quality.
ElevenLabs API pricing lists Flash/Turbo and v3 Conversational at $0.05 per 1,000 characters and shows that as approximately $0.05 per minute, or about $3 per hour. Its v3 creative model is approximately $0.10 per minute, or $6 per hour. Against that published minute estimate, Gemini Flash-Lite Standard is $0.54 per hour now and Flash is $0.81.
Deepgram pricing meters Aura-2 at $0.030 per 1,000 characters and Aura-1 at $0.015. Under a declared planning assumption of 1,000 characters per spoken minute, those normalize to about $1.80 and $0.90 per hour. That assumption is the weak point: speaking rate, pauses, and nonverbal audio change duration, while Deepgram still bills characters.
The honest comparison is a paid audition on your own script. Normalize the providers to the same approved hour, include discarded takes, and score pronunciation, performance, consistency, latency, and editing time. Gemini's raw token advantage is meaningful, but a cheaper voice that creates more revision work is not the cheaper production.
Hidden Costs and the January 2027 Budget Move
The scheduled rate change is the budget risk. A 1,000-hour Flash-Lite Standard backlog costs $540 in calculated audio output if completed by December 31 and $1,080 from January 1. Flash moves from $810 to $1,620. Batch or Flex after the increase costs the same output subtotal as Standard does today.
The other costs are operational:
- Regeneration: rejected takes create more billable audio output.
- Human quality control: every proper noun, number, consent-sensitive voice, and final edit needs review.
- Cache storage: a saved context keeps billing by token-hour until it is released.
- Prepay expiry: unused Gemini API prepay credits expire after one year and are generally non-refundable. Unused postpay funds may be eligible for a refund, but promotional credits are not.
- Application split: a consumer Gemini subscription does not turn Developer API TTS into an included feature.
The Monday move is concrete: run one representative hour through Flash-Lite Standard, save actual text-input usage and output duration, mark every segment that fails the craft bar, and rerun only those segments on Flash. Put the resulting mix into two budget columns, one at today's rates and one at January's. Then move the approved backlog to Batch if a 24-hour target is acceptable.
Pricing FAQ for Gemini 3.8 TTS
How much does Gemini Audio TTS cost?
Through December 31, 2026, Standard audio output costs $0.009 per minute for Gemini 3.8 Flash-Lite TTS and $0.0135 per minute for Gemini 3.8 Flash TTS. Those calculated figures exclude text input, cache reads, and cache storage.
How much do 1000 tokens cost?
Token type matters. On Standard today, 1,000 text-input tokens cost $0.0005 for either model. One thousand audio-output tokens cost $0.009 on Flash or $0.006 on Flash-Lite and correspond to 40 seconds of generated audio. Each amount doubles on January 1, 2027.
Is Google TTS API free?
Google lists Gemini 3.8 Flash TTS and Flash-Lite TTS input, output, and caching as free of charge on the free tier. It does not publish a fixed TTS-specific token or minute quota, so check the active limit in AI Studio.
How to get TTS for free?
Create or select an active project in Google AI Studio, open the speech-generation workspace, and use one of the two Gemini 3.8 TTS models within the project's free limits. Do not assume the free capacity is guaranteed for production.
Does TTS cost money?
Yes, once you use the paid Gemini API tier. Google bills text input, audio output, cache reads, and cache storage separately; the output-only Standard rates currently begin at $0.009 per generated minute.
How expensive is TTS?
Gemini Flash-Lite Standard currently costs $0.54 per generated hour in audio output, while Flash costs $0.81. Batch and Flex halve those amounts; Priority raises them to $0.972 and $1.458.
What is the best FreeTTS software?
Gemini TTS is a cloud API, not the FreeTTS software library. If the goal is zero-cost evaluation, Gemini's free tier is useful, but its public pricing page does not promise a specific number of free minutes.
How do I turn on Google TTS?
Open Google AI Studio's speech-generation workspace or call gemini-3.8-flash-tts or gemini-3.8-flash-lite-tts through the Gemini API with an active project and API key.
Does Gemini 3.8 Flash TTS have a student discount?
Google's Developer API pricing page lists no student-specific rate for Gemini TTS. Students use the same free or paid API tiers shown for every developer.
Can I get a refund for Gemini TTS API charges?
Google says unused funds in a linked postpay payments account may be eligible for a refund. Unused Gemini API prepay credits expire one year after purchase and are generally non-refundable, while promotional credits are also excluded.
Did Gemini 3.8 Flash TTS pricing change in 2026?
The models launched on September 23, 2026 with introductory paid rates. Those rates apply through December 31 and are scheduled to double on January 1, 2027.
Use the AI Business Workflow Audit Checklist to decide where generated voice belongs before you commit a production budget. Get it with the newsletter.
- Last Updated
- Sep 24, 2026
- Category
- Design
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Best Software for Tatting Diagrams
Compare tools for tatting diagrams by ring and chain editing, stitch labels, reusable symbols and clean printable patterns.Sep 20, 2026Design
Best Software for Tablet Weaving Patterns
Compare tablet-weaving tools for threading, turning, twist control and printable drafts so your design can reach the loom.Sep 20, 2026Design
PCStitch vs WinStitch for Photo Conversion
Compare PCStitch and WinStitch on photo cleanup, thread colors and readable charts before turning a picture into a stitching project.Sep 20, 2026Design
Quilt Assistant Review
QuiltAssistant turns photos into pieced blocks and templates. Check its free tools, old Windows release and limits before choosing it.Sep 20, 2026Design
WinStitch Pricing
Decode WinStitch's Premium price, local taxes, Mac bundle and optional lifetime upgrades before paying.Sep 20, 2026Design
ngram vs Demosmith
Compare ngram and Demosmith for product videos, browser capture, revisions and usable exports, with costs matched to the same job.Sep 19, 2026Design
How to Tile Sewing Patterns in Seamly2D
Export a Seamly2D pattern as tiled pages, set the printer scale, align the sheets and check a test square before cutting fabric.Sep 19, 2026Design