Gemini 3.8 Live Keeps Callers Talking During Lookups
Gemini 3.8 Live runs tools during voice calls. See what changes for booking flows, customer updates and the cost of a completed task.




On September 15, 2026, Google made Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking generally available. The useful change is simple: a voice agent can keep a caller informed while your calendar, order system, or booking API does the slow work in the background.
The call no longer has to stop for the lookup
A voice agent usually has two jobs happening at once. It has to hold a natural conversation, and it has to do real work in another system.
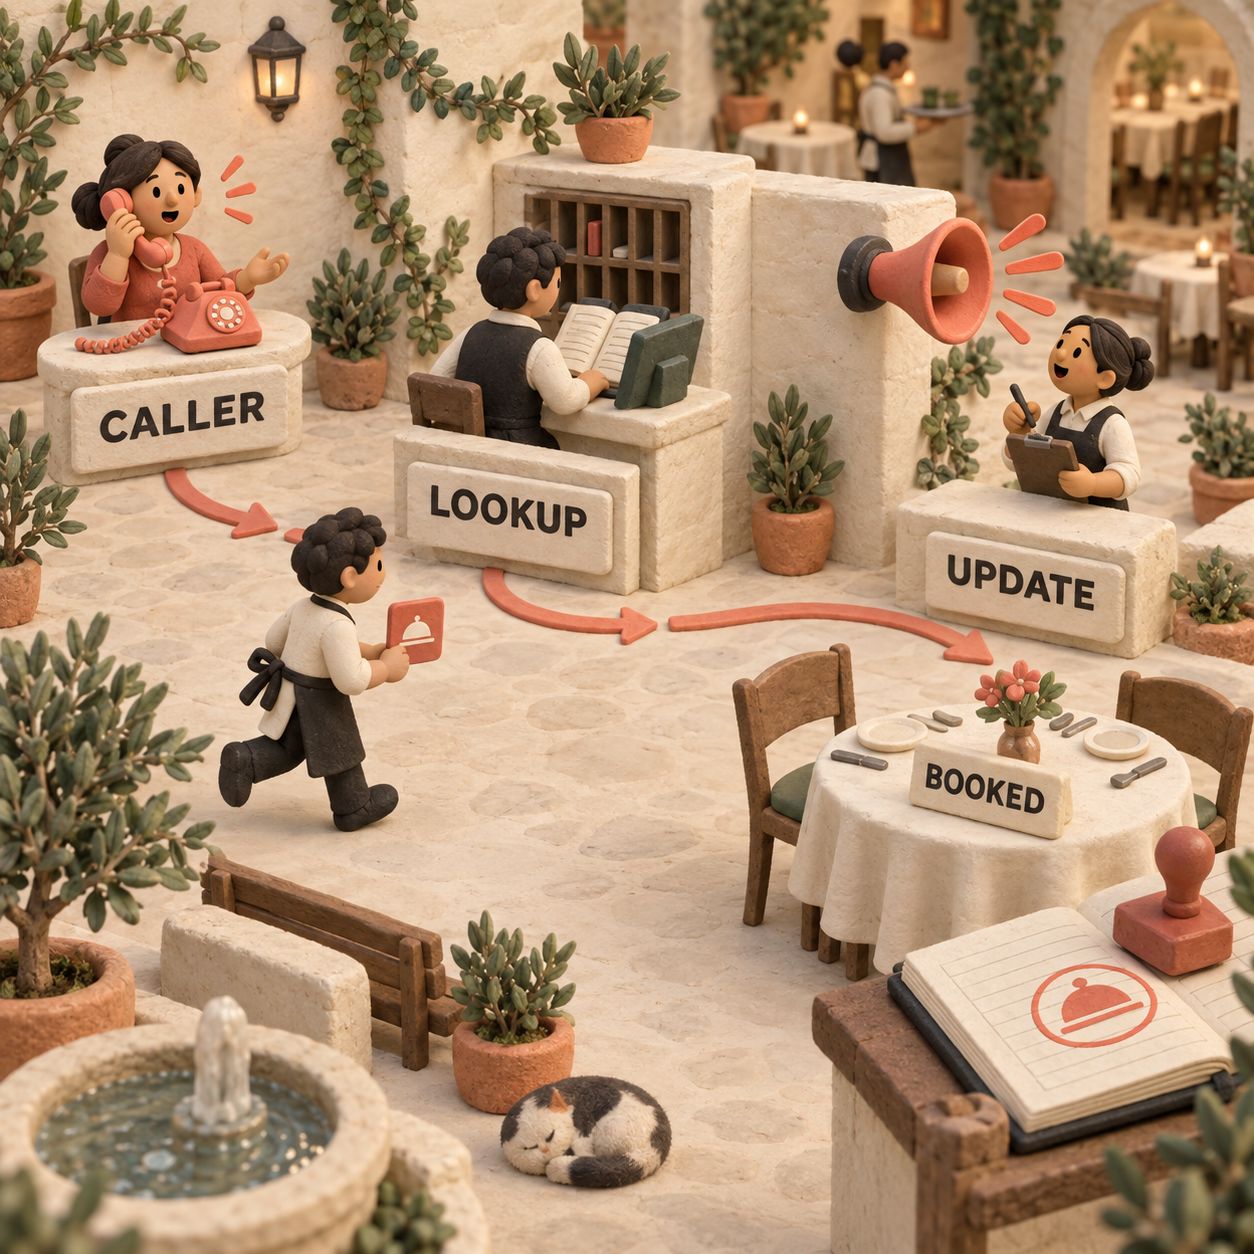
That second job is where calls get awkward. The agent asks your booking API for an open slot, waits, and leaves the caller in silence. The caller repeats the request, asks whether anyone is there, or hangs up. If the application treats that repeat as a new instruction, it can also start the same task twice.
Gemini 3.8 Live changes that flow with asynchronous function calling. Asynchronous means the tool can keep running without freezing the entire live session. The caller can add context, correct a detail, or hear an update while the lookup is still in flight.
Gemini 3.8 Live Extended Thinking goes further. It can reason through a multi-step task and speak short progress updates while tools run. Google's own example is a travel booking flow that checks several systems without interrupting the live conversation.
This does not mean Gemini books anything by itself. Your application still receives the function call, runs the calendar or order lookup, and sends the result back. The model handles the conversation around that work.
That last column is the production trap. With Extended Thinking, turnComplete: true can mean only that an intermediate spoken update has finished. The lookup may still be running. Close the session, enable the booking button, or mark the task complete at that point and you create false completions.
The business metric is cost per completed task
Background speech is not automatically a saving. It can add model output while a tool runs, and a longer conversation can increase the amount of context processed again on later turns. The feature earns its place only when the extra continuity produces more finished bookings, fewer abandoned calls, or less human cleanup.
Google lists the same standard rates for both new models: audio input costs $0.005 per minute and audio output costs $0.018 per minute. Text input costs $0.75 per 1 million tokens, while text output, including thinking tokens, costs $4.50 per 1 million tokens.
Take a five-minute booking call where the model speaks for two minutes. Because proactive audio is permanently enabled, the simple new-audio arithmetic is $0.025 for five minutes of input plus $0.036 for two minutes of output. That is a $0.061 raw audio subtotal.
It is not the final call cost.
The Live API billing guide says the persistent session can reprocess accumulated context on later turns. Transcriptions add text-token charges. Extended Thinking can add thinking output. Your calendar, CRM, phone carrier, hosting, retries, and human escalation sit outside Google's audio subtotal.
Use this formula instead:
Cost per completed task = all model, tool, phone, infrastructure, retry, and escalation spend divided by verified completed tasks.
A completed task is not a pleasant transcript. For an appointment line, it is a booking ID written once, read back correctly, and accepted by the caller. For order support, it is the right order action attached to the right account. For a transfer, it is a handoff that reached the intended queue with the context intact.
Google periodically returns consumed-token totals in usageMetadata. Join that record to the tool-call ID, carrier session, final business result, and any human work. That gives you a per-call ledger you can audit instead of a per-minute estimate you have to trust.
The launch numbers do not replace this pilot. Google reports 68.6% on the tau-Voice task benchmark and 35.1% on its banking version for Extended Thinking. Those scores tell you the model can be tested on agentic voice work. They do not tell you what percentage of your callers will finish a booking in your calendar, with your policies and your phone connection.
Four workflows where the wait matters
A dental practice booking an appointment
An operations lead can let the agent collect the caller's preferred day, run an availability check, and say that it is still looking while the calendar responds. The payoff is not shorter silence by itself. It is more confirmed appointments with fewer staff callbacks.
The safety rule is strict: a spoken update is not a reservation. The system should create a booking only after the caller chooses a returned slot, and retries should reuse an idempotency key so one call cannot create the same appointment twice.
An ecommerce team checking an order
A support lead can keep the caller in the same conversation while the agent queries the order system. If the caller changes from “where is my package” to “change the delivery address,” your application must treat the newer request as the active one and cancel or ignore stale work.
The payoff is fewer handoffs for routine cases. The risk is a correct answer to an old question, delivered after the caller has moved on.
A travel team handling a rebooking
Flight search, policy checks, hotel availability, and fare comparison make this a better fit for Extended Thinking. The model can narrate progress while several non-blocking functions run.
Keep payment and ticket changes behind a confirmation step. A natural voice does not lower the approval standard for an irreversible action.
A technical-support queue diagnosing an account issue
A fast account lookup belongs on Gemini 3.8 Live. A diagnosis that gathers several logs and checks a configuration can justify Extended Thinking.
That split matters because deeper reasoning is not free. Route by job complexity, then compare resolution and escalation rates. Do not put every password reset through the heavier path because the model name sounds safer.
Wire the background lifecycle before the phone line
Start with a text-triggered session and a stub tool. It isolates the async behavior before a carrier, microphone, audio bridge, and production calendar add four more places to debug.
The example below follows Google's current Python SDK, Extended Thinking configuration, non-blocking function declaration, tool-response pattern, interaction_status, and usageMetadata fields. It writes returned 24 kHz audio to response.wav. The tool result is a local stub, so it does not touch a real calendar.
pip install -U google-genai
export GEMINI_API_KEY="YOUR_API_KEY"import asyncio
import wave
from google import genai
from google.genai import types
client = genai.Client()
model = "gemini-3.8-live-extended-thinking"
check_availability = types.FunctionDeclaration(
name="check_availability",
description="Checks the calendar for the next available appointment.",
behavior="NON_BLOCKING",
parameters={
"type": "OBJECT",
"properties": {},
},
)
config = types.LiveConnectConfig(
response_modalities=["AUDIO"],
thinking_config=types.ThinkingConfig(thinking_level="low"),
tools=[types.Tool(function_declarations=[check_availability])],
)
async def main():
async with client.aio.live.connect(model=model, config=config) as session:
await session.send_client_content(
turns={
"parts": [
{"text": "Find the next available appointment and keep me updated."}
]
}
)
with wave.open("response.wav", "wb") as audio:
audio.setnchannels(1)
audio.setsampwidth(2)
audio.setframerate(24000)
async for message in session.receive():
status = getattr(message, "interaction_status", None)
if message.data is not None:
audio.writeframes(message.data)
if message.usage_metadata:
print("Tokens:", message.usage_metadata.total_token_count)
if message.tool_call:
replies = []
for call in message.tool_call.function_calls:
replies.append(
types.FunctionResponse(
id=call.id,
name=call.name,
response={"result": "Tuesday morning is available."},
)
)
await session.send_tool_response(function_responses=replies)
if status == "IDLE":
print("Interaction complete")
break
if __name__ == "__main__":
asyncio.run(main())The one thing people will get wrong is breaking on the first turnComplete. Extended Thinking may have spoken “I am checking” and still be waiting on the tool. Keep listening until interaction_status is IDLE, and keep the tool-call ID attached to the eventual business result.
For a production phone agent, add the audio bridge only after this loop behaves correctly. The broader voice-agent cost comparison is useful for choosing the carrier and orchestration layers around the model. If you are comparing Google's token meter with a simpler front-end voice rate, the GPT-Live-1 call-cost breakdown shows why the completed-task denominator matters on both.
Run the pilot around a ledger, not a demo
Pick one completion event
Use one narrow workflow, such as a confirmed appointment. Write the exact database event that proves completion, and name every state that counts as failure, abandonment, duplicate work, or human escalation.
Log the live lifecycle
Store the session ID, every tool-call ID,
interaction_statuschanges, tool start and finish times, andusageMetadata. A spoken filler is progress, not completion.Join every billed layer
Attach Gemini usage, calendar or CRM fees, carrier charges, infrastructure, retries, and staff time to the same call record. Do not compare Google's $0.061 illustrative audio subtotal with an all-in incumbent bill.
Test the failure paths
Interrupt the agent, change the requested date while a lookup runs, make the tool time out, return no availability, and hang up before the result. Confirm that stale calls cannot write a booking.
Compare completed tasks
Run the same call types through the current flow and the new flow. Compare verified completion, abandonment, escalation work, duplicate actions, and total cost per completed task. Claim a saving only after those records reconcile.
The honest limits
The model can fill silence. It cannot make a slow calendar fast, repair a bad phone connection, or decide what your business counts as done.
Audio-only sessions are limited to 15 minutes unless you add session-management techniques for longer conversations. The native-audio context limit is 128,000 tokens. Long, turn-heavy calls also cost differently from a simple duration estimate because old context can be processed again.
Security still belongs to your application. A browser that connects directly should use ephemeral tokens, not a standard API key. A booking, refund, or account change still needs authentication, validation, idempotency, and an audit trail.
The async path creates one more production risk: stale work. If a caller changes the request while a tool is running, the old result can arrive later. Track task state explicitly and reject results that no longer match the current intent.
Monday's move: instrument one narrow queue
Act this week if silent tool waits are causing callers to repeat themselves, abandon a booking, or require staff cleanup. Put Gemini 3.8 Live on direct lookups and Extended Thinking on one genuinely multi-step flow. Keep both behind the same completion ledger.
Wait if you cannot yet prove completion in your own system, if your carrier path is unsettled, or if the workflow contains an irreversible action with no confirmation gate. You need the record before you need the new model.
This release does not matter to text-only products, voice flows whose tools already return immediately, or a working phone agent that already meets its completion, escalation, and cost targets. A new model is not a reason to replace a measured system.
For more plain-English breakdowns of changes that move operating costs and workflows, join the newsletter.
- Last Updated
- Sep 16, 2026
- Category
- Explained
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Cloudflare Can Stop AI Spend Landing on the Wrong Bill
Cloudflare AI Gateway can require your provider credentials. Learn when missing keys stop a request and which charges stay separate.Sep 17, 2026Explained
Cloudflare Lets Python Apps Reuse Existing Databases
Python Workers can connect through Hyperdrive. Check what that changes for an existing database, app architecture and hosting bill.Sep 16, 2026Explained
Cloudflare Limits What a Client's Deploy Agent Can Change
Cloudflare adds access controls for individual Workers. See how to separate debugging, code review and deployment rights across client projects.Sep 15, 2026Explained
Claude Code Stops One Install From Widening the Whole Job
Claude Code can approve network hosts for one command at a time. See what that changes for dependency installs and unattended build jobs.Sep 15, 2026Explained
Vercel AI SDK Can Move Agent Spend to Existing Plans
Vercel AI SDK can use supported agent subscriptions. Check which credentials win, which allowance pays, and what sandbox costs remain.Sep 15, 2026Explained
Cloudflare Browser Run Keeps Client Jobs on Approved Hosts
Limit client browser jobs to approved hosts, budget for required CDNs, and let reviewers watch through read-only Live View.Sep 14, 2026Explained
GPT-Live-1 Changes the Budget for AI Phone Calls
Understand GPT-Live-1 phone-agent costs: the voice layer, backend reasoning, telephony, and the interruption handling worth testing.Sep 14, 2026Explained