GPT-Live-1 Changes the Budget for AI Phone Calls
Understand GPT-Live-1 phone-agent costs: the voice layer, backend reasoning, telephony, and the interruption handling worth testing.



GPT-Live-1 makes one part of an AI phone call easy to price: the voice session costs $0.05 per minute. Since September 10, 2026, teams can simplify the speaking and listening loop, but the useful budget number is still the full cost of a resolved call, including backend reasoning, tools, and phone transport.
The five-cent line is the voice layer
GPT-Live-1 is a full-duplex voice model. Full duplex means it can listen while it speaks, so a caller can interrupt, pause, correct a detail, or give a short acknowledgment without waiting for a rigid turn to end.
That changes the shape of the system. A traditional voice agent often chains speech-to-text, a language model, and text-to-speech. Your application has to move information across each handoff and decide what happens when both sides talk at once.
GPT-Live-1 handles the live conversation in one voice layer. It listens, speaks, tracks timing, and decides when deeper work should go to a backend. That backend might check a reservation, read an account record, call a tool, or reason through a policy.
The backend is deliberately separate. You can use Responses delegation, where GPT-Live-1 sends work to an OpenAI text model you configure, or client delegation, where your own application runs any model, agent, or service and returns the result. The voice can stay the same while you choose a cheaper or deeper brain for the task.
The phone connection is separate again. An inbound call can reach GPT-Live-1 through a SIP trunk, which is the internet connection supplied by a phone provider, or through an application that relays the audio. OpenAI handles the Live session. Your carrier still handles the number and phone transport.
That is the whole budget change. You no longer have to price speech recognition and speech generation as two separate OpenAI model stages for this path. You do have to keep three ledgers straight.
The bill has three moving parts
The first trap is the clock. GPT-Live-1 billing follows the active session from start through closure. Silence counts. Time spent waiting for a tool counts. Muting the microphone does not stop the bill.
The second trap is treating the backend as free because it runs behind the conversation. It does not. Standard short-context pricing for GPT-5.6 Luna is $0.20 per million input tokens and $1.20 per million output tokens. GPT-5.6 Terra is $2.00 and $12.00. GPT-6 Astra is $10.00 and $50.00. The right comparison is not which model has the lowest token rate. It is which combination finishes the job reliably with the least total call time and rework.
A reservation call shows the real math
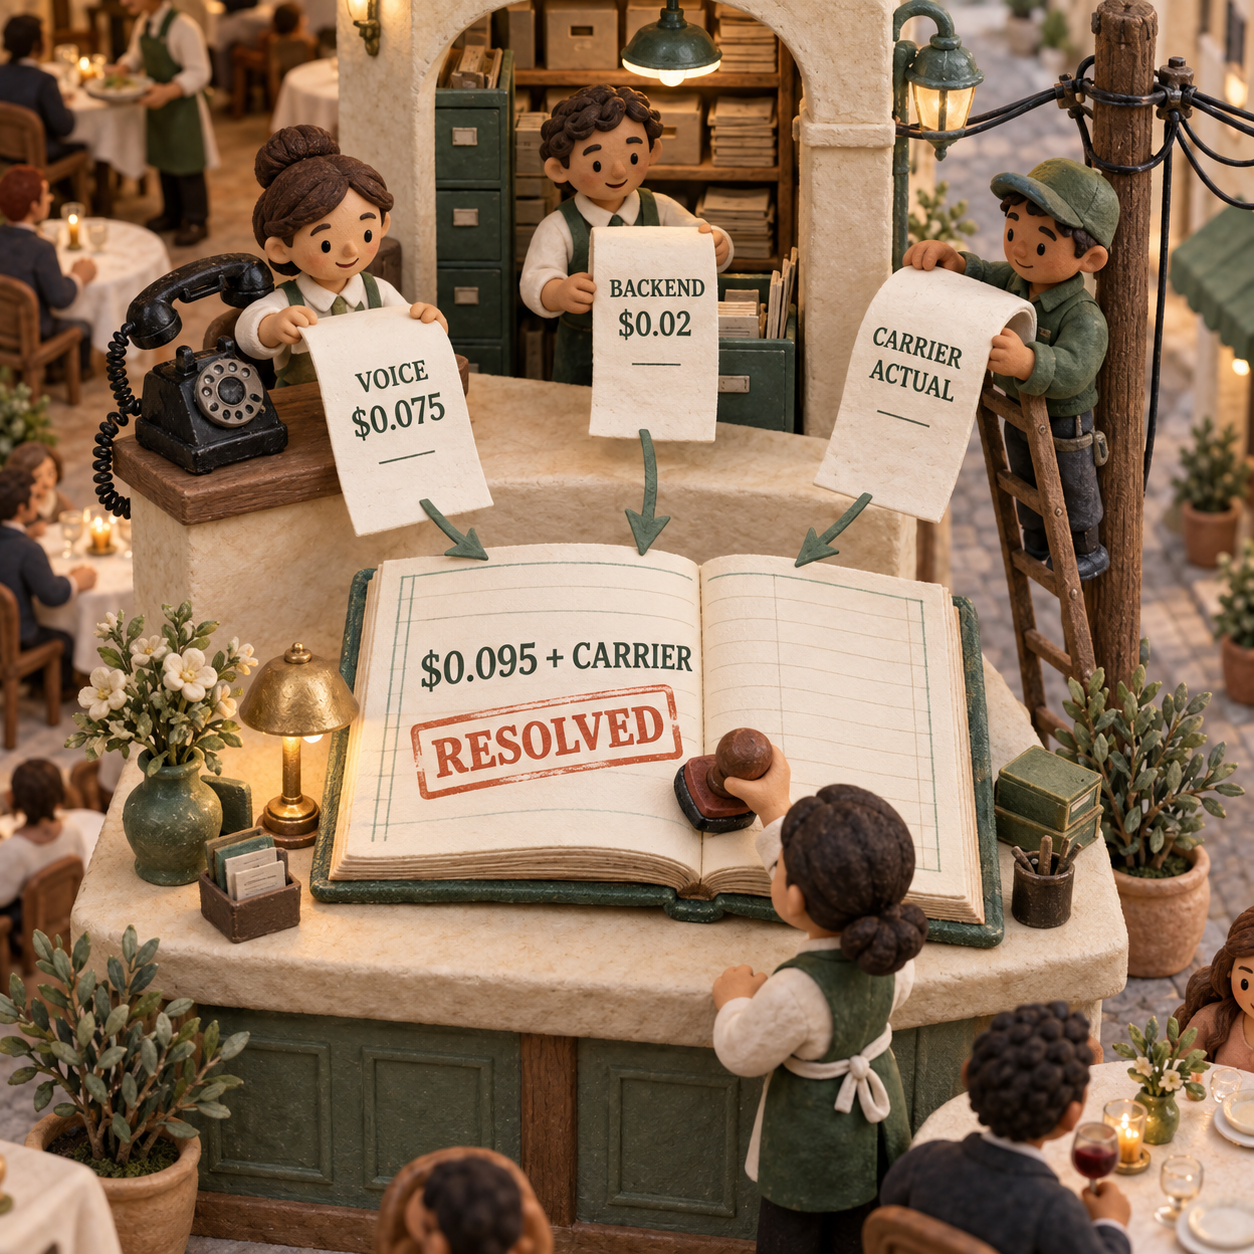
Take a 90-second inbound restaurant reservation call. OpenAI's own cost example gives the clean starting point:
- Voice: 90 seconds divided by 60, multiplied by $0.05, equals $0.075.
- Backend: assume the measured model and tool usage for this example totals $0.02.
- Voice-plus-backend subtotal: $0.095.
- Phone transport: add the carrier charge for that actual call.
So the call does not cost $0.075. It costs $0.095 plus phone transport in this example. If the reservation is confirmed, that is the direct runtime cost of one resolved reservation. If the agent fails and a person has to repeat the work, the failed call stays in the numerator when you calculate cost per resolution.
This is why a symbolic carrier line is more honest than dropping a made-up market rate into the total. OpenAI does not set that carrier line, so pull the transport charge from your own provider invoice.
There is one more interaction in the math. A faster backend can be worth a higher token rate if it closes the Live session sooner. One minute less open time saves $0.05 in voice charges. A cheaper backend can cost more overall if it makes the caller repeat details, waits on tools, or fails the reservation.
Where this fits in a real call flow
A restaurant operator can put GPT-Live-1 on an inbound reservation number and keep the job narrow. The voice layer handles the conversation. A low-cost backend checks availability and prepares the booking. The application confirms the final slot, writes the reservation, and prevents a late result from booking the wrong time.
A support lead can use the same frontend with different backend policies. Routine order lookups can go to a cost-sensitive model. A disputed charge or policy exception can go to a deeper model or a human. The payoff is not one voice model doing every job. It is choosing reasoning cost by task while keeping one spoken experience.
A product team with an existing speech-to-text, model, and text-to-speech chain has a different decision. GPT-Live-1 may remove handoff code and make overlapping speech easier to manage, but migration only pays if the new system improves task completion or maintenance enough to cover the work. The broader AI voice-agent cost comparison is still useful when the choice is build versus buy.
A browser-app team can connect through WebRTC and skip the phone-provider line entirely. It still pays for Live duration and backend work. Text-only agents, batch workflows, and apps where nobody needs to speak are not affected by this release.
The smallest useful phone pilot
The direct SIP path starts when your provider sends an inbound call to OpenAI and your webhook receives a Live session ID. This is the documented acceptance shape:
curl -X POST "https://api.openai.com/v1/live/sessions/$SESSION_ID/accept" \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "session": {
      "type": "live",
      "model": "gpt-live-1",
      "instructions": "You are answering an inbound support call.",
      "audio": { "output": { "voice": "marin" } },
      "delegation": { "type": "client" }
    }
  }'
The API key stays on your trusted backend. SIP negotiates the audio format, so you leave audio.format out. The client-delegation setting means your application owns the backend model, tools, permissions, and usage records.
For an inbound reservation pilot, the work is short enough to keep the measurement clean.
Choose one outcome
Use a confirmed reservation, not a pleasant conversation, as success. Save the requested time, the final booked time, and whether a person had to take over.
Record every cost line
Keep the latest cumulative voice seconds during the call. On graceful close, replace that value with final
session.closedusage. Save each backend response ID and its token and tool usage once. Join those records to the carrier's call detail.Test how people actually interrupt
Use the pauses, corrections, background speech, and short acknowledgments your callers make. Check the transcript, the action your backend took, and the audio the caller actually heard. A completed backend response does not prove the result was spoken.
Compare cost per completed job
Add voice, backend, and transport spend across the pilot, then divide by confirmed reservations. Keep failed calls, retries, and human handoffs in the spend. Compare that result with the current system on the same call scripts.
The interruption claim still needs your data
GPT-Live-1 is built for overlapping speech, but a launch example is not your service-level agreement. Andrew Hsu, Speak's co-founder and CTO, says Speak's early evaluation cut interruptions during thinking pauses by almost 80% compared with its previous turn-based systems. That result belongs to Speak's language-tutor setup.
A noisy restaurant line, a support caller reading an order number, and a patient pausing before a date are different workloads. Prompting, the phone codec, carrier jitter, tool latency, and your own playback controls all affect what the caller experiences. There is no honest universal interruption or latency improvement to copy into a forecast.
The production edge case matters too. When a caller interrupts and changes Friday to Thursday, the spoken correction does not automatically cancel backend work for Friday. Your application has to revise or cancel the old task, ignore a late result, and make sure a retry does not create a second booking.
Direct GPT-Live SIP currently covers inbound calls. The Live session creation endpoint does not originate an outbound SIP call, so outbound campaigns still need a provider-owned partner path. Teams that need outbound first should verify that route before planning a migration.
What to do on Monday
If you run an inbound reservation or support queue, instrument one narrow pilot. Put voice seconds, backend usage, carrier charges, completed jobs, handoffs, and interruption failures in the same record. Test a cost-sensitive backend against the deeper model you think you need.
Move forward when the full cost per resolved call beats your current stack and callers can correct the agent without producing stale actions. Wait when the only win is the $0.05 headline, or when your carrier and outbound path are not settled. Ignore the release for text-only work and for voice experiences that already meet their cost and completion targets.
For more plain-English breakdowns of changes that move the operating math, join the newsletter.
- Last Updated
- Sep 14, 2026
- Category
- Explained
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

ChatGPT Appshots Cut Context Copying on Windows
Use ChatGPT Appshots on Windows to share an app window, reduce context copying, and check what text and images enter the chat.Sep 14, 2026Explained
Vercel FastAPI Cuts Function Use for Static Files
Vercel now serves eligible FastAPI assets from its CDN. See which requests stop using Functions and which protected paths still need them.Sep 13, 2026Explained
OpenAI API Key Expiry Needs a Rotation Plan
OpenAI now lets teams expire project API keys. Plan replacement and verification before scheduled agents lose access.Sep 13, 2026Explained
Vercel Connect Gives Shared Credentials a Clear Owner
Vercel Connect lets Pro and Enterprise teams restrict connector management. See how to assign owners and keep agent setup moving.Sep 13, 2026Explained
Cloudflare AI Search Can Index R2 Files Without Renaming
Cloudflare AI Search now indexes extensionless R2 files with valid Content-Type metadata. See which ingestion steps you can remove.Sep 12, 2026Explained
Vercel Sandbox Gives Larger Agent Jobs More Disk Room
See which repository, build, and data jobs fit Vercel Sandbox’s larger disk, plus what to measure before retrying a storage-heavy agent run.Sep 12, 2026Explained
Cloudflare Workflows: Budget for Shorter Run History
New Paid Workflows keep completed and errored state for seven days by default. Set retention before old failures disappear.Sep 11, 2026Explained