How Much Does an AI Agent Cost? Three Monthly Bills, Explained
Compare packaged agents, no-code builders and model APIs, with current maker prices and three worked budgets for 1,000 support emails a month.
For 1,000 support emails a month, the worked software budgets below are $82 for a packaged agent, $25.50 a month equivalent for an annually billed hosted builder, and $10.50 for your own API workflow. Each still needs human review, an inbox, and somebody responsible when it fails. The useful number is the monthly cost of an accepted answer.
There are three ways to pay for an AI agent
An AI agent uses a model to work through a job and take actions in your tools. For support, that might mean reading an email, finding the relevant policy and preparing a reply. Buying the model alone doesn't buy the inbox connection, the approval process or the finished support service.
Your bill depends on how much of that system you buy:
- A packaged agent: pay for a ready-made assistant, usually through a subscription or seat. A seat is a paid user account. Usage allowances can sit underneath that subscription.
- A no-code builder: connect the steps yourself and pay for credits, tasks or workflow executions. An execution is one complete run; a credit is the vendor's unit for metered work.
- Your own API workflow: your software calls a model through an API, the connection programs use to request work. You pay for tokens, the pieces of text the model reads and generates, plus hosting and any paid tools.
These are three ways to buy the same job, with different responsibilities attached. A founder can buy inbox drafts. An operations manager can assemble the workflow. A backend team can own the software that runs it.
The prices here were checked on the makers' pages on October 7, 2026. Dollar amounts are USD. Annual rates are marked as annual, and the worked totals are forecasts from stated assumptions, not performance tests. Record setup hours separately from the recurring bill.
Current maker prices, with the billing unit attached
The model rows use ordinary rates without caching, batch discounts or speed premiums. Different models can produce different token counts and different-quality answers from the same email. A cheaper rate earns its place only when the replies meet your support standard.
The other rows need the same care. Lindy's entry fee isn't a promise of 1,000 replies: drafting sits inside a broad 2 to 250-credit everyday-work range, and sending an email requires approval. Adding active users adds paid seats. Lindy's usage and approval rules.
Gumloop's credits cover more than text. Its current usage-based rules value a credit at $0.005, charge at least 1 credit per successful connector call, and charge 5 credits per active session-minute, before the ordinary 8% orchestration fee. Gumloop's complete credit meter.
Bringing your own model key leaves tool and compute charges in place and changes that agent fee to 16% under the current usage-based policy; older accounts can have older rules. That fee uses what the full run would have cost, including the model usage moved to your provider. Don't calculate it on the remaining tool charges alone.
The same job: answer 1,000 support emails a month
Let's make the job concrete. A small business receives 1,000 separate support emails that can be answered from its existing policy. The workflow prepares replies, and a person reviews and sends the accepted answers.
Allow 100 additional draft attempts, giving 1,100 attempts in total. That's a planning allowance of 10%, not a claim about any product's retry rate. The examples include no attachments, internet searches or paid enrichment, and keep the existing inbox outside the new software subtotal.
The builder and API forecasts assume 3,000 input tokens and 400 billed output tokens per full attempt. Those counts cover a single model call; a workflow that makes several calls needs their combined usage. The packaged service sets its own internal model usage, so its published task meter is what matters.
Way 1: Marblism costs $82/month for the native drafting job
A SaaS founder using Marblism's Eva pays from a shared pool of metered hours. These are fixed task values, not a stopwatch measuring how long the AI runs: sorting a new email uses 20 seconds, and a reply draft uses 5 minutes. Marblism's task values and capacity tiers.
For this job:
- Sort 1,000 new emails: 1,000 × 20 seconds = 5.56 hours.
- Request 1,100 reply drafts, including the extra attempts: 1,100 × 5 minutes = 91.67 hours.
- Total metered work: 97.22 hours.
That fits the 100-hour plan at $82 on monthly billing. The base 50-hour plan at $44 doesn't. On the yearly option, the 100-hour tier is $45/month, with annual billing attached. The whole account's other AI work draws from that same pool.
Eva prepares drafts in your inbox; a human reviews and clicks send. This budget therefore buys assisted support replies, with the approval work still yours. How Eva handles replies.
There's a capacity trap here too. Marblism separately meters an app integration action or automation run at 25 seconds. If your setup adds one such action for every attempt, that's another 7.64 hours, taking the total to 104.86 hours. You'd need the 150-hour tier at $120/month. The $82 estimate covers native sorting and drafting only; check the usage breakdown before adding other actions.
Way 2: n8n plus Claude costs $25.50/month equivalent
An ecommerce operations manager can connect incoming support mail, the relevant policy and a model call, then save a draft for review. n8n's Gmail integration supports reading messages and creating drafts, and its Anthropic integration supports your own API key. Gmail operations, Anthropic credentials.
Assume the configuration creates one complete workflow execution per attempt. 1,100 executions fit inside Starter's 2,500-execution allowance. Steps inside a run don't each become another execution, but extra triggered runs still need to fit your quota. n8n's execution definition and plan.
With your own Anthropic key, the model bill is separate:
1,100 × 3,000 = 3.3 million input tokens.
1,100 × 400 = 0.44 million output tokens.
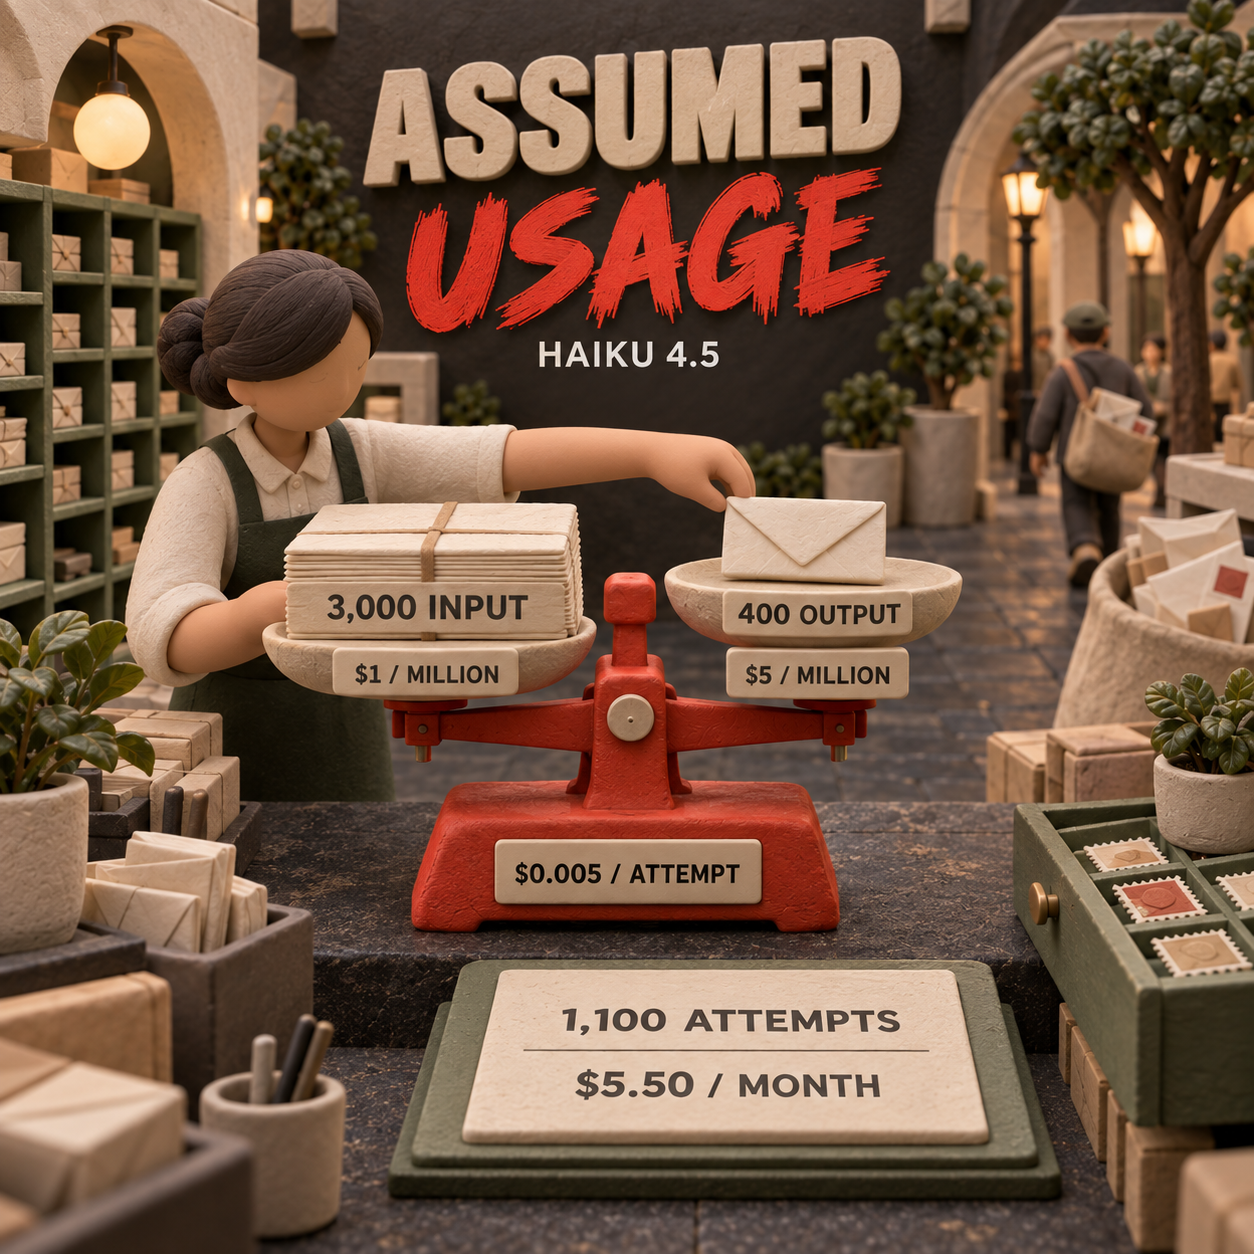
At Haiku's verified rates, 3.3 × $1 + 0.44 × $5 = $5.50. Add the $20/month annual-plan equivalent and the software budget is $25.50/month equivalent. n8n hosts Starter, so this example adds no separate hosting subscription.
Also keep n8n's two credit balances straight. Assistant credits pay for help building and troubleshooting workflows. Gateway credits pay for models called while workflows run. This example uses your own Anthropic key instead of Gateway credits. An Assistant allowance doesn't cover that model bill. The two credit systems.
Way 3: your Claude API workflow plus hosting costs $10.50/month
A backend team can run the same bounded workflow in its own application: accept the email, supply the policy, request a draft and save it for human review. At the same assumed token counts, Haiku still costs $5.50/month.
For a concrete hosting line, Cloudflare Workers Paid starts at $5 per account per month, including 10 million requests and 30 million CPU milliseconds. The example assumes the application and its small data store stay within the included allowances. Workers and included data-service pricing.
The software subtotal is $5.50 + $5 = $10.50/month. That assumes an existing inbox, no optional paid tools, and no other work consuming the account's allowance. Workers also has a Free plan; whether its limits fit your implementation needs a separate check.
Holding the token counts constant, Sonnet would cost $11 in tokens, or $16 with that hosting line. GPT-6 Luna would cost $0.55 in tokens, or $5.55 with hosting. Those are rate comparisons, not evidence that all three models handle your emails equally well.
The low API subtotal comes with ownership: your team maintains the inbox connection, draft storage, error handling and model behavior. The Claude API pricing guide goes deeper on model rates, caching and batch processing once you've measured your workload.
How to estimate tokens for one task
Start with everything the model receives, not just the customer's email. Instructions, earlier messages, policy passages, tool descriptions and tool results can all contribute input tokens. Each later model call can process some of that material again. Claude's tool-use token accounting.
For an initial spreadsheet, suppose the instructions use 800 tokens, the email and thread use 400, and the relevant policy uses 1,800. That gives 3,000 input tokens. Assume 400 billed output tokens for the draft. These are planning inputs to replace with measurements, not typical counts promised by a maker.
Count the full input for your chosen model
Send the complete request to the model's token-counting endpoint. Claude's counter is free and model-specific, but gives an estimate; requests using most hosted tools or external tool connections need actual response usage instead. A word-count shortcut can't establish the invoice. Claude token counting.
Measure the completed task
Run representative emails through your real configuration. Record billed input and output across every model call, including extra drafts and retries. Record cache usage separately if you enable it. In a credit builder, use its full task breakdown: Gumloop's chat-header credit count opens the details drawer. Gumloop's cost breakdown.
Multiply attempts, then add the fixed bill
Cost per attempt = (input tokens × input rate + output tokens × output rate) ÷ 1,000,000. Monthly token cost = that cost × monthly attempts. Then add the platform or hosting fee and separately metered tools.
For Haiku, (3,000 × $1 + 400 × $5) ÷ 1,000,000 = $0.005 per attempt. At 1,100 attempts, that's the $5.50 used above. If a task needs several calls, sum their costs before multiplying by monthly jobs; don't price the final draft alone.
The costs people miss
Human review and corrections. At an assumed 30 seconds per accepted email, reviewing 1,000 replies takes 500 minutes, or 8.33 hours. At a minute each, it's 16.67 hours. Multiply measured review, correction and handoff hours by your own loaded hourly cost, including employment overhead. Compare that with the time the same queue used to take.
Retries and extra decisions. The examples reserve 100 additional attempts. Your agent might also classify the request, retrieve information and check its draft through separate model calls. Count those calls and failed work in the monthly bill, even when you count only the accepted answer as the result.
Tool calls. A low token bill doesn't include every tool. Claude web search costs $10 per 1,000 searches, plus tokens for the results. One search per attempt in this example would add $11 in search fees, and more input tokens. A support agent answering from your own policy might need none. Claude search pricing.
Data and other APIs. Check the inbox, helpdesk, CRM, database, document storage and enrichment services the workflow uses. An included connector gives you a connection; it doesn't automatically pay the connected service's subscription or usage bill. Keep existing costs and new costs visible so you can calculate both the total operating budget and the extra spend this agent creates.
Maintenance and capacity. Somebody still fixes broken credentials, stale policy documents and changed behavior. Track that person's time. Subscription pools also have limits: other work can consume the same hours or credits and force you into a larger tier.
For helpdesk agents billed by completed resolutions, the customer-service own-versus-rent guide covers that separate buying decision. Keep its project economics separate from the recurring software forecast here.
What to measure in the first 30 days
- Results: incoming emails, accepted replies, reopened issues and cases handed to a person.
- Every meter: paid users, hours, credits, executions, input/output tokens and billable tool calls.
- Extra work: attempts per accepted reply, corrections and repeated runs.
- Human time: review, handoffs and maintenance, compared with the previous workflow.
- Other fees: hosting, storage, connected APIs and the next capacity tier.
- Cost per accepted reply: all attributable software, tool and human costs divided by accepted replies. Track resolution cost separately if you measure issues closed.
Choose the bill you can operate
A SaaS founder who wants inbox drafts this week can start with a packaged assistant. Check the allowance against the whole queue and assign the reviewer before buying. The benefit is a ready-made working surface; the number to watch is accepted replies per paid month.
An ecommerce operations manager who needs to combine email, policies and order data can use a builder. Pilot the full workflow and read its execution or credit breakdown. Add paid order-data lookups before comparing its bill with a simpler drafting service.
A backend lead with someone available to maintain the workflow can use the API route. Start with a bounded support job and evaluate the lowest-cost model that meets your reply standard. The token savings only help if ongoing engineering and review time fit the budget.
The same method travels. A sales lead should count every follow-up message and enrichment action, not just leads contacted. A finance operator should count each scheduled report's data fetches, model calls and review, then compare the accepted report with the manual time it replaces.
Wait on a broad autonomous rollout if you can't yet say what a correct result looks like or who handles the exceptions. If your existing rule-based workflow already completes the job reliably, a model adds a new bill without an established payoff.
Get more practical tool and budget breakdowns in the newsletter.
- Last Updated
- Oct 7, 2026
- Category
- Explained
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Grok Voice Transcribe 2.0 Keeps Batch Audio at $0.10/Hour
Grok Voice Transcribe 2.0 keeps batch and streaming rates unchanged. Check the default-model transition and test transcript quality before switching.Sep 20, 2026Explained
Cloudflare Lets You Debug a Failed Browser Job Before Rerunning
Cloudflare Browser Run now records more evidence for debugging. Learn what to inspect before rerunning a broken browser job.Sep 19, 2026Explained
v0 Can Now Reuse Your Private Component Library
v0 can now install private npm packages. See how to reuse your team's components and check the work still needed before shipping.Sep 19, 2026Explained
Claude Code Cuts Auto Mode Classifier Charges
Claude Code 2.1.278 removes classifier charges for eligible sessions. Check /status and gateway fallback before changing your agent budget.Sep 19, 2026Explained
Vercel Lets You Pay for Faster Builds One Deploy at a Time
Use Vercel Turbo for an urgent deployment while keeping routine build defaults. Compare the extra build cost with the time saved.Sep 18, 2026Explained
ChatGPT for Word Cuts Document Copying Between Apps
Draft and revise inside Word with ChatGPT. Check add-in access, shared usage limits and a practical document-editing workflow.Sep 18, 2026Explained
Antigravity Local Jobs Need an October 5 Migration
Keep Antigravity jobs running after October 5. Learn which integrations need new tool adapters and which only need the new agent ID.Sep 18, 2026Explained