How to Use GPT-6 Prompt Caching
Set up GPT-6 prompt caching, diagnose misses, and measure cache reads, writes and cost in a repeatable agent workflow.



A GPT-6 agent gets cheaper when its repeated instructions, tools, and context stay exactly the same at the front of every request. In a live GPT-6 Sol run, an exact repeat reused 1,980 cached tokens and cost $0.000452. Changing one tool name wrote the prefix again and cost $0.0050085. The September 22 dashboard and diagnostics make that difference visible before it becomes a production bill.
The Rule: Stable First, Changing Last
Prompt caching saves the model's processed state for an unchanged prefix, the content at the beginning of a request. Think of it as leaving a workshop set up overnight. The policy manual, tool rack, and half-built assembly stay in place, so the next shift starts from that point instead of rebuilding the workshop.
OpenAI stores key-value tensors, the model's working state, rather than a copy of your prompt. The cache covers the full rendered context: OpenAI instructions, your developer messages, tool definitions, and the conversation history. A later request can reuse that work only until the first meaningful difference in the rendered prefix.
That makes request order a cost decision. Put the stable policy, reference material, examples, and tool definitions first. Put timestamps, request IDs, customer details, and the current task later. Editing an early line can invalidate everything after it.
Prompt caching is already on for supported models. On GPT-5.6 and later, a prefix becomes eligible at 1,024 visible input tokens. The first eligible request writes the prefix at 1.25 times the ordinary input rate. A matching request reads it at 0.1 times the ordinary rate. The entry stays eligible for at least 30 minutes after its latest write or reuse.
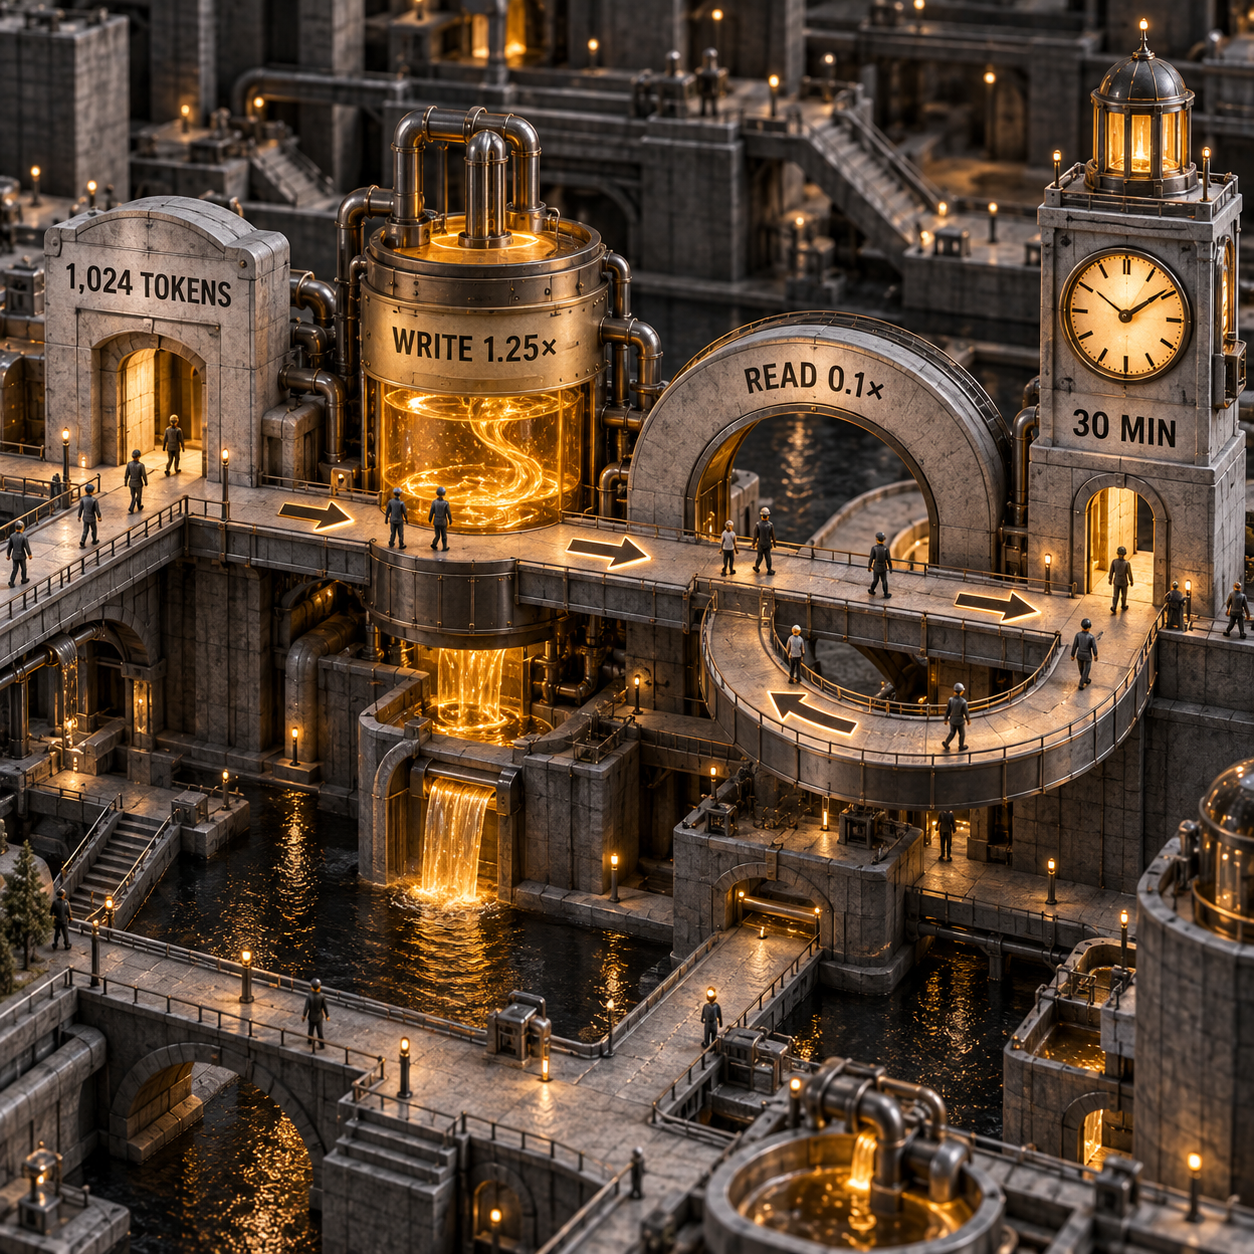
This is prefix reuse, not semantic similarity. Two policies that mean the same thing but differ near the beginning are different cache inputs. The same is true when a tool name, description, JSON schema, order, model, output format, reasoning setting, or verbosity changes.
What Changed on September 22
The new operator layer matters more than the cache itself. OpenAI's September 22 release added a Prompt Caching Dashboard, request comparison diagnostics, and a cache-preserving way to change reasoning effort during a GPT-6 conversation. OpenAI also says the GPT-6 family improves default hit rates.
Do not confuse those additions with mechanics that also apply to GPT-5.6. The current prompt caching guide applies the 1,024-token minimum, 1.25× write rate, 0.1× read rate, implicit and explicit breakpoints, and 30-minute TTL to GPT-5.6 and later.
The existing GPT-6 Sol versus Luna comparison is the model-choice decision. Caching comes after that choice. A cheaper model with stable prefixes and an expensive model with stable prefixes keep the same relative model tradeoff.
Start With Automatic Caching
Automatic caching is the correct first setup because it gives you a clean baseline with almost no prompt surgery. Send the real request twice within the active window, keep every cache-sensitive field fixed, and inspect the second response.
The two fields that settle the billing question are usage.input_tokens_details.cached_tokens and cache_write_tokens. A large cached_tokens count means the request reused processed input. A large cache_write_tokens count means the request paid to create fresh cache state. Ordinary input tokens are total input minus those two counts.
The new diagnostic flow adds cause to those counts:
- Save a recent completed response ID from the same organization.
- Put it in
prompt_cache_options.comparison_response_idon the current request. - Read
prompt_cache_diagnosticson the response. - Use the usage fields, not the diagnostic estimates, for billing.
The direct Responses API can report cache_hit, cache_miss, comparison_response_not_found, or unavailable. A changed tool definition is classified as tools_changed when the diagnostic system identifies it. Diagnostics are best effort and report the first classified cause, so fix that cause and compare again.
Here is a compact direct-API test script. The policy file needs enough useful stable content to clear the 1,024-token minimum.
from pathlib import Path
from openai import OpenAI

client = OpenAI()
policy = Path("support-policy.txt").read_text()
tool = {
    "type": "function",
    "name": "lookup_order",
    "description": "Look up a synthetic order by its test identifier.",
    "parameters": {
        "type": "object",
        "properties": {"order_id": {"type": "string"}},
        "required": ["order_id"],
        "additionalProperties": False,
    },
    "strict": True,
}

def run(tools, comparison_id=None):
    options = {"mode": "implicit", "ttl": "30m"}
    if comparison_id:
        options["comparison_response_id"] = comparison_id
    return client.responses.create(
        model="gpt-6-sol",
        reasoning={"effort": "low"},
        instructions=policy,
        input="Reply with exactly OK.",
        tools=tools,
        prompt_cache_options=options,
    )

baseline = run([tool])
hit = run([tool], baseline.id)
broken = run([{**tool, "name": "lookup_shipment"}], baseline.id)
print(hit.prompt_cache_diagnostics, hit.usage.input_tokens_details)
print(broken.prompt_cache_diagnostics, broken.usage.input_tokens_details)
Use a recent baseline. Diagnostic records expire after a short period, and the comparison ID requests an explanation only. It does not load the earlier conversation or create a cache hit by itself.
A Deliberately Broken Cache Hit
The live test used GPT-6 Sol, a synthetic 1,635-word support policy, one function tool, and the short task Reply with exactly OK. The model returned OK on every request. Only the cache-sensitive structure changed.
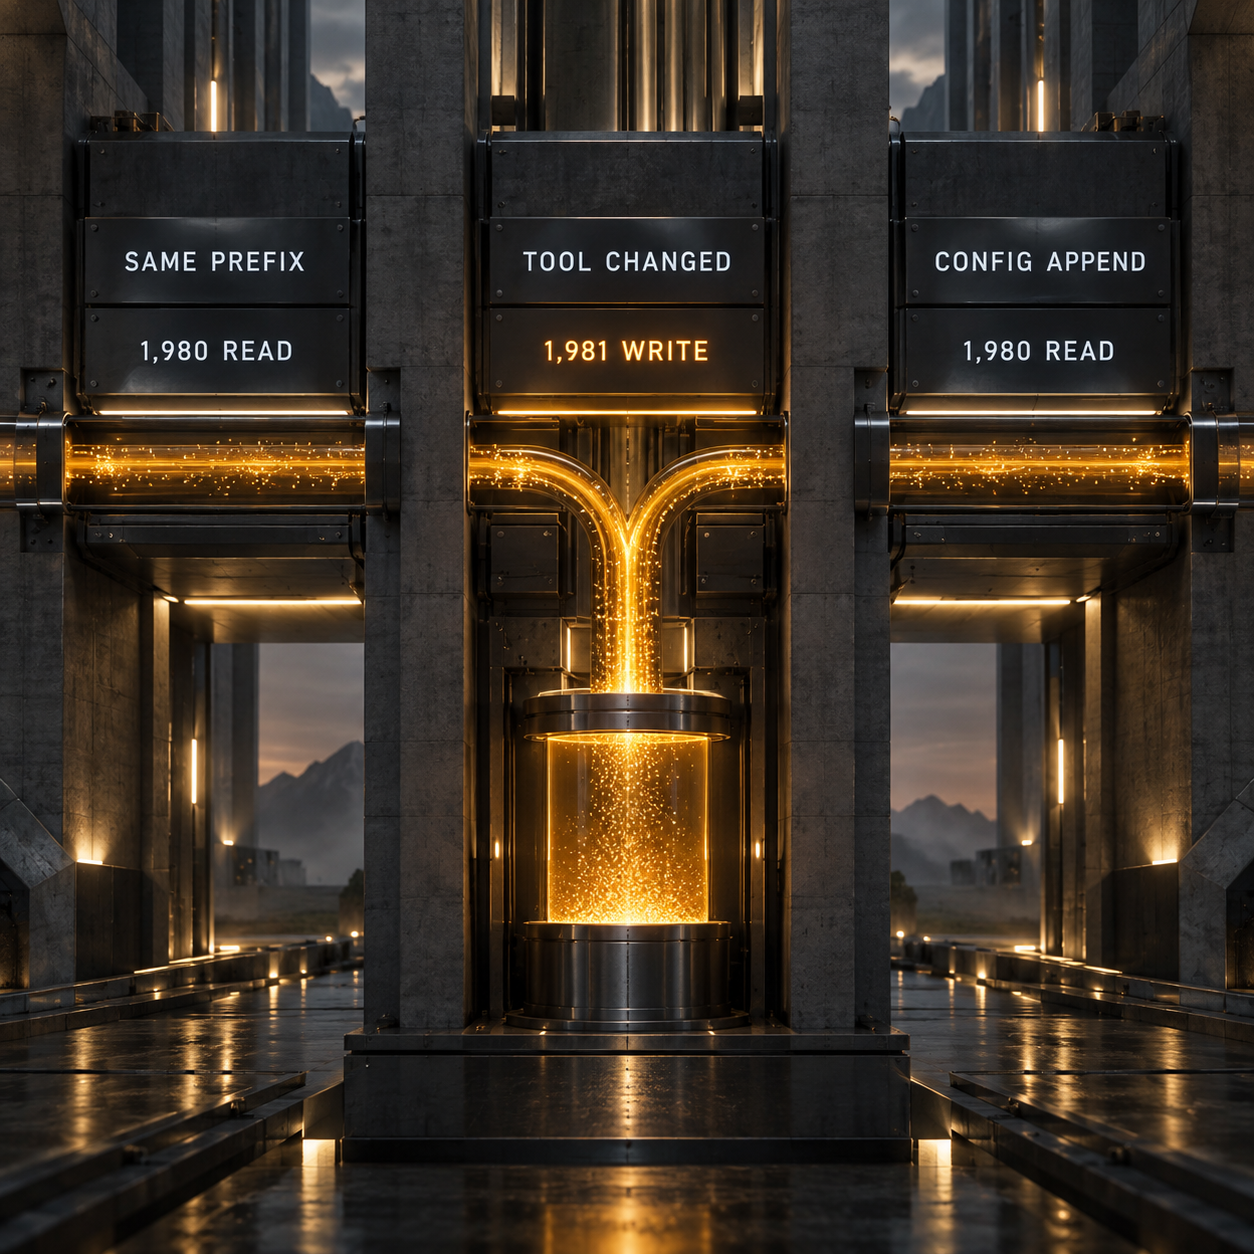
The cost uses current GPT-6 Sol Standard short-context rates: $2 per million ordinary input tokens, $0.20 per million cached input tokens, $2.50 per million cache-write tokens, and $10 per million output tokens. Each response used five output tokens.
The exact repeat cost 91.0% less than the baseline response after output was included. For a ten-step agent with this same token shape, one write plus nine reads costs about $0.009074. Ten fresh writes cost about $0.05006. Keeping the prefix stable cuts completed-step cost by 81.9% in this synthetic workload.
That is the decision metric. A cache-hit percentage can look healthy while a few expensive long-context turns keep rewriting. Sum actual token classes and cost across completed tasks, then compare accepted outcomes, retries, and tool charges.
The elapsed times do not support a latency claim. The four calls ranged from 892 to 1,254 milliseconds, and the cached repeat was not the fastest call. Network and routing noise dominate a sample this small. Cost changed clearly; latency needs repeated measurements and time-to-first-token data.
There was one useful integration failure. The Vercel AI Gateway forwarded prompt_cache_options, returned the OpenAI provider response ID, and reported cache reads and writes, but its normalized response omitted prompt_cache_diagnostics. The deliberate miss was still obvious from zero cached tokens and 1,981 write tokens. If an SDK or gateway sits between your app and OpenAI, test that it exposes the new diagnostic field before depending on it in production.
Fix the Prefix Before Adding Breakpoints
Most misses come from ordinary request construction. Fix those first:
- Keep tool names, descriptions, schemas, configuration, and order unchanged. Use
tool_choice: "none"when no tool should run, orallowed_toolswhen only a subset should be callable, while retaining the full supplied tool list. - Keep the model, service tier, text schema, request-level reasoning effort, and verbosity stable for requests expected to share a prefix.
- Move timestamps, user IDs, trace IDs, and per-task data after stable instructions and references.
- Append messages and tool results. Rewriting or summarizing earlier conversation content changes the prefix.
- Compare against the intended baseline after each fix. Diagnostics report only the first classified difference.
For GPT-6, change effort with a conversation item instead of changing the top-level setting. The request below stays at top-level low, then applies high to the follow-up.
follow_up = client.responses.create(
    model="gpt-6-sol",
    previous_response_id=baseline.id,
    reasoning={"effort": "low"},
    tools=[tool],
    input=[
        {"type": "configuration_update", "reasoning": {"effort": "high"}},
        {"role": "user", "content": "Analyze the difficult exception."},
    ],
    prompt_cache_options={"comparison_response_id": baseline.id},
)
Configuration updates work for the GPT-6 family in standard, single-agent mode and change only reasoning effort. Do not place two updates next to each other. They also cannot be combined with automatic compaction or automatic truncation.
The Responses API migration guide covers the wider state decision. For caching, the key point is simpler: preserve the old items in place and append the change.
Add Explicit Breakpoints Only Where They Pay
An explicit breakpoint is useful when the request has a stable core followed by a suffix that changes too often to deserve a cache write. Put the stable instructions in an input_text block inside a developer message, add prompt_cache_breakpoint: {"mode":"explicit"} to that block, and set prompt_cache_options.mode to explicit.
Top-level instructions cannot hold an explicit breakpoint. In explicit mode, a request with no explicit marker performs no cache write. That can be the right answer for a one-off prompt, because a cache write costs 25% more than ordinary input and pays back only when a later request reads it.
A request can create up to four cache writes. Do not spend those slots on every message. Choose boundaries that reflect how the application actually branches: a shared company policy, a workspace context, a conversation fork, and perhaps a stable evaluation rubric.
Prewarming is a separate latency tool. A request with prompt_cache_options.prewarm: true prepares known context without generating output, then the user request sends the same prefix. The prewarm call is billed at the normal cache-write rate, so use it for predictable traffic and measure time to first token.
Seven Workflows That Profit Most
1. Coding-agent platforms
A coding agent repeatedly sends repository maps, developer rules, tool schemas, and earlier turns. Keep those blocks stable, append file changes and tool results, and fork background tasks from the shared history. The payoff is lower context cost across long sessions. One renamed tool can erase the saving, so this group benefits most from a cache regression test in CI.
2. Customer-support agents
A support team may have a long policy manual, product catalog rules, and fixed escalation tools. Put that shared material first and add the current ticket later. The measured synthetic policy is this pattern. At the same request shape, ten completed short responses fell from about $0.05006 in repeated writes to $0.009074 with one write and nine reads.
3. Evaluation and quality teams
An evaluator can reuse a grading rubric, labeled examples, output schema, and tool definitions while changing only the candidate interaction at the end. Explicit mode can stop the changing candidate from receiving a write charge. This turns the cache into part of evaluation unit economics rather than an invisible platform detail.
4. Research and diligence agents
A research workflow can keep a vetted source pack and analysis rules stable while appending new questions. Forked summaries, contradiction checks, and memo sections can share the same prefix. The benefit grows when several workers start from the same evidence and produce different deliverables.
5. Contract and compliance review
A legal operations team can place its clause library, risk rubric, approved language, and review tools before the contract under review. Each new document becomes the changing suffix. The cache does not make the judgment safer, but it can reduce the repeated cost of loading the same controls.
6. Multi-agent operations
An orchestrator can preserve a common plan, workspace state, and tool history before branching into specialist agents. Cache reuse makes forks less expensive when the shared prefix is large. Keep tool definitions stable, and add newly discovered tools through append-only history when the application supports it.
7. Predictable interactive launches
A product with known reference material can prewarm during startup before the first user request. This moves prefix processing out of the user's wait. It is useful only when traffic arrives soon enough to reuse the entry and the latency gain survives a proper repeated test.
Three Products Worth Building
1. Cache Regression CI, the strongest opportunity
Build a test gate that replays representative agent requests, compares each response with a saved baseline, and fails a pull request when cached tokens fall or cache writes jump. Agent-platform teams pay because a harmless tool-schema edit can turn every production turn into a fresh write.
The demand is small enough to serve and large enough to notice: prompt caching draws about 1,300 US searches a month, openai prompt caching draws 320, and the exact GPT-6 setup query returned only two independent written guides. Helicone already charges $79 a month for a Pro plan with alerts and reports, which shows that teams budget for LLM monitoring.
The smallest sellable version is a CLI, a GitHub check, and one report with baseline response ID, diagnostic reason, cached tokens, write tokens, elapsed time, and calculated cost. The catch is OpenAI's own dashboard and diagnostics. The product needs a deployment gate, cross-provider coverage, or code-level blame to earn its seat.
2. A Cache-Aware Cost Allocator
Build a per-customer cost ledger for AI products that separates ordinary input, cache reads, cache writes, output, and tool fees. Finance and platform teams pay when a shared agent prefix serves many customers but the product still needs defensible workspace-level margins.
About 50 US searches a month target openai api prompt caching, and the live People Also Ask set includes “Should I use prompt caching?” and “When not to use caching?” Langfuse prices production cloud plans at $29 and $199 a month, another sign that token and cost tracking already has a software budget.
The MVP is an SDK wrapper, a pricing table, tenant tags, and a completed-task view. The honest catch is attribution. GPT-5.6 and later do not need prompt_cache_key for routing, and separate keys exist mainly for accounting. Poor tenant boundaries can create confusing bills or privacy concerns.
3. An Adapter Conformance Monitor
Build a test suite that checks whether an SDK, proxy, or model gateway forwards new Responses fields and returns them intact. It would test comparison_response_id, diagnostic types, cache token details, configuration updates, explicit breakpoints, and provider response IDs after every dependency upgrade.
The demand signal is the learning gap: what is prompt caching gets about 480 US searches a month, how does prompt caching work gets 140, and “How do I turn on prompt caching?” appears in the live People Also Ask results. The first-hand run also exposed a concrete failure, the gateway preserved usage but omitted the diagnostic object.
The MVP is a hosted compatibility matrix plus a command that runs five synthetic requests against a customer's endpoint. The catch is durability. Gateway vendors will add fields, so the product needs continuous protocol testing across providers rather than a one-time GPT-6 checker.
Limits and the Honest Take
Prompt caching is worth designing for when a long prefix repeats. It is a bad target when requests are short, unique, or constantly rewritten near the front.
The 1,024-token floor matters. Padding a tiny prompt merely to qualify can raise cost. Stable useful examples or reference material may justify the extra tokens, but the decision depends on reuse count and quality, not the desire to see a cache hit.
Cache state is also physical. Entries live on individual machines, and traffic above about 15 requests per minute can overflow to other machines. Routing and load can create misses even when application content looks stable. A cache hit is an optimization outcome, not a correctness guarantee.
Cached inputs still count toward tokens-per-minute limits. The cache cannot be cleared manually. Reuse does not change output generation, so identical requests can still produce different answers. For GPT-6 Sol, a request above 272,000 input tokens also moves the full request onto higher long-context rates.
The strongest operating rule is simple: track cost per accepted task, keep the prefix stable, and treat every write spike as an incident worth explaining.
The Monday Move
Pick one production agent endpoint next Monday. Save a representative response ID, replay the same completed task, and record cached tokens, write tokens, elapsed time, output tokens, and total cost. Then change one tool description or name, compare against the same baseline, restore the tool list, and rerun. If the restored request lowers completed-task cost without harming acceptance, add that exact test to CI before changing prompts or adding breakpoints.
Frequently Asked Questions
How do I turn on prompt caching?
You usually do not need to turn it on. Prompt caching is enabled by default for supported OpenAI models. Keep at least 1,024 visible tokens stable at the beginning of a GPT-5.6 or later request, send a matching request within the active window, and inspect cached_tokens. Use prompt_cache_options.mode only when you need deliberate breakpoint control.
What is prompt caching and how does it work?
It saves the model's processed key-value state for an exact prompt prefix. The first eligible request writes that state, and later matching requests can read it instead of processing the same prefix again. New suffix content and output generation still require work.
When not to use caching?
Do not optimize for it when prompts are below the minimum, rarely repeat, change near the beginning, or expire before another request arrives. In explicit mode, leaving out a breakpoint avoids paying the 1.25× write rate for a prefix you do not expect to reuse.
Should I use prompt caching?
Use it when repeated input is a meaningful part of completed-task cost. Measure one write and several reads with your real tools and acceptance checks. A high hit rate is useful only when the total cost per accepted task falls.
What is the best caching strategy?
Start with automatic implicit caching. Put stable content first, append changing content, keep tools and request settings fixed, and diagnose misses. Add explicit breakpoints only around stable blocks that will be reused enough to recover the write cost.
If you want this measurement and regression gate built into your agent stack, AI production systems is the matching place to start.
- Last Updated
- Sep 27, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Copilot Managed Runtime Pricing
Separate Copilot Managed Runtime build costs, runtime credits and Power Apps Premium coverage before budgeting an internal AI app.Sep 26, 2026Build
n8n Agents vs Workflows
Choose between n8n Agents and workflows for support and operations, with execution costs, approvals and the limits of the new preview.Sep 26, 2026Build
Is Jev Router Free
Jev Router's catalog says $0. Check what that covers, the cost of routed model calls and the usage records before budgeting an agent.Sep 26, 2026Build
How to Publish Claude Plugins
Publish a Claude plugin through the new directory portal. Check paid-plan access, choose a bundle or MCP connector, and prepare for review.Sep 26, 2026Build
Is Cloudflare MCP Portals Free
Check Cloudflare MCP Portals' free-plan limits, paid seats and separate model or server costs before connecting your team's agents.Sep 26, 2026Build
How to Use Agentic CUDA Optimizer
Set up the CUDA optimizer, run a bounded kernel experiment, and check correctness, GPU time and model costs before trusting a speedup.Sep 25, 2026Build
Runpod Pricing (2026): Pods or Serverless by Paid Time
Calculate Runpod pricing for Pods, Serverless, storage and production inference, with a dated H100 worksheet and a billable-time break-even.Sep 25, 2026Build