GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.




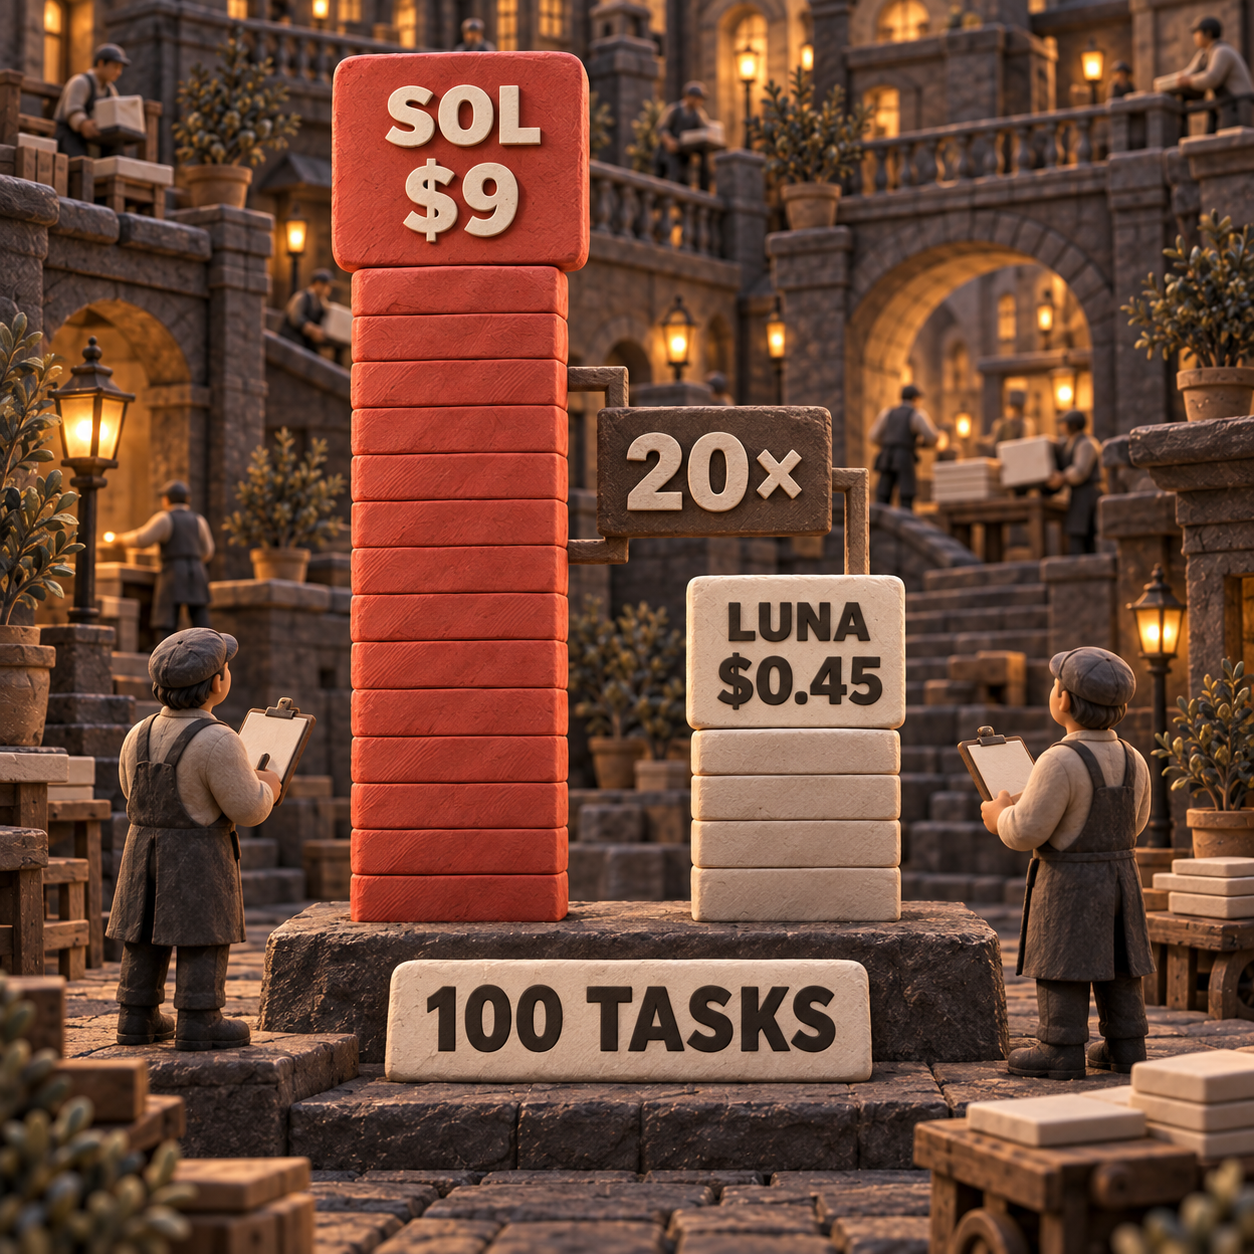
GPT-6 Sol vs Luna is a default-versus-escalation decision: start with Luna. On 100 short-context tasks at 20,000 input and 5,000 output tokens each, Luna costs $0.45 and Sol costs $9; Sol earns the 20× premium only when better acceptance or lower review effort saves more than the extra $8.55.
GPT-6 Sol vs Luna: Pick Luna First, Sol for the Hard Tail
Pick GPT-6 Luna for predictable work you can verify cheaply. Pick GPT-6 Sol for ambiguous coding, long agentic jobs, and decisions where a weak answer creates expensive review or rework. If you cannot name that extra consequence, Luna is the better starting model.
OpenAI positions Sol for complex coding and agentic workflows, while Luna is its efficiency model for focused, high-volume tasks. That distinction matters more than the shared GPT-6 name: the two models expose almost the same operating envelope, but they are priced for different levels of judgment.
Price winner: Luna. The input and output rates are each one twentieth of Sol's. That makes Luna the obvious route for extraction, classification, routine transformations, and code changes guarded by deterministic tests.
Difficult-work winner: Sol. OpenAI gives it the stronger coding result and explicitly positions it for complex agentic work. The case is strongest when the output is hard to verify, a retry blocks other work, or a reviewer must reconstruct the model's reasoning.
GPT-6 Sol vs Luna Price: The 20× Gap Never Closes on Tokens
Luna stays 20× cheaper at every comparable token rate. More volume does not produce a crossover because OpenAI kept the same ratio for input, cached input, cache writes, and output at both short and long context on its live API pricing page.
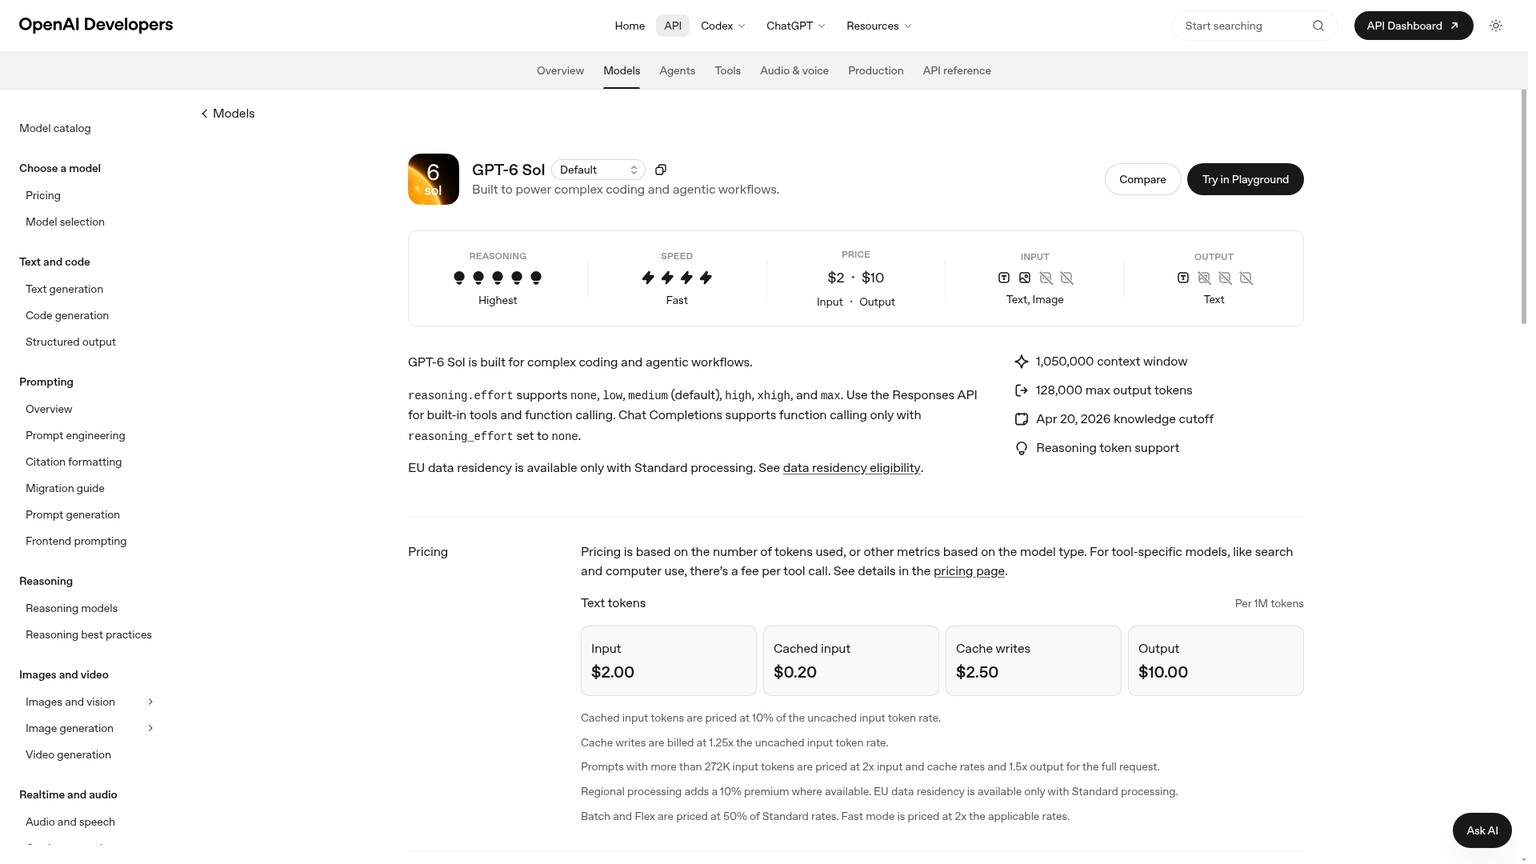
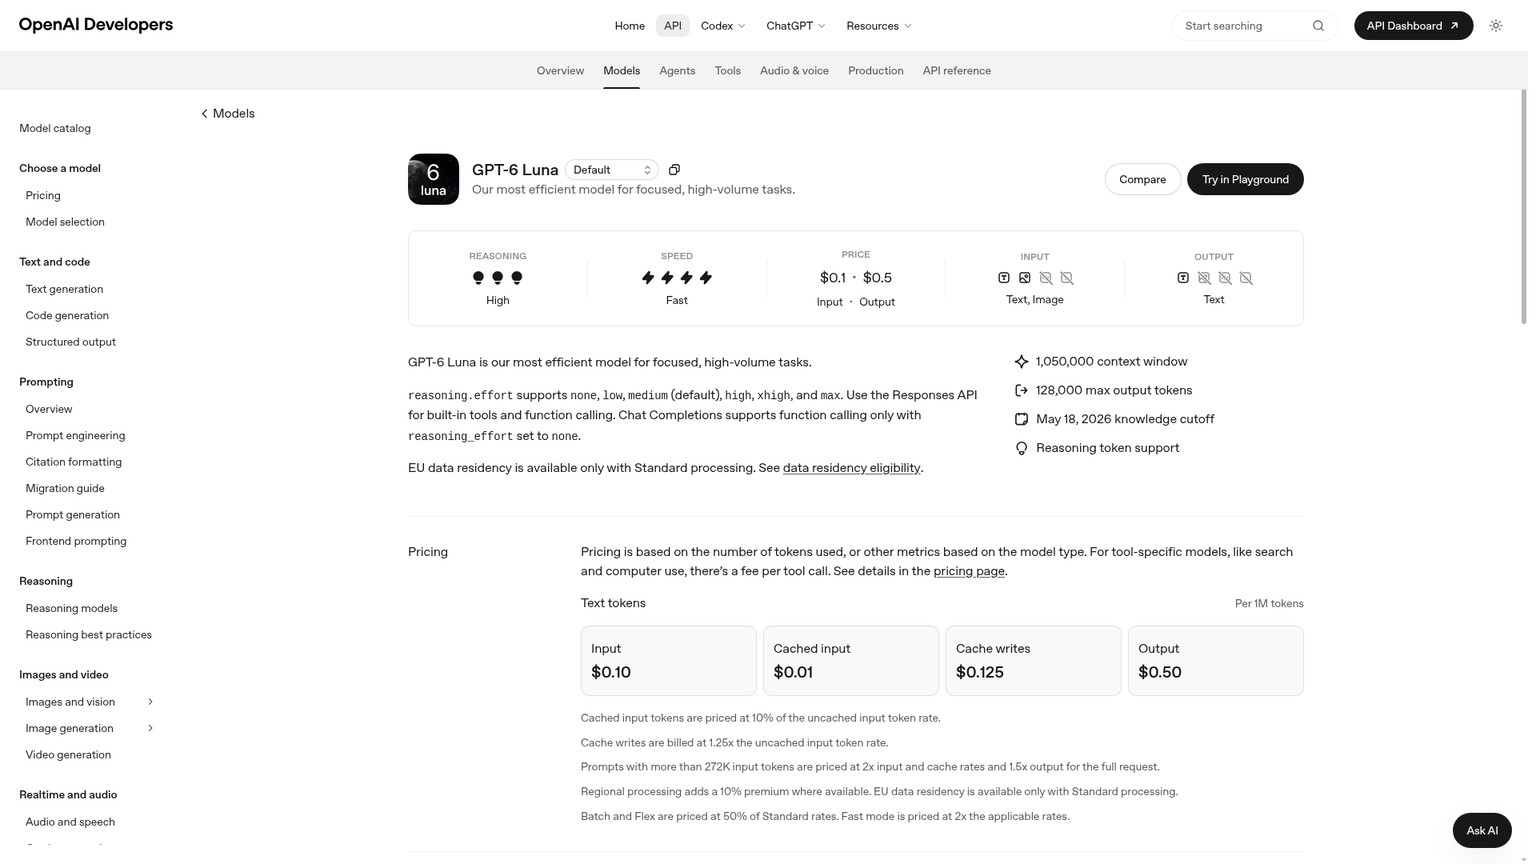
At Standard short-context rates, Sol costs $0.002 per 1K input tokens and $0.010 per 1K output tokens. Luna costs $0.0001 per 1K input tokens and $0.0005 per 1K output tokens.
For the same 20,000-input, 5,000-output task:
- Sol costs $0.0900.
- Luna costs $0.0045.
- Sol adds $0.0855 before tools, retries, cache effects, or changed token use.
Across 100 separate tasks, that becomes $9 for Sol and $0.45 for Luna. The batch saves $8.55 on Luna before any quality difference enters the calculation.
GPT-6 Sol Pricing at Short Context
Sol's price is easy to underestimate when the comparison stops at input. Output is five times the input rate for both models, so a verbose agent or coding loop can make generated tokens the larger part of the bill. In the reference workload, Sol's 500,000 output tokens cost $5, more than its $4 input cost.
Caching reduces both bills without changing the choice. Cached reads cost 10% of uncached input, while cache writes cost 1.25 times uncached input. That is useful for stable system prompts, tool definitions, and reused repository context, but the same 20× Sol-to-Luna ratio remains.
There is no honest seat-month or per-image crossover to calculate here. These are token-priced API models, not different seat plans. Both accept image input and produce text, while image generation is a separate tool with separate charges. Model selection still comes back to accepted text work.
GPT-6 Model Comparison: Same Envelope, Different Judgment
The models share enough infrastructure that feature checklists are a poor selector. Both list a 1,050,000-token context window, a 128,000-token maximum output, text and image input, text output, structured outputs, function calling, streaming, and the same reasoning-effort ladder from none through max.
GPT-6 Sol is the complex-work option. Its live model page lists web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search through the Responses API.
GPT-6 Luna is the efficient option, not a stripped endpoint. Its live model page lists the same tools and controls, so moving routine work down does not require giving up structured output or the agent tool surface.
One API constraint matters during evaluation: at medium reasoning effort, use the Responses API. The model pages say Chat Completions supports function calling only when reasoning effort is none. A comparison that gives one model tools through Responses and the other a reduced Chat Completions path is not controlled.
The knowledge cutoffs also resist a simple hierarchy. Sol lists April 20, 2026, while Luna lists May 18, 2026. Sol's higher capability tier does not mean every dated specification is larger or newer.
GPT-6 Sol vs Luna Review: What the Evidence Supports
Sol has the better launch-day difficult-coding signal, but not enough neutral evidence to justify a blanket upgrade. OpenAI's official developer announcement confirms the release and its lower-price positioning.
In OpenAI's launch evaluation, GPT-6 Sol scored 68.8% on DeepSWE v1.1 at max effort and GPT-6 Luna scored 66.6% at max effort. Sol's lead is 2.2 percentage points.
That comparison is useful but bounded. It is vendor-reported, uses max effort, and measures a specific set of long-horizon software-engineering tasks. It does not tell you that Sol will return 20 times as many accepted outputs on extraction, support triage, policy mapping, or a repository with unusually strong tests.
No independent matched run of this exact model pair supports a neutral quality-per-dollar number yet. The defensible reading is narrower:
- Winner for measured coding ceiling: Sol. It leads the one direct pairwise score OpenAI published.
- Winner for cost-adjusted routine work: Luna. A small quality gap is overwhelmed by a 20× price gap when failures are cheap to detect.
- Unresolved for your application: acceptance rate, latency, retry count, and reviewer time at the effort setting you will deploy.
The earlier GPT-5.6 review explains why model-family labels should become routing rules rather than status rankings. The GPT-6 price cut changes the numbers, not that principle.
GPT-6 Luna Coding: Use Tests as the Gate
Luna wins bounded coding work when the repository can judge the answer. A lint repair, typed extraction, fixture update, or localized bug with a failing test gives a cheaper model a hard signal. If the patch fails, escalation is automatic and the low first-pass cost was not wasted.
Sol wins when the repository cannot express success cleanly. Cross-module migrations, intermittent production failures, unclear requirements, security-sensitive changes, and architecture work force a human to inspect assumptions rather than merely read a test result. The extra $0.0855 on the reference task is trivial if Sol prevents even a small amount of senior review.
This makes the test suite part of the model budget. Better assertions, type checks, linters, and narrow acceptance criteria expand the share of work Luna can own. Paying Sol for every change is often a substitute for building those controls.
For an earlier cross-vendor example of this method, the GPT-5.6 versus Claude Sonnet 5 comparison separates raw model price from the cost of accepted repository work.
GPT-6 Sol or Luna: The Decision Rule
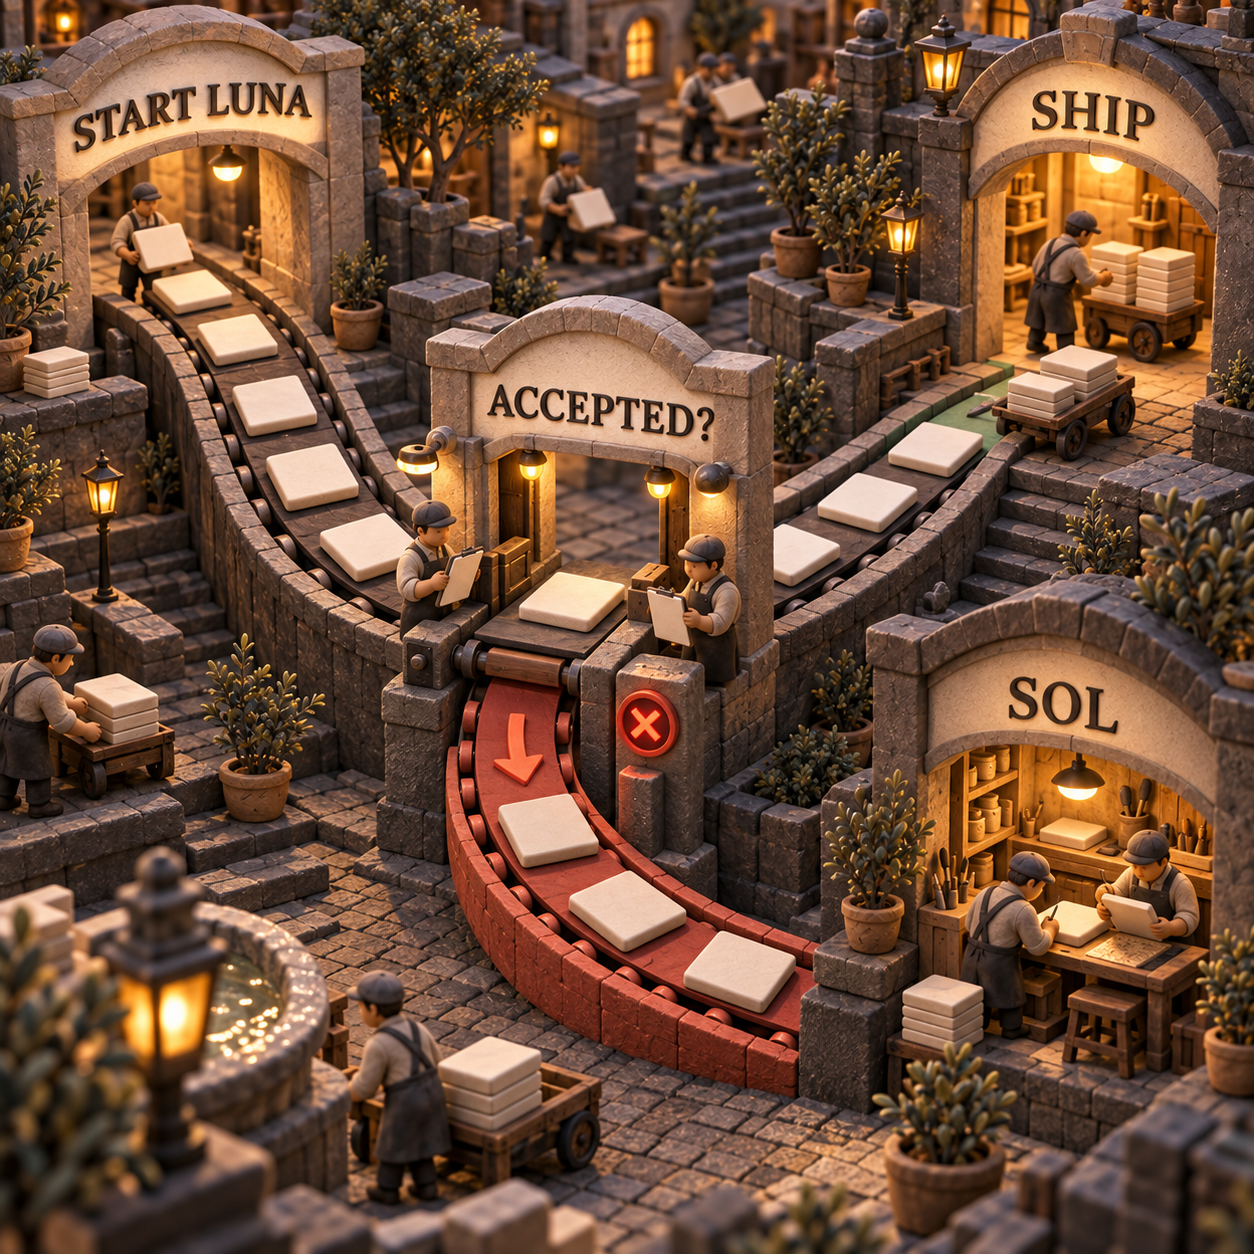
Start on Luna, then promote only the tasks whose failures cost more than the model premium. For the reference workload, the exact promotion rule is:
(Luna failure rate - Sol failure rate) × cost of a failed task > $0.0855
The cost of failure can include a retry, reviewer time, delayed automation, customer impact, or a bad decision. Use your own observed value. Inventing a universal dollar amount would hide the variable that decides the model.
For a funded founder: use Luna for structured research extraction, document comparison, and repeatable operational drafts. Try Sol on investment memos, diligence synthesis, or product decisions only when a rubric shows fewer material corrections.
For a mid-market CTO: put Luna behind ticket triage, log classification, routine patches, and test-backed maintenance. Keep Sol for incident investigation, difficult migrations, agent plans spanning several systems, and work whose mistakes consume senior engineering time.
For a senior operator: route standardized forms, summaries, tagging, and reconciliations to Luna. Escalate ambiguous exceptions, conflicting evidence, and approvals with financial or customer consequences to Sol.
For a solo technical builder: Luna is the economical loop for tasks with a command that can prove success. Sol is the deliberate escalation when the task remains underspecified after one attempt or the repository lacks reliable checks.
Switching from Luna to Sol Is Cheap in Code, Expensive in Validation
The mechanical switch is one model ID, but the production switch is an evaluation. Both models use the same Responses API controls and support the same named tools, so gpt-6-luna can become gpt-6-sol without a provider migration. Output behavior can still change enough to break prompts, schemas, tool choices, and reviewer expectations.
Use an explicit medium-effort comparison because medium is the documented default for both models and a realistic production baseline. Keep the extraction set separate from the repository set so a large easy category cannot conceal failures on the work that motivated Sol.
Freeze the task set and acceptance rubric
Choose representative extraction and repository tasks. Define accepted output before the run: required fields, test command, forbidden changes, review checklist, and what counts as a retry.
Run both exact model IDs at medium effort
Send identical inputs to
gpt-6-lunaandgpt-6-solthrough the Responses API withreasoning.effortset tomedium. Keep system instructions and output schemas identical.Hold tools and cache state constant
Give both runs the same tool definitions, repository snapshot, permissions, and cache conditions. Record fresh input, cached input, cache writes, output tokens, and tool charges separately.
Record outcomes, not impressions
Capture accepted or rejected, retry count, elapsed time, token use, and reviewer minutes. Blind the reviewer to the model name when practical.
Promote only the winning task class
Calculate total cost per accepted result for each task class. Route a class to Sol only when its avoided failure and review cost clears the extra $0.0855 on the reference task, adjusted for that class's token use.
The missing API credential in this run means those paired results are not claimed here. The protocol is the line between a defensible routing policy and a launch-day assumption.
The Monday Move: Price Accepted Work, Not Tokens
Next week, keep Luna as the baseline and sample the hard tail on both models at medium effort. Review the results by task class, not as one blended average. Promote only the class where Sol lowers total cost per accepted output.
If no class clears the threshold, stay on Luna and spend the difference on better tests, retrieval, and review gates. If one class does clear it, route narrowly. The useful system is not Sol everywhere or Luna everywhere; it is Luna until evidence pays for Sol.
For ChatGPT plan access rather than API economics, use the separate guide to whether GPT-6 Luna is free.
Frequently Asked Questions
Is GPT Sol or Luna better?
GPT-6 Luna is better for cheap, focused, high-volume work you can verify. GPT-6 Sol is better for difficult coding and agentic work only when higher acceptance or lower review cost covers its 20× token premium.
What is GPT-5.6 Luna good for?
GPT-5.6 Luna is the previous-generation efficiency model. The GPT-5.6 review covers its routing role; new evaluations should start with GPT-6 Luna at the current $0.10 input and $0.50 output rates per million short-context tokens.
Why is GPT-5.6 Luna so cheap?
It occupied OpenAI's focused, high-volume tier. GPT-6 Luna continues that efficiency role, and OpenAI says improved caching and inference helped cut its launch API rates by 50% from GPT-5.6 Luna's promotional pricing.
Which is better, GPT-5.6 Luna or Terra?
That is a previous-generation choice. Read the full GPT-5.6 model-family comparison for that decision; for a new deployment, compare current GPT-6 Luna and Sol first.
Why pay $20 for ChatGPT?
$20 is a consumer-subscription question, not a GPT-6 API charge. Use the separate GPT-6 Luna access guide to compare plan surfaces, then price API automation independently by tokens and tools.
Why are people leaving ChatGPT?
That broad behavior question does not decide an API route. For production, compare accepted outputs, latency, reviewer time, privacy requirements, and total cost on the workload you own.
Is there an AI better than GPT?
There can be a better model for a specific job, but not a useful universal winner. Define the acceptance rubric first, then compare providers and models on the same tasks, tools, effort, and review process.
Is ChatGPT Pro $200 worth it?
The $200 premise is stale, and a subscription cannot be valued from API rates. Check OpenAI's current plan selector, then judge the bundled usage separately from the Sol-versus-Luna token decision.
Get the AI tools map for business owners
A plain-English map of which models and tools fit which business job, updated as prices and capabilities change. Free to subscribers.
- Last Updated
- Sep 23, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI
Is MiMo V2.6 Free
MiMo V2.6 Flash has a temporary free endpoint. Compare that offer with MIT model downloads, paid API access and desktop plans.Sep 22, 2026AI
Grok 4.7 vs Grok 4.6
Grok 4.7 starts at the same token price as 4.6. Compare access, coding evidence and task costs before moving your workflow.Sep 21, 2026AI
Specification Gaming in Production AI Agents
An AI editor sent 50 of 96 articles off topic. The measured costs, the rules that rewarded drift, and the controls that replaced them.Sep 21, 2026AI
Step 5 Preview Pricing
Compare Step 5 Preview API rates with Step Plan Credits, cached-input discounts, and reasoning costs before choosing your billing route.Sep 21, 2026AI