How to Use Unreal Agent
Run Unreal Agent from Unreal Labs on a bounded repo task. Check Go setup, provider keys, JSONL output, sessions and actual usage.


You can use Unreal Agent to run a repository task from the command line, keep the full session as JSONL, and decide whether its asynchronous tool handling is worth putting inside your own application. This is the new Go agent runtime from Unreal Labs, not an Unreal Engine assistant. Start with one read-only repo summary, record the model, reasoning level, elapsed time, exit status, token usage, and files changed, then compare that evidence with your current agent.
What Unreal Agent actually is
Unreal Agent is the layer between a model and the tools that do work. Think of that layer as a site foreman. The model decides what needs doing, while the runtime dispatches commands, records what happened, and decides when the model should see each result.
The distinctive choice is asynchronous tool execution. When the model calls a tool, the runtime records that the work is in progress and lets it continue in the background. When the tool finishes, the runtime appends the final result to the session and calls the model again. That means a slow setup command does not have to prevent other useful work or a new steering message.
Unreal Labs launched the project on September 22, 2026. The SDK includes a Go library, an installable runner, and a Harbor-compatible benchmark runner. The repository uses the MIT License.
Unreal Labs reports up to 40% lower cost than Codex and up to 20% lower cost than Pi in its production workloads and published agent benchmarks. Treat those as vendor results, not a portable discount. The claimed mechanism is credible enough to test: a smaller prompt footprint, compact tool results, no sub-agents or workflows, and more tool work between model calls. The percentage is not useful until the model, reasoning level, prompt, repository state, and success criteria are matched.
The business math starts with the job, not the benchmark
The runner itself has no per-seat license fee under the MIT License, but operating it is not free. You still pay for model calls, compute, sandboxing, integration, logs, and the engineer who keeps the system reliable.
The budget it can challenge is visible in code-review pricing. Graphite lists Starter at $20 per user per month and Team at $40, billed annually. CodeRabbit lists annual prices of $24, $48, and $72 per developer per month. For a 10-developer team, that published range is $200 to $720 each month.
That does not make Unreal Agent a drop-in replacement for either product. It gives a platform team an open runtime from which to build one narrow internal workflow. The economic test is simple: compare the full monthly cost of the narrow workflow, including model spend and maintenance, with the seat budget or engineering hours it replaces. If you cannot measure completed-task cost, the cost claim is decoration.
How to run one bounded repository task
Use the runner first. The library is for teams that already know which agent behavior belongs inside their application.
1. Put the repository behind a real boundary
-workspace chooses the working directory for the agent and its Bash tool. It is not documented as a security sandbox. Use a disposable checkout or container, remove production credentials, restrict network access, and give the process only the tokens it needs. A prompt saying “do not modify files” is an instruction, not enforcement. If this is new territory, start with the practical options in AI agent code sandboxes.
Check the workspace for a .env file too. The runner loads one from the selected workspace, so a copied repository can still expose credentials you forgot were there.
2. Pin the runner, provider, model, and reasoning level
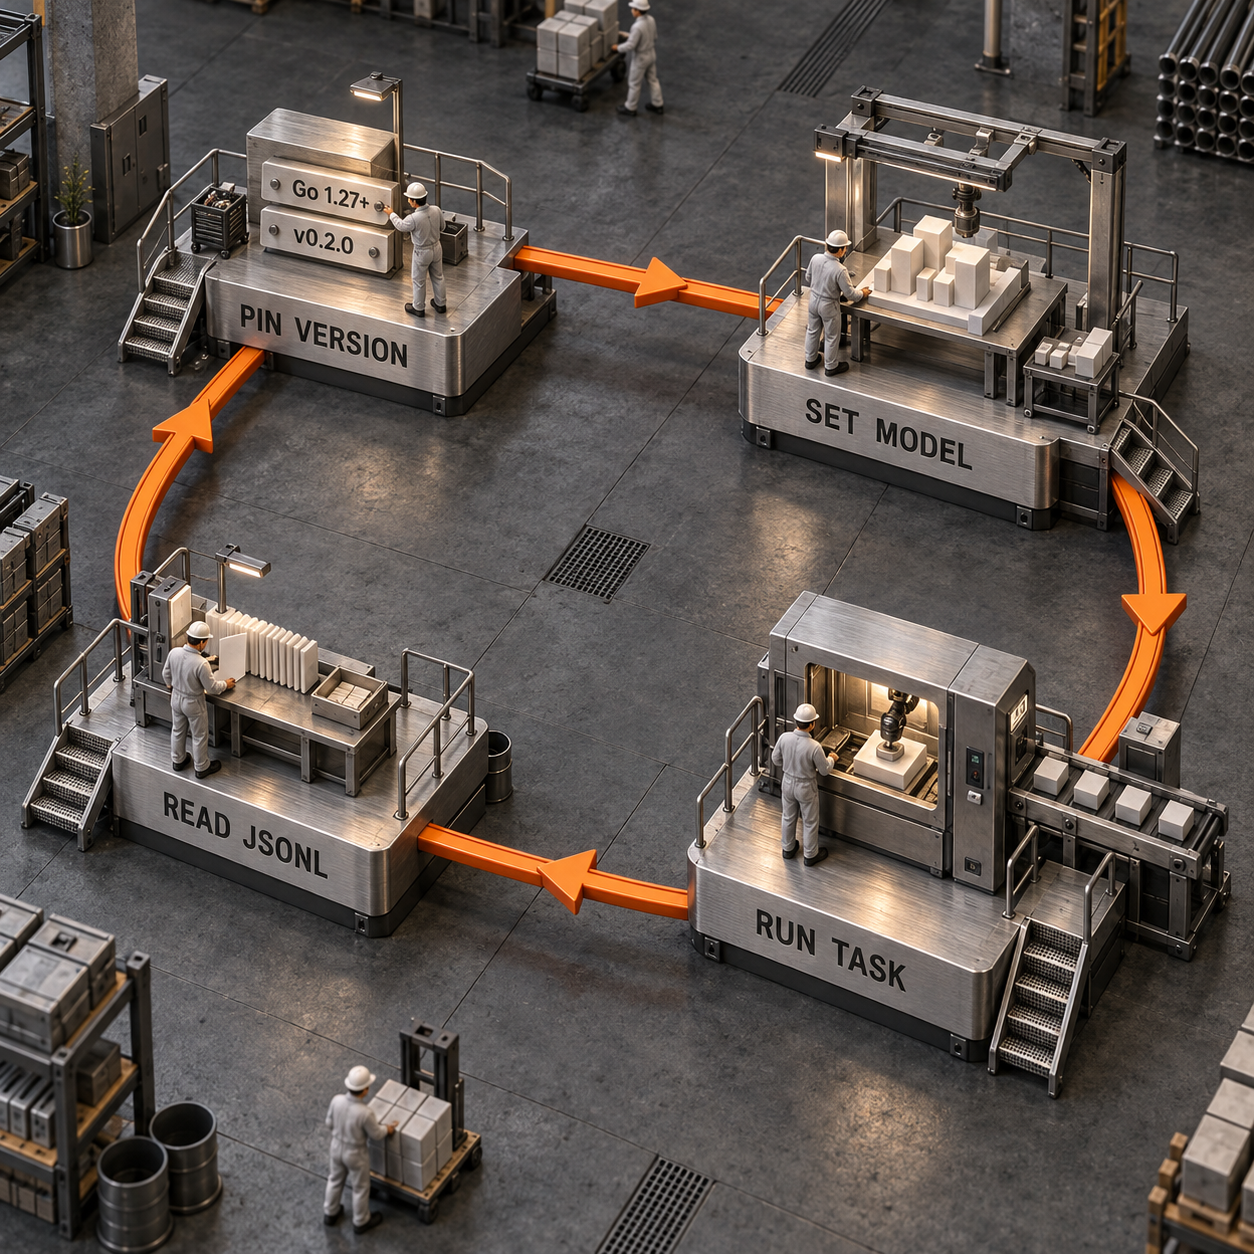
As of September 24, 2026, the current release is v0.2.0, published one day earlier. The runner README requires Go 1.27 or newer and documents @latest; use a release tag for a repeatable evaluation.
The following run uses OpenAI, the current source default gpt-6-astra, and high reasoning. Replace the model only if you record the replacement. Run this against a disposable copy of my-project:
go version
go install github.com/unreallabsai/unreal-agent/cmd/unreal-agent-runner@v0.2.0

export OPENAI_API_KEY="..."
export UNREAL_HARNESS_LLM_PROVIDER="openai"
export UNREAL_HARNESS_LLM_MODEL="gpt-6-astra"

started_at=$(date +%s)
set +e
unreal-agent-runner \
  -workspace ./my-project \
  -session-directory ./unreal-sessions \
  '{"prompt":"Read this repository. Return its purpose, entry points, test command, and three concrete risks. Do not modify files.","model":"gpt-6-astra","thinking_level":"high","session_id":"repo-summary-v1","disallowed_tools":["ViewImage"]}' \
  > run.jsonl
run_status=$?
set -e
elapsed_seconds=$(( $(date +%s) - started_at ))
printf 'exit_status=%s elapsed_seconds=%s\n' "$run_status" "$elapsed_seconds"
jq -c 'select(.Kind=="model_response") | .Data.Response.Usage' run.jsonl
The runner also supports openai-codex, openrouter, fireworks, and ollama. A request can choose the model, reasoning level, retry count, session ID, system prompt, and tools to exclude. It cannot add arbitrary tools through extra_allowed_tools today because that field is accepted but ignored.
3. Read the run as evidence
A useful evaluation record has six parts:
The persisted session is unreal-sessions/repo-summary-v1.session.jsonl. Reuse the same session_id to continue that session. Use a new ID when you want a clean comparison, otherwise earlier context can change both quality and cost.
No first-hand performance result is claimed here because a live provider run was not completed. The only honest performance number is the one you capture on your own repository.
Runner or library?
Choose the runner when you are testing a prompt, evaluating a repository job, or wiring a process into CI. Choose the Go library when the agent must live inside your product and you are prepared to own session storage, lifecycle behavior, tools, security, and provider integration.
The distinction is like a power tool versus its motor. The runner gives you a usable tool with switches already attached. The library gives you the motor and the freedom to design the housing, controls, and safety system. If session ownership is the deciding issue, this Agents API versus SDK comparison provides a useful adjacent framework.
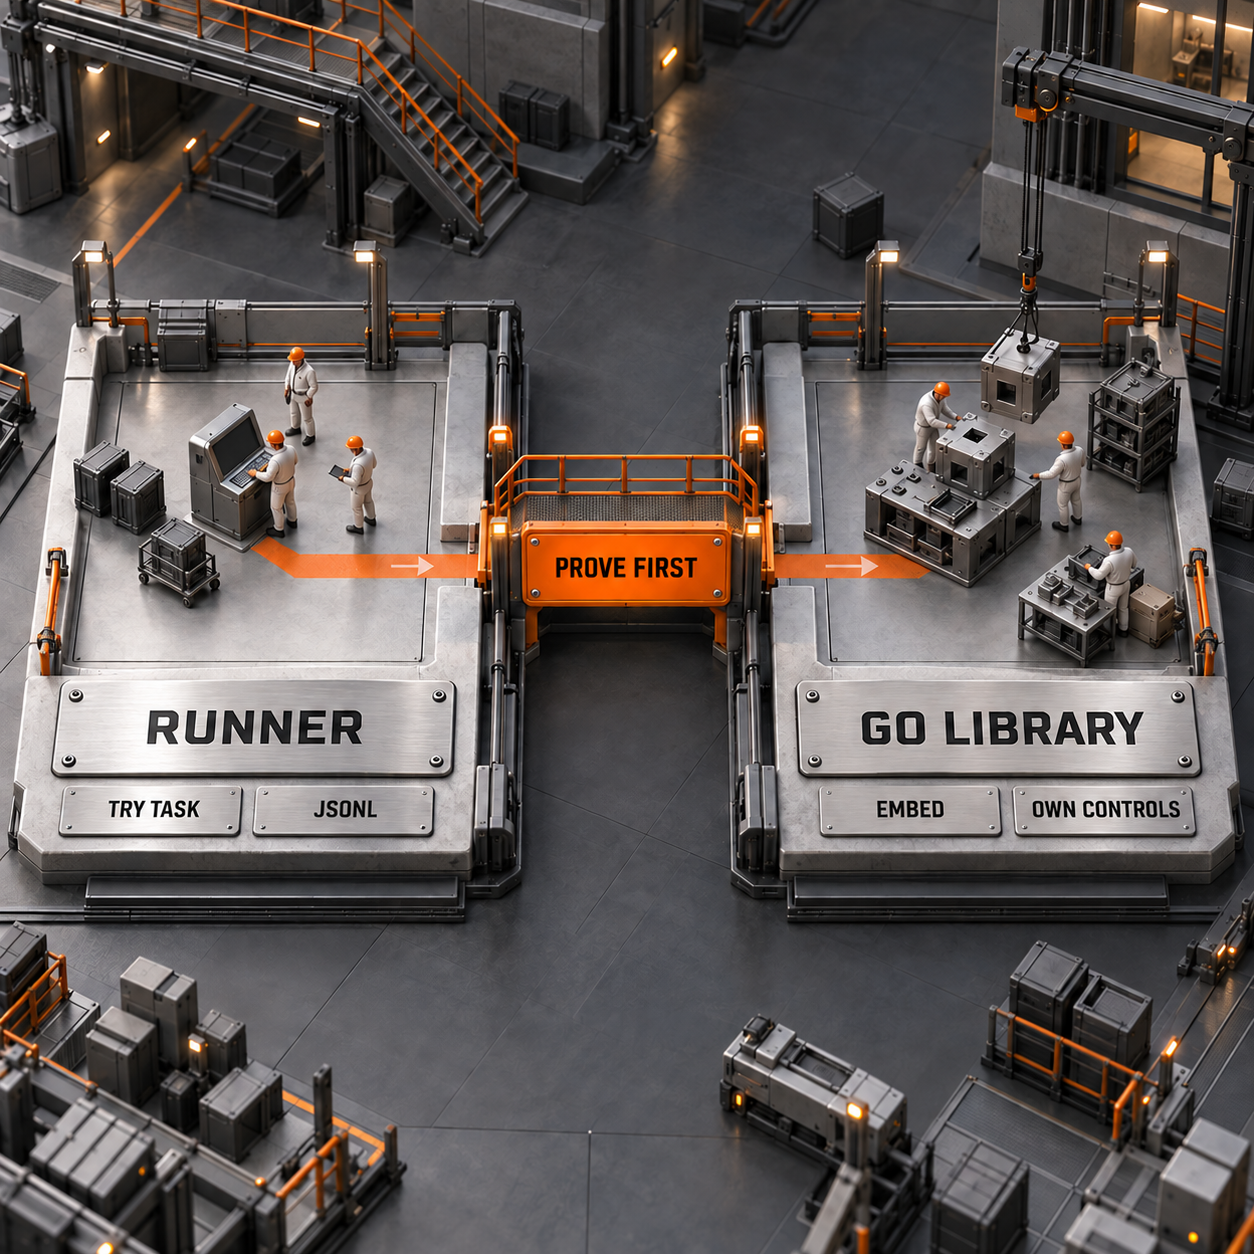
The runner is the right default because integration work can hide a weak task. If the same bounded prompt cannot produce a useful result twice, an API wrapper will not repair the product idea.
Six jobs worth testing, ranked
1. First-pass review of agent-written pull requests
An engineering team receiving large AI-generated pull requests could give the runner a clean checkout, the diff, and the repository test commands. It could inspect affected code, run targeted checks, and return a JSONL-backed review packet. The payoff is not removing human review. It is moving repetitive repository inspection ahead of the reviewer so attention goes to architecture and risk.
2. New-engineer repository orientation
A platform team could run the exact summary prompt above whenever a new engineer joins a service. The output would map entry points, test commands, configuration, and obvious hazards, with the session trace available for verification. The payoff is a repeatable first hour without asking a senior engineer to narrate the same repository from scratch.
3. Failing-test triage
A developer with a noisy CI failure could ask the runner to reproduce one failing test, search the relevant code paths, and separate the likely cause from unrelated output. Async tool handling matters here because environment setup, searches, and test execution can overlap. The payoff is a smaller evidence packet for the engineer who makes the fix.
4. Dependency-upgrade preparation
A maintainer could point the agent at a branch containing one dependency bump and ask for affected imports, deprecated calls, test coverage, and migration notes. The output becomes a checklist, not an automatic merge. The payoff is faster scoping before someone commits a full engineering block.
5. Release-readiness checks
A release owner could ask for changed surfaces, missing migrations, documentation gaps, and the relevant test commands on a release candidate. The session record preserves what the agent actually inspected. The payoff is a consistent preflight that complements, rather than replaces, deterministic CI.
6. Support escalation packets
A product engineer could place a reproducible customer issue in a scrubbed repository environment and ask the runner to trace likely code paths, reproduce the symptom, and list unresolved questions. The payoff is a structured handoff from support to engineering without granting an agent access to customer production systems.
Two products worth building
Strongest: a review gate for AI-generated code
Build a GitHub or GitLab check that launches Unreal Agent in an isolated workspace, reviews the pull request against repository rules, runs allowed checks, and posts an evidence-linked summary for a human reviewer. Teams producing more code with agents are the buyer.
The demand is direct. ai powered code review platform gets about 1,900 US searches a month, while ai code review gets about 1,300 and carries a $55.73 CPC. Existing products validate a seat budget from $20 to $72 per developer per month on annual plans.
The smallest sellable version supports one code host, one model provider, a fixed review prompt, a strict command allowlist, and a result page built from the JSONL trace. The catch is trust. False positives, leaked secrets, noisy comments, and unsafe commands can erase the value quickly. This is still the best opportunity because it is frequent, measurable, and attached to an existing budget.
A bring-your-own-model repository job runner
Build a small internal control plane where a team chooses a repository, a vetted task template, a provider, a model, and a cost cap, then receives a session trace and approval-ready result. Agencies and platform teams that want an open runtime without building the queue, isolation, and reporting layers would pay for it.
open source ai coding agent gets about 5,400 US searches a month with commercial intent and a $13.11 CPC. That is broader demand than the review query, but the product request is less specific.
The MVP is a repository connector, ephemeral workspace, two task templates, provider configuration, job status, token reporting, and downloadable JSONL. The catch is differentiation. A thin dashboard around an early runtime is easy to copy, and serious buyers will demand identity controls, audit logs, network policy, and dependable cleanup. Win on a specific workflow and operating controls, not on the product name.
What Unreal Agent does not solve
It does not provide a complete production boundary. The workspace flag is not a sandbox, and the built-in Bash tool can act inside the environment you give it. Isolation, network policy, credentials, approvals, and cleanup remain your job.
It does not remove provider differences. Unreal Labs reports that the in-progress-plus-final tool-result pattern was rejected by some models on some non-OpenAI inference providers during its testing. Validate the exact provider and model pair you intend to ship.
It does not offer elaborate orchestration. The small footprint, with no sub-agents or workflows, is part of the efficiency argument. It is a poor fit when your product depends on a visual workflow builder, a large catalog of managed connectors, or delegated specialist agents out of the box.
It also does not prove savings for your workload. Model choice, reasoning effort, cache behavior, tool output, retries, and task success all change the bill. Compare successful completed tasks, not raw token totals from different settings.
The Monday move
On Monday, a platform engineer should pin v0.2.0, prepare one credential-free repository copy, and run the repository-summary task twice with the same model and reasoning level. Keep the JSONL, session file, exit status, elapsed time, token usage, and repository diff. If both runs are useful and clean, repeat the same task with the current agent. Only then decide whether to test a review workflow or embed the library.
What is Unreal Agent?
Unreal Agent is an async-first Go agent runtime from Unreal Labs. It includes a Go library, an installable command-line runner, and a Harbor-compatible benchmark runner. It is unrelated to Epic Games' Unreal Engine.
What do I need to run Unreal Agent?
For the source install, you need Go 1.27 or newer, a workspace, a supported provider configuration, a model, and any required provider credential. The runner supports OpenAI, OpenAI Codex, OpenRouter, Fireworks, and Ollama.
Can Unreal Agent resume a session?
Yes. Set a session_id in the JSON request. Reusing that ID resumes its persisted session; a new ID creates a fresh session.
Does the workspace flag sandbox the agent?
No. It selects the workspace and Bash working directory. Put the process inside a separate sandbox or disposable environment and restrict credentials and network access there.
Is Unreal Agent cheaper than Codex?
Unreal Labs reports up to 40% savings against Codex in its workloads and published benchmarks. That is a vendor result, not a guarantee. Compare the same model, reasoning level, prompt, repository state, and success criteria before drawing a cost conclusion.
If you want a controlled repository agent built around your own workflow, AI agent development is the right place to start.
- Last Updated
- Sep 24, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

How to Use JetBrains Air
Install Air Alpha in your JetBrains IDE, connect an agent, add project context, and review your first code change.Sep 23, 2026Build
Is JetBrains Air Free
Air's IDE plugin is free. Compare Junie Lite, existing agent subscriptions, provider API billing, and JetBrains AI credits.Sep 23, 2026Build
Firecrawl Self Host
Self-host Firecrawl from a pinned release, verify a scrape, and compare features and 30-day costs with Cloud before choosing a deployment.Sep 22, 2026Build
Human Approval for AI Agent Retries
An agent spent $5.48 before anyone looked. See why paid redos need approval that the model cannot grant itself.Sep 22, 2026Build
MindStudio AI Agent Builder
Evaluate MindStudio AI Agent Builder by workflow fit, plan limits, model charges, and the cost of 1,000 or 10,000 completed jobs.Sep 22, 2026Build
Superwhisper vs Wispr Flow
Compare Superwhisper and Wispr Flow for business dictation: local and cloud settings, supported devices, correction work, and the full subscription cost.Sep 22, 2026Build
AI Automation Agency
Choose an AI automation agency by workflow fit, 90-day total cost, support, and ownership. Compare providers and check the pilot before signing.Sep 22, 2026Build