Jev vs GLM-5.3-Flash
Compare Jev with GLM-5.3-Flash through Privatemode Decisions for support routing, image inputs, latency and cost per correct decision.

- JJev
- PPrivatemode Decisions
- GGLM-5.3-Flash
- Lllama.cpp
Choose Jev for high-volume text routing when the lowest raw inference cost matters; choose GLM-5.3-Flash through Privatemode Decisions when images, European proximity, confidential processing, or model portability decide the workflow. For a 500-token ticket with four choices, today's list prices work out to about $0.034 per 1,000 Jev decisions versus $0.146 for the Privatemode path, but one scanned invoice makes Jev ineligible without a separate OCR step.
Which One Should You Pick?
Pick Jev when the job is text-only classification at scale: route a support ticket, score a policy condition, or select one answer from a known set. Its low input price makes it the clear raw-cost winner, and its purpose-built API keeps the decision primitive simple.
Pick GLM-5.3-Flash through Privatemode Decisions when the state can include an image, the client sits closer to Privatemode's European service, confidential processing is part of the buying case, or you want the same library to point at another vLLM-backed server later. You pay more per text decision, but you gain multimodal input and a more portable implementation.
For a US-based text queue, Jev is the stronger default. For a Germany-based image queue, the Privatemode route is the stronger default. If neither description fits, do not pick from a feature grid. Run the same labelled cases through both and price the errors and handoffs, not just the tokens.
Jev vs GLM-5.3-Flash: What the Choice Really Means
Jev and GLM-5.3-Flash are not two interchangeable chat models. Jev is a purpose-trained decision model. You send state plus a typed question such as a Choice or Score, and the API returns an answer with probabilities and a confidence statistic. The product is designed for the narrow moment when software must choose, not converse.
Privatemode Decisions is a library technique wrapped around a general language model. It presents named options to GLM-5.3-Flash, masks the next token to the valid option indexes, reads those token probabilities, and renormalizes them. One forward pass and one output token turn a broad multimodal model into a fast constrained chooser.
That distinction changes the buying question. Jev is the specialized service. Privatemode Decisions is the decision layer plus the model and endpoint behind it. The library can target an OpenAI-compatible vLLM server, while Privatemode's own endpoint adds its confidential-computing deployment. Portability belongs to the library; Privatemode's encrypted-processing guarantees do not automatically follow it to an arbitrary server.
There is another naming trap. The Jev Decisions API compared here is not the OpenRouter product called Jev Router. The latter chooses a model for a prompt. If that is what you are evaluating, use the separate guide to Jev Router pricing. Mixing the two products makes every cost and capability comparison wrong.
Jev Support Routing Wins on Text Cost
Jev is the cleaner fit for a queue of ordinary text tickets because its contract already speaks in decisions. The current TypeSafe model page lists jev-1.13.0 at $0.042 per million input tokens, with output free. The jev-latest alias currently resolves to that version, and the response includes a versioned model field that should go into your test log.
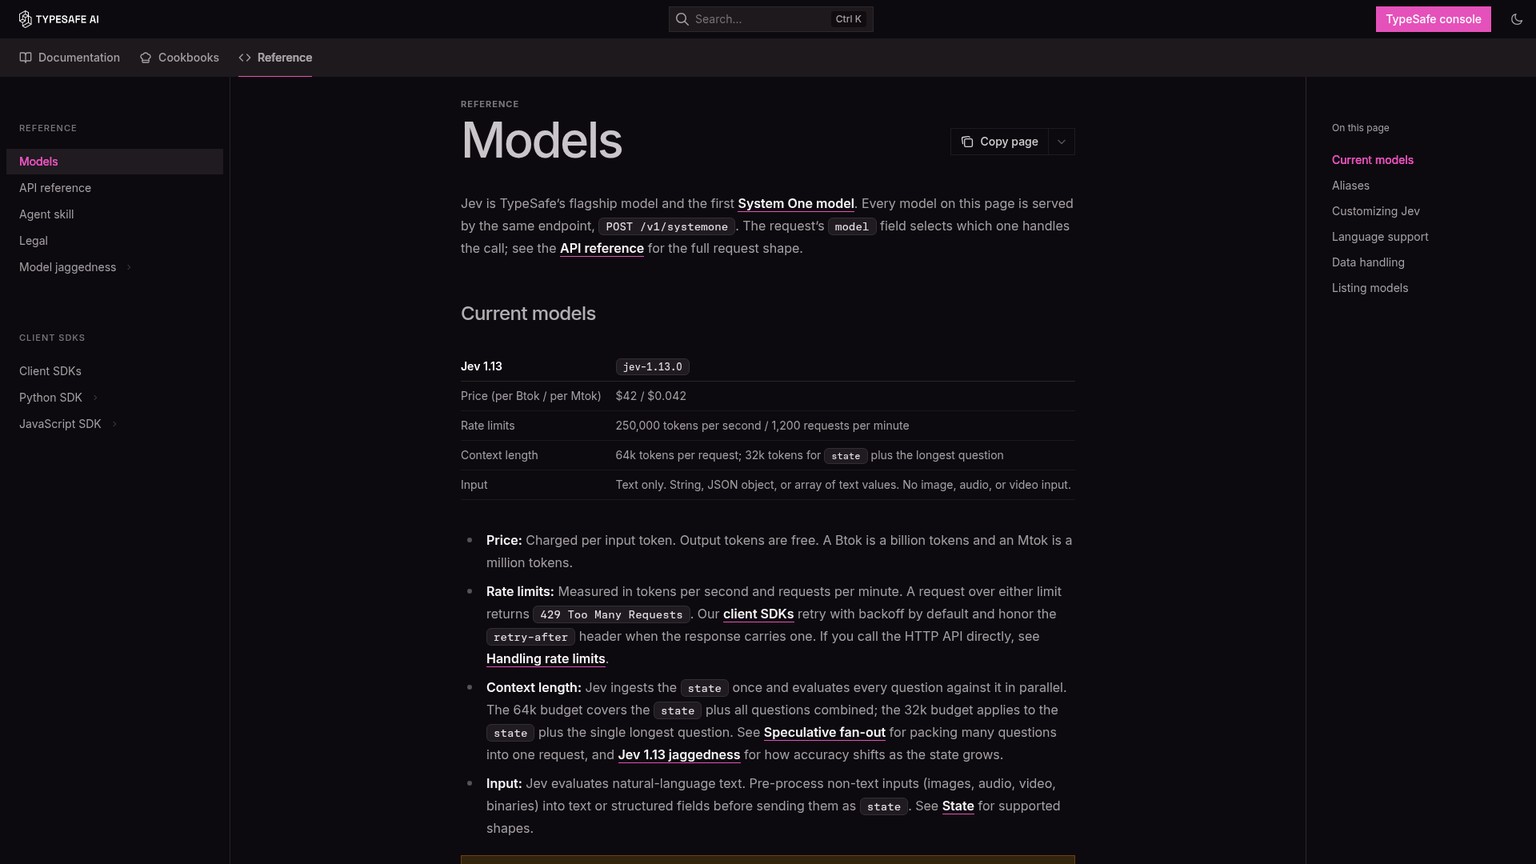
A support-routing call can carry the ticket as state and choices such as billing, cancellation, bug, and none of these. Jev accepts strings and structured text such as JSON or arrays, but not images, audio, or video. Its request limit is 64,000 tokens, with a 32,000-token limit for state plus the longest question. Those limits are generous for ticket routing, but they do not turn an attached scan into text.
The advantage is economic, not mystical. Under the vendor's packaging estimate, a four-option decision adds roughly 270 fixed tokens and 10 per option. Add a 500-token ticket and the billable input becomes 810 tokens. At the live price, that is $0.00003402 per decision.
If Jev is new to your stack, the existing Jev support-routing walkthrough covers the API setup. The comparison here starts after setup, at the point where you must decide whether a text-only specialist is still enough.
Category winner: Jev for text-only support routing and raw inference cost.
Privatemode Decisions: The GLM Flash Decision Model
Privatemode Decisions is the better-shaped path when the case itself contains an image or when you want decision logic that can move between compatible model servers. The first library commit landed on September 21, 2026. The pinned release metadata says version 0.1.0, Python >=3.10, and a dependency-free core.
The live Privatemode catalog exposes GLM-5.3-Flash through chat completions, completions, and messages endpoints. It accepts text and images and has a 1 million-token context window. Its official model card describes a natively multimodal mixture-of-experts model with 320 billion total parameters and 18 billion active.
The crucial test-integrity detail is the model name. The example code uses glm-flash-latest, a moving alias. It maps to preview glm-5.3-flash today, but that does not make every future run a GLM-5.3-Flash run. Resolve and record the served model before collecting results. The library also caches option token IDs for 10 minutes per model, so a version change and stale cache are worth ruling out during a controlled test.
The one-token method is efficient, but it has boundaries. The options must map to single-token indexes. The implementation supports up to 191 indexes, while a 151-option question takes two reads because the hosted endpoint returns at most 128 requested log-probability token IDs in one response. For ordinary routing taxonomies this is ample; for a giant flat label space, hierarchy may be the better design.
Category winner: GLM-5.3-Flash through Privatemode Decisions for image input, context, and runtime portability.
Accuracy Is a Workload Result, Not a Probability
Neither a high probability nor a broad benchmark proves that the next ticket is correct. Both systems normalize confidence over the question they were given. If the real answer is missing, the model can still be highly confident in the least-wrong supplied option. An explicit none of these choice is therefore part of the task definition, not an optional escape hatch.
Privatemode's published comparison covered 29 public labelled datasets, with both systems able to answer 28 text datasets. Each led on 10, and eight more were within one percentage point. The reported median gap was 0.7 percentage points in Jev's favor with p=0.64. Identical temperature-zero runs changed up to 3.5% of answers, so the vendor treated small gaps as noise. Those are useful vendor-reported measurements, not this article's benchmark.
An independent benchmark by Kumzha tested 200 human-labelled items per task. It reported 83.5% Banking77 accuracy for GLM-5.3-Flash and 81.5% for Jev 1.13, then 91.0% versus 86.0% on prompt-injection classification. That evidence is independent, but it is not a validation of Privatemode Decisions. Its GLM lane used ordinary constrained generation through OpenRouter with low reasoning, while Jev went directly to an Oregon AWS origin. The latency paths and decision methods were different.
The useful conclusion is deliberately modest: published evidence does not establish a universal accuracy winner. It does show that both paths are credible enough to test on your labels. Your scorecard should separate an ordinary wrong choice from a wrong high-confidence choice, because the second is more likely to bypass human review.
Category winner: no general winner on published text accuracy. Jev or GLM wins only after the same labelled workload is replayed through both.
Latency Depends on Client Region
Latency is a geography result before it is a model result. Privatemode's simultaneous measurement across four datasets reported Germany medians of 180 ms for Privatemode and 264 ms for Jev. For a US client, the order reversed: 299 ms for Privatemode and 164 ms for Jev.
The repository separately describes a typical Privatemode decision as about 150 ms including network time. That is a useful orientation point, but it is not the same measurement as the regional four-dataset test. Treat the repository headline and blog test as separate vendor-reported views, not a combined benchmark.
For a support desk in Frankfurt, the European Privatemode path has the more favorable published latency. For a worker in the US, Jev has the more favorable vendor-reported median. The right test pins the client region and records both p50 and p95, because a queue feels its slow tail, not only its middle request.
Category winner: Privatemode in the reported Germany tests; Jev in the reported US test.
Price Difference and the No-Crossover Result
The live prices verified on September 27, 2026 are straightforward. Jev 1.13 is $0.042 per million input tokens with free output. Privatemode's price sheet lists GLM-5.3-Flash at €0.20 per million input tokens, €0.65 per million output tokens, and €0.05 per million cached input tokens, plus VAT where applicable. For like-for-like USD comparisons, the calculation below uses the ECB's September 25 reference rate of €1 to $1.1403.
The common decision assumes 500 state tokens and four choices including none of these. With the vendor-reported prompt packaging, Jev sends about 810 input tokens. Privatemode Decisions sends about 635 input tokens and produces one output token. GLM packages fewer tokens here, yet its converted input-token rate is about 5.43 times Jev's. The resulting decision is about 4.28 times as expensive.
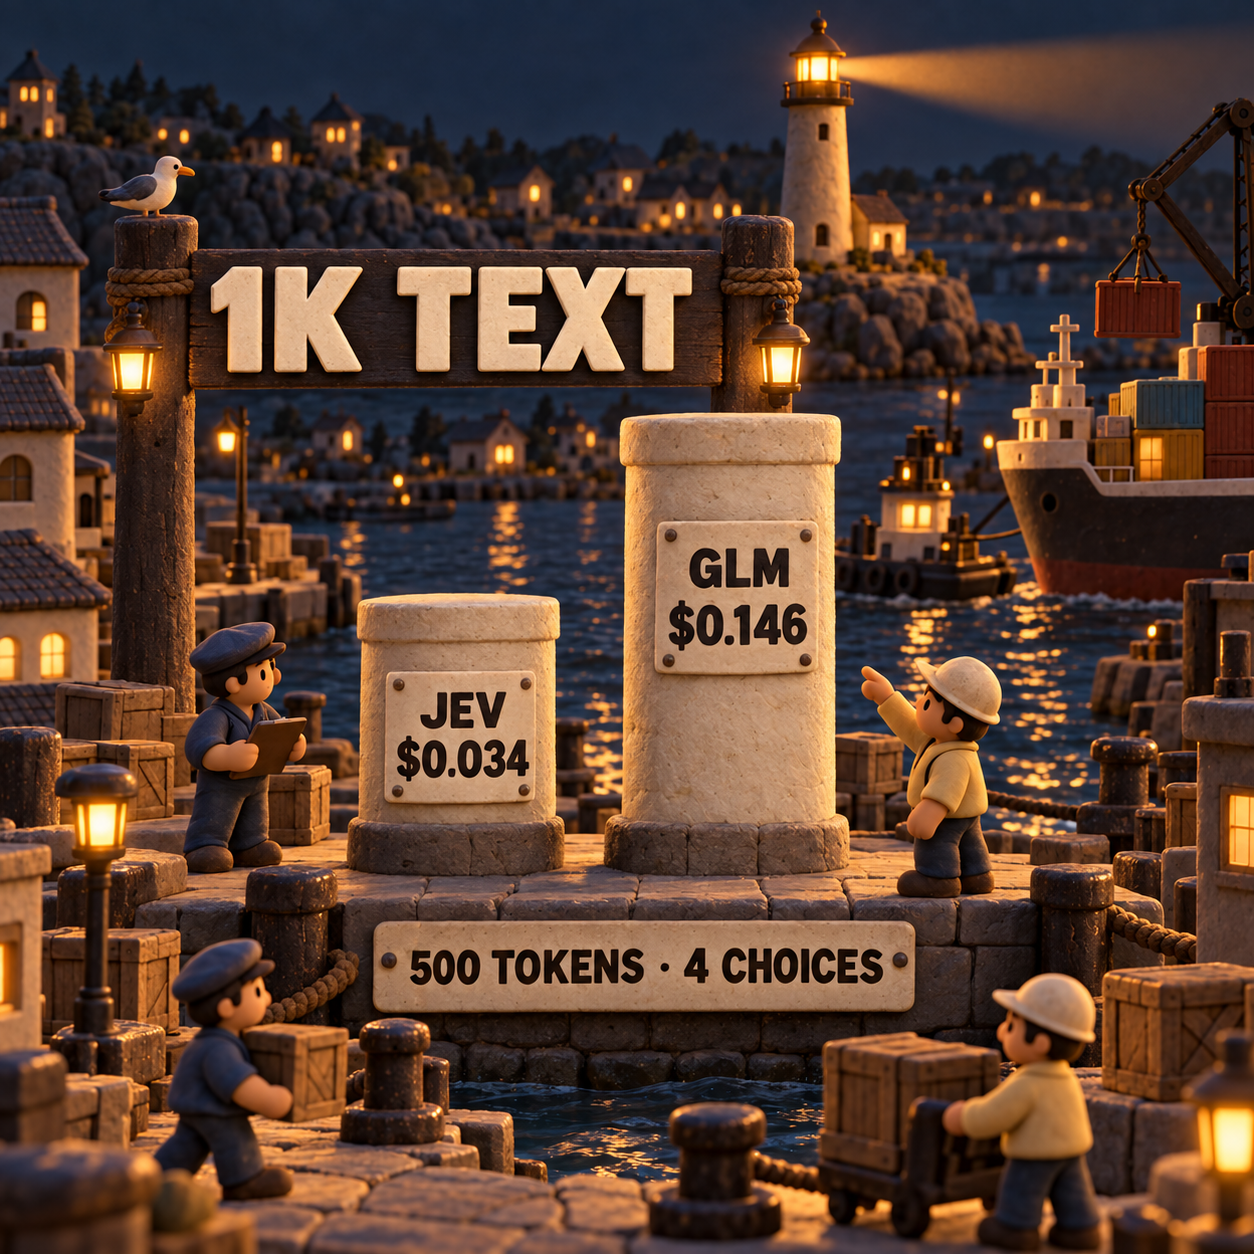
There is no nonnegative raw-token crossover under these list prices and linear packaging estimates. Even though Privatemode's prompt stays shorter below about 21 options, the rate difference is too large for the lines to cross. If both paths return the same operational result, Jev stays cheaper.
But inference is not the whole bill. At 100,000 common decisions, the raw difference is about $11.1539. Suppose a review costs $30 per hour and takes two minutes, or $1 per handoff. Privatemode would need to avoid 12 human handoffs per 100,000 decisions to cover its inference premium. That is a scenario, not a claim that it does so.
This is the metric to own: (inference cost + review cost + retry cost) / correct decisions. A cheaper call that creates more escalations can lose. A costlier call that handles an image without a separate OCR service can win. Without both credentials, there is no honest observed cost-per-correct number to publish.
Category winner: Jev on raw text cost. The workflow winner depends on measured errors, retries, OCR, and human review.
Images Change the Winner for Document Triage
GLM-5.3-Flash wins the direct-input comparison for scanned invoices because Privatemode accepts images and Jev does not. That is a capability boundary, not a small feature difference. A Jev workflow needs OCR or another vision model before its decision call, bringing a second vendor, another failure mode, more latency, and its own cost.
Privatemode reports 70.2% accuracy on 1,600 RVL-CDIP scanned documents across 16 classes. Jev could not enter that image test. The vendor says each image added about 1,350 input tokens and estimates about €270 for 1 million document decisions. Those results establish that the route can ingest scans; they do not establish how it handles your invoices.
Keep five synthetic invoices as a separate capability test. Under the common 500-token base plus the reported 1,350-token image increment, one Privatemode decision would cost about €0.00039765, or $0.00045344; five would cost about €0.00198825, or $0.0022672. Do not mix those five results into the 30-ticket text accuracy score. Otherwise, GLM gets credit for entering a test that Jev cannot take and the text comparison becomes unreadable.
Category winner: GLM-5.3-Flash for direct document-image triage.
Run the Same 30-Ticket Check Before Switching
The smallest credible internal comparison is a frozen set of 30 labelled synthetic tickets, replayed with identical choices, identical order, and an explicit none of these option. Synthetic cases avoid sending customer data during evaluation. They should still represent the short, ambiguous, and out-of-scope tickets that break a production router.
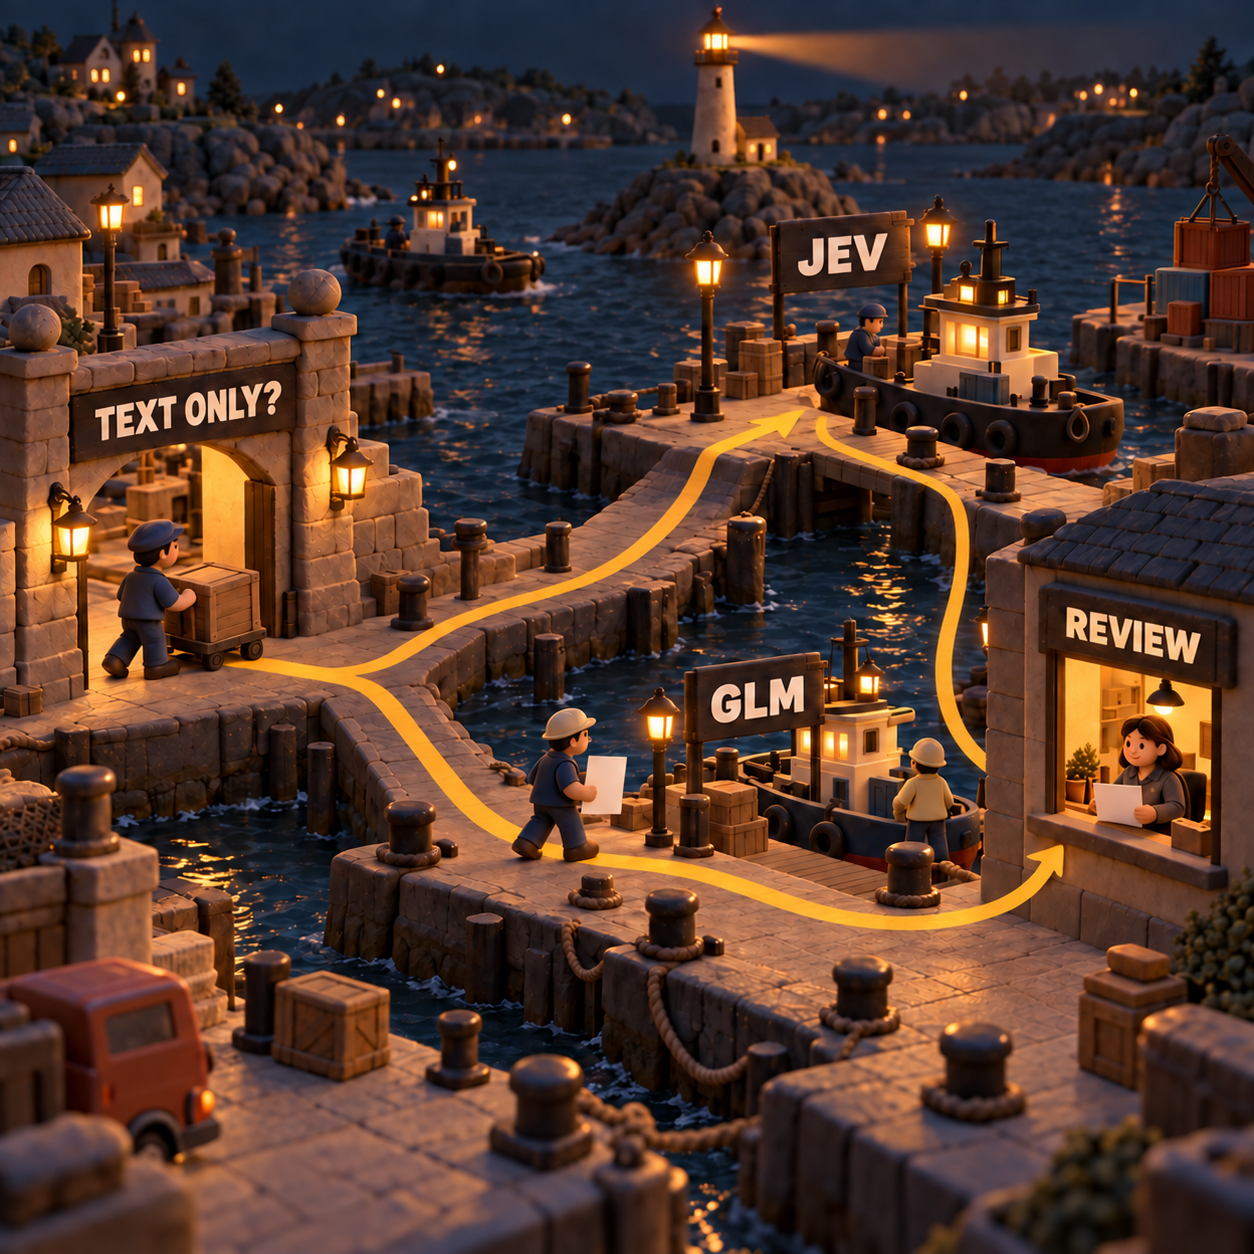
Freeze the fixture
Write 30 text tickets, their expected labels, and the allowed choices into one versioned file. Include
none of these, keep choice order fixed, and hold back the five invoice images as a separate capability set.Pin what each endpoint served
Call versioned
jev-1.13.0or log Jev's returnedmodelfield. Resolveglm-flash-latestand record the actual served model before calling the result a GLM-5.3-Flash test. Record the endpoint and client region beside both.Replay identical decisions
Send the same state and semantically identical options to both paths. Do not quietly improve one prompt, reorder one label set, or let retries count only on one side.
Capture the operational record
For every call, save p50 and p95 latency at the run level, input tokens, billed cost, selected choice, probability or confidence, correctness, retry, and human handoff. Flag incorrect high-confidence choices separately.
Test images outside the text score
Send five synthetic invoice images through Privatemode. Record model, tokens, cost, latency, and label. Mark Jev as direct-input ineligible rather than scoring it as an incorrect text classifier.
Calculate cost per correct decision
Add inference, retry, preprocessing, and human-review costs, then divide by correct decisions. Report the shared 30-ticket text result and the five-image capability result separately.
The raw inference for the planned text run would be about $0.0010206 on Jev versus €0.0038295, or $0.0043668, on Privatemode before retries. That difference is too small to decide a purchase. The run is valuable because it exposes label fit, calibration, regional tail latency, and handoff behavior.
Switching Costs and Who Should Not Switch
Moving from Jev to Privatemode Decisions is not a model-name swap. A Jev Choice or Score becomes a library Choice with fixed option indexes. Your team must map the existing taxonomy, recreate confidence thresholds, replace client and retry behavior, validate the OpenAI-compatible endpoint, and make the alias resolution observable. If confidential processing drove the move, the deployment must remain on the covered Privatemode path rather than an arbitrary vLLM host.
Moving in the other direction also costs work. Image state needs OCR or another vision stage. Long prompts must fit Jev's context limits. Any GLM-specific prompt assumptions need to become Jev questions, and historical probabilities cannot be treated as interchangeable calibration.
Is GLM-5.3-Flash a Jev Alternative?
Yes for finite-choice text decisions, and especially when the same workflow also needs images. No if “alternative” means drop-in replacement with identical confidence, infrastructure, and compliance properties. The API shape, preprocessing, model lifecycle, and deployment boundary all change.
Do not switch away from Jev if the queue is text-only, its labels are stable, current accuracy is acceptable, and saving fractions of a cent per thousand decisions matters more than multimodal input. Do not switch away from Privatemode if direct images or its confidential European service are hard requirements. In either direction, a marginal public-benchmark lead is not enough to repay migration risk.
The Monday Move
Freeze the evaluation fixture before anyone tunes prompts around favored examples. Put the 30 synthetic tickets, five synthetic invoices, choice taxonomy, expected labels, review-cost assumption, and client region into one test record. Add fields for actual model version, endpoint, p50, p95, tokens, billed cost, retries, wrong high-confidence choices, and handoffs.
Then wait for both credentials and run the shared workload. Until that happens, the defensible decision is conditional: Jev owns cheap text routing; GLM-5.3-Flash through Privatemode Decisions owns direct image input and the portable library path.
Frequently Asked Questions
What are the key differences between GLM-5.3 and GLM-5.3 Flash?
On Privatemode, GLM-5.3 is text-only and costs €1.55 per million input tokens and €7.74 per million output tokens. GLM-5.3-Flash accepts images and costs €0.20 input and €0.65 output per million tokens, so Flash is the cheaper and multimodal option there.
Is a GLM flash good?
GLM-5.3-Flash is a credible candidate when a decision task needs images, long context, or the Privatemode deployment. “Good” still depends on accuracy, high-confidence errors, latency, and cost per correct decision on your own labels.
Is GLM-5.3-Flash open source?
Its model files are published under the MIT License. That answers the model-license question, but deployment privacy and service terms still depend on where and how you run it.
Does GLM-5.3-Flash support images?
Yes. The official model card describes it as natively multimodal, and Privatemode lists image input for its GLM-5.3-Flash endpoint.
What does GLM stand for?
The original research paper expands GLM as General Language Model.
Does GLM-5.3-Flash have vision capabilities?
Yes. It can accept images as well as text, which is why it can enter a scanned-document test that Jev cannot enter directly.
How many parameters is GLM-5.3-Flash?
Z.ai's official model card reports 320 billion total parameters and 18 billion active parameters.
Is GLM-4.7-Flash a MoE?
Yes, but it is a different model. Its official card describes a 30B-A3B mixture-of-experts architecture, so do not transfer its specifications to GLM-5.3-Flash.
Is GLM-5.3-Flash multimodal?
Yes. In this comparison, that is the decisive advantage for scanned-document triage.
Want a simpler way to place both options in your stack? Get the AI Tools Map for Business Owners and map the decision layer before you add another model.
- Last Updated
- Sep 27, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI
GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI
Is MiMo V2.6 Free
MiMo V2.6 Flash has a temporary free endpoint. Compare that offer with MIT model downloads, paid API access and desktop plans.Sep 22, 2026AI
Grok 4.7 vs Grok 4.6
Grok 4.7 starts at the same token price as 4.6. Compare access, coding evidence and task costs before moving your workflow.Sep 21, 2026AI