MindStudio AI Agent Builder
Evaluate MindStudio AI Agent Builder by workflow fit, plan limits, model charges, and the cost of 1,000 or 10,000 completed jobs.



MindStudio AI Agent Builder earns a trial when one operator can describe a recurring job as a bounded workflow and its full cost beats the current process. Individual is $20 per month plus usage, but the public team plan is quote-only; this dated worksheet puts a two-call GPT 5.6 Luna job at $0.002 in model usage before review labor. This is a documentary review: no authorized account was available, so the requested 20-record intake test was not run.
Disclosure: MindStudio is an affiliate partner. A tracked purchase may earn a commission at no extra cost. That relationship does not change the verdict, and every plan, rate, and capability below was checked against public first-party pages on 22 September 2026.
MindStudio AI Agent Builder: What It Actually Is
MindStudio is a hosted visual environment for turning a defined business job into an AI-assisted workflow. A builder connects inputs, model calls, rules, code, approvals, outside services, and an end result, then exposes that workflow through a web interface or an automated trigger. It sits between a simple app-to-app automation and software your engineering team owns end to end.
The useful distinction is not "agent" versus "automation." It is judgment versus plumbing. If a request needs interpretation, classification, summarization, drafting, or another model decision, MindStudio can keep that judgment visible inside a larger process. If every step is a fixed move from one system to another, a conventional automation tool is usually easier to price and debug.
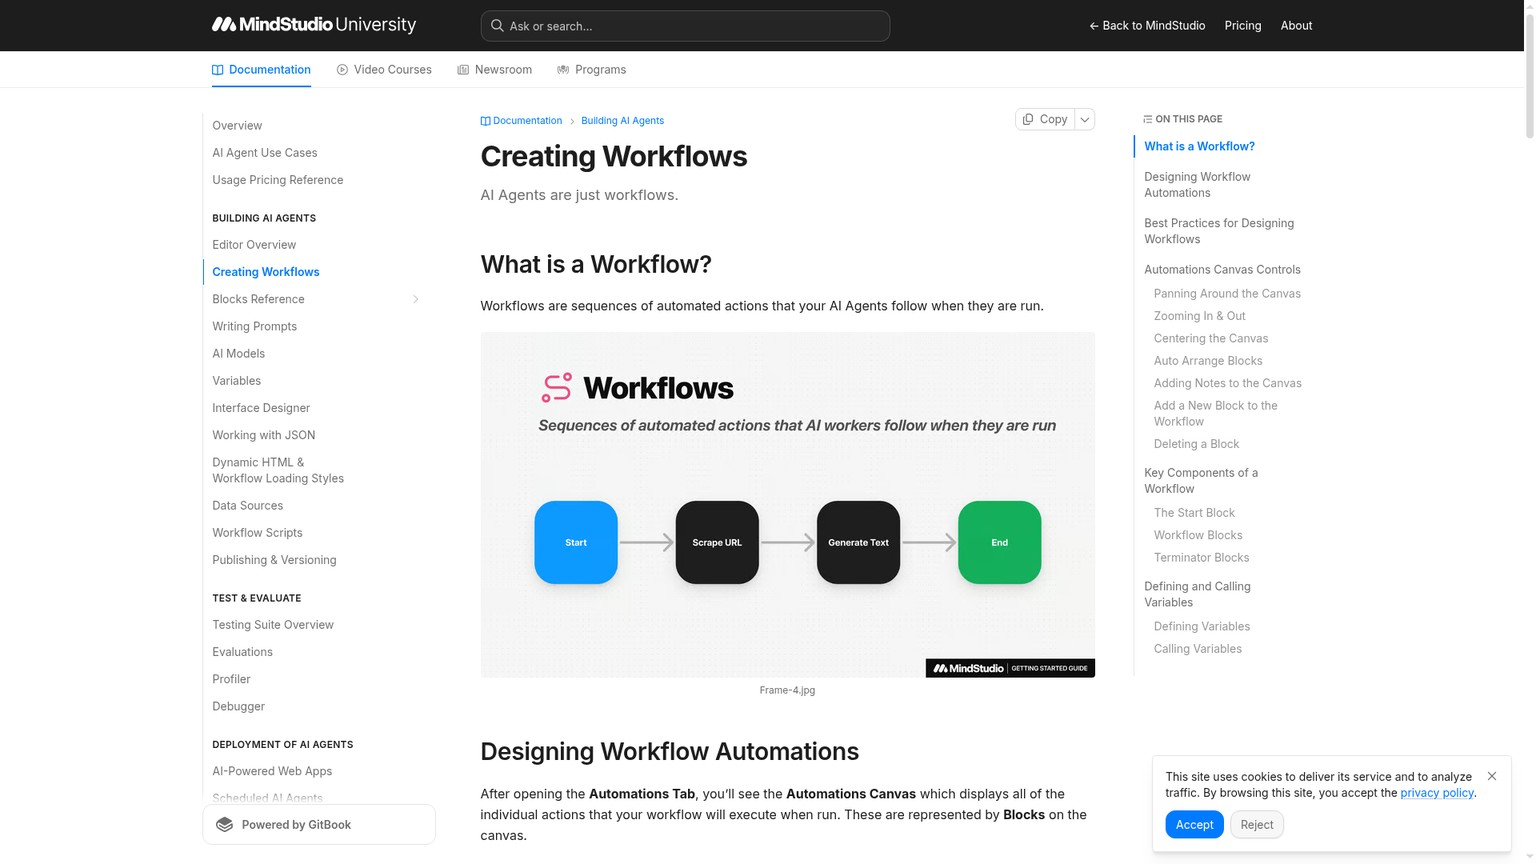
MindStudio's public workflow documentation describes a Start block, launch variables, visual workflow blocks, and a terminator that can return structured output. That is closer to a small application runtime than a chatbot prompt box. The buyer still owns the input contract, permissions, failure handling, review policy, and definition of a completed job.
This MindStudio review is documentary, not hands-on. The public pages establish what the product exposes and what it charges. They do not establish how a particular integration behaves under load, how often a model result needs correction, or how quickly support resolves a failed production run. Those questions belong in the account trial described in the verdict.
Is MindStudio the right no-code AI agent platform for you?
MindStudio fits a solo operator, automation consultant, product manager, or technically curious founder who has one recurring, bounded job in which AI judgment adds value. Good candidates accept named inputs, produce an inspectable result, tolerate a human checkpoint, and have an obvious fallback when the model is uncertain.
An intake-triage job is a clean example. A request arrives with a company name, contact, request text, and consent flag. The workflow validates those fields, classifies the request, drafts a summary, routes sensitive cases to review, and returns a fixed packet. The model decides meaning; deterministic blocks decide what data may enter, where the result may go, and whether a person must approve it.
Skip MindStudio when the job is mostly deterministic. If the requirement is "when a paid invoice appears, add a row and notify accounting," Zapier or Make is the more legible starting point. If the team needs self-hosting, repository-level control, custom nodes, and owned operations, n8n is the stronger candidate. If the purchase centers on a managed workforce of several cooperating agents, Relevance AI is the more direct shortlist entry.
The shared-team case also deserves an early stop. MindStudio Individual is marked "Just me." A five-collaborator workspace belongs on Business, whose public price is custom. Do not model five Individual subscriptions as if they provided the permissions, audit surface, or shared workspace of Business.
That boundary matters more than the number of blocks or integrations. A small business evaluating the broader market can use the AI tools for small business shortlist to separate a tool that performs one job from a system that must be built, monitored, and governed.
Capability 1: Turn One Business Intake Job Into a Visible Contract
MindStudio makes a bounded process inspectable because its canvas shows the handoffs among input, model work, logic, and output. The workflow guide says the Start block can define launch variables, blocks can store runtime variables, routing blocks can branch, and a terminator can return structured output.
For a business-intake agent, the useful build is deliberately narrow:
- Start with a schema. Require
company_name,contact_email,request_text,consent, and a caller-issuedrequest_id. Reject missing or malformed values before paying for a model call. - Use the first model call for classification. Return a closed category such as sales, support, partnership, billing, or other, plus a review flag and a short reason.
- Use the second model call for the deliverable. Draft a concise summary and recommended next action from the validated record and classification.
- Pause sensitive cases. Money, legal language, account deletion, identity conflict, or an invalid result goes to a human checkpoint.
- End with a fixed packet. Return the request ID, category, summary, recommended owner, review status, and failure reason. Only a reviewed packet may update a CRM.
This is a real workflow design, but not a claimed deployment. Its value is the contract around the model: the input fields are known, the output fields are known, and the model does not inherit permission to send, delete, refund, or publish merely because it produced fluent text.
The visual canvas becomes less valuable as the process becomes vague. A giant text box feeding several open-ended model calls is still an ambiguous prompt, even if the connecting lines look orderly. MindStudio deserves credit when the canvas exposes where uncertainty begins and ends.
Capability 2: Choose Models Per Step, Then Price the Choice
MindStudio gives a builder model choice without requiring a separate provider account for every model, but choice only pays when it is tied to a fixed evaluation set. The live model catalog displayed 418 entries on the verification date, spanning text, vision, image, video, speech, embedding, and other model types.
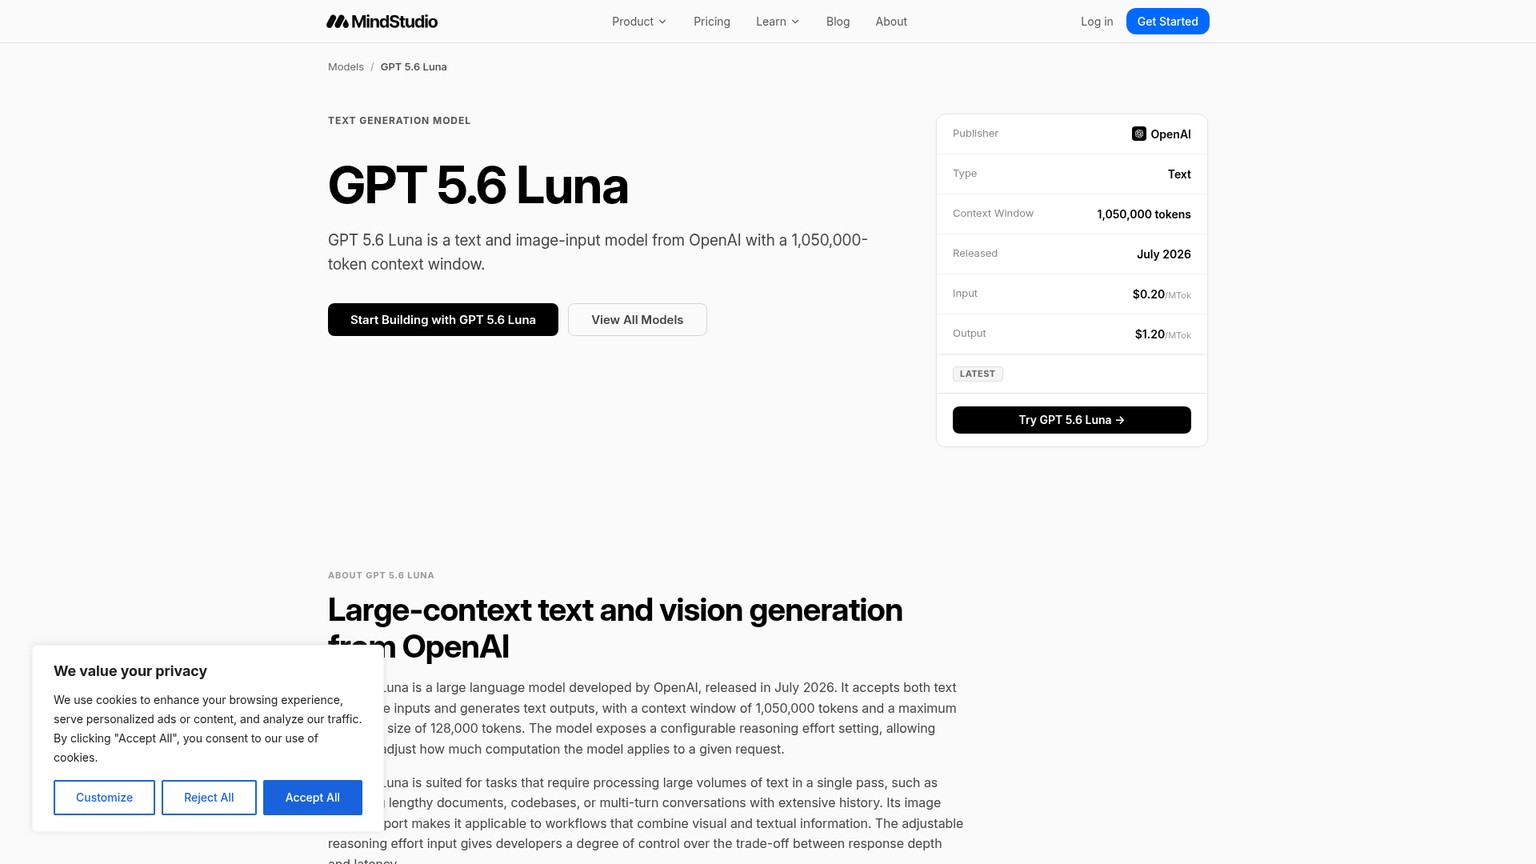
For the worksheet, GPT 5.6 Luna is a useful current reference because MindStudio publishes both sides of its rate card: $0.20 per million input tokens and $1.20 per million output tokens. It is not declared "best" for intake work. It is a supported model with a public price, which makes the arithmetic reproducible.
Model switching is valuable in three places:
- A low-cost model can classify routine inputs while a stronger model handles only difficult drafting.
- A fixed suite can compare the old and new model on the same records before a change reaches production.
- A builder can move a verbose step to a cheaper model when output tokens, rather than subscription price, drive spend.
The trap is optimizing the isolated call instead of the accepted outcome. A model that costs half as much but doubles corrections is more expensive once review time is included. The right unit is cost per completed, accepted job after retries and human corrections. That is why the worksheet prices review separately from tokens.
The same discipline applies to the model catalog. Hundreds of options are useful for specialist media or latency needs, but they also create a governance job: choose an approved default for each step, record the rate and settings, and require an evaluation before changing it.
Capability 3: Connect the Workflow Without Making the Model the Boss
MindStudio can surround model judgment with deterministic connectors, which is the safest way to use it in an operating process. Its live capability catalog displayed 196 capabilities and included HTTP requests, URL scraping, SQL queries, HubSpot actions, Slack and email, plus handoffs to Make, n8n, and Zapier.
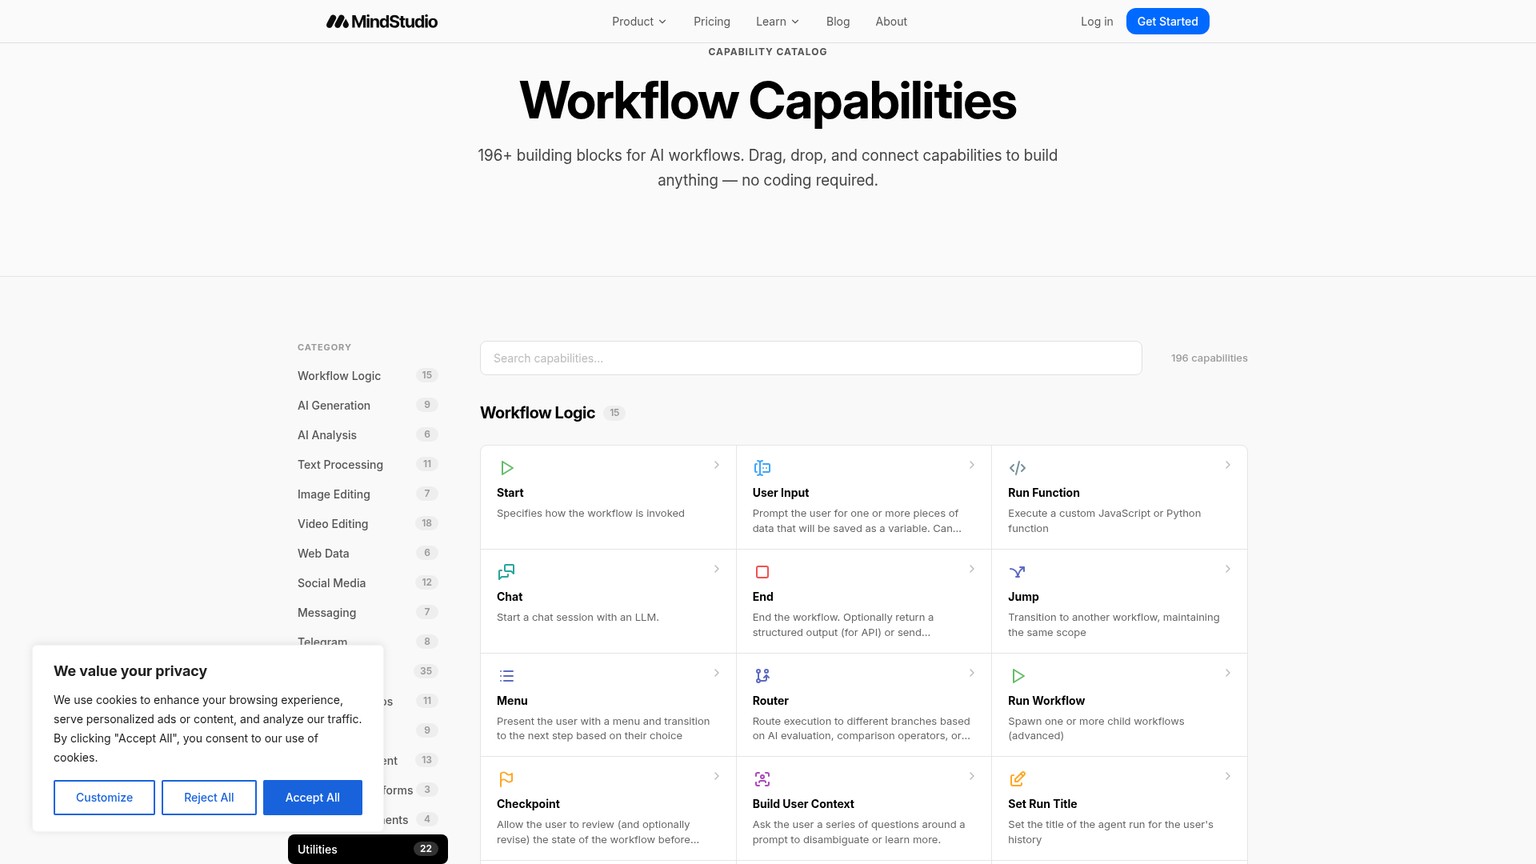
In the intake example, the model should not choose arbitrary systems or fields. A fixed HubSpot block may look up the contact. A fixed Slack block may notify the assigned owner. An HTTP request may send the structured result to an internal endpoint. The workflow determines those allowed actions, and the model supplies only the bounded values the workflow expects.
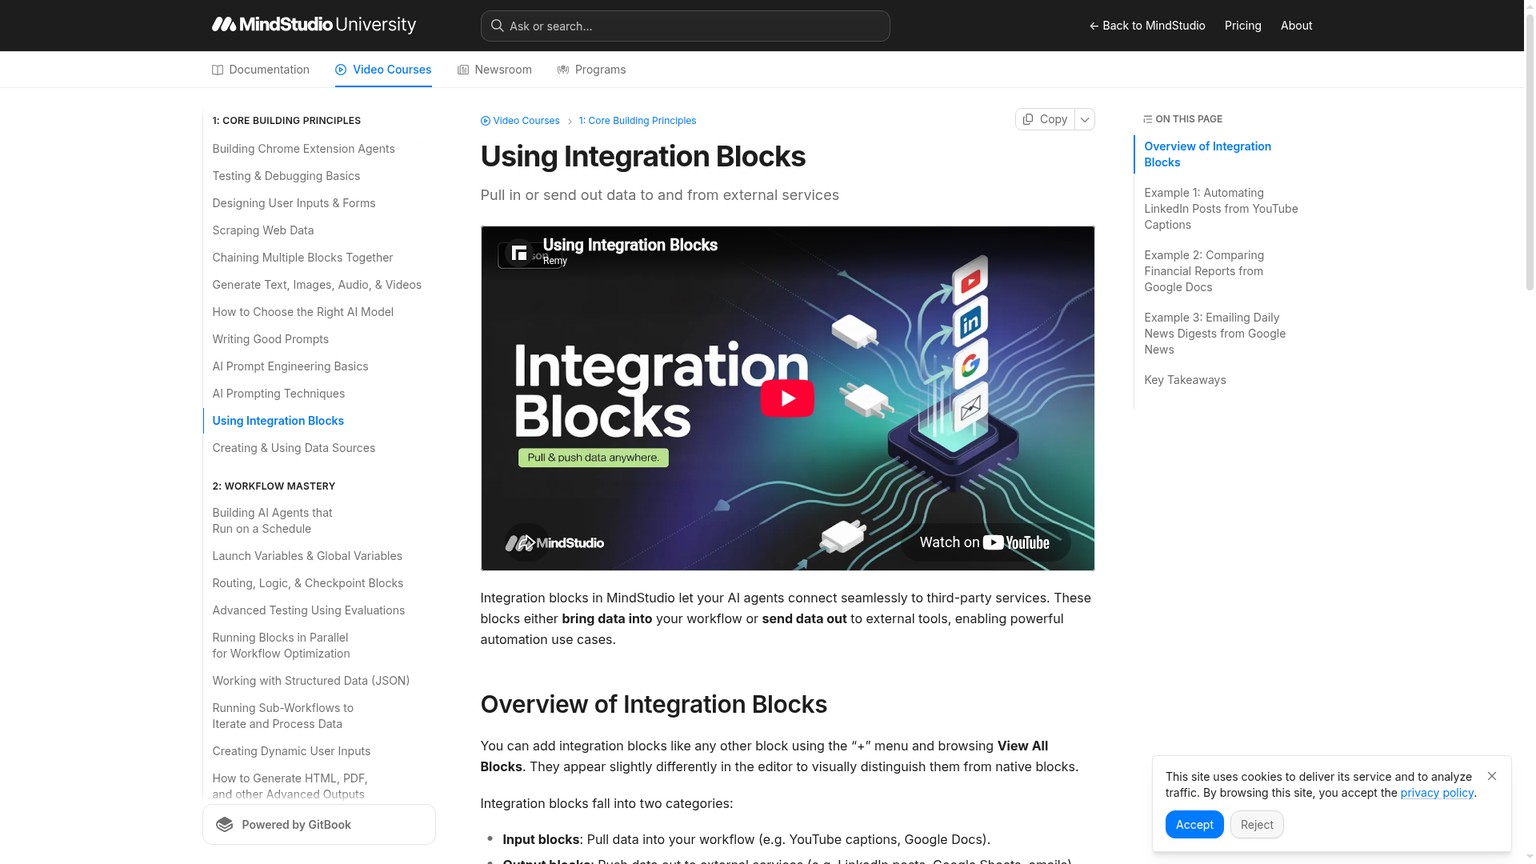
MindStudio's public integration-block lesson shows the same pattern in concrete examples: pull captions and publish a LinkedIn post, compare two Google Docs and write a Google Sheet, or gather news and send a digest. Inputs and outputs move through configured blocks rather than giving a language model unrestricted credentials.
This is also where an ordinary automation tool can be enough. If the model step can be removed without changing the outcome, keep the process in Zapier, Make, or n8n. If one small step genuinely needs interpretation, MindStudio can either own the whole bounded workflow or sit inside a deterministic shell. The latter often gives a technical team clearer retries and reconciliation.
Connector breadth is not connector depth. A logo in a catalog does not prove that the connector exposes the exact trigger, field, attachment, pagination behavior, or permission boundary the job needs. Test the specific action and its failure response with disposable data before granting write access.
Capability 4: Put Review and Regression Tests Inside the Build
MindStudio includes the two controls that make model behavior easier to govern: a human checkpoint and repeatable evaluations. The Checkpoint documentation lists Approve/Reject and Revise Variable modes, so an operator can stop, correct, or approve a result before the workflow continues.
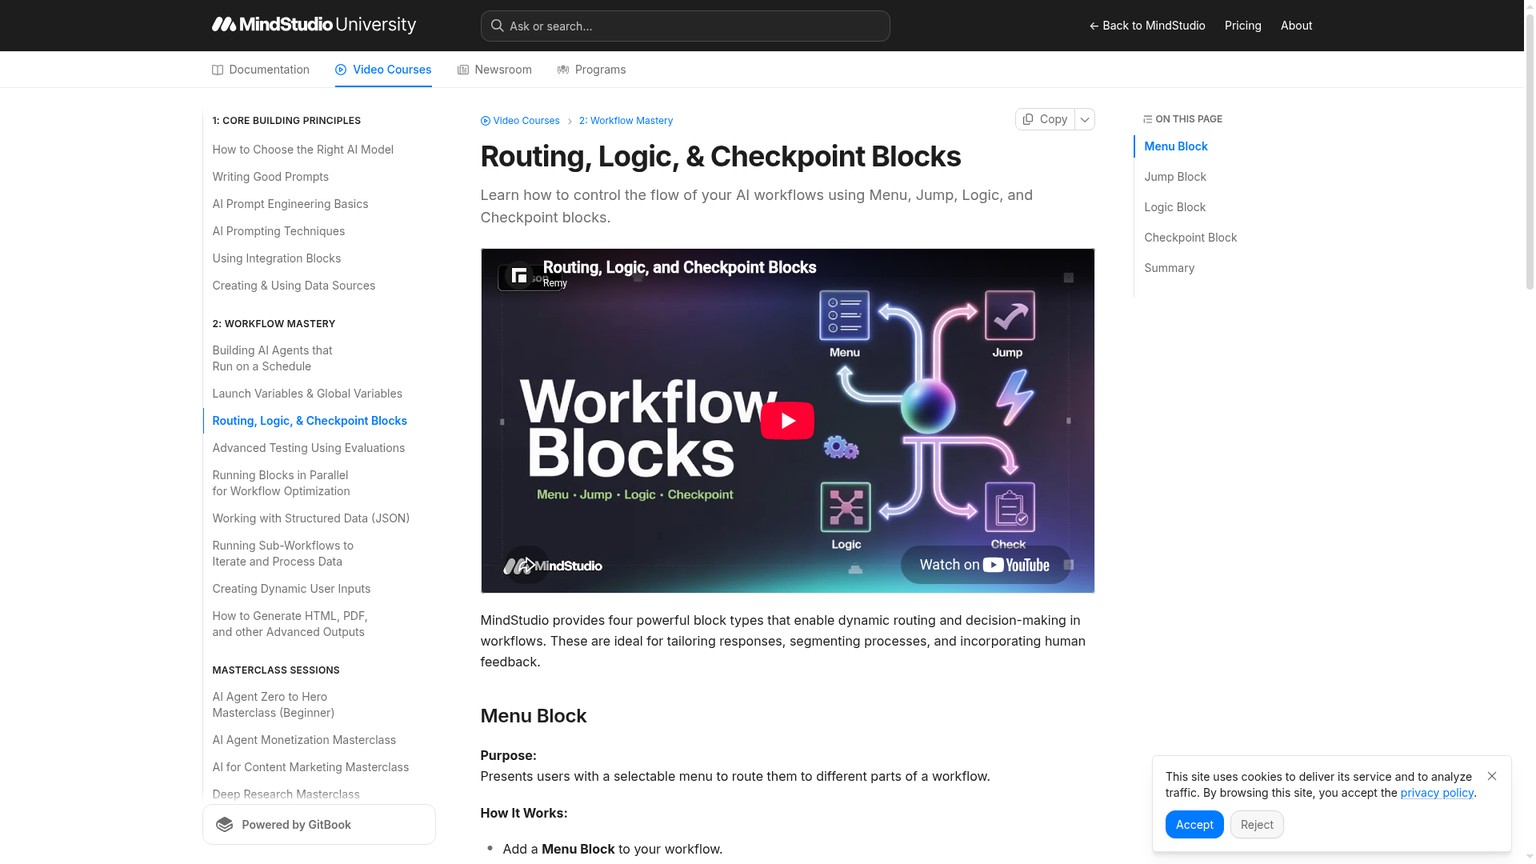
For the intake workflow, a checkpoint belongs after the structured result and before any external write. The reviewer should see the source record, category, summary, proposed owner, and reason the case was escalated. A correction should not disappear into chat history. It should become a test case for the next version.
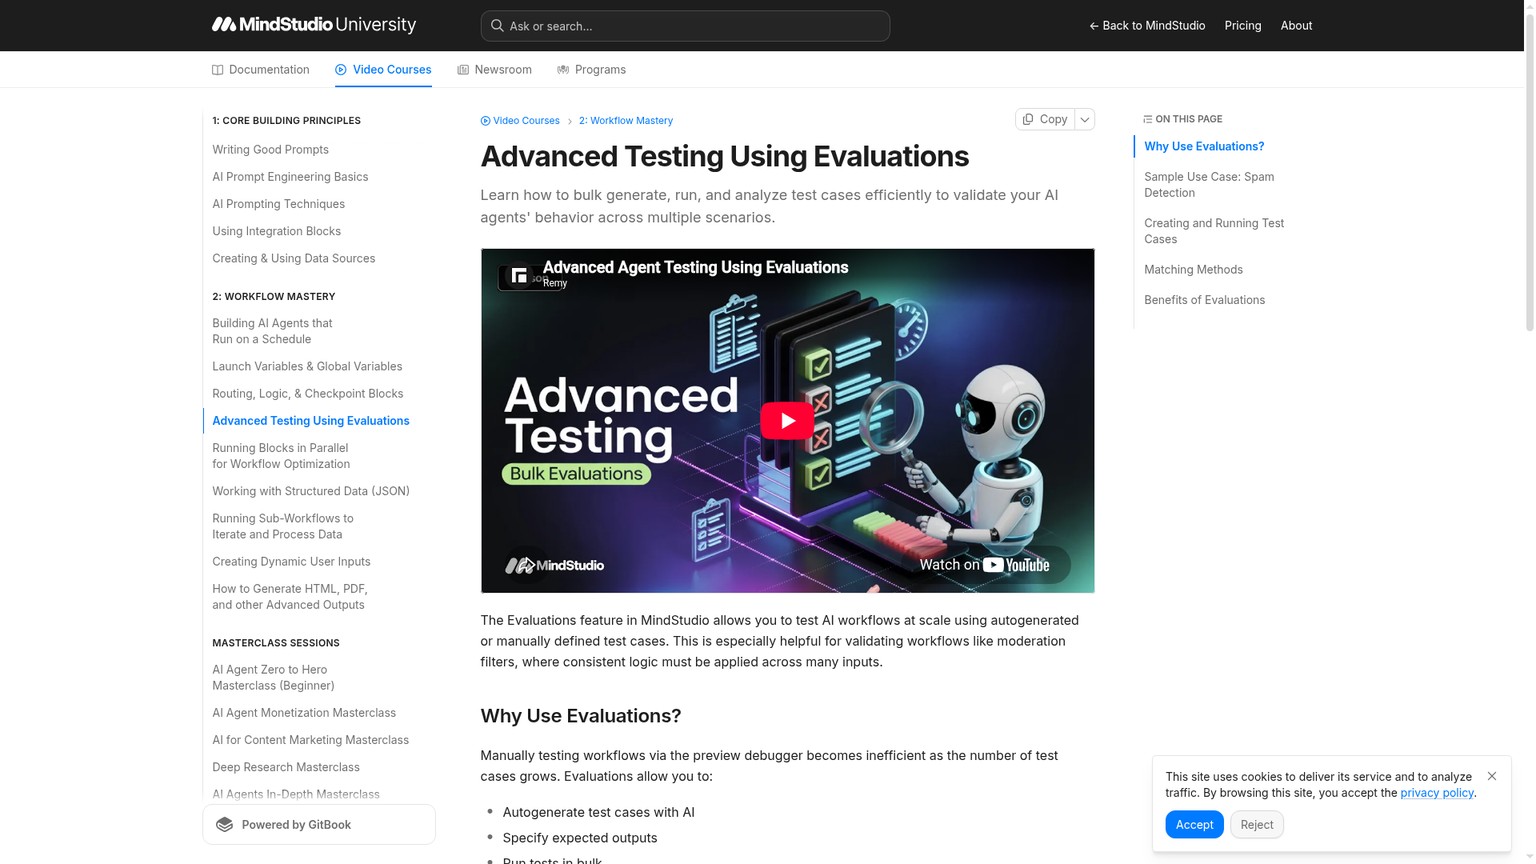
MindStudio's Evaluations documentation supports manually defined or autogenerated cases, expected outputs, bulk runs, pass/fail inspection in the debugger, and both literal and fuzzy matching. Literal matching fits fields such as category and review flag. Fuzzy matching fits a short summary whose wording may vary while meaning stays acceptable.
Custom code fills the deterministic gaps. MindStudio's function documentation supports JavaScript and Python, predefined test data, and separate execution environments. Use a function to validate a schema, normalize a phone number, calculate a score, or enforce a closed enum. Do not ask a model to improvise arithmetic or validation that code can perform exactly.
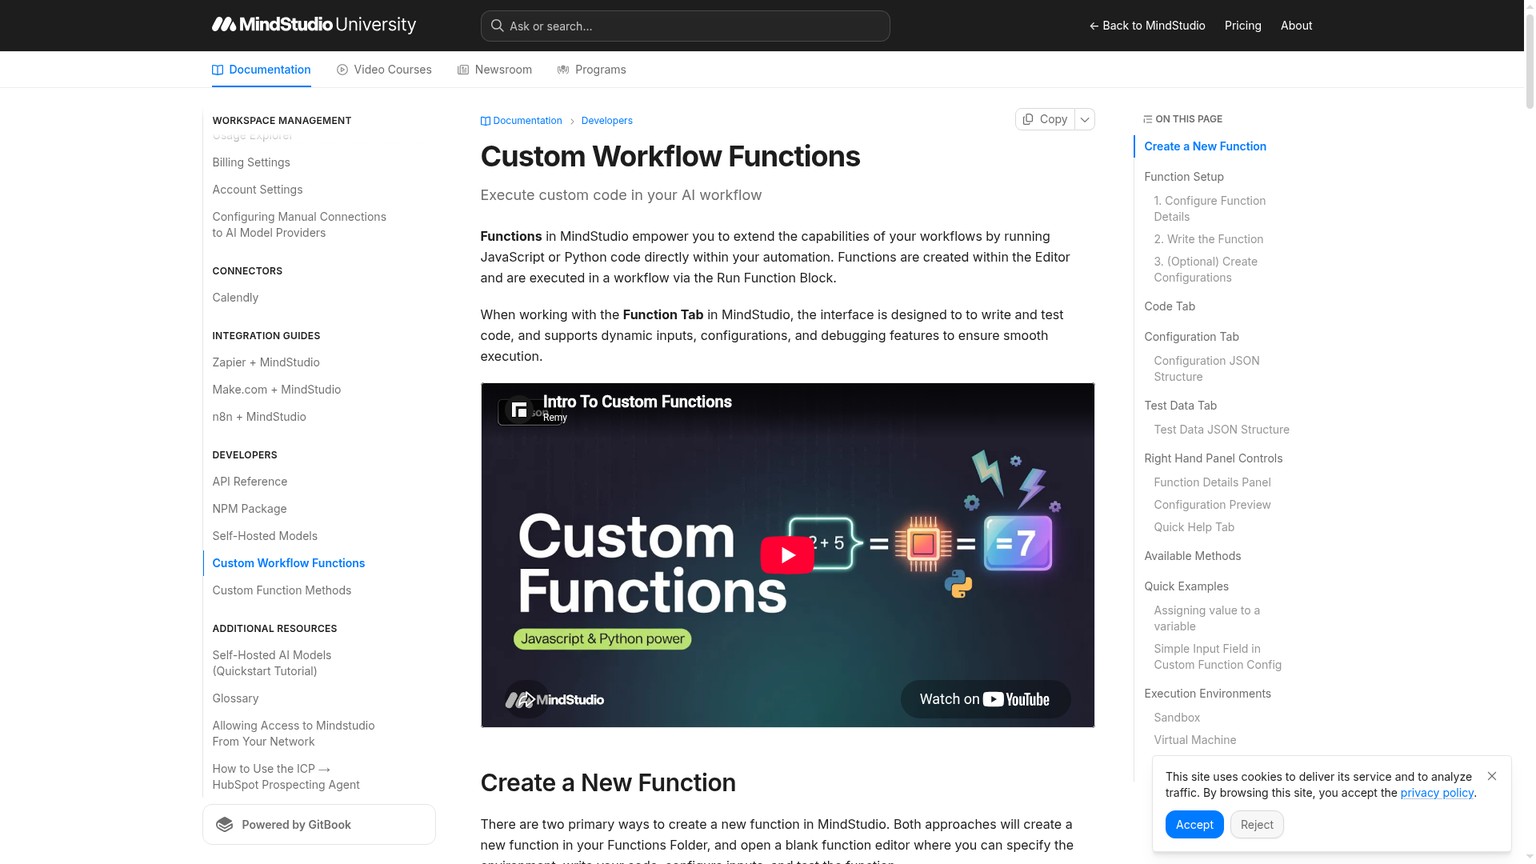
The capability has a concrete wall. The default Sandbox does not support installing NPM packages. MindStudio says typical Sandbox results can return in under 50 milliseconds, while starting a Virtual Machine and installing packages takes at least around 5 seconds and can take longer. That gap matters in a user-facing workflow. A dependency that forces VM execution can turn a quick intake interaction into a visibly slower experience before the model even responds.
MindStudio Pricing: Every Current Tier and the Team Boundary
MindStudio pricing separates the platform subscription from model usage. The live pricing page, verified on 22 September 2026 with both billing selectors checked, shows three tiers:
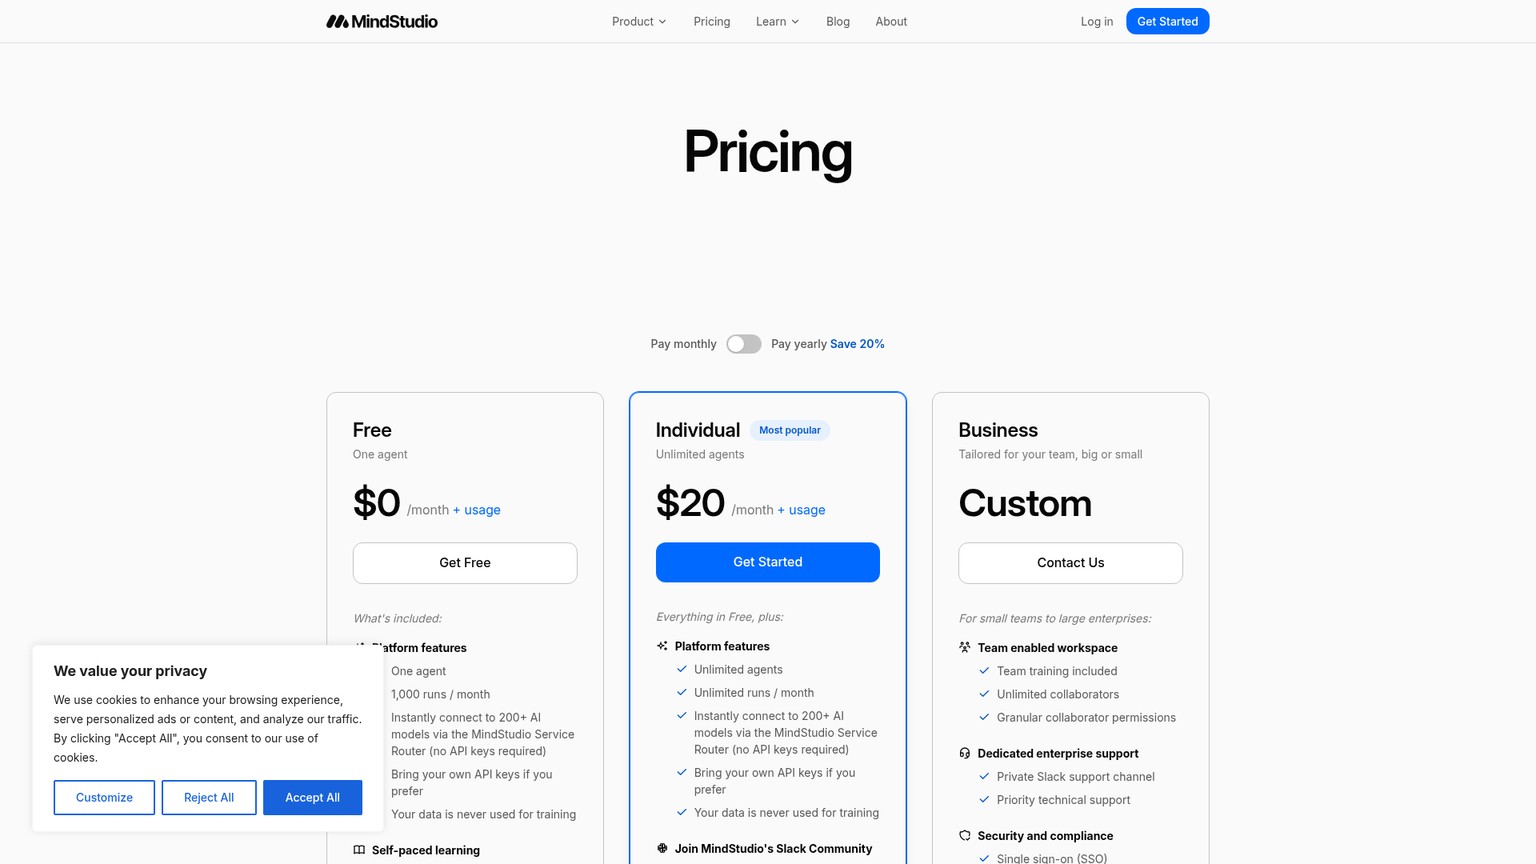
- Free: $0 per month plus usage, one agent, and 1,000 runs per month.
- Individual: $20 per month plus usage, or $16 per month billed yearly, with unlimited agents and unlimited runs. Collaboration is marked "Just me."
- Business: custom pricing for a team-enabled workspace with unlimited collaborators, granular permissions, security and governance controls, usage limits, alerts, and flexible deployment.
A run is one Agent execution. MindStudio says each manual or automatic trigger counts once. Two model calls inside one execution still fit the one-run definition, while a full retry that triggers the Agent again creates another run. This distinction is why an allowance measured in runs and a bill measured in tokens must be modeled separately.
"Unlimited runs" on Individual removes a platform run ceiling. It does not make inference free. The same pricing page says most model usage is charged from input and output tokens, and MindStudio says it passes provider model cost through without markup. Bring-your-own provider keys are also supported.
Create your own AI agent for free: the exact boundary
MindStudio Free is credible for learning one agent and trying a bounded workflow. It can also cover exactly 1,000 executions in a month. It is not a safe production budget for 1,000 completed jobs because setup tests, failures, and retries consume executions too. The public FAQ says extra runs may be purchased or the plan may be upgraded, but it does not publish the additional-run unit price.
Free AI agent builder no-code plan or paid Individual?
Choose Free when the goal is to learn the editor and collect early evidence. Choose Individual when one builder needs multiple agents or enough run headroom to test, retry, and operate. Individual is still a solo workspace. If several people need shared building, permissions, budgets, and audit controls, ask for a Business quote before investing in the pilot.
For five collaborators, the public arithmetic stops at the quote. Five Individual subscriptions would cost five times the sticker price, but they would still be five "Just me" plans, not one Business workspace. Treating them as equivalent would understate the collaboration and governance requirement.
The 1,000- and 10,000-Job Operating-Cost Worksheet
MindStudio's base fee is not the interesting part of the operating bill. Under this scenario, tokens are cheap and review labor dominates. Every figure below is an explicit assumption, not measured MindStudio usage.
The scenario uses one Individual builder, two GPT 5.6 Luna calls per completed job, 2,000 input tokens and 500 output tokens per call, and the published rates of $0.20/MTok input and $1.20/MTok output.
One call costs:
(2,000 / 1,000,000 × $0.20) + (500 / 1,000,000 × $1.20) = $0.001
Two calls make model usage $0.002 per completed job before retries. That becomes $2 at 1,000 jobs and $20 at 10,000 jobs.
The separate retry case assumes 10% of completed-job volume reruns the full Agent. That means 1,100 executions to produce 1,000 completed jobs, or 11,000 executions to produce 10,000. Model usage becomes $2.20 and $22 respectively. This is a scenario, not a claim about MindStudio's failure rate.
Review labor assumes a person samples 5% of completed jobs for 3 minutes each at a loaded rate of $35 per hour. That is $87.50 at 1,000 jobs and $875 at 10,000. Setup is priced separately at 12 builder hours × $75 per hour = $900 one time.
The recurring totals include Individual, model usage, and sampled review. They exclude the $900 setup, taxes, paid third-party services, storage, media generation, charges outside the two stated model calls, and any Business quote.
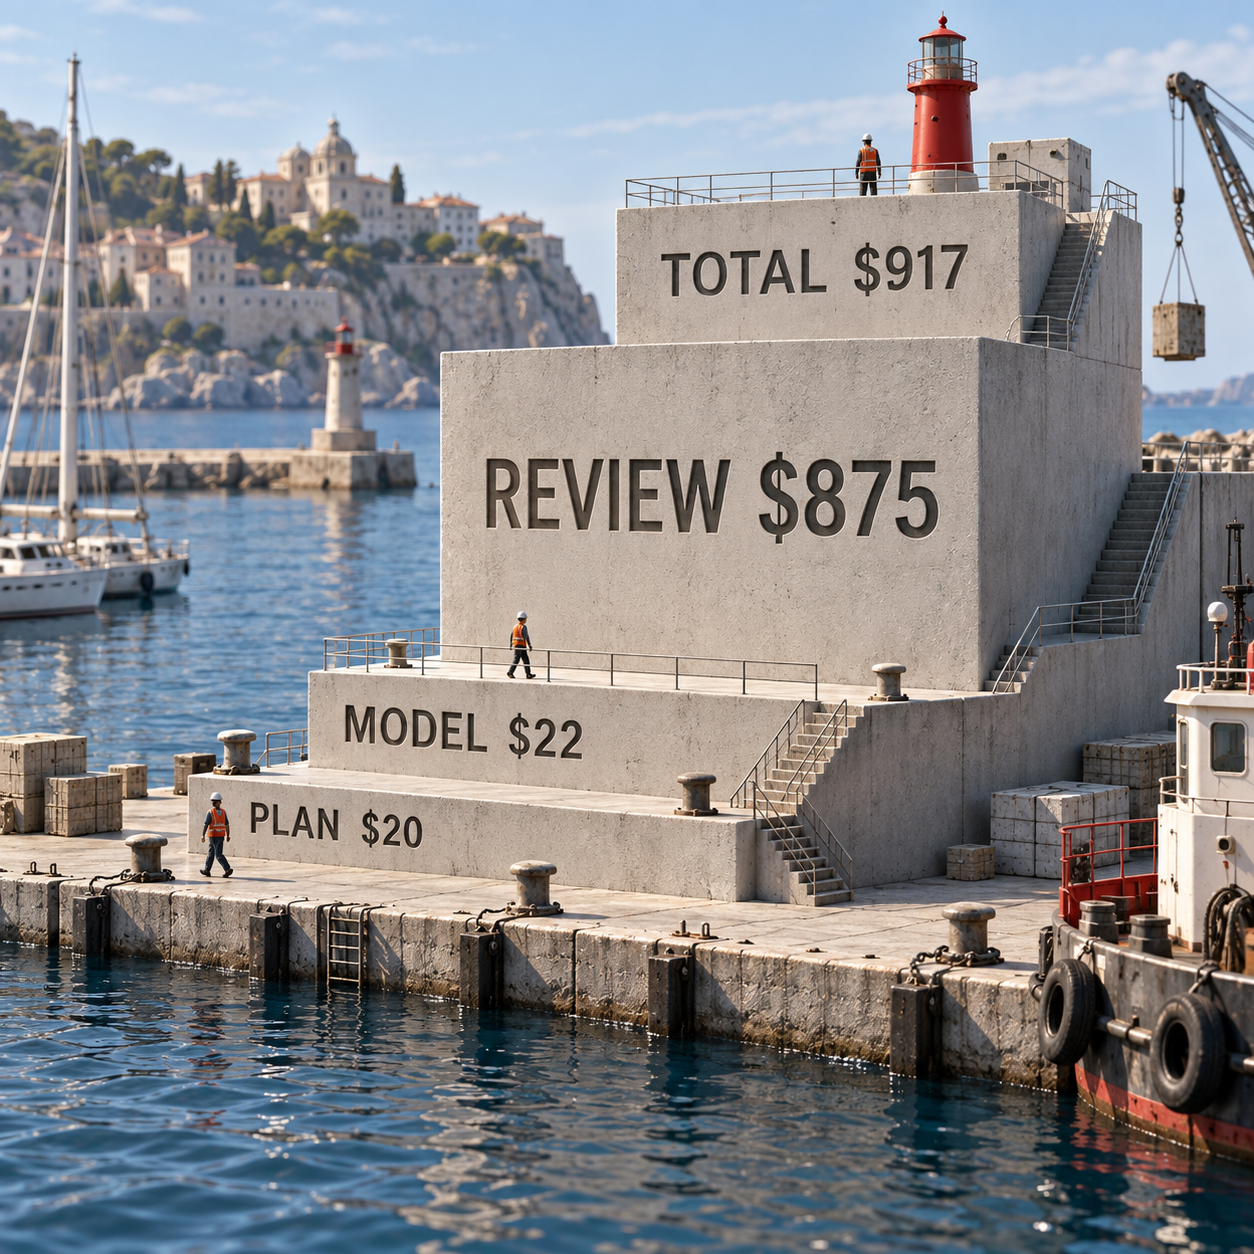
At the 10% retry assumption, recurring cost is about $0.1097 per completed job at 1,000 jobs and $0.0917 at 10,000, before setup. A buyer should compare those figures with the current process, then add the cost of wrong decisions that pass review, missed work, integration fees, and any Business quote.
The useful result is not that MindStudio is cheap. It is that model cost is almost irrelevant in this particular design. Reducing the sampled review rate, review time, or correction rate changes the business case far more than shaving a fraction from token price. That is also the lesson in the broader AI marketing agent cost analysis: measure accepted outcomes, not impressive activity.
MindStudio Limitations That Change the Buy
MindStudio has a credible solo plan and a capable workflow surface, but five specific limits can reverse the decision.
1. Team pricing is not publicly computable
Individual is explicitly "Just me," while Business is custom. A five-collaborator buyer cannot calculate the shared workspace from the pricing page alone. Ask sales for the platform fee, included usage, overage rules, collaborator definition, support, data controls, renewal terms, and deployment options in writing.
2. Unlimited runs still carry usage and labor
Individual and Business list unlimited runs, but model and media usage remain separate. A failed or low-quality run can also create review and correction work. Budget per accepted outcome, not per trigger. Spend limits help contain damage; they do not prove the workflow is economical.
3. Free has no operating margin at exactly 1,000 jobs
Free includes 1,000 monthly runs. A target of 1,000 completed jobs consumes the full allowance before tests, retries, or manual reruns. The plan is useful for learning and a small trial, but the numerical match between allowance and desired outcomes is not production headroom.
4. Custom dependencies can add a five-second floor
Simple JavaScript or Python can stay in the fast Sandbox, but installing packages requires the Virtual Machine path. The public function documentation says VM startup and package installation take at least around 5 seconds, compared with typical Sandbox results under 50 milliseconds. That can be a decisive latency penalty in interactive work.
5. Public capability pages are not reliability evidence
The docs show blocks, evaluations, budgets, and deployment choices. This run did not execute a workflow, inspect billed usage, measure latency, provoke an integration failure, or retain corrected outputs. A buyer cannot infer production reliability from the catalog, this article, or a polished demo. The 20-record trial is the evidence step.
- Individual gives one builder a low fixed platform fee with unlimited agents and runs.
- The model catalog and per-model rate pages make token scenarios reproducible.
- Visual blocks, structured End output, checkpoints, and evaluations support bounded workflows.
- HTTP, database, CRM, messaging, and automation-platform blocks can keep AI judgment inside deterministic edges.
- Spend limits and per-Agent cost visibility support early budget control.
- Business pricing is hidden, so a shared team's full bill is unknown before a quote.
- Usage, review, correction, and connected-service charges survive the "unlimited runs" label.
- Free's 1,000-run allowance leaves no margin for 1,000 completed jobs plus testing or retries.
- Custom dependencies may force a materially slower VM execution path.
- The public evidence cannot answer account-level reliability, support, or correction-rate questions.
Is MindStudio the best no-code AI agent builder?
MindStudio is the best fit in this shortlist when one builder owns a bounded, recurring AI-native workflow, the inputs and outputs can be specified, and a small amount of human review is acceptable. It is not the default for every automation, and the public Business boundary prevents a team verdict without a quote.
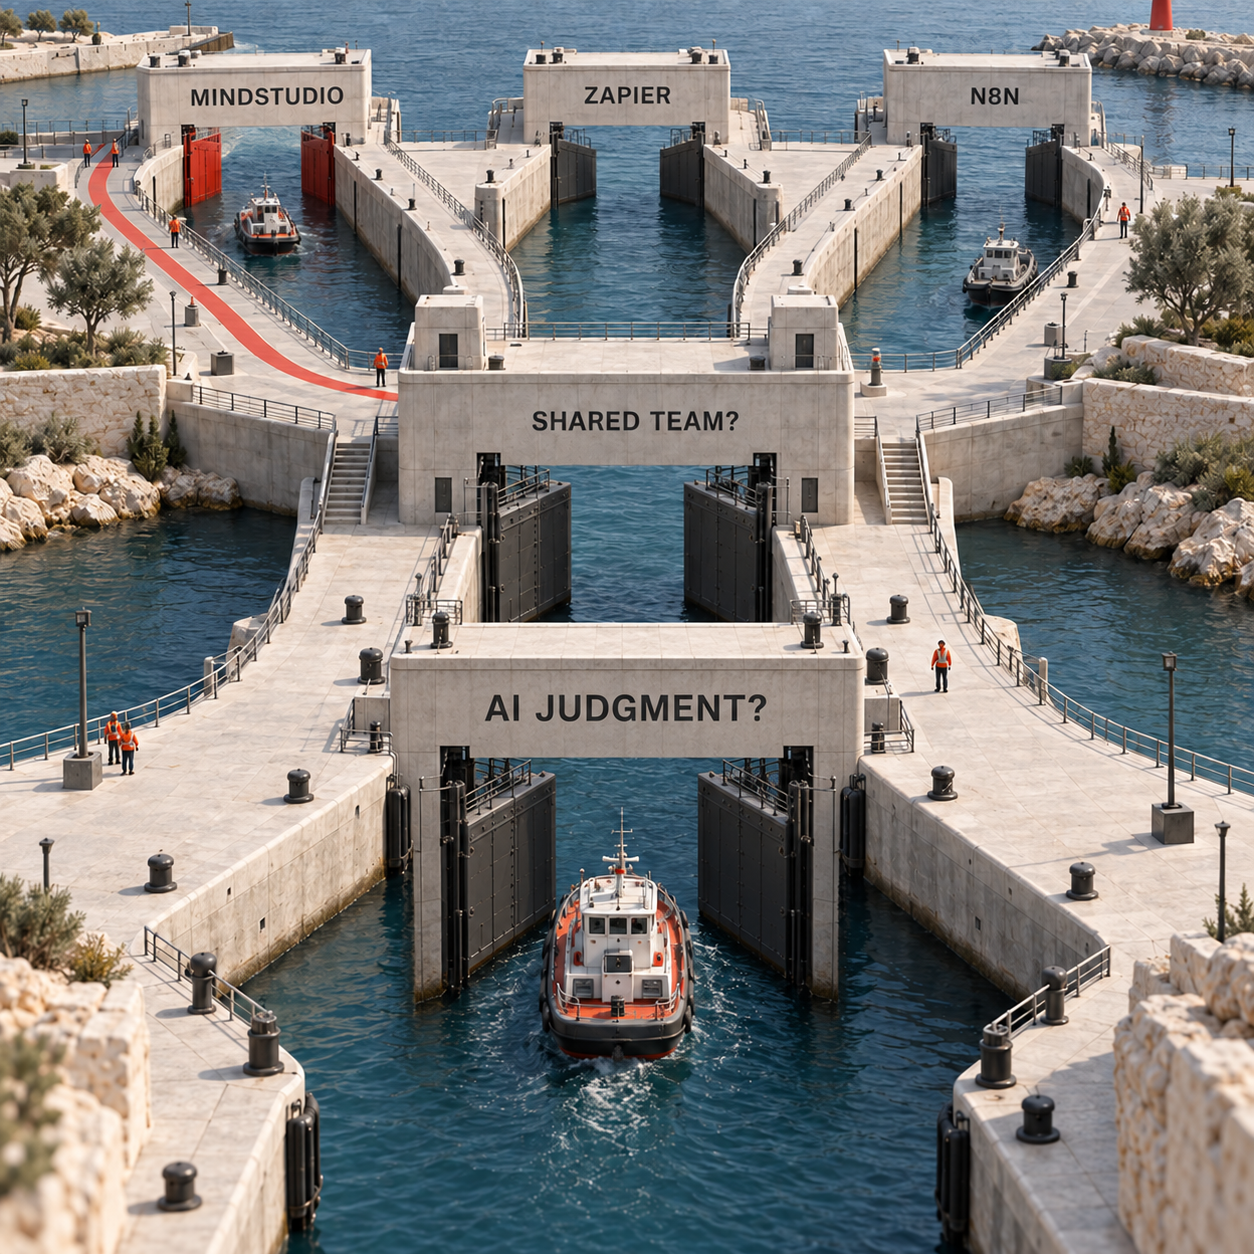
The explicit decision rule is simple:
- Choose MindStudio Individual when one builder needs model-driven classification, generation, analysis, or review inside a visible workflow, and the full cost per accepted job beats the current process.
- Ask for MindStudio Business pricing before building when two or more collaborators need one governed workspace. Do not discover the quote after the workflow has become difficult to move.
- Choose Zapier or Make when removing the model step leaves the job intact.
- Choose n8n when self-hosting, code ownership, custom execution, or deeper retry control matters more than the easiest visual AI setup.
- Choose Relevance AI when the main requirement is a managed workforce of several agents rather than one bounded workflow.
If the job needs a persistent browser, terminal, files, and a durable working environment rather than a finite workflow, compare persistent AI workspaces instead. That is a different runtime question.
The Monday move: a 20-record trial
MindStudio should earn expansion through retained evidence, not a successful preview. Use synthetic data and one read-only workflow first.
Define the accepted packet
Write the required inputs, closed categories, exact End fields, review reasons, and failure result. Keep external writes disabled. Set the maximum recurring cost per accepted job before the build starts.
Create 20 synthetic records
Cover ordinary requests, missing fields, ambiguous intent, money, legal language, deletion, identity conflict, duplicates, malformed text, and one case that should fail closed. These are test inputs, not customer data.
Run and retain every result
For each record, save the output, model and settings, billed usage, run status, failure, retry, and elapsed review minutes. A screenshot of a good output is not enough.
Correct and turn corrections into tests
Record the expected category and summary changes. Add each meaningful correction to the evaluation set, then rerun the fixed set before changing a model or prompt.
Apply the decision rule
Calculate cost per accepted result, including review and retries. Upgrade only if the workflow clears its accuracy, permission, latency, failure, and cost limits. If the trial needs a shared workspace, price Business before continuing.
Frequently Asked Questions
What is the best AI agent builder?
There is no best builder independent of the job. MindStudio is a strong choice for one builder creating a bounded visual AI workflow. Zapier fits deterministic SaaS automation, n8n fits technical or self-hosted execution, and Relevance AI fits a managed multi-agent workforce.
Is MindStudio free?
Yes. MindStudio Free is $0 per month plus usage and includes one agent with 1,000 runs per month. Tests and retries count because each Agent execution is a run.
Is AI agent builder free?
Some AI agent builders offer a free plan, but "free" rarely describes the full operating cost. Model usage, run allowances, connected services, setup, failure handling, and human review still need a budget.
Who are the big 4 AI agents?
There is no official or stable "big four" category for AI agents. For this buying job, MindStudio, Zapier, n8n, and Relevance AI form a useful shortlist because they represent visual AI workflows, deterministic automation, technical ownership, and multi-agent workforces respectively.
Which is the most powerful AI agent?
No agent is most powerful for every task. The better system is the narrowest one that completes a defined job, passes a fixed evaluation set, stays inside its permissions, exposes failures, and meets the cost ceiling.
What are the risks of using AI agents?
The main operating risks are wrong outputs, excessive permissions, prompt injection, duplicate actions, data exposure, model and integration cost drift, silent failures, and corrections that never become regression tests. Bound the model's authority and put deterministic checks around it.
What is the 30% rule in AI?
The phrase is not a MindStudio feature, plan, or pricing rule, and it is used ambiguously in AI commentary. Do not use it as a purchasing criterion without the original source, definition, and measurement method.
What did Bill Gates warn about AI?
A public figure's broad warning does not decide whether this workflow is safe or economical. For a MindStudio purchase, translate general AI-risk concerns into limited permissions, human checkpoints, retained logs, a tested failure path, and a clear stop rule.
What are the disadvantages of AI agents?
AI agents add probabilistic behavior, evaluation work, model charges, review labor, permission risk, and failure recovery to a process. If the job does not need model judgment, ordinary automation is usually simpler and more predictable.
Get the AI Business Workflow Audit Checklist
The free AI Business Workflow Audit Checklist helps you define one accepted outcome, its data boundary, failure cost, owner, and stop rule before buying another builder. Subscribe to get the next verified edition.
- Last Updated
- Sep 22, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Superwhisper vs Wispr Flow
Compare Superwhisper and Wispr Flow for business dictation: local and cloud settings, supported devices, correction work, and the full subscription cost.Sep 22, 2026Build
AI Automation Agency
Choose an AI automation agency by workflow fit, 90-day total cost, support, and ownership. Compare providers and check the pilot before signing.Sep 22, 2026Build
How to Use Claude Code Projects
Set up Claude Code Projects, check beta access, share context across cloud threads, and see which usage and local-tool limits matter.Sep 21, 2026Build
How to Use Jev
Use Jev to route a support ticket, read its confidence scores, and test when your workflow should hand the decision to a person.Sep 21, 2026Build
How to Make Claude Code Read AGENTS.md
Set up Claude Code's native AGENTS.md support, check which instruction file loads, and handle provider limits and existing CLAUDE.md files.Sep 19, 2026Build
How to Set Claude Code MCP Startup Timeout
Set the MCP startup wait for Claude Code jobs, distinguish connection waits from tool timeouts, and check required tools before work starts.Sep 17, 2026Build
How to Block AI Training Without Blocking Search
Use Cloudflare’s new training controls while keeping search access. Check migrated settings and separate crawler preferences from request blocking.Sep 16, 2026Build