How to Use GPT-6.1 Sol for Agents and Codex
Set up GPT-6.1 Sol in the Responses API and Codex, choose reasoning effort, price a real task, and know when Sol or Astra still fits.



Put GPT-6.1 Sol under the serious, repeatable work that is too demanding for a lightweight model but too frequent to send blindly to Astra. The practical setup is simple: use gpt-6.1-sol on the Responses API, start at medium, expose only the tools the job needs, and promote it only after fixed acceptance checks pass. A fresh Codex run for this guide created a small JavaScript utility, wrote four tests, and passed all four for a token-only API equivalent of $0.02816.
The Decision in One Minute
GPT-6.1 Sol is ready for API agents, Codex, and paid ChatGPT Work plans. It is not yet in ordinary Chat, and Ultrafast for this model has been announced but is not live.
The Standard API price is $2 per million input tokens and $10 per million output tokens. GPT-6 Astra is $10 and $50. OpenAI's launch announcement confirms the product rollout. For the fuller access and rate comparison, use GPT-6.1 Sol vs GPT-6 Sol; this guide stays focused on setup and operating choices.
What GPT-6.1 Sol Actually Is
Think of the GPT-6 family as an operations bench. Astra is the specialist you reserve for the hardest disputed case. GPT-6.1 Sol is the senior operator you can keep on repeated complex work. GPT-6 Sol is the compatibility hold for an older tool route. That framing is more useful than treating the new model as a universal default.
GPT-6.1 Sol accepts text and images, returns text, and carries a 1,050,000-token context window with up to 128,000 output tokens. Its real value for an agent is the tool surface. On Responses, it supports web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, tool search, and your own functions. The Responses tools guide explains how the API can keep the model in an agentic loop while it decides which allowed tool to call next.
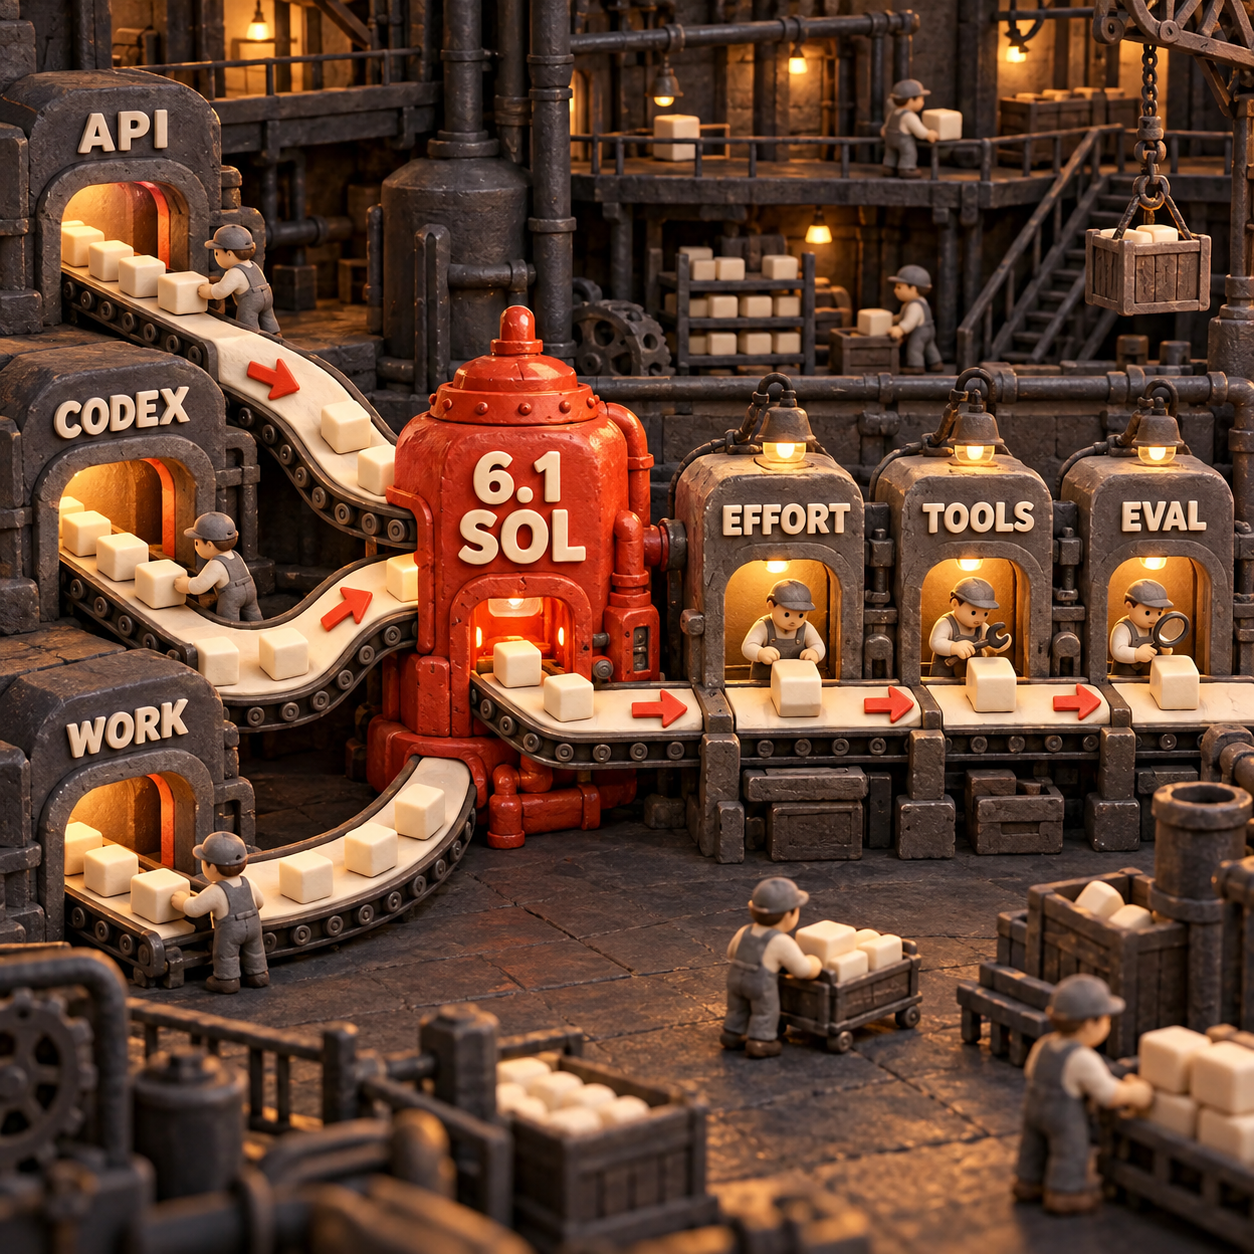
The constraint is just as important: GPT-6.1 Sol can use tools only through Responses. Chat Completions still accepts a plain request, but not a tool-calling one. If your current agent calls functions through Chat Completions, changing only the model ID is not a migration.
Set It Up on the Responses API
Start with one route and one acceptance check. Do not expose every tool because the model page lists it. A research worker may need web search and file search. A repository worker may need shell and patch access. An operations agent may need two functions and an approval boundary.
This is the smallest useful JavaScript request:
import OpenAI from "openai";

const client = new OpenAI();

const response = await client.responses.create({
  model: "gpt-6.1-sol",
  reasoning: { effort: "medium" },
  tools: [{ type: "web_search" }],
  input: "Find today's source for our target metric, cite it, and return one sentence."
});

console.log(response.output_text);
The model ID chooses Sol. The reasoning object sets how much work it can spend thinking. The tools array grants a capability, not a command to use it. The prompt still needs an outcome, evidence requirement, and stopping condition.
For an existing Chat Completions agent, treat the move as three changes: send the request to Responses, parse the typed output items, and decide how conversation state continues. The Astra Responses migration guide covers that plumbing in more depth.
Freeze five real tasks
Choose accepted examples from the workflow, including one failure case. Preserve the prompt, inputs, permissions, and success checks.
Start at medium
Use the default effort first. Change one variable at a time so a model win does not get confused with a prompt or tool change.
Grant the narrow tool set
Expose only the search, files, functions, shell, or computer controls required for that route. Keep write actions behind explicit policy and approval boundaries.
Record accepted-result cost
Capture fresh input, cached input, output, retries, tool fees, and whether the final state passed. A cheap failed run is not a saving.
Route by evidence
Keep Sol where it passes. Escalate only the hard residue to Astra. Leave incompatible routes on GPT-6 Sol until their caller changes.
Pick Reasoning Effort by the Job
medium is the right first setting for most agent work. GPT-6.1 Sol also accepts low, high, xhigh, and max. It rejects none and minimal, so an existing route using either needs a deliberate behavior and latency test. OpenAI's reasoning-effort guide gives the same progression from efficient execution to maximum reasoning.
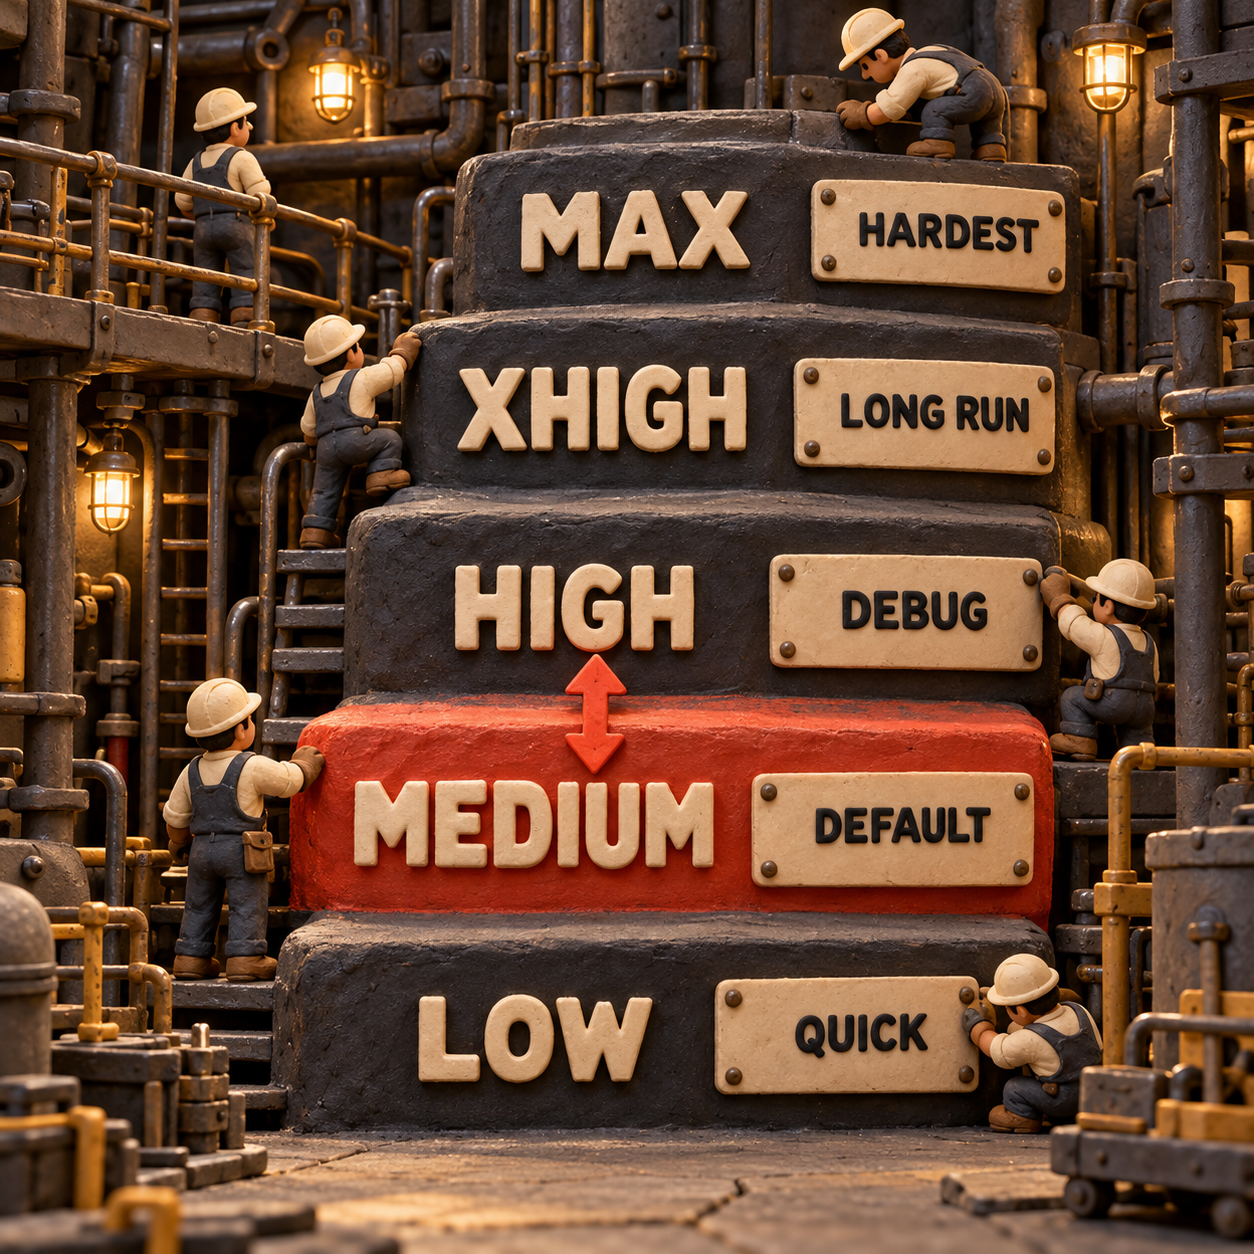
Three similar names describe different controls. max is an API reasoning effort. Ultra in Codex is a multi-agent mode that divides work across subagents. Ultrafast is a speed mode, and GPT-6.1 Sol support for it is still coming. Do not write an Ultrafast budget or launch plan as if it were available today.
A Real GPT-6.1 Sol Task and Its Token Cost
A small run exposes more useful economics than a headline price. GPT-6.1 Sol at low effort received this job in Codex: create a dependency-free JavaScript slugify function, add exactly four node:test cases for trimming, whitespace, punctuation, and mixed case, run the tests, and fix any failure.
The model created slugify.js and slugify.test.js, then ran node --test slugify.test.js. The result was 4 passed and 0 failed. Captured usage was 57,578 input tokens, of which 48,640 were cached, plus 542 output tokens. That means only 8,938 input tokens were billed at the fresh-input rate.
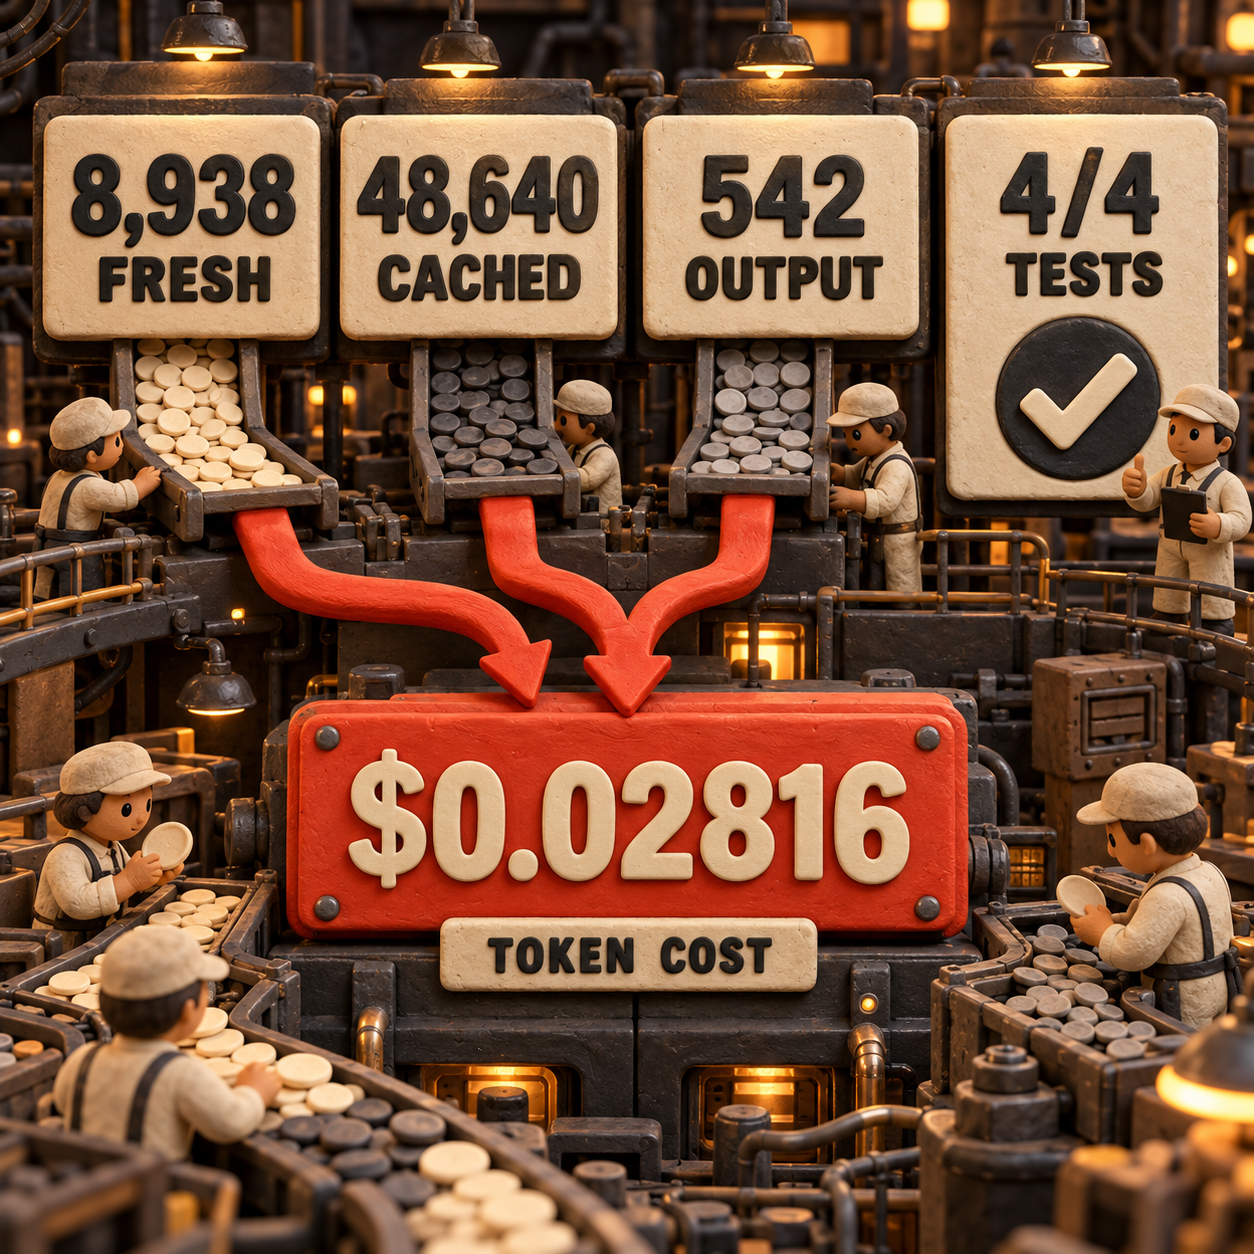
This was a real Codex run, so it consumed plan access rather than producing an API invoice. The $0.02816 figure is the exact token mix priced at GPT-6.1 Sol's published Standard API rates. It excludes any paid hosted-tool charge. At 10,000 identical runs, that mix would be $281.60 in model tokens. Holding the token mix constant, Astra's rates would make it $1,651.20. That Astra comparison is rate arithmetic, not a claim that Astra would use the same number of tokens.
The lesson is not that every small patch costs three cents. It is that the agent runtime, tool definitions, instructions, and history can outweigh the visible request. Measure the whole accepted run, including cached context and retries.
Seven Jobs Where Sol Makes the Most Sense
The teams that gain most are those with difficult work that repeats. Ranked by likely operating value:
Sol does not remove the need for approval design, deterministic checks, or observability. It gives those systems a more capable worker at a lower token rate than Astra.
Three Products Worth Building
1. A Sol Migration Test Bench for Coding Agents
This is the strongest opportunity. About 8,100 US searches a month target ai powered coding agent, with commercial intent. Teams do not need another vague model leaderboard. They need to know whether their repository tasks pass on gpt-6-sol, gpt-6.1-sol, and Astra under the same prompt, tools, and checks.
The smallest sellable version is a CLI plus CI action. A team supplies five JSON fixtures, a pass command, and the allowed tools. The test bench runs each model, records accepted results, latency, fresh and cached tokens, retries, and cost, then prints a promotion decision. The catch is that generic eval runners are easy to copy. The defensible part is the library of practical coding fixtures, integrations, and useful failure diagnoses.
2. An Effort and Cost Router for Operations Agents
About 1,000 US searches a month target ai workflow automation, with commercial intent and a $37.80 CPC. That is a market looking for completed work, not another chat box. A router could send bounded cases to low, normal multi-step work to medium, hard failures to high, and only the unresolved residue to Astra.
An MVP needs one queue, three effort policies, an acceptance function, and a spend dashboard. Sell it to operations teams already paying for several automations. The catch is false confidence: a cheap router that misclassifies one consequential case can erase its savings. The product needs replayable fixtures and a manual override from day one.
3. A Document-Agent Acceptance Layer
ai document analysis receives about 1,000 US searches a month and carries a $10.44 CPC. The product is not another upload-and-summarize screen. It is a verification layer that checks whether a document agent found every required field, preserved citations, reconciled totals, and escalated uncertainty.
The smallest version supports one recurring pack, such as vendor contracts or monthly finance PDFs, with a fixed schema and exception queue. GPT-6.1 Sol handles the repeated analysis; Astra receives only disputed or incomplete cases. The catch is domain specificity. A broad horizontal product will look generic, while a narrow pack with credible checks can earn trust.
When to Keep GPT-6 Sol or Pay for Astra
Keep GPT-6 Sol when compatibility is the constraint. It still accepts none reasoning and can call functions through Chat Completions when reasoning_effort is none. GPT-6.1 Sol cannot. A stable route that depends on those behaviors should move its API path and pass regression tests before it changes model.
Pay for GPT-6 Astra when the best result matters more than the token bill. OpenAI describes it as the most capable model for the most demanding reasoning, coding, computer use, research, and document creation. Use it for the ambiguous, high-value tail where your fixed evaluation shows a material win. At Standard rates, Astra is $10 input and $50 output per million tokens, versus $2 and $10 for GPT-6.1 Sol.
Use GPT-6.1 Sol for the large middle: serious Responses-based work that repeats and has a measurable success condition. OpenAI's launch evaluations report stronger results than GPT-6 Sol across several difficult workloads, but those are vendor-run results. Your own accepted-result rate is the release gate.
Limits That Change the Setup
GPT-6.1 Sol is not a replacement for every route. It has no none or minimal effort, no tool calling through Chat Completions, no fine-tuning, no audio or video input, and no ordinary Chat access at launch. Paid tools add their own charges. A request above 272,000 input tokens also moves the full request onto higher long-context rates, so a 1,050,000-token window should not be treated as free working space.
Ultrafast is the other honest limit. OpenAI announced up to 8x faster token generation than standard speed in Codex, but described it as coming. Until it appears for your account and client, plan with Standard or Fast and measure the latency you actually receive.
The Monday Move
Take five jobs your current agent completed recently: one easy success, two normal tasks, one tool-heavy task, and one known failure. Run the same fixtures on GPT-6.1 Sol at medium, without changing prompts or permissions. Record pass or fail, wall time, fresh input, cached input, output, retries, and tool charges.
Then route, do not declare a winner. Move bounded work down to low if it still passes. Test high only on failures that need deeper reasoning. Keep compatibility-bound callers on GPT-6 Sol. Send the expensive residue to Astra only when its acceptance gain justifies the price. That gives you a production decision this week, not a model opinion.
Frequently Asked Questions
What is GPT-6.1 Sol?
GPT-6.1 Sol is OpenAI's lower-cost model for complex coding, computer use, and professional work. Its API ID is gpt-6.1-sol, and tool calling runs through the Responses API.
What are AI coding agents?
AI coding agents can inspect a repository, edit files, run commands and tests, and report a result within permissions you define. The useful unit is a tested outcome, not generated code alone.
Does ChatGPT have a coding agent?
Yes. Codex is OpenAI's coding agent, and GPT-6.1 Sol is available in its paid-plan rollout. The model is also in ChatGPT Work, but it is not yet available in ordinary Chat.
Is GPT-6 Sol cheaper?
Not on fresh input or output: both Sol models list $2 input and $10 output per million Standard tokens. GPT-6.1 Sol has the lower cached-input rate. The full Sol comparison covers that pricing and compatibility split.
If you want one of these agent routes designed, tested, and shipped for your business, see AI production systems.
- Last Updated
- Sep 30, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
GPT-6.1 Sol vs GPT-6 Sol
Compare GPT-6.1 Sol with GPT-6 Sol on cache costs, coding evidence, and the reasoning and tool-call changes that affect an upgrade.Sep 30, 2026AI
How to Use Claude Sonnet 5.5
Start using Claude Sonnet 5.5, choose an effort level, and fix the thinking and tool-call settings that can break an existing API workflow.Sep 28, 2026AI
Jev vs GLM-5.3-Flash
Compare Jev with GLM-5.3-Flash through Privatemode Decisions for support routing, image inputs, latency and cost per correct decision.Sep 27, 2026AI
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI
GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI