GPT-6.1 Sol vs GPT-6 Sol
Compare GPT-6.1 Sol with GPT-6 Sol on cache costs, coding evidence, and the reasoning and tool-call changes that affect an upgrade.



GPT-6.1 Sol vs GPT-6 Sol is a test-first upgrade: move cache-heavy Responses API agents to GPT-6.1 Sol, but keep GPT-6 Sol while a Chat Completions tool caller or reasoning none still blocks migration. Both cost $2 input and $10 output per million tokens; only cached input falls, from $0.20 to $0.10.
GPT-6.1 Sol vs GPT-6 Sol: Which One Should You Pick?
Pick GPT-6.1 Sol for a compatible Responses API workload that reuses long prompt prefixes or needs a stronger candidate for coding, computer use, document work, and multi-step business tasks. Keep GPT-6 Sol while your application depends on Chat Completions function calling or reasoning_effort: none. Those are not minor configuration differences. They are the line between changing a model ID and changing the request path around it.
The decision splits cleanly by situation:
- Existing Responses API agent at medium effort or above: test GPT-6.1 Sol now. It offers the lower cached-read rate and the stronger launch-day capability signal.
- Chat Completions function caller: do not swap the model ID first. Move the tool path to Responses, regression-test it, then compare models.
- Workload using
nonereasoning: stay on GPT-6 Sol until you can accept at leastlow, withmediumas GPT-6.1 Sol's default. - Mostly fresh input and output: there is no token-price saving. Both models charge the same fresh-input, cache-write, and output rates, so capability must earn the switch.
The explicit decision rule is simple: switch only when GPT-6.1 Sol improves accepted work after the caller passes its compatibility check. A lower cache rate is useful, but a failed tool call, changed reasoning floor, or extra retry can consume the saving quickly.
GPT-6 Sol vs 6.1 Sol Pricing
GPT-6.1 Sol wins the pricing category only when your requests produce cached reads. The fresh-input, cache-write, and output prices are unchanged.
I verified the rates against OpenAI's live GPT-6.1 Sol model page and GPT-6 Sol model page on September 30, 2026.
Normalized per 1,000 tokens, either model costs $0.002 for fresh input, $0.0025 for a cache write, and $0.01 for output. A cached read costs $0.0001 on GPT-6.1 Sol and $0.0002 on GPT-6 Sol. There is no volume point where GPT-6 Sol becomes cheaper on these rates: every nonzero cached-read token shifts the token bill toward GPT-6.1 Sol, while zero cached reads produce a tie.
GPT-6.1 Sol Cache Pricing
The cached-input rate is 50% lower, but total task cost falls by less because only one component changed. Cached input means an unchanged prompt prefix that the model can reuse. OpenAI's prompt-caching guide says the prefix must reach 1,024 visible input tokens for GPT-5.6 and later, and maintaining a session does not guarantee a hit.
The cache-write line also needs careful reading. A write is an alternative input-token charge, not an extra fee layered on top of another input charge. Both models charge $2.50 per million written tokens. GPT-6.1 Sol changes the later read price, not the cost of creating the reusable prefix.
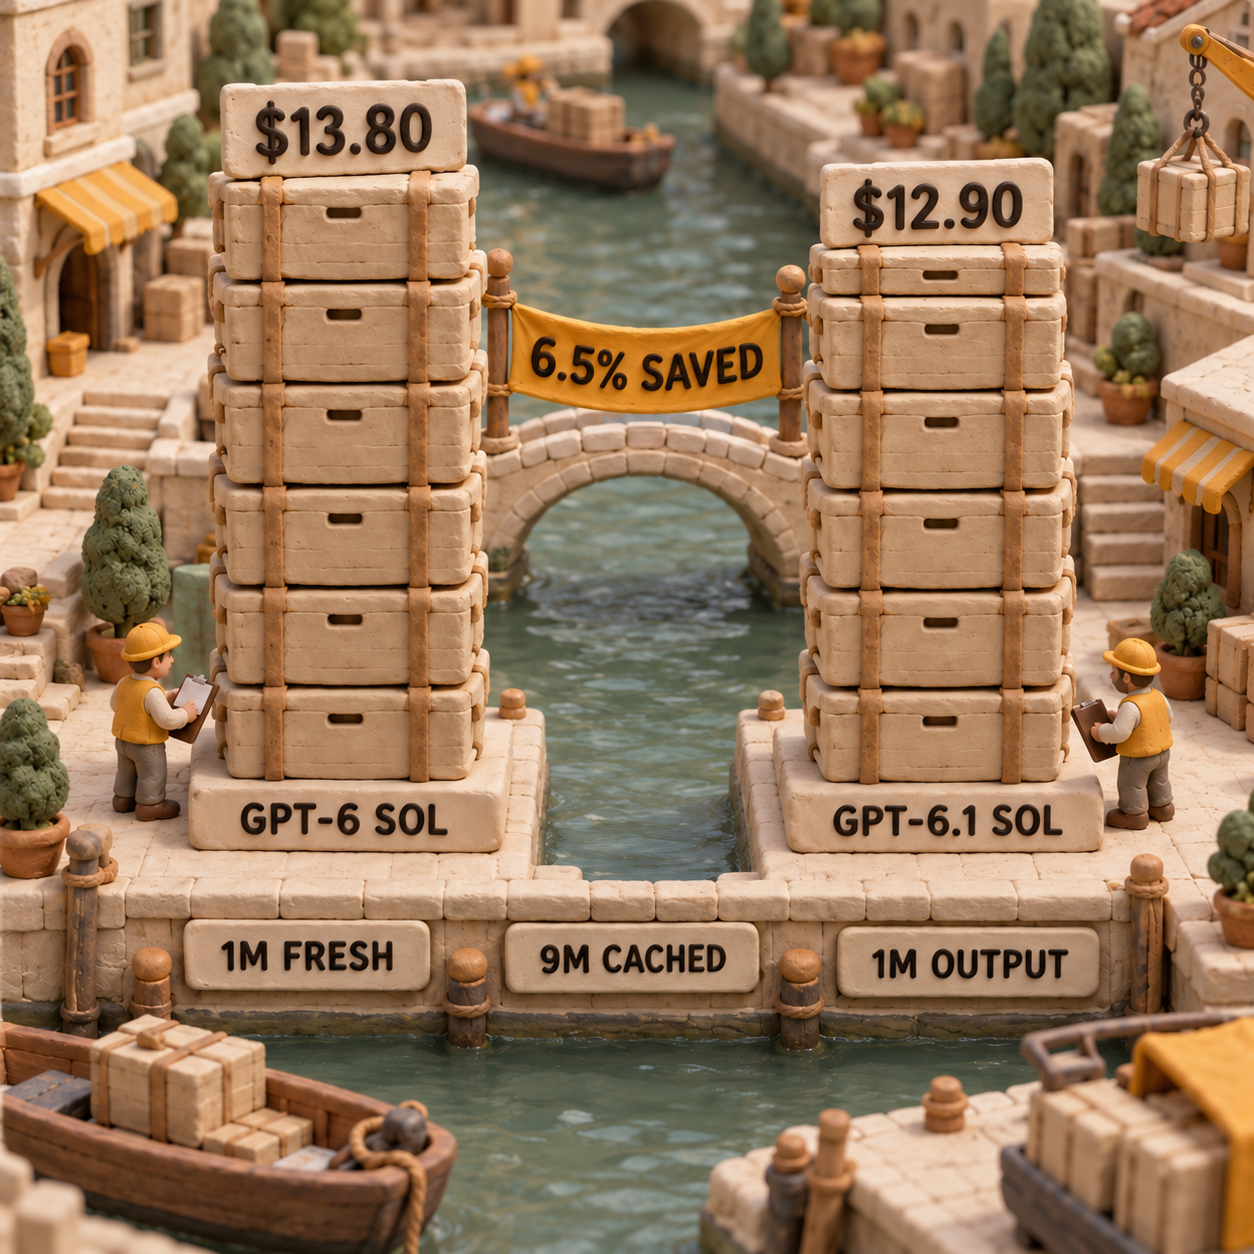
Consider a short-context batch with 1 million fresh input tokens, 9 million cached input tokens, and 1 million output tokens:
- GPT-6 Sol: (1 x $2.00) + (9 x $0.20) + (1 x $10.00) = $13.80
- GPT-6.1 Sol: (1 x $2.00) + (9 x $0.10) + (1 x $10.00) = $12.90
That is a $0.90 saving, or 6.5%, before cache writes and tool charges. This is calculated pricing, not an executed workload or observed invoice.
The illustration also assumes each request stays at or below 272,000 input tokens. Above that threshold, both model pages say the full request is billed at 2x input and cache rates and 1.5x output. A batch can total millions of tokens without crossing the threshold if it is made of smaller requests; the threshold applies per request.
For an existing agent, start by measuring cached_tokens and cache-write tokens instead of estimating them from prompt length. The GPT-6 prompt-caching diagnostics guide explains how to separate a weak cache-hit rate from a model-price problem.
Winner: GPT-6.1 Sol for cache-heavy work. Tie for workloads without cached reads.
GPT-6.1 Sol Benchmarks
GPT-6.1 Sol wins the launch-day capability category, but the evidence is OpenAI's, not an independent head-to-head test. That distinction matters because system prompts, tool access, reasoning effort, and retry policy can change the result and its cost.
OpenAI's launch report gives five useful signals against GPT-6 Sol:
- Coding: GPT-6.1 Sol beat GPT-6 Sol's best DeepSWE v1.1 score by 6.4 percentage points at lower reasoning effort and cost.
- Business workflows: it scored 4.8 percentage points higher on AutomationBench 1.0.6 at the same setting.
- Computer use: it gained 7 percentage points on the OSWorld 2.0 offline set at maximum effort, at less than half the cost per task.
- Scientific workflows: it more than doubled GPT-6 Sol's Terminal-Bench Science 0.1 score at maximum effort, again at less than half the cost per task.
- Factuality: on deliberately difficult prompts at low effort, answers containing at least one factual error fell from 11.4% to 7.7%, an approximately 32% relative reduction.
Those are promising deltas, not a universal percentage improvement. OpenAI notes that its GPT evaluations ran in its research environment or through its API and may differ from production ChatGPT because the prompts, tools, and effort settings can differ. No like-for-like independent benchmark for both exact model IDs was available on September 30, 2026, so an external score should not replace a workload-specific gate.
The mapping from benchmark to buyer is narrower than the headline. DeepSWE is relevant to a team giving an agent long-horizon repository work. AutomationBench is relevant to an operator chaining sales, marketing, support, finance, or HR tools. OSWorld matters when the model controls computer applications. None of them proves that a two-step support classifier, a short copy edit, or your private codebase improves.
Winner: GPT-6.1 Sol on current capability evidence. Confidence: vendor-reported until independent exact-pair results arrive.
GPT-6.1 Sol vs GPT-6 Sol Specs
The models share almost the entire operational envelope. Both list a 1,050,000-token context window, a 128,000-token maximum output, text and image input, text output, structured outputs, streaming, and the same Responses tool surface. Neither supports audio or video input on these model pages, and neither supports fine-tuning.
GPT-6.1 Sol moves the documented knowledge cutoff from April 20 to April 30, 2026. Ten days is not a migration case. Retrieval quality, private context, and tool correctness will dominate that small date difference in most production systems.
GPT-6.1 Sol: The New Default Candidate
GPT-6.1 Sol is OpenAI's newer complex-work model under the exact API ID gpt-6.1-sol. It supports low, medium, high, xhigh, and max reasoning, with medium as the default. Its standard rates are $2 fresh input, $0.10 cached input, $2.50 cache write, and $10 output per million tokens.
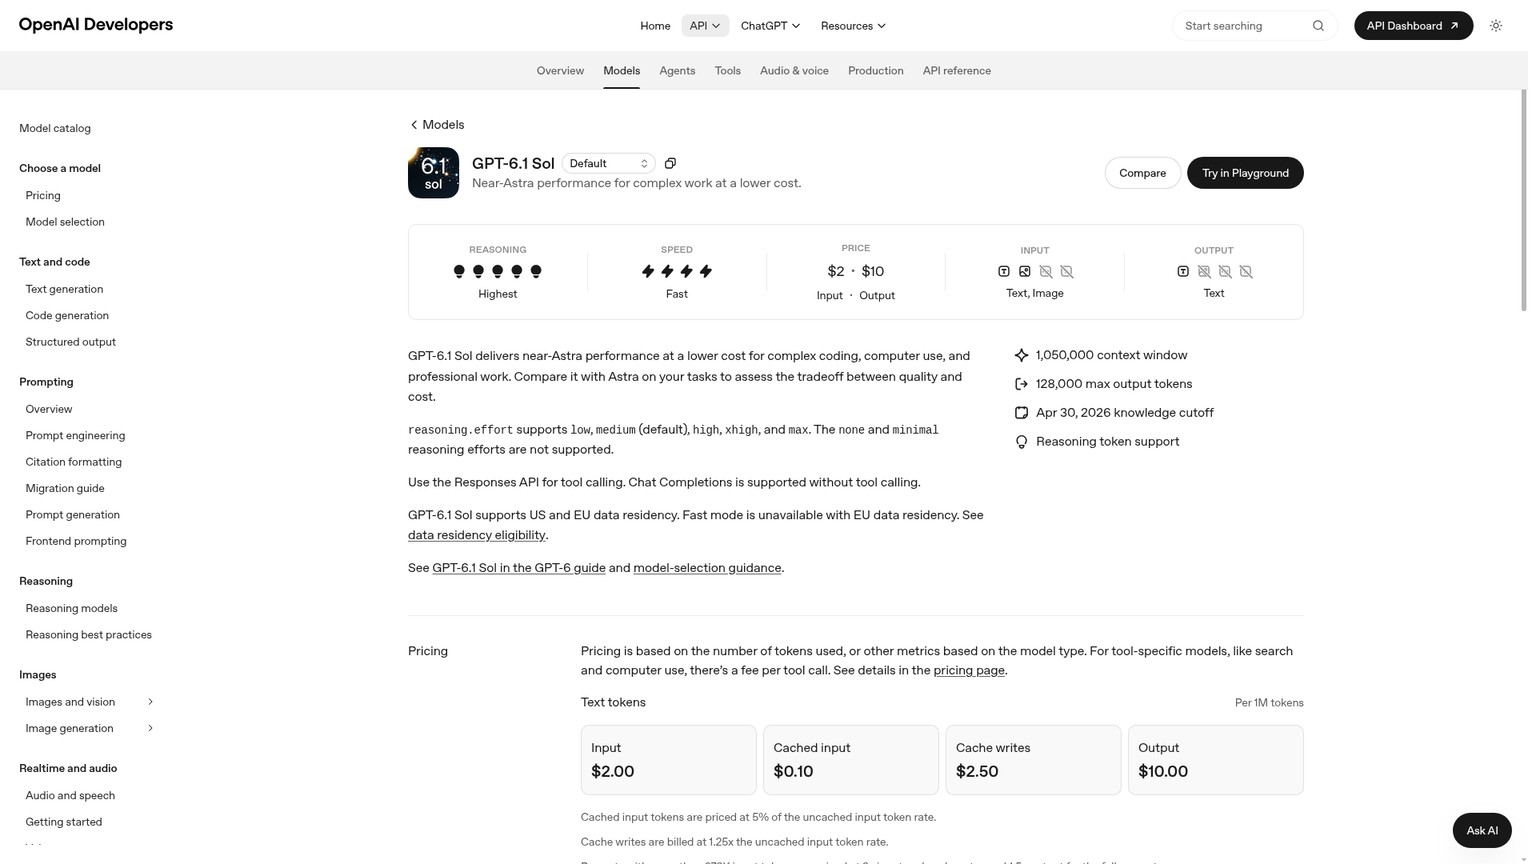
The model page lists web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search through Responses. Choose it when that API path already fits and the task resembles the stronger coding, document, computer-use, or workflow signals. Skip an immediate default change when you still need an independent acceptance test or depend on a removed reasoning setting.
GPT-6 Sol: The Compatibility Hold
GPT-6 Sol remains available as gpt-6-sol. It supports none, low, medium, high, xhigh, and max reasoning. Its standard rates remain $2 fresh input, $0.20 cached input, $2.50 cache write, and $10 output per million tokens.
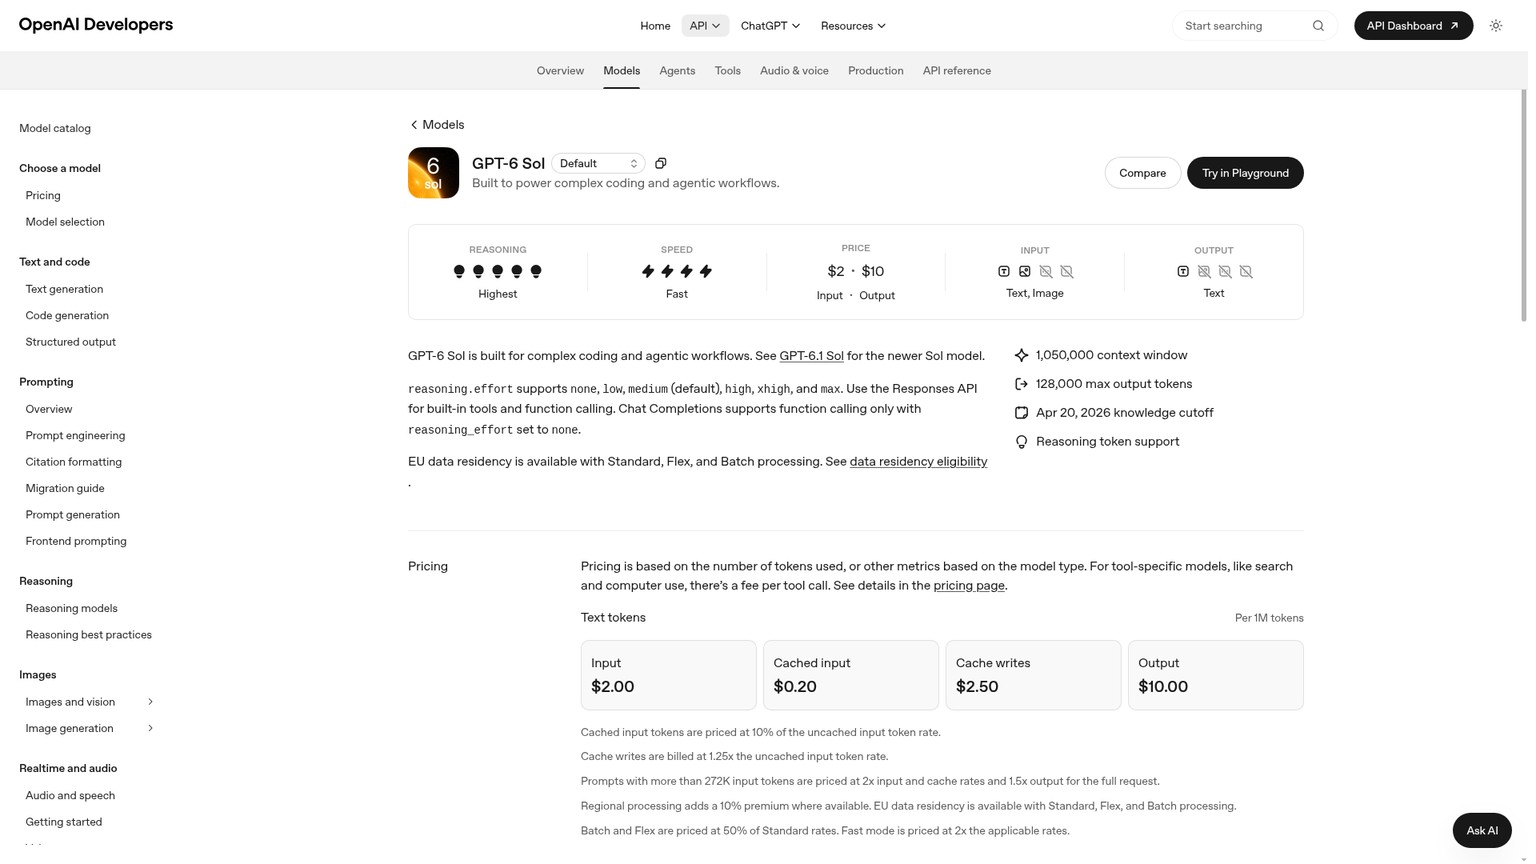
Its Responses tool surface matches the newer model's documented list. The practical difference is the legacy escape hatch: Chat Completions can call functions when reasoning effort is none. That makes GPT-6 Sol the temporary winner for a stable application that has not moved its tool loop to Responses. It is not the cheaper model once cached reads appear.
Winner: tie on context, output limit, modalities, and documented Responses tools. GPT-6.1 Sol wins recency; GPT-6 Sol wins legacy compatibility.
GPT-6.1 Sol Upgrade: The Compatibility Check Comes First
The GPT-6.1 Sol upgrade can be a one-line model change only for a caller that already uses Responses, avoids none and minimal, and treats model output as behavior to validate rather than a drop-in contract. Everyone else has migration work before model evaluation.
GPT-6.1 Sol Tool Calling
GPT-6.1 Sol tool calling requires the Responses API. Chat Completions remains available for plain model calls, but not for tool calling. GPT-6 Sol is different: its model page allows Chat Completions function calling only with reasoning_effort set to none.
Inspect every existing Chat Completions function caller before changing the model ID. The migration cost can include request construction, conversation state, tool-result handling, response parsing, retry logic, tracing, and cache-prefix stability. A wrapper that hides the endpoint does not remove those differences; it only moves where you must test them.
Reasoning is a second contract. GPT-6.1 Sol does not support none or minimal. If a production route uses none for lower latency, deterministic tool selection, or cost control, the closest valid setting is not automatically behaviorally equivalent. Move the route to a supported effort and run the same acceptance checks before comparing speed or spend.
Who Should Not Switch Yet
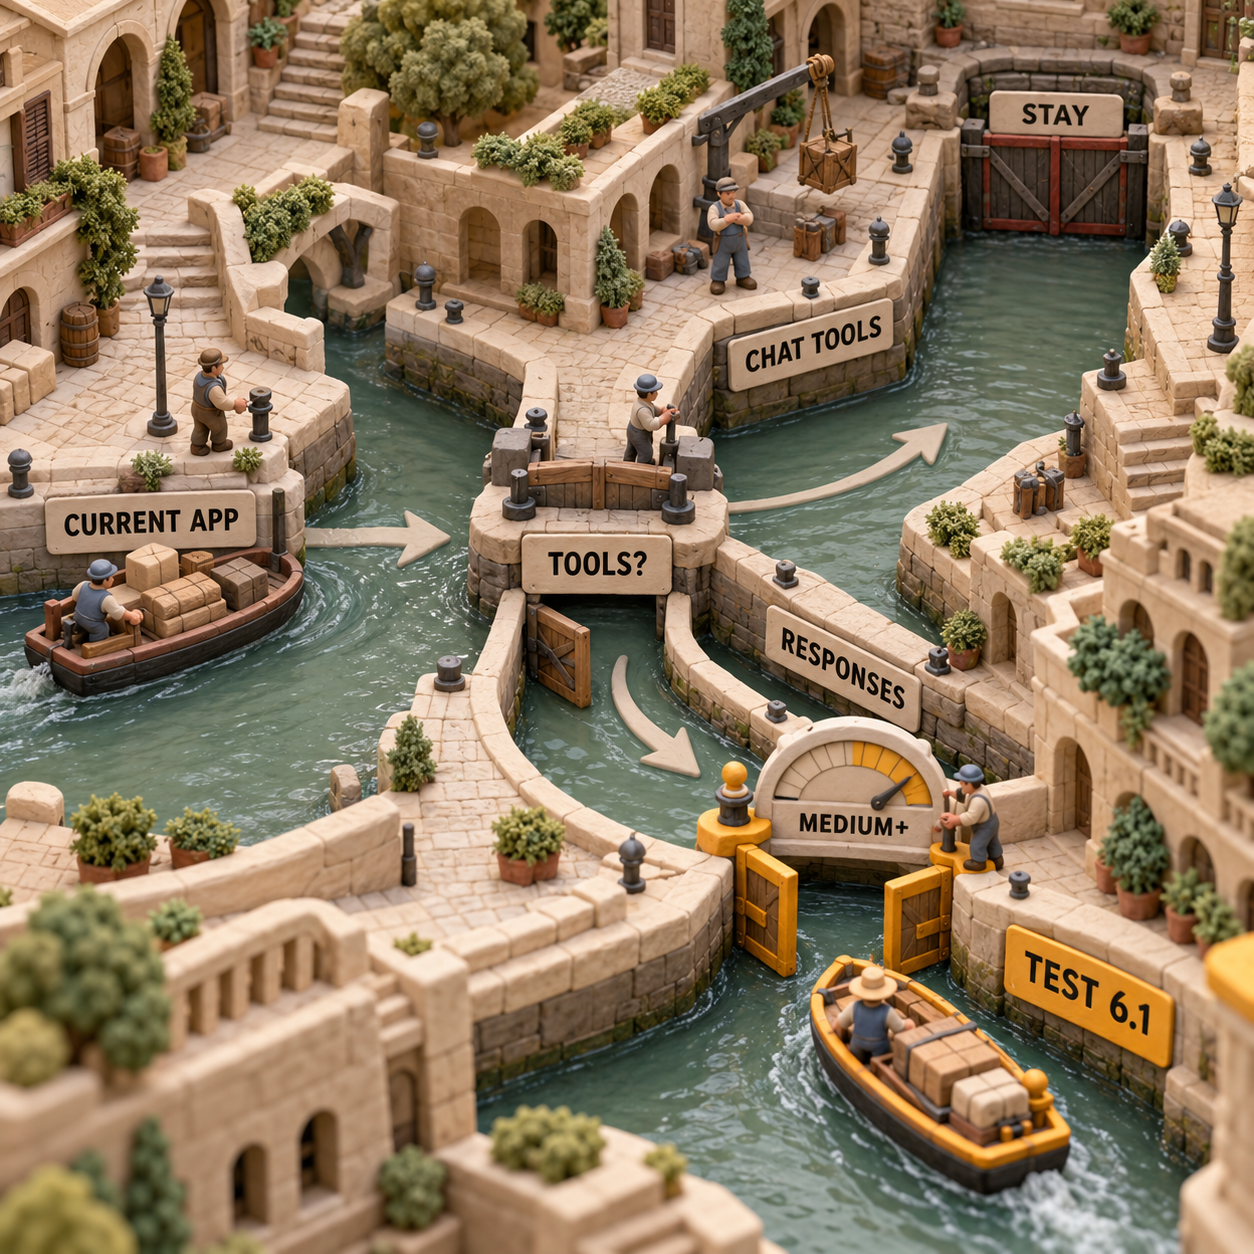
Do not switch the default yet if any of these are true:
- Tool calls still run through Chat Completions.
- A route explicitly uses
noneorminimalreasoning. - Most billed tokens are fresh input and output, so cache savings are immaterial.
- The current model already passes the business acceptance checks and no GPT-6.1 Sol capability gain has been measured on the same fixtures.
- A regulated deployment needs a separate review of processing mode, data residency, logs, and changed model behavior.
This is workflow lock-in rather than permanent vendor lock-in. The model names are close, but the caller may be coupled to an endpoint, reasoning floor, response shape, and tool loop. Price that validation work as part of the upgrade.
Winner: GPT-6 Sol for an incompatible caller today. GPT-6.1 Sol after the caller and fixtures pass.
Run Five Fixed Fixtures Before You Change the Default
Use five fixed fixtures on both exact model IDs at medium effort, with identical prompts, tools, context, output limits, and acceptance checks. This is a proposed evaluation design, not a benchmark executed for this article.
Fix a repository bug
Give both models the same failing test, repository state, and allowed tools. Accept only a patch that fixes the target failure without breaking the existing suite.
Refactor across files
Use a bounded cross-file change with a build, lint, and test gate. Reject a polished explanation if the repository check fails.
Route a support case
Provide the same policy, customer message, and routing tools. Require the correct queue, priority, structured fields, and no unsupported action.
Answer with policy evidence
Ask for a customer-facing answer grounded in the same document set. Accept only the required conclusion, cited evidence, and escalation behavior.
Complete a business workflow
Use the same multi-step lookup and update task with a permission boundary. Require the correct tool sequence, final state, and refusal of any unauthorized step.
Record accepted outputs, end-to-end latency, fresh input, cached input, reasoning and output tokens, tool charges, and retries. Then calculate total cost per accepted result, not cost per first response:
effective cost per accepted result = total model, retry, and tool spend / accepted outputs
That denominator can reverse the token-price story. A model that saves $0.90 on a cache-heavy batch but introduces one extra failed tool run may cost more. A model that costs the same on fresh tokens but removes retries may be the cheaper production choice.
Availability Is Split Across API, Work, Codex, and Chat
GPT-6.1 Sol is live through the API as gpt-6.1-sol and, according to OpenAI's launch announcement, in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users. It was not available in ordinary Chat at launch.
OpenAI also says GPT-6.1 Sol Ultrafast is forthcoming, with up to 8x faster token generation than standard speed in Codex. The announcement does not publish an Ultrafast price, so do not build a cost forecast from an unofficial multiplier.
API usage is billed separately from a ChatGPT subscription. Access in Work or Codex does not turn the $2 and $10 API rates into an included allowance for a production application.
Frequently Asked Questions
What is GPT-6 SOL?
GPT-6 Sol is OpenAI's model for complex coding and agentic workflows under the API ID gpt-6-sol. GPT-6.1 Sol is the September 29, 2026 upgrade, with a lower cached-input rate and a different reasoning and tool-calling compatibility envelope.
How much better is GPT Sol?
There is no single honest percentage. OpenAI reports GPT-6.1 Sol gains of 6.4 percentage points on DeepSWE, 4.8 points on AutomationBench, and 7 points on OSWorld against GPT-6 Sol in specified settings. Your fixed workload should decide whether those gains transfer.
Which GPT version is better?
GPT-6.1 Sol is the better model to test for compatible coding and business-agent work. GPT-6 Sol is the better temporary runtime when you still require Chat Completions tool calls or none reasoning.
What are the features and pricing of OpenAI's new GPT-6 Sol and Luna models?
That is the earlier family decision. The GPT-6 Sol vs Luna comparison covers their routing roles and current token economics; this page isolates whether an existing Sol workload should move to GPT-6.1 Sol.
Which GPT is better, Sol, Terra or Luna?
There is no universal family winner. Match the model to task difficulty, latency, and accepted-result cost, then evaluate the exact IDs you plan to deploy. This comparison supports a Sol-to-Sol upgrade decision, not a Terra or Luna verdict.
Is GPT-6 Sol cheaper?
No on the documented Standard token rates. GPT-6 Sol ties GPT-6.1 Sol on fresh input, cache writes, and output, while GPT-6.1 Sol is cheaper on cached input at $0.10 versus $0.20 per million tokens.
Is it worth to pay $20 for ChatGPT?
That is a consumer-subscription decision, not an API-model price comparison. GPT-6.1 Sol was available in Work and Codex on the listed paid plans at launch, but not in ordinary Chat, and API usage is billed separately.
Is GPT-5.6 Sol better than GPT-5?
That older comparison does not determine this upgrade. For a current deployment, evaluate GPT-6.1 Sol and GPT-6 Sol under the exact API path, reasoning effort, tools, and acceptance checks the application uses.
How good is GPT-6?
GPT-6 capability varies by model, task, effort, and tool setup. GPT-6.1 Sol has the stronger vendor-reported evidence than GPT-6 Sol on several difficult evaluations, but a fixed private eval is the production answer.
GPT-6.1 Sol vs GPT-6 Sol weight
OpenAI's live model pages do not publish parameter counts or downloadable weights for either model. Compare the documented limits, prices, API behavior, and measured task outcomes instead.
The Monday Move
Start with the caller, not the model picker. Search your code and workflow configuration for Chat Completions function calls and reasoning_effort values of none or minimal. If either appears, scope that migration before changing the default.
Then run the five fixed fixtures against gpt-6-sol and gpt-6.1-sol at medium effort with the same tools and checks. Compare accepted-result cost, latency, cache usage, and retries. Promote GPT-6.1 Sol on the routes where it wins; leave the rest on GPT-6 Sol until the compatibility or outcome gap closes.
Get the Claude Code and Codex setup checklist before you change a production model route.
- Last Updated
- Sep 30, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

How to Use Claude Sonnet 5.5
Start using Claude Sonnet 5.5, choose an effort level, and fix the thinking and tool-call settings that can break an existing API workflow.Sep 28, 2026AI
Jev vs GLM-5.3-Flash
Compare Jev with GLM-5.3-Flash through Privatemode Decisions for support routing, image inputs, latency and cost per correct decision.Sep 27, 2026AI
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI
GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI