Perplexity Fast Search vs Default
Compare Perplexity Fast Search with default web search on price, latency, source coverage, and the API setting your agent should use.




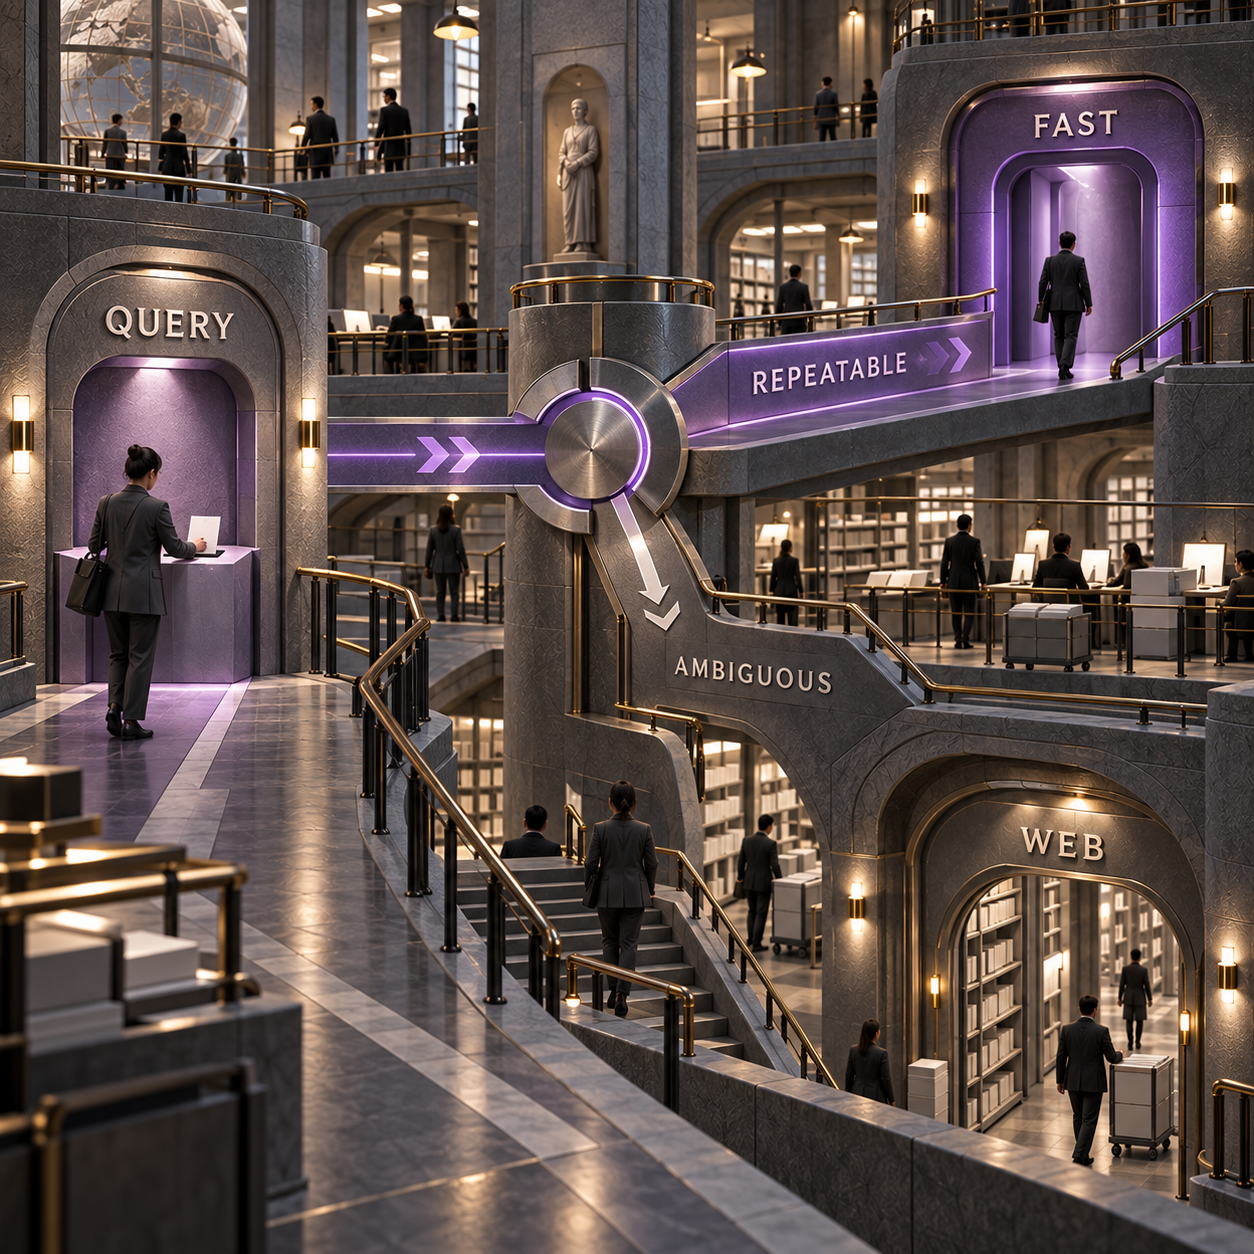
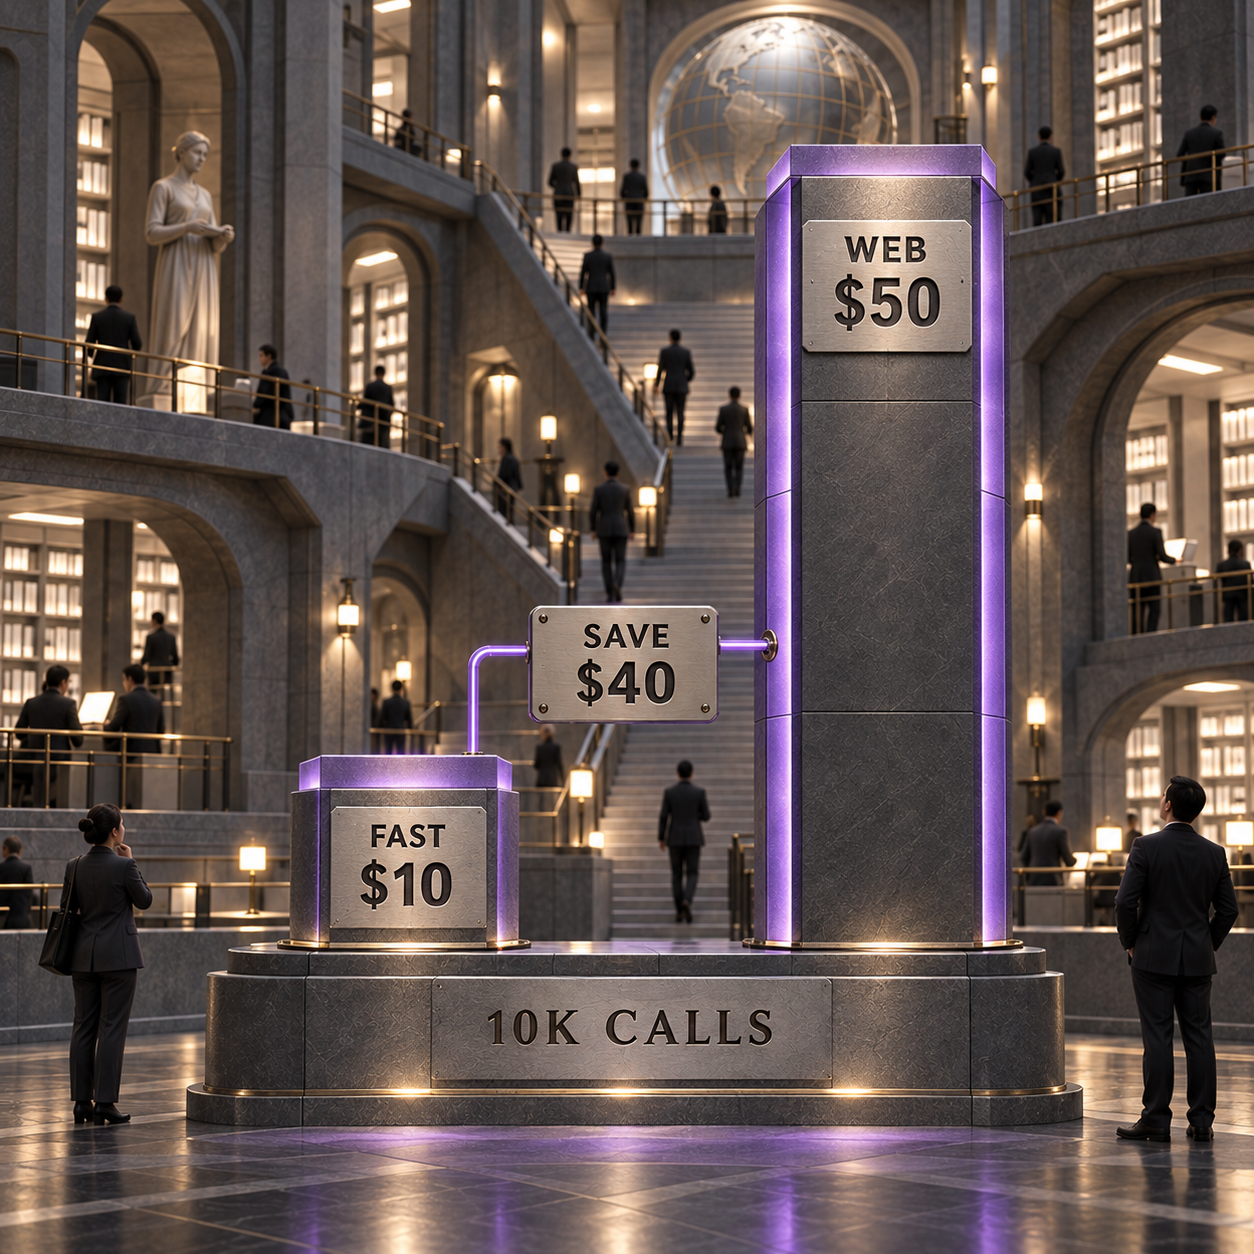
Perplexity Fast Search vs Default is a routing decision: use fast for repeatable agent lookups at $1 per 1,000 successful calls, and keep the default web mode for ambiguous or coverage-sensitive research at $5. At 10,000 calls, the raw search bill is $10 versus $50 before the model that consumes those results.
Perplexity Fast Search vs Default: Which Should You Pick?
Pick Fast Search for bounded, repeatable work; pick default web when one missed source can change the decision. Fast is the price and latency winner. Default web is the retrieval-quality and answer-availability winner. A production agent should route between them, not force every query through one mode.
Perplexity's live Fast Search guide recommends fast for day-to-day agent work and the default web setting for rare, difficult, or ambiguous questions. Prices and vendor measurements in this comparison were verified against Perplexity's live pages on September 24, 2026.
For a solo builder shipping a support agent, start routine documentation and status lookups on fast, then escalate empty or weak evidence to web. The $0.004 premium for a default-web call is tiny when a miss triggers human review, but wasteful when the answer is a low-risk lookup repeated thousands of times.
For a funded founder building market research, default web should own ambiguous company, policy, and competitive questions. Fast can still handle known-source checks, product availability, and repeated monitoring. The workload has two retrieval classes even if the product exposes one search box.
For a mid-market CTO, keep default web on procurement, security, regulation, and incident research until an internal replay shows Fast Search preserves the required source set. A five-times-cheaper request is not cheaper if an analyst must repair the evidence bundle.
Perplexity Fast Search API: What Changes Under Photon
Fast Search changes the retrieval budget, not the endpoint or result schema. Perplexity released the mode on September 24, 2026, backed by Photon, its in-house retrieval and ranking engine. The live Fast Search documentation confirms availability: the same POST /search endpoint returns the same ranked results[] array, and the request simply adds search_type: "fast".
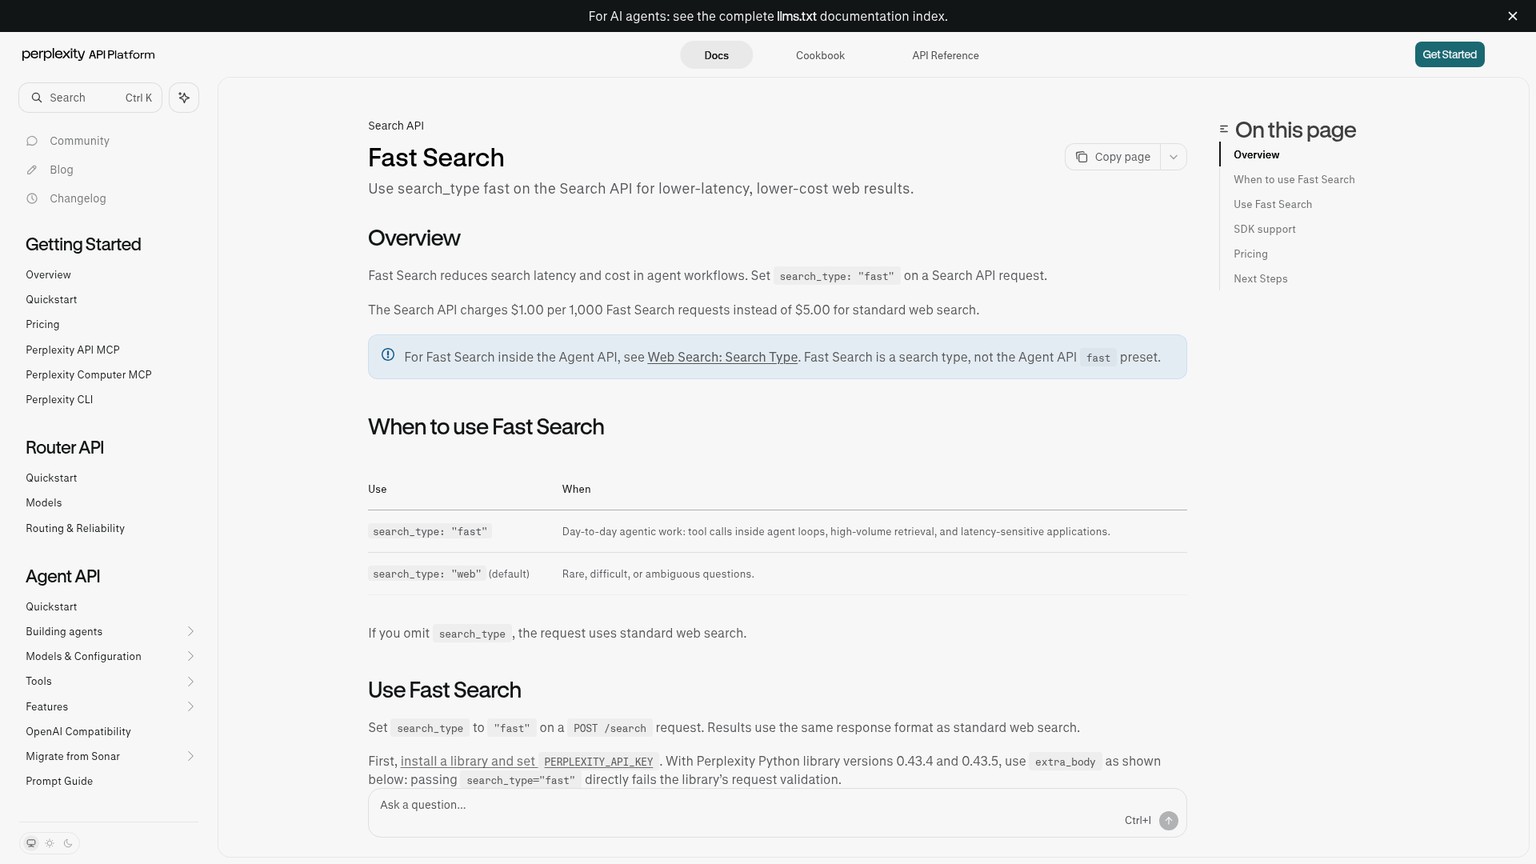
If search_type is omitted, Perplexity uses standard web. That detail matters because “default” here does not mean the consumer Perplexity app's default language model. It means the Search API's standard retrieval mode. Both modes return titles, URLs, snippets, and optional publication and update dates for downstream processing.
The Photon release describes an engine that reads only the data needed for a query, overlaps disk waits, and uses batch-aware caching; Perplexity's official architecture figure shows the request path through its broker and shards. Those engineering choices explain the speed claim. They do not erase the deliberate ranking trade-off: Fast Search uses less compute and gives up some broader retrieval quality.
Perplexity Photon is the engine, not a third mode
Photon is infrastructure under Perplexity's search stack. The API choices remain fast, web, and the separate people search type. A builder does not select Photon directly, deploy it, or receive a different response object.
The current SDK caveat is practical. Perplexity documents extra_body={"search_type": "fast"} for Python library versions 0.43.4 and 0.43.5 because direct validation rejects the new value. Its TypeScript example casts "fast" as any with SDK 0.38.5 until the types catch up. Direct HTTP requests avoid both temporary client-side constraints.
Perplexity Search API Cost: $10 vs $50 at 10,000 Requests
Winner: Fast Search. The live Perplexity pricing table charges $1 per 1,000 successful raw Fast Search requests and $5 per 1,000 successful default-web requests, with no additional Search API token fee.
The normalized workload is simple:
- 10,000 Fast Search calls: 10,000 × $0.001 = $10.
- 10,000 default-web calls: 10,000 × $0.005 = $50.
- Difference: $40, or an 80% reduction in the raw retrieval line.
That $40 is not the whole agent bill. The model reading the results, follow-up fetches, retries, validation, and human review sit downstream. Fast wins only if it does not create more than $40 of extra work across that 10,000-call batch.
Successful empty responses still cost money
A successful POST /search response is billable even when results[] is empty. Invalid requests, rate-limited requests, and upstream failures are not billed under the current pricing rules. This makes empty-result rate a budget metric, not just a quality metric.
Batching changes the bill, not the quality decision
Perplexity's multi-query quickstart accepts as many as five related queries in one request. A successful multi-query request is one billing unit, although every query still counts against rate limits. Twenty queries packed into four requests per mode would therefore cost $0.024 in total, compared with $0.12 for 40 separate single-query requests.
Do not use batching for a single-call latency comparison. A five-query payload changes the work performed by the request and hides query-level timing. First compare 20 single-query calls per mode. Test batching separately after the mode decision is sound.
Keep Agent API tool rates in their own budget row
The Agent API tool table has different standard pricing: $1 per 1,000 fast web_search invocations and $2.50 per 1,000 standard-web invocations, plus the selected model's token charges. Those are not the raw Search API's $1 and $5 rates. Fast Search is also not the Agent API's separate fast preset, despite the reused word.
The older Perplexity versus Exa versus Tavily cost comparison answers which provider to buy. This decision happens one level deeper, after Perplexity is already in the stack.
Latency Winner: Fast, With a Vendor-Measurement Asterisk
Winner: Fast Search, based on Perplexity's measurement. Perplexity's official latency chart reports 160 ms at p50 and 230 ms at p95 for a single Fast Search call. Perplexity does not publish a matched default-web p50 and p95 in the surrounding launch text or the live Fast Search guide, so there is no honest paired latency ratio to quote.
The percentiles matter. p50 is the middle request. p95 is the threshold under which 95% of requests finish. An agent with several sequential search calls feels the slow tail more than the median, because one delayed tool call can hold the entire plan open.
Fast therefore deserves the latency-sensitive lane, but the production question remains workload-specific. Network distance, filters, requested result count, extracted context, batching, and retry policy all affect the end-to-end time seen by the agent. The vendor's number is a baseline, not a service-level promise for every integration.
Mikhail Basyuk's practitioner framing lands on the right standard: sub-250 ms p95 is useful only if the relevance needed by the task survives. Speed and evidence belong on the same dashboard.
Coverage Winner: Default Web
Winner: default web for difficult and ambiguous research. Perplexity's internal retrieval chart gives Fast Search a relevance score of 2.21 versus 2.45 for default, a 0.24-point gap. Answer availability is 0.567 versus 0.596, a 2.9-percentage-point gap.
Relevance asks whether the ranked material matches the query well. Answer availability asks whether retrieval surfaced enough material to support an answer. Fast can return quickly and still leave the next model with a thinner evidence set. That is why a broad policy question, a multi-company comparison, or a disputed claim belongs on default web even when the fast path feels responsive.
Perplexity also reports a seemingly opposite result in its aggregate vendor chart across six public agentic benchmarks and 3,554 selected tasks: Fast scored 64.3% at an estimated $59.73 in total model-plus-search cost, while default scored 64.0% at $187.60. The vendor describes the fast configuration as approximately 68% cheaper with comparable aggregate task quality.
Those findings can coexist. Aggregate agents can compensate for weaker retrieval through model knowledge, reasoning, repeated calls, or because the selected tasks do not punish every missing source. A raw retrieval system serving compliance or business research cannot assume the downstream model will repair a missing document.
The broader AI search API guide uses the same operating principle across vendors: buy the cheapest retrieval rung that produces an evidence bundle the next deterministic check will accept.
How to Set Perplexity Search Type Fast
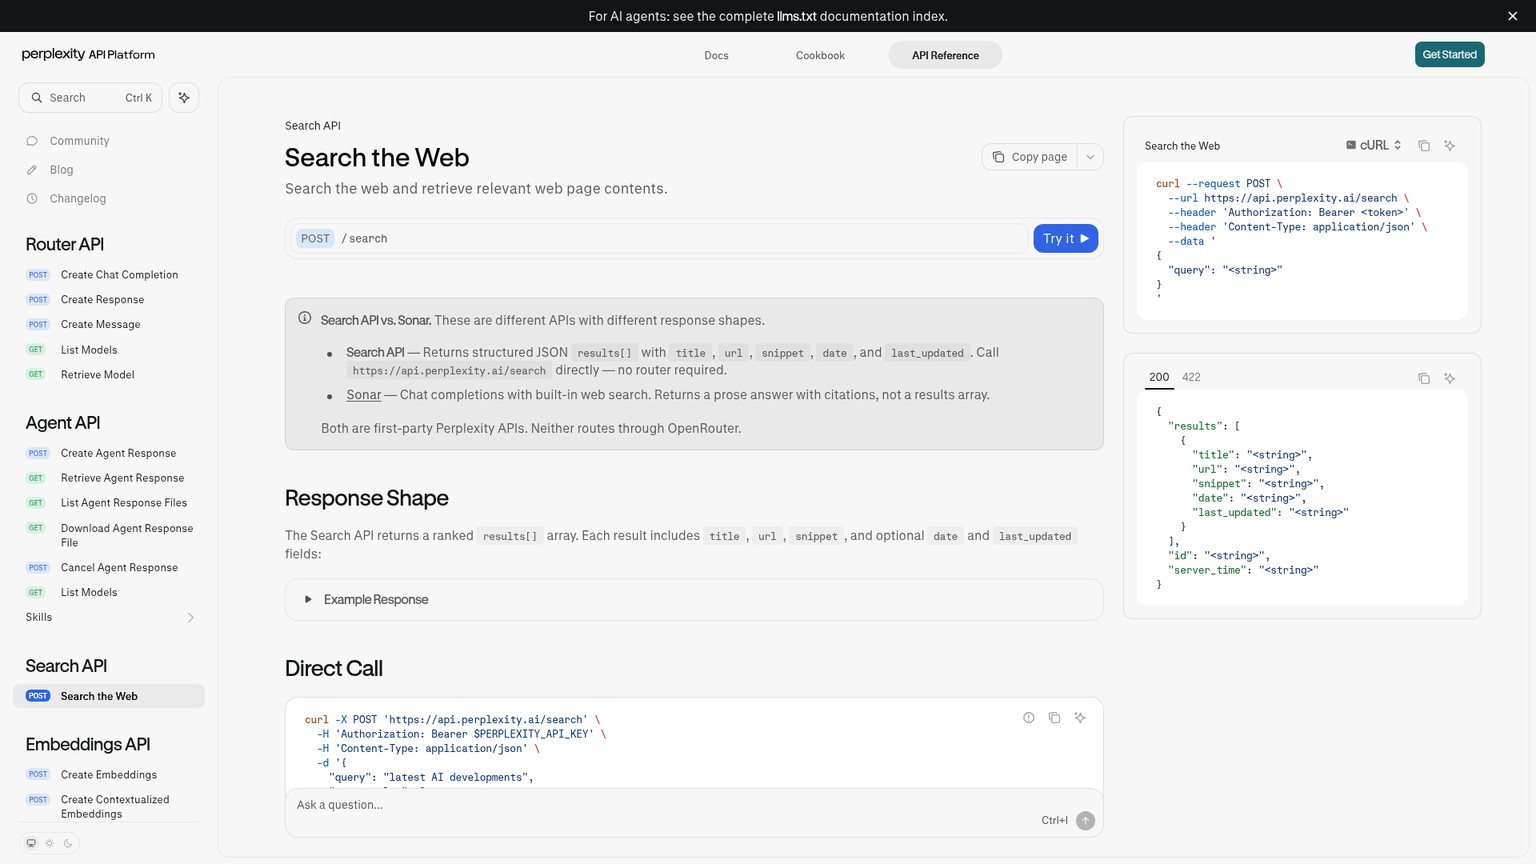
Use the same request twice and change only search_type. Hold query, max_results, search_context_size, filters, region, and client location constant. The live Search API reference documents web as the default, max_results at 10 by default, and high as the default extracted-context size. Set both comparison controls explicitly so a later API default cannot alter the replay.
This request pair is runnable as written:
set -euo pipefail
: "${PERPLEXITY_API_KEY:?Set PERPLEXITY_API_KEY first}"

QUERY='Which CRM has the stronger current EU data residency and audit-control evidence?'
COMMON=$(jq -nc --arg query "$QUERY" '{
  query: $query,
  max_results: 10,
  search_context_size: "high"
}')

for MODE in fast web; do
  jq --arg mode "$MODE" '. + {search_type: $mode}' <<<"$COMMON" |
    curl -sS 'https://api.perplexity.ai/search' \
      -H "Authorization: Bearer $PERPLEXITY_API_KEY" \
      -H 'Content-Type: application/json' \
      -o "$MODE.json" \
      -w "$MODE\tHTTP %{http_code}\t%{time_total}s\n" \
      --data-binary @-
done
No Perplexity API credential was available in this publication run. No measured latency, coverage, empty-result rate, or answer-support result is claimed here. The protocol below is a small paired check, not a replication of Perplexity's six-benchmark study.
Use 20 business-research queries: 10 specific lookups with an authoritative target and 10 ambiguous questions requiring several sources. A practical fixed set can cover current SaaS pricing, cloud limits, regulatory dates, supported countries, security controls, recent filings, vendor comparisons, policy effects, total-cost questions, and claims with credible evidence on both sides.
At single-query granularity, those 40 successful raw requests cost $0.12 before any downstream model call: $0.02 for 20 fast calls plus $0.10 for 20 default-web calls.
Freeze the request
Use
max_results: 10andsearch_context_size: "high"for both modes. Keep filters, country, language, and the client region identical. Randomize which mode runs first for each query so warm caches and transient network conditions do not always favor one side.Record retrieval behavior
Capture end-to-end
time_total, HTTP status, result count, an empty-response flag, unique domains, authoritative-source count, and whether the expected primary source appears. Keep all raw JSON for review.Apply one usefulness rubric
Score useful source coverage as zero for no decision-relevant source, one for a usable but incomplete set, and two for enough independent evidence to proceed. Do not award points for duplicate domains or long snippets that repeat one source.
Hold the answer layer constant
If a model turns results into an answer, use the same model, prompt, token budget, and citation checker. Score answer support as zero when a material claim lacks evidence, one when support is partial, and two when every material claim maps to returned evidence.
Decide by workload class
Compare medians and p95 latency, empty responses, source coverage, and answer support separately for lookup and ambiguous groups. Promote fast only for a class whose evidence score stays inside the team's acceptance band.
The key comparison is not average result count. A pile of weak links can be worse than a small set of primary sources. Useful coverage and supported answers are the metrics that let price and latency mean something.
What Switching Actually Costs
Changing the request body is easy; changing the operating policy is the work. Moving a workload from default web to fast requires no data migration and no new endpoint. It still changes retrieval behavior, cache identity, monitoring, and failure handling.
Put search_type in the cache key. A cached fast response must not silently satisfy a later default-web request whose caller paid for broader retrieval. Include context size, result count, filters, country, and language for the same reason.
Log the mode on every request and every downstream claim. Without it, a falling source-acceptance rate looks like model drift or random search noise. The router also needs a visible escalation reason such as empty_results, missing_primary_source, ambiguous_query, or high_impact.
Keep retries mode-aware. A timeout retry on the same mode is an availability action. A fast-to-web retry is a quality escalation and changes the price. Those events should not share one counter.
Who should not switch
Do not make Fast Search the universal default when:
- The agent handles contracts, regulation, security, finance, medical information, or incident response where missing a source has a high consequence.
- The current workload is dominated by ambiguous questions that need source diversity rather than a known factual lookup.
- No accepted-evidence rubric exists, so “faster” would become the only visible success metric.
- A provider adapter or SDK rejects the new enum and the team cannot safely use the documented workaround or direct HTTP.
- Empty successful responses are not logged separately from transport failures.
- The default-web premium is immaterial beside the human review already required for every answer.
The better migration is a routed rollout. Move one repeatable class to fast, preserve web as the escalation path, and compare accepted evidence before expanding.
The Monday Move
Ship a simple search policy before changing the global default. Route repeatable, low-impact lookups to fast; route ambiguous or high-impact questions to web. Then make evidence rejection an automatic escalation, not an invisible weak answer.
Start with last week's requests rather than invented demos. Select 20 that represent the product's ordinary work, split them into specific and ambiguous groups, and replay the exact pair above. The test costs $0.12 in raw search fees if all 40 single-query requests succeed.
Review four outputs on Tuesday: p95 request latency, successful empty responses, useful source coverage, and answer-support score. If fast holds the evidence bar for the specific group, move that one class. If it loses a primary source on the ambiguous group, keep default web there regardless of the aggregate benchmark.
That is the business consequence of Photon: not one cheaper global setting, but a practical search-risk router. The agent spends $1 per 1,000 calls when the query is forgiving and pays the extra $4 only when broader retrieval can prevent a more expensive miss.
Frequently Asked Questions
Why is Perplexity controversial?
Debates around the consumer product, source attribution, and publisher relationships are separate from this API-mode choice. An API buyer should validate source coverage, usage terms, and evidence handling against the organization's own requirements.
How to change default search engine to Perplexity?
That is a browser or device setting. In this comparison, “default” means the Search API behavior: omitting search_type uses standard web, while Fast Search requires search_type: "fast".
Why is Perplexity failing?
The premise is too broad to establish from the cited API evidence. For an integration, define failure precisely as an empty result, missing expected primary source, weak useful coverage, unsupported answer, timeout, or upstream error.
Which is better for searching, Perplexity or Google's AI mode?
That compares consumer answer products, not Perplexity's raw Search API modes. Fast versus default web should be decided by retrieval latency, useful source coverage, and the downstream answer's evidence support.
Why is Joe Rogan using Perplexity?
A public endorsement or advertisement does not establish a technical reason and provides no evidence for choosing fast or web. Use workload data, not celebrity usage, for the API decision.
Is Perplexity any good anymore?
Fast Search has a clear job at $1 per 1,000 successful raw requests, and Perplexity reports 160 ms p50 latency. The vendor's own retrieval results also show that default web remains the better choice when broader relevance and answer availability matter.
What is the downside of Perplexity?
For Fast Search, the documented downside is lower retrieval relevance and answer availability. For default web, the downside is a five-times-higher raw request price and higher latency than the mode built specifically for speed.
Is Perplexity losing users?
The cited launch and API pages do not publish audited active-user trend data, so this comparison cannot support that claim. User growth would not settle which Search API mode fits a production query anyway.
Is Perplexity AI better than ChatGPT?
Perplexity's raw Search API returns ranked web results for another system to process, while ChatGPT is an end-user assistant with its own tools and models. Compare the concrete workflow and evidence requirements rather than the brands in the abstract.
Want the routing, validation, and cost questions in one working sheet? Download the AI Business Workflow Audit Checklist and map the first search-risk router on Monday.
- Last Updated
- Sep 24, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

AI Agent Fallback Costs
A sandboxed writer triggered paid image fallbacks until a shared balance ran out. The incident, missing outputs, and fix at the upload boundary.Sep 24, 2026Build
Is Cursor Rollouts Free
Cursor Rollouts needs Teams or Enterprise. Understand the 10-day launch credits, roughly 50 or 500 changes, and the costs to check.Sep 24, 2026Build
How to Use Unreal Agent
Run Unreal Agent from Unreal Labs on a bounded repo task. Check Go setup, provider keys, JSONL output, sessions and actual usage.Sep 24, 2026Build
How to Use JetBrains Air
Install Air Alpha in your JetBrains IDE, connect an agent, add project context, and review your first code change.Sep 23, 2026Build
Is JetBrains Air Free
Air's IDE plugin is free. Compare Junie Lite, existing agent subscriptions, provider API billing, and JetBrains AI credits.Sep 23, 2026Build
Firecrawl Self Host
Self-host Firecrawl from a pinned release, verify a scrape, and compare features and 30-day costs with Cloud before choosing a deployment.Sep 22, 2026Build
Human Approval for AI Agent Retries
An agent spent $5.48 before anyone looked. See why paid redos need approval that the model cannot grant itself.Sep 22, 2026Build