Best AI Code Review Tools for Small Teams in 2026: CodeRabbit, Greptile, Cursor Bugbot, Codex, Claude Code and Codex Security
Compare six AI code reviewers: live prices for five developers, noise controls, GitHub and GitLab support, retention and one PR reviewed by three bots.



For the best AI code review tools for small teams, start with CodeRabbit Essentials at $150 a month for five developers, or use the Codex or Claude Code subscriptions your team already has for a review before opening a PR. Greptile, Cursor Bugbot and managed Claude review earn a place when their workflow and usage bill fit; Codex Security serves a separate security job.
Prices and plan names verified against vendor pages on 2 October 2026. The budgets below assume five active human developers, US dollar pricing before tax, no promotional discounts, and monthly billing unless an annual equivalent is explicitly named. Usage examples assume 100 completed review runs a month, evenly split between the developers. Those are budgeting assumptions, not a claimed industry average.
Best AI Code Review Tools for Small Teams at a Glance
CodeRabbit is the default paid PR bot for a small team that wants reviews to happen consistently in its existing pull-request workflow. An existing coding-agent subscription is the better first purchase decision when the team can reliably request a review before pushing. That distinction matters more than a vendor's benchmark leaderboard.
The subscription price buys access or an allowance. It does not always buy every review your team might trigger. A PR reviewed when opened, after a fix, and after a rebase can produce several billable runs. A five-seat budget also changes if only some developers are active authors, if agent usage consumes a shared allowance, or if the team buys additional credits.
The purchase rule: pay for a dedicated automatic reviewer when requesting reviews manually is the failure in your process. Reuse an agent when reviews already happen reliably and you need another correctness pass. Add a security reviewer when the question is attacker reachability and exploitability.
Where AI-Powered Code Review Happens
The review location decides who sees the finding, when the author can fix it, and whether the team can count on the review happening.
A PR bot such as CodeRabbit or Greptile watches a connected repository and posts findings into the pull request. It puts review activity where the team already decides whether to merge. The author does not have to remember a terminal command.
An editor vendor's reviewer such as Cursor Bugbot connects review to the coding and fixing workflow. Bugbot also reviews hosted PRs; choosing it does not require every contributor to write code in Cursor. Its useful distinction is the connection between reviewing a change and returning it to an agent for a fix.
A coding agent reviewing work can inspect a branch or diff before it becomes a PR. Codex also offers connected cloud review, while Claude Code has both a local review command and a separately billed managed GitHub service. These routes need separate budget and retention decisions.
A security reviewer examines the threat model: what an attacker can control, which boundaries the code crosses, and whether a suspicious path produces an actual vulnerability. Codex Security belongs alongside general code review, with a narrower purpose.
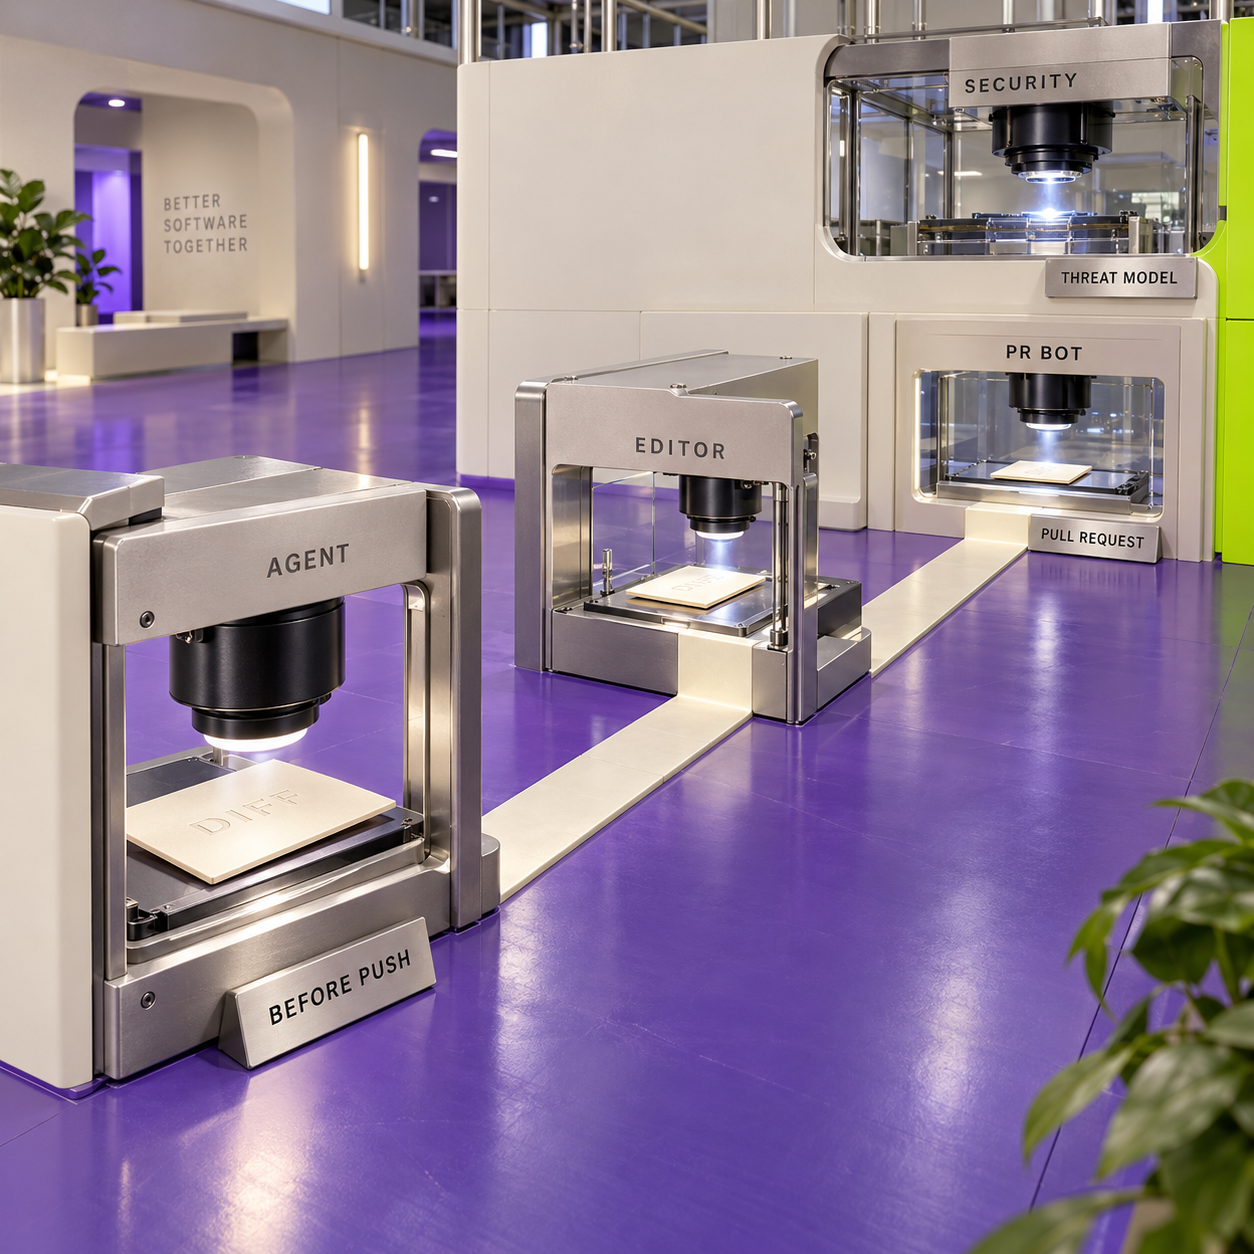
A local checkout does not imply local model inference. Claude Code and Codex can run commands on your machine while sending prompts and relevant code to their model service. Likewise, deleting a cloud container does not necessarily delete the resulting review report.
PR Bots: CodeRabbit and Greptile
CodeRabbit: the Default Automatic Reviewer
CodeRabbit is a repository-connected AI reviewer that posts summaries and line-level feedback into PRs. Choose it when the team's recurring problem is that ordinary changes reach human review without a consistent preliminary pass. Its configuration can narrow the feedback, and its paid plans provide a straightforward starting seat budget. Skip an upgrade until you can name the capability or usage limit that requires it.
Verdict: CodeRabbit Essentials is the first dedicated bot to trial for a five-person team; its $150 monthly seat cost is easy to understand, provided your review bursts fit the plan's limits.
Best for: Small teams wanting automatic GitHub or GitLab feedback on routine changes.
Standout: Review profiles, path-specific instructions and feedback-driven context in the PR workflow.
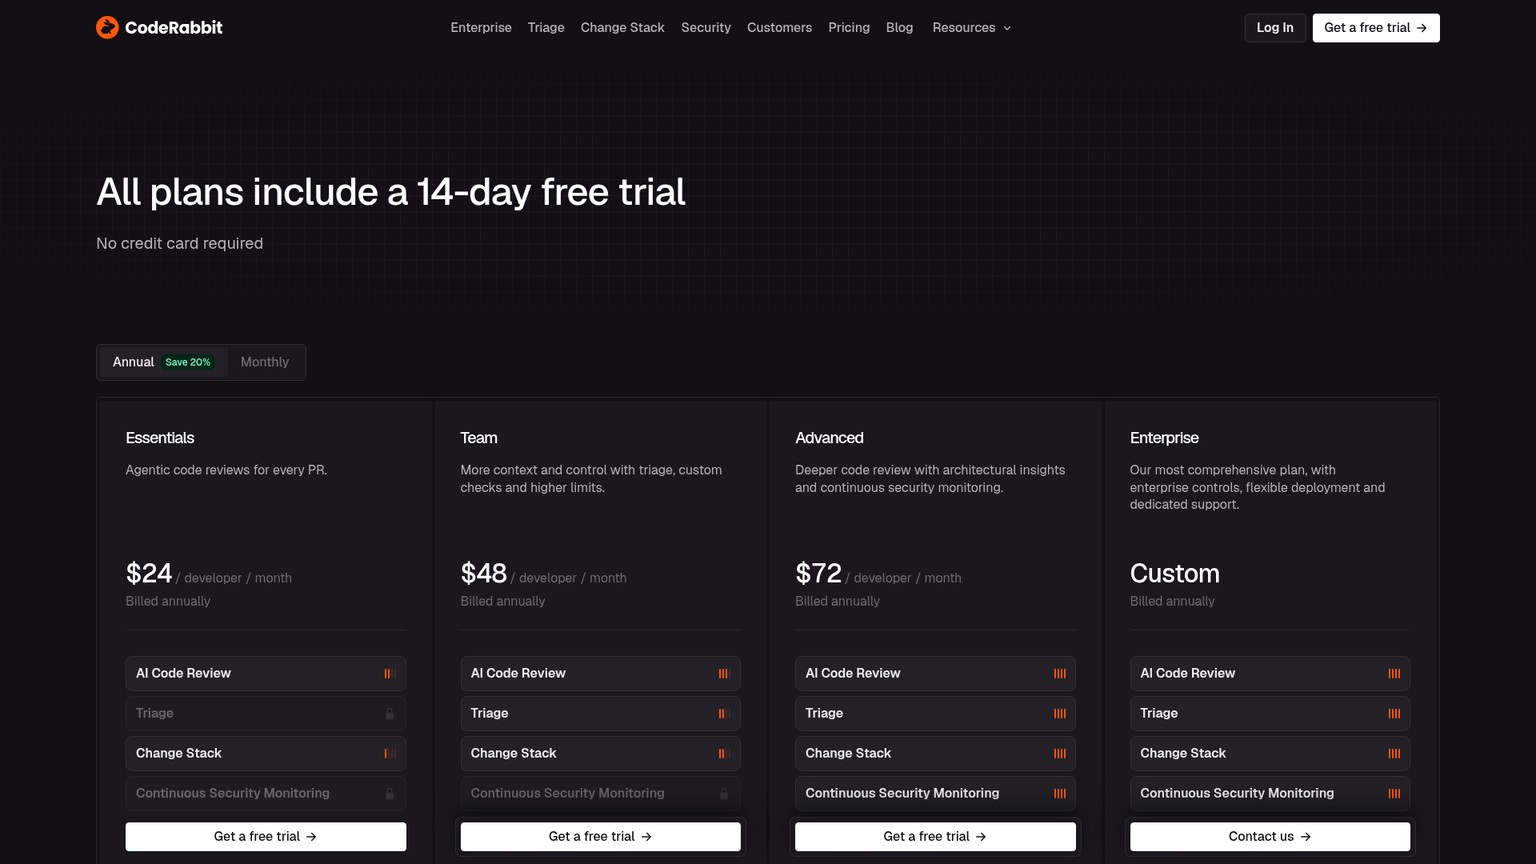
Pricing: Essentials $30, Team $60, Advanced $90 per developer monthly; Enterprise custom.
Free trial: 14 days. Free private-repository features are more limited than paid PR review.
Every Plan and the Five-Developer Cost
The current plans are Free, Essentials, Team, Advanced and Enterprise. Annual billing reduces the displayed paid rates to $24, $48 and $72 per developer per month. The five-developer annual equivalents are therefore $120, $240 and $360 a month, requiring annual commitments of $1,440, $2,880 and $4,320 respectively. Monthly billing costs $150, $300 or $450 for the same team. Enterprise needs a quote. The live pricing page and official plan documentation are the sources for those rates.
Free provides private PR summaries rather than the full paid private-PR review service. CodeRabbit also offers free local review allowances and free reviews for public open-source work. A CTO requiring automatic private-code findings should budget for a paid plan rather than treating a summary as a correctness review.
Essentials is the sensible starting point. Team adds capabilities such as more extensive multi-repository context and custom checks; Advanced adds deeper security and architectural features. Buy those for an identified need. Having five developers does not, by itself, make the plan named Team necessary.
False Positives and Tuning
Start with the quiet profile if the team wants only consequential feedback. The default chill profile is balanced; assertive deliberately produces more feedback and can feel nitpicky. Those are documented behavior controls, not measured precision guarantees. Use path filters to exclude generated outputs from review and path instructions to state the actual invariants for sensitive code. These settings live in .coderabbit.yaml or the dashboard. Configuration reference.
For a billing service, useful guidance explains that a retry must not charge twice and that a refund must preserve its audit trail. “Be rigorous” gives the reviewer less help. Ask for evidence showing the changed line, the reachable caller and the failing condition. Leave formatting that your linter already enforces to CI.
When a comment is wrong, explain the protecting condition rather than replying only that the bot is wrong. If it points to a genuine but intentionally accepted tradeoff, record the scope of that exception. Broad instructions to ignore a whole bug class can silence the next real defect.
GitHub, GitLab and Retention
CodeRabbit documents direct integrations with GitHub.com, GitHub Enterprise Server, GitLab.com and self-managed GitLab. Connecting a self-managed code host is different from running the reviewer itself on your infrastructure. Its Enterprise self-hosting option is documented for 500 or more seats, so it is not the routine five-person purchase path. Supported platforms.
The reusable repository-and-dependency cache is enabled by default and expires after a maximum of seven days. It is used for review acceleration, not training; cached data is encrypted except for open-source projects. Set reviews.disable_cache to true to disable it. That seven-day rule concerns the prepared repository cache. The privacy policy separately describes vector embeddings for personalized reviews and a storage opt-out, without one published deletion clock for every artifact. Cache documentation.
Review comments also remain in GitHub or GitLab according to your host's policies. Treat source caching, learned context and posted comments as separate records when writing an internal retention rule.
- Automatic reviews meet the team inside its existing PR discussion.
- Quiet, balanced and assertive profiles make the feedback policy explicit.
- Path instructions can describe different risks in different parts of the repository.
- GitHub and GitLab are documented integration targets.
- Free private PR summaries do not replace paid correctness review.
- Hourly and file-count limits still matter despite the absence of a monthly PR cap.
- Repository cache expiry does not establish the lifetime of all learned context.
Connect the repository that represents your work
Install CodeRabbit for a normal active repository, with access limited to the repositories you intend to review. Start on Essentials unless a documented requirement needs another tier.
Give it a short review contract
Choose quiet, exclude generated outputs, and describe the invariants in the risky paths. Ask for a concrete failure condition and avoid duplicating lint rules.
Label findings before expanding coverage
Have the team classify comments as useful, wrong, already covered or true but too minor. Keep automatic feedback advisory during the pilot, and inspect the hourly usage pattern as well as the invoice.
Greptile: Choose It for Configurable Repository Context
Greptile is a repository-aware AI PR reviewer with review rules, directory-scoped settings and feedback-based learning. It is a strong alternative when the team wants to shape review behavior around its codebase and is willing to manage author-level usage. The purchasing trap is assuming that a $30 seat buys an unlimited number of equally priced reviews.
Verdict: Greptile is a credible CodeRabbit alternative, but choose its review effort and flex cap before enabling it on every push.
Best for: Teams that want repository-specific standards and detailed control over which comments appear.
Standout: Separate controls for review effort, comment categories, importance and directory-level behavior.
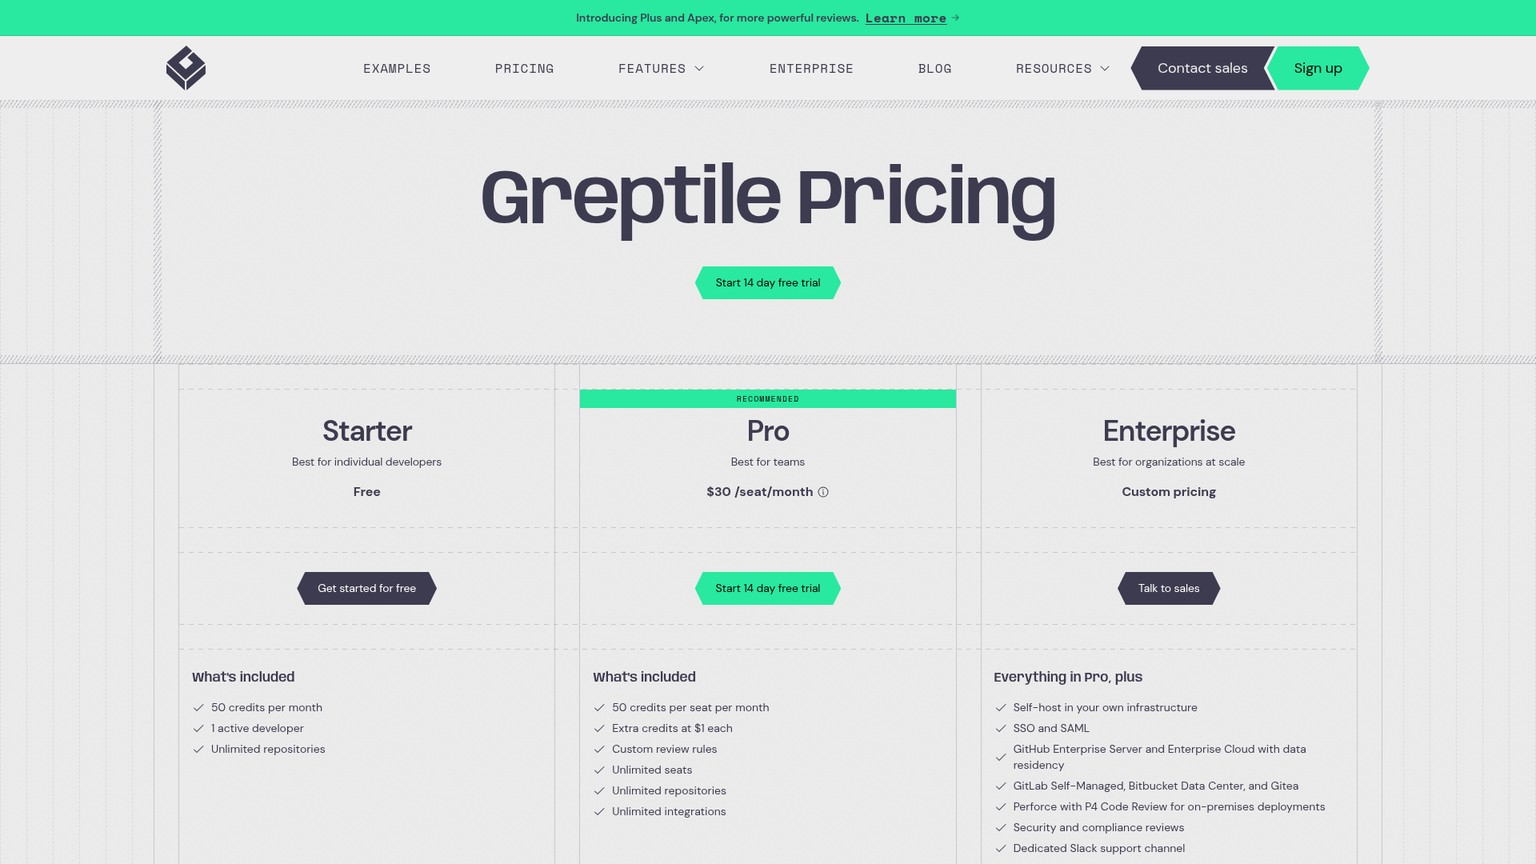
Pricing: Starter free for one active developer; Pro $30 per active developer monthly plus extra credits; Enterprise custom.
Free trial: 14 days; qualified noncommercial open-source projects can apply for free access.
Every Plan and the Five-Developer Cost
Starter includes one active developer, unlimited repositories and 50 monthly credits. Pro includes 50 credits per active developer, with excess credits at $1 each. Enterprise has custom pricing and includes options such as self-hosting, SSO and self-managed code-host integrations. Annual and multi-year discounts are negotiated rather than a single published annual price. Live pricing.
The effort tiers are Base at 1 credit, Plus at 3 and Apex at 10. Auto chooses a tier per PR, so Auto is not a fixed-cost review. Those are units of work and billing, not evidence that a more expensive review has a lower false-positive rate.
An active developer is an author with a completed review charged to them during the billing period. Reviews are charged to the PR author, and unused included credits are not pooled across the team. Billing counts completed reviews, including fresh runs after configured events, rather than unique PRs. A reviewer clicking the trigger does not move the bill to that reviewer. Billing documentation.
For example, an author receiving 70 Base reviews exceeds their allowance by 20 credits. Another author receiving only 10 cannot lend the unused credits. Set the organization's Flex Usage Limit to the extra amount you accept; setting it to $0 disables flex reviews. Authors still inside their included allowance can continue receiving reviews after that cap is reached.
False Positives and Tuning
Use strictness to control which findings are posted: 1 is verbose, 2 is the balanced default, and 3 is critical-only. Use commentTypes to select logic, syntax or style feedback. For a team already enforcing formatting in CI, starting with logic and syntax removes an obvious source of duplicate work. The recommended .greptile/ configuration supports directory-specific overrides; the older root greptile.json route remains available. Noise controls.
Strictness and effort solve different problems. Raising strictness narrows reported comments. Changing Base to Apex changes the work and credit consumption. Do not use a larger bill as a substitute for defining what an actionable finding looks like.
Upvote useful findings and downvote irrelevant ones with a brief reason, such as a documented guarantee that the suspected value cannot be null. Keep the exception local to the code where it holds. Restrict automatic triggers when frequent pushes keep restarting reviews before a change is ready.
A particularly useful data-boundary detail: ignorePatterns excludes files from PR review, but does not exclude them from repository indexing. A generated file you do not want comments on and a confidential directory you do not want the vendor to access are different requirements.
GitHub, GitLab and Retention
Greptile supports hosted GitHub and GitLab review. GitHub Enterprise Server and GitLab Self-Managed appear among Enterprise features on the pricing page; do not assume those deployment needs are covered by a standard Pro seat.
Its security page states that encrypted source code stays cached until access is revoked in GitHub or GitLab, after which it is deleted. Greptile also stores embeddings of paths, documentation and generated docstrings. This is an access-linked cache lifetime, not a fixed seven-day expiry. Chat logging can be disabled. The policy permits training and improvement using de-identified customer data, with an account opt-out for further training. Security and data policy.
An administrator can request deletion of customer data: the stated production hard-deletion window is 24 hours, with backups destroyed within 30 days except for an incident-investigation extension. Record the training preference and deletion process when evaluating the trial. A general statement that data is encrypted answers a different question from how long it remains stored.
- Importance filters and comment categories provide concrete noise controls.
- Directory-scoped settings can match different teams inside a monorepo.
- Feedback can capture why a suggestion does or does not apply.
- An explicit flex cap makes excess review spending controllable.
- Included credits belong to individual authors and cannot cover another author's spike.
- Higher effort and frequent reruns can materially increase the monthly bill.
- Ignoring a path for review does not prevent indexing it.
- Source caching and training preferences need explicit attention during procurement.
For a closer choice between these bots, use Greptile vs CodeRabbit. If neither fits, CodeRabbit alternatives covers a broader candidate set; apply the same current-price and data-boundary checks to those options.
The Editor's Reviewer: Cursor Bugbot
Cursor Bugbot: Best When Review and Fixing Already Happen in Cursor
Cursor Bugbot is Cursor's AI reviewer for pull requests and pre-push changes. Choose it when the team already uses Cursor and wants a finding to move smoothly back into its fixing workflow. It is also a connected PR bot, so “the editor's reviewer” describes its product home rather than a restriction to reviewing inside the IDE.
Verdict: Bugbot belongs on a Cursor team's shortlist, but budget usage rather than adding an old standalone $40 Bugbot seat to every developer.
Best for: Cursor teams connecting branch review, PR feedback and agent-assisted fixes.
Standout: Pre-push Bugbot review can recognize the same diff later and avoid repeating the remote review.
Pricing: Usage-based Bugbot billing; Cursor subscription tiers and review spending are separate budget inputs.
Free trial: No separate current Bugbot trial promise in the cited documentation.
Every Plan and the Five-Developer Cost
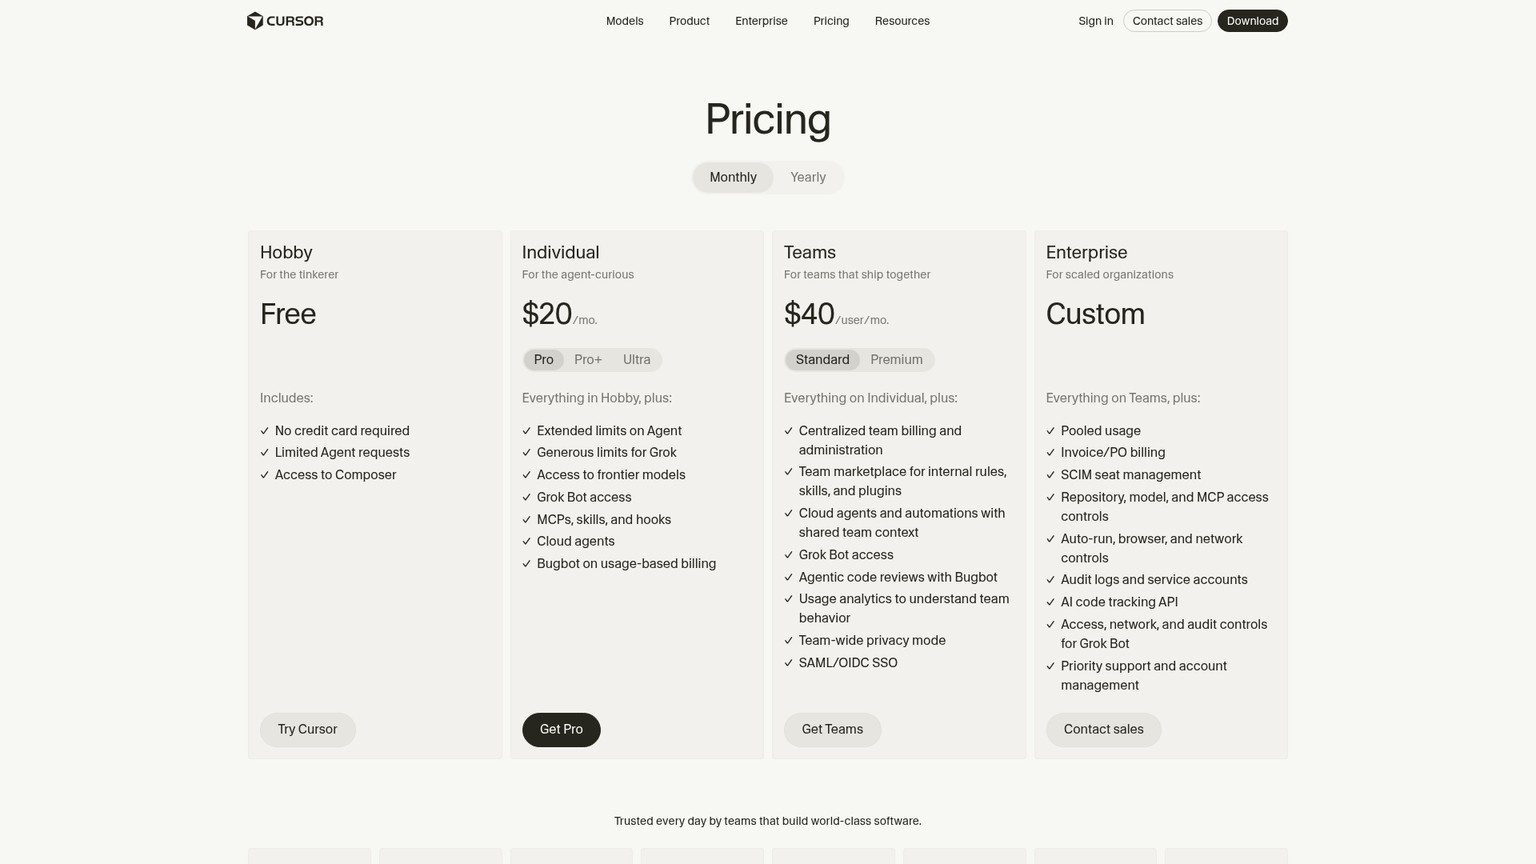
Cursor's US plans include free Hobby, Pro at $20 a month, Pro Plus at $60 and Ultra at $200. Five individual subscriptions cost $100, $300 or $1,000 a month. Teams has Standard seats at $40 per user monthly and Premium at $120, making five-seat bases $200 and $600. Enterprise is custom. The India-only Start plan is ₹649 monthly including tax and excludes Bugbot, so it is not a cheaper review tier for this comparison. Current plan documentation.
Bugbot moved to usage billing for Teams and Individuals. Teams uses on-demand spending; Individuals draw from included usage before additional spending. Cursor's published average is $1.00 to $1.50 per Bugbot run, varying with size and complexity. This average is a budgeting input, not a fixed tariff or a promise about your next PR. Existing customers move from legacy seat billing at their first renewal after 8 June 2026; an unrenewed annual contract can therefore show a historical seat charge. Billing change.
Hobby is not a promised free automatic Bugbot service for a private five-person team. Individual included pools also have competing uses, so a Pro subscription should not be presented as a guaranteed fixed number of free reviews.
False Positives and Tuning
Bugbot needs its own review instructions. Put project-specific guidance in .cursor/BUGBOT.md, including scoped files for particular directories. Ordinary Cursor editor rules in .cursor/rules/*.mdc do not apply to Bugbot. Team and repository rules provide additional guidance; verbose review output shows which rules were included. Bugbot documentation.
Use .cursor/config/bugbot.yaml for repository settings such as effort and triggering. Bugbot reads that file from the default branch, so a PR cannot change its own review behavior through a modified copy. That is useful for keeping a review policy stable while the branch under inspection changes.
Start with incremental review, which is enabled by default, and use manual triggering when rapid updates create more discussion than the team can process. Low, Default, High and Smart effort affect the work and usage; Smart can follow guidance about when a change warrants more scrutiny. Higher effort is not a measured noise cure.
Bugbot reads existing PR discussion as context. Keep a human explanation of an accepted tradeoff in the thread, and diagnose missing instructions before assuming the model ignored them. The pre-push /review-bugbot route can recognize an identical patch on the connected host and skip another remote review. That is a useful way to reduce duplicate review work.
GitHub, GitLab and Retention
GitHub, including Enterprise Server, and GitLab, including Self-Hosted, are documented targets. Review-only use and Autofix have different operational requirements: Autofix uses Cloud Agent credits and requires storage to be enabled. Include that extra activity in the budget if the team intends to turn it on.
Bugbot follows Cursor's processing policy. In Privacy Mode, Cursor does not train on customer data and maintains provider zero-data-retention agreements, with stated exceptions for abuse investigations and explicitly identified or administrator-enabled non-ZDR models. Temporary encrypted file caches also exist. Turning Privacy Mode off can permit storage and training. Cursor data use.
Those controls should not be rewritten as “nothing is ever stored.” PR comments and learned review rules are workflow records, and the cited pages do not give one deletion duration for every Bugbot artifact. Verify the team's enforced privacy setting and any selected model exceptions.
- Findings connect to a workflow the Cursor team already uses to fix code.
- Pre-push review can avoid a duplicate remote review of the identical patch.
- Default-branch configuration helps keep review policy stable.
- GitHub and GitLab are supported review hosts.
- Usage billing makes cost depend on review activity and effort.
- Existing IDE rules do not automatically become Bugbot instructions.
- Autofix introduces additional credits and storage requirements.
Coding Agents Reviewing Work: Codex and Claude Code
Codex Code Review: Reuse the Agent, Then Decide Whether to Automate
Codex code review is OpenAI's coding-agent review workflow, available locally and through connected repositories. Choose it when the team already uses Codex and wants another pass over changes before a human approves them. Its cloud integrations also make it a candidate for automatic review rather than only a command developers must remember.
Verdict: Start with the Codex access you already pay for; for a new business workspace, five monthly Business seats start at $125, with review capacity and extra credits evaluated separately.
Best for: Teams adopting Codex for both coding and review, especially those wanting shared workspace controls.
Standout: Repository instructions in AGENTS.md guide review, and native GitLab review is now documented in beta.
Pricing: Plus $20 monthly; Pro $100, $200 or $500; Business $25/user monthly or $20 with annual billing; Enterprise and Edu custom.
Free trial: No separate code-review trial or fixed per-PR tariff stated.
Every Plan and the Five-Developer Cost
ChatGPT Free is $0 and Go is $8 a month, with lightweight local Codex access subject to rollout. The pricing page explicitly lists cloud integrations such as automatic review on Plus at $20. Pro has $100, $200 and $500 monthly levels. Business is $25 per user with monthly billing or $20 per user monthly equivalent with annual billing, with a two-user minimum. Enterprise and Edu need a quote. Codex pricing.
Five Plus subscriptions cost $100 a month. Five equal Pro subscriptions cost $500, $1,000 or $2,500. Five Business seats cost $125 with monthly billing, or $100 monthly equivalent on a $1,200 annual commitment. A cheap consumer subscription and a centrally governed business workspace are different purchases even when both can review code.
API-key use is another route for the CLI, SDK or IDE, with token-based billing. It does not include cloud features such as hosted GitHub code review. Do not buy API credits expecting them to activate the same connected review service.
False Positives and Tuning
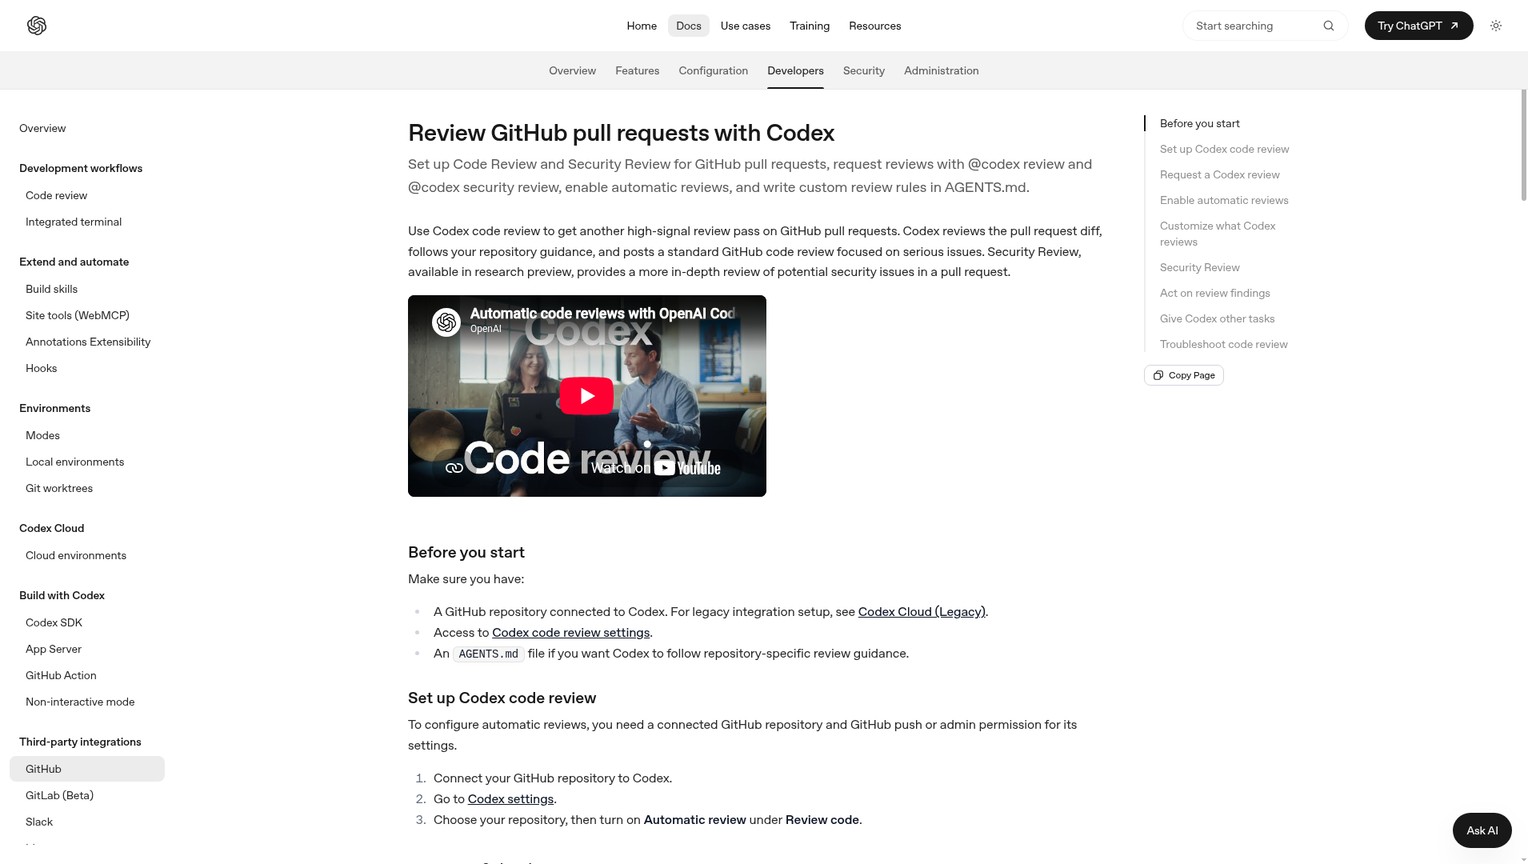
On GitHub, the documented default reports P0 and P1 issues, the urgent and high-priority findings. This deliberately favors consequential feedback. Add a Code Review Rules section to applicable AGENTS.md files and state what counts as a meaningful defect in that path. Codex reads the instructions relevant to the changed files. GitHub review documentation.
Useful rules describe facts: an endpoint is internal-only; a migration must support both old and new readers; a nullable field is guarded by a specific caller. Require the reviewer to identify how a changed line violates the fact. Long instructions to find “every possible issue” encourage hypotheses that a small team must then disprove.
A local or manual review is useful before pushing because the author can inspect the evidence without starting a public comment round trip. For important changes, ask for a fresh review focused on the diff and repository evidence. An agent that wrote the implementation may carry the same mistaken assumption into its explanation, so keep human approval and targeted tests in the loop.
GitHub, GitLab and Retention
GitHub supports a requested @codex review and repository-configured automatic review. Native GitLab code review is in beta and available on all ChatGPT plans, according to the current GitLab documentation. It requires a project environment and enabled activity delivery; self-managed and Dedicated installations also need administrator setup and a review identity. Manual GitLab reviews can include P0, P1 and P2 findings, while automatic reviews default to P0 and P1. GitLab review documentation.
Treat the beta as a deployment to validate on your actual GitLab host. “GitLab support” does not remove the need for the right connection, permissions and hooks, and does not imply every separate Codex Security feature has the same integration.
For retention, ChatGPT-authenticated Codex follows the workspace's data policies, while API-authenticated use follows the API organization's data-sharing and retention settings. Business states that business data is not used for training by default; Enterprise includes retention and residency controls. The cited pages do not publish one universal day count covering every Codex cloud review artifact. Authentication and data-policy distinction.
Ask the workspace owner for the actual rule for cloud tasks and review history. Do not copy an API retention statement into the approval for a ChatGPT-authenticated cloud reviewer.
- An existing Codex subscription can serve coding and review.
- Applicable repository instructions make project assumptions available to the reviewer.
- Automatic GitHub review and native GitLab beta provide hosted routes.
- Business offers a shared workspace rather than separate consumer accounts.
- Included capacity is shared with other Codex work.
- An API key does not activate the connected GitHub review service.
- GitLab beta and self-managed setup require validation on the team's installation.
- No single public retention duration describes all cloud review artifacts.
Claude Code: Local Review and Managed PR Review Are Different Purchases
Claude Code is Anthropic's coding agent with a local review command and a separate managed Code Review service. Choose the local command when your team already works in Claude Code and can request a review before opening the PR. Consider managed review for selected high-consequence GitHub changes when automatic, separately billed verification fits the budget.
Verdict: For five developers, reuse local Claude Code review first. Managed review on every routine push is a substantial new expense, even when the team already has eligible seats.
Best for: Claude Code teams reviewing a branch before handing it to a human.
Standout: Local review runs with a separate context; managed review has dedicated review-only instructions and verification.
Pricing: Pro $20 monthly locally; Team Standard $25/user monthly; managed review averages $15 to $25 per run, billed separately.
Free trial: No separate managed-review trial promised; managed service is a research preview for eligible Team and Enterprise organizations.
Every Plan and the Five-Developer Cost
Claude Free costs $0 but is not the paid Claude Code subscription. Pro is $20 monthly, or $200 upfront for a year. The page displays the annual rate as $17 per month, a rounded label. Five Pro subscriptions therefore cost $100 monthly, or $1,000 annually with an effective monthly cost of about $83.33. Live Claude pricing.
Max 5x is $100 a month and Max 20x is $200, making five equal seats $500 or $1,000 monthly. Those are subscription usage levels rather than fixed counts of reviews. Max pricing.
Team Standard is $25 per seat monthly or $20 with annual billing: $125 monthly for five, or $100 annual monthly equivalent. Premium is $125 monthly or $100 annual equivalent per seat: $625 monthly for five, or $500 annual equivalent. The respective annual commitments are $1,200 and $6,000. Enterprise lists a $20-per-seat monthly equivalent billed annually plus API-rate usage; five-seat arithmetic is $100 equivalent before usage, subject to contract eligibility. Education is institution-priced and API access is usage-priced, so neither has a general five-developer fixed quote.
The managed service is available in research preview for Team and Enterprise, and is not available to organizations with zero data retention enabled. Its token bill is separate from the plan's included usage. Anthropic states an average of $15 to $25 per review, depending on the change, codebase and verification work. Managed review pricing and eligibility.
Manual managed triggers are sensible for a small team selecting payment changes, authentication changes or a difficult migration for additional scrutiny. Reviewing every push multiplies spending. Set the Code Review service's monthly spend cap and make the behavior when it is reached explicit to the team.
False Positives and Tuning
Local /code-review runs as a background reviewer with its own context and can target a diff, branch or PR. Lower effort settings prioritize fewer, higher-confidence findings; a broader review can also include cleanup suggestions. Ask for the failure condition and keep optional cleanup separate from correctness blockers.
The instruction-file distinction is crucial. Local review reads CLAUDE.md, not REVIEW.md. Managed Code Review uses CLAUDE.md as project context and REVIEW.md for review-specific behavior. A local review will not automatically inherit the managed service's carefully written review-only policy.
For managed review, use REVIEW.md to define severity, suppress categories already enforced by CI, skip generated outputs, and require source evidence for behavior claims. Tell it how to converge on rereview: once the substantial finding is fixed, newly discovered cosmetic work should not prolong the same PR indefinitely. A short review policy focused on your real risks is easier to maintain than a general coding handbook.
The managed service does not approve the PR or block merging merely because it finds issues. A team that wants findings to gate a merge needs an explicit workflow connecting them to that decision. Keep the author able to dispute a finding with evidence rather than treating every bot annotation as a veto.
GitHub, GitLab and Retention
Managed Code Review is the GitHub PR service. Local review can inspect GitLab changes and, with a current supporting client and glab, post findings as a merge-request note. Claude can also run in your own GitLab CI/CD. Those local or self-run routes should not be sold as an equivalent managed GitLab bot.
Retention changes with the account and data preference. Consumer Pro and Max data is retained for five years when model improvement is allowed, or 30 days when it is not. Commercial Team, Enterprise and API use has a stated standard 30-day period. Qualified Enterprise zero data retention requires separate enablement; it is not automatic with an Enterprise seat, and managed Code Review does not support it. Claude Code data usage.
Local CLI transcripts are also stored in plaintext under ~/.claude/projects/, with a default 30-day cleanup period that can be changed. Desktop or Cowork sessions continued there have separate default exceptions. Sending transcripts through /feedback, /bug or /share creates a separate five-year retention path. Include local files and support submissions in the team's rule, as well as provider storage.
- Existing paid Claude Code access can support a review before the PR opens.
- A separate review context gives the author another pass over the diff.
- Managed review-only instructions can require evidence and limit rereview noise.
- Local and self-run workflows provide a GitLab route.
- The managed service's variable per-run spending is additional to eligible seats.
- Local and managed review use different instruction files.
- Managed review is GitHub-focused and unavailable under zero data retention.
- Consumer preferences, local transcripts and feedback submissions have different retention periods.
Security-First Scanning: Codex Security
Codex Security: Add It for a Threat Model, Not for More General Comments
Codex Security is OpenAI's application-security agent for investigating vulnerabilities with repository and threat-model context. Choose it when the team needs to establish whether an attacker can reach and exploit a suspicious path. It complements a correctness reviewer and the deterministic checks already in CI.
Verdict: Use Codex Security for the security question, with documented access and reporting thresholds; do not count a quiet general review as evidence that the application is secure.
Best for: Small teams making changes to authentication, authorization, untrusted input or other security boundaries.
Standout: Threat-model-aware investigation and attempted validation, with separate automatic and manual reporting thresholds.
Pricing: Security Review is available on Pro, Business, Enterprise and Edu; it consumes included Codex allowance or ChatGPT credits.
Free trial: No guaranteed separate trial. Eligibility and workspace Security access must be checked.
Plans and the Five-Developer Cost
There is no published standalone fixed per-seat Codex Security subscription to multiply by five. Security Review is not available on Plus. Eligible Pro bases remain $100, $200 or $500 a month, making five seats $500, $1,000 or $2,500. Business is $25 per user monthly or $20 annual equivalent: $125 or $100 for five. Enterprise and Edu are custom. The base buys the eligible plan; Security access and credit consumption still need verification. Security Review eligibility.
False Positives and Tuning
Write a threat model that names the assets, trust boundaries, attacker capabilities and security assumptions. A reviewer considering an unauthenticated public endpoint should reach a different conclusion from one examining a restricted administrative function. Leaving that context implicit makes a speculative warning harder to resolve.
Automatic Security Review defaults to reporting High and Critical findings; manual requests include Medium, High and Critical. Minimum severities can be set independently, with path-based overrides. The threshold controls which findings are posted to GitHub, while the full report remains in Codex. Filtering the comment feed is therefore different from removing the underlying report.
Security scans can attempt to validate vulnerabilities. A finding that was not validated is not automatically a false positive: the environment or reproduction attempt can be incomplete. Ask for the entry point, exploit preconditions and evidence before deciding whether to fix, suppress or investigate further. The Security FAQ explains the scan and validation workflow.
The CLI provides a false-positive marking command with an occurrence ID and reason, along with severity-based CI failure and an estimated-cost cap. Use the reason to record the actual protective condition. An estimated cap helps control work but should not be presented as a guaranteed invoice limit. CLI reference.
GitHub, GitLab and Retention
Hosted Security Review documents GitHub triggers, including @codex security review, review on opening a PR, on each push, or alongside general code review. The local CLI can run in GitLab CI/CD and produce SARIF, a standard machine-readable security findings format. That is a documented GitLab security route; it does not establish a native hosted GitLab Security bot equivalent to the general Codex beta.
Cloud scans use temporary isolated repository containers and destroy them after extracting results. The reports and extracted artifacts still exist. Apply the workspace's retention policy rather than describing the entire service as zero retention because the execution container is short-lived.
The CLI also persists scan output by default under $CODEX_HOME/state/plugins/codex-security/scans/, including a local workbench database. Your team controls deletion of those files and of any CI artifacts it publishes. A vulnerability report can reveal sensitive code paths even after the repository clone is gone.
- Threat-model context focuses investigation on reachable security risks.
- Validation can provide more evidence than a speculative code comment.
- Separate reporting thresholds reduce automatic low-severity interruption.
- CLI and GitLab CI/CD provide a self-run security workflow.
- Plus does not include Security Review, and eligible plans still require access.
- It does not replace ordinary correctness review or deterministic security checks.
- GitLab CI support is a different setup from a native hosted review bot.
- Ephemeral execution still leaves reports and local or CI artifacts to govern.
One Real PR Reviewed by Three Bots
A public negative-cache change shows why overlapping comments and follow-up reviews need interpretation. jdx/mise-versions PR #224, merged on 6 June 2026, added caching for failed GitHub release requests. A negative cache remembers an error temporarily so repeated requests avoid hitting the upstream service again.
CodeRabbit, Greptile and Cursor Bugbot all left review comments on this PR. The record contains initial reviews and later reviews of revised commits. It provides concrete evidence of what the products flagged, but it is not an experiment where all three received a frozen identical commit and settings.
CodeRabbit caught error preservation. If the GitHub request fails and the attempt to store that failure also throws, the cache exception can replace the useful original error. A caller expecting an upstream error, such as a missing release, can then handle the failure incorrectly. The bot's comment identified a narrow issue rather than a general request to refactor.
Greptile caught the scope of a rate limit. A 403 can mean that one token is rate-limited. Caching it as a failure for the requested resource suppresses token rotation, even when another token could succeed. In this implementation, that could produce a five-minute failure window. Greptile also asked for tests of expiry and error-specific lifetimes. The test request is a coverage concern, not another independently established runtime bug.
Bugbot caught stale state and a later edge case. Its initial stale-cache warning concerned preserving a negative result after a successful fetch should have cleared it. It also raised the rate-limited 403 concern, overlapping Greptile. After the first fix, a later Bugbot comment pointed out a secondary rate-limit response identified by Retry-After that the revised classifier still missed.
The first follow-up patch protects the original error from cache-write failure, clears negative cache after success, avoids negative-caching classified rate limits, and adds relevant tests. The next patch handles Retry-After rate-limit classification and tests it. Those inspected code changes support the practical usefulness of the comments.
AI Code Review Benchmark: What This PR Proves
This PR supports a finding-by-finding comparison, not a vendor ranking. CodeRabbit contributed an error-handling finding; Greptile and Bugbot overlapped on a rate-limit issue; Bugbot's later run inspected a changed implementation and found another edge case. Counting comments would exaggerate the number of distinct bugs and ignore the different inputs.
The thread does not contain a human-labeled set of all true and false findings, so it cannot establish each tool's false-positive rate or recall. Fixes following comments are useful evidence, but they do not show every defect the tools missed. The conclusion for a CTO is to inspect actionable findings, overlap and rereview behavior, then run a comparable pilot on the team's own changes.
Who Should Pick What
Choose the review location your team can operate consistently, then price the workload in that location. Keep the initial shortlist small enough that the team can label findings rather than merely install integrations.
GitHub AI Code Review
Choose CodeRabbit Essentials when your immediate need is a dedicated automatic reviewer for ordinary private PRs and its limits fit your workload. At $150 monthly for five developers, it has a clear base budget and direct tuning controls.
Choose Greptile when repository-specific review rules and directory controls are compelling enough to justify author-level credit management. Start with a known effort tier and flex cap. Compare its findings with CodeRabbit on representative changes; the public PR does not settle that purchase for your codebase.
Choose Bugbot when Cursor is already the coding workflow and the team values moving between pre-push review, PR discussion and fixes. Judge the incremental review bill if the seats already exist, and the full subscription-plus-usage bill if they do not.
GitLab AI Code Review
CodeRabbit and Greptile provide direct GitLab review, with self-managed deployment needs checked against their plans. Bugbot documents GitLab and Self-Hosted support too. For a conventional bot installation, start with those native routes.
Codex now documents native GitLab review in beta, including self-managed setup. Trial it on the host and permission model your team actually uses. Claude Code's local review and self-run CI are valid GitLab options, but require your workflow to execute them. Codex Security's documented GitLab CI route is similarly a security integration you operate, rather than a promised hosted GitLab Security bot.
Best AI Code Review Tool if You Already Pay for an Agent
Use Codex or local Claude Code first when the author can reliably request a review before handing over the change. You already have coding-agent access; the question is whether its additional consumption and findings are useful. Put the right instructions in the files that route actually reads.
The choice flips to an automatic PR reviewer when manual invocation is unreliable or reviewers need a durable shared discussion on every change. A slightly cheaper subscription does not compensate for reviews that the team forgets to run. Conversely, adding a second automatic service is hard to justify if the existing review route consistently catches actionable defects without creating another queue of comments.
Use managed Claude review selectively when the change warrants its additional verification spending. Add Codex Security for security boundaries and investigation, with explicit access and report handling. Neither purchase should be justified by a universal model leaderboard.
Free AI Code Review Tools
Greptile Starter is a genuine free entry for one active developer, not five. CodeRabbit Free private PR summaries are not the full private review product, although its open-source and local allowances can be useful. Codex's lightweight Free and Go access should not be assumed to provide the same automatic GitHub allowance as Plus; GitLab's documented beta eligibility is a separate statement. Claude Free is not a free Claude Code seat.
For a five-person private team, first reuse access already purchased and check its actual limits. “Free to install” and “free to review every private PR” are different budget promises.
False Positives: Set the Review Contract Before the Pilot
Review noise has several causes, and only some are false positives. A false positive asserts a defect that does not occur under the actual program's conditions. A true cosmetic suggestion can still be low-value noise. A duplicate finding repeats work already under discussion. A speculative security concern may need investigation before either label is defensible.
Require each actionable correctness comment to identify the changed behavior, the path making it reachable, the impact and the source evidence. A specific caller or test is more useful than a confident severity badge. Have the author explain a disputed finding and have another developer resolve the disagreement for important cases.
Start a pilot with 20 representative PRs, a proposed evaluation sample rather than a product limit. Include the kinds of change the team ships: routine edits, a migration, failure handling and a security boundary. For the bots being compared, preserve the commit, instructions and trigger settings. Label distinct findings as useful, wrong, already covered or true but too minor; keep unverified concerns separate.
Measure the work the team actually had to do: which findings changed the patch or its tests, which required clarification, and which were ignored. Deduplicate the same root cause across tools. A reviewer catching the rate-limit cache bug in the public PR and another reviewer repeating it created corroboration, not another independent defect.
Tune the specific source of noise. CodeRabbit's profile narrows feedback; Greptile's strictness and categories narrow posted comments; Bugbot needs its own instructions and sensible triggers; Codex needs applicable review rules; Claude needs the file appropriate to local or managed review; Codex Security needs threat assumptions and evidence. Increasing effort without clarifying those inputs can increase work without improving the decision.
Keep the human approval rule explicit. A quiet bot may have filtered findings, skipped a path, exhausted its allowance or failed to understand the change. No comments should not be interpreted as a complete audit.
How These Were Picked
These six products cover the review locations in the brief: dedicated PR bots, the editor vendor's reviewer, coding agents and security-first investigation. The selection favors a workflow a small team can adopt, a price it can model, and controls it can use to contest or reduce irrelevant feedback.
Pricing, plan names and capabilities were checked against primary vendor pages on 2 October 2026. The five-developer totals and evenly distributed review scenarios are calculations from those pages. The real-PR evidence comes from inspected public bot comments and follow-up commit diffs. The products were compared through documentation and public evidence, not exercised in private trials for this article.
Vendor benchmark claims did not determine the recommendations. A result measured on another corpus cannot establish the noise, integration work or invoice on your repository. The strongest evidence here is narrower: named findings on a traceable PR, current controls and explicit budget assumptions.
A broader catalog can include other bots and static analyzers, but adding them without the same depth would make this decision less useful. No active affiliate partner honestly fits this AI reviewer shortlist, so none was inserted as a paid recommendation. Tool links follow the site's normal monetized-link system where a matching program exists; commercial availability did not determine the verdict.
The Ones to Avoid
Avoid CodeRabbit Free as your required private correctness reviewer. A summary does not deliver the paid review you are trying to procure. Start the paid trial and assess the findings.
Avoid buying Greptile as “$30 for unlimited reviews.” Effort, reruns and non-pooled author allowances change the cost. Choose a flex limit before broad automatic rollout.
Avoid budgeting new Bugbot purchases with the legacy standalone seat price. Current usage billing, the team's Cursor subscription and any Autofix activity are the relevant inputs.
Avoid managed Claude review on every routine push if the extra usage bill does not fit your team. Its local review route is a different purchase decision; reserve the managed service for work whose risk warrants the estimated cost.
Avoid Codex Security as a substitute for general review. It asks a security question and requires eligible access. It cannot decide whether a feature matches the product requirement or whether an operational migration is acceptable.
Avoid any configuration that makes a bot's approval your only merge decision. Keep CI, human review and the ability to dispute a finding connected to the actual release risk.
Frequently Asked Questions
Is there any AI tool for code review?
Yes. CodeRabbit and Greptile review connected PRs, Cursor Bugbot links review to Cursor's workflow, and Codex and Claude Code can review work as coding agents. Codex Security adds a narrower vulnerability-investigation route. Choose the location and reporting behavior before comparing subscription prices.
Which AI is best for teams?
CodeRabbit Essentials is the default dedicated bot recommendation here for a small team wanting routine automatic PR feedback: $150 monthly for five developers within the plan's limits. An existing Codex or Claude Code workflow is the better starting point when the team already requests reviews reliably. Security work requires a separate scope decision.
Can ChatGPT do a code review?
Yes, ChatGPT can discuss supplied code, and Codex provides a repository-aware coding and review workflow through eligible access. A chat response based on a pasted snippet has different context from connected Codex review. Check the account's data settings and avoid assuming the model has inspected files it was never given.
What are the top 5 code review tools?
The five general-review options compared here are CodeRabbit, Greptile, Cursor Bugbot, Codex code review and Claude Code. Codex Security is the sixth featured product and serves a separate security purpose. They are grouped by workflow rather than placed in a universal benchmark ranking.
Is code review obsolete?
No. AI review can identify defects and help an author prepare a change, but a team still has to judge product intent, operational risk and acceptable tradeoffs. Human approval and CI also provide evidence that a bot's absence of comments cannot supply.
What are the key differences between Copilot and CodeRabbit for code review?
GitHub Copilot code review is part of GitHub's assistant workflow, while CodeRabbit is a dedicated reviewer with documented GitHub and GitLab integrations and its own review configuration. Both need the right repository context and a policy for disputing findings. GitHub's Copilot review documentation describes how to request and use its reviews.
Why don't people like Copilot?
There is no single defensible answer about everyone's preferences. For a CTO, assess whether the reviewer misses repository context, repeats existing checks or creates comments the team cannot act on. Compare those outcomes on your PRs rather than treating a complaint or vendor claim as a measured false-positive rate.
Can Copilot perform code review?
Yes. GitHub documents requesting Copilot review and working with the resulting feedback. Its existence does not make it the automatic choice for GitLab or a substitute for a dedicated security investigation. Evaluate it against the workflow your team actually needs.
Is there a better AI than Copilot?
There can be a better fit for a specific team. CodeRabbit or Greptile may fit a dedicated PR-bot requirement, Bugbot may fit a Cursor workflow, and an existing coding agent may cover a pre-push review. Use actionable findings, noise, host support and actual spending to decide; no vendor benchmark settles all four.
Get the Claude Code and Codex setup checklist to establish your coding-agent workflow before adding another review subscription.
- Last Updated
- Oct 2, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Best AI Email Assistants in 2026: Fyxer, SaneBox, Superhuman, Shortwave, Gemini and Copilot (Compared)
Compare Fyxer, SaneBox, Superhuman, Shortwave and native Gmail/Outlook AI by job, live prices, setup time and mail storage.Oct 2, 2026AI
Granola Alternatives: Circleback, MeetGeek, Claap, Krisp, Otter, Fireflies and Fathom (Compared)
Compare Granola alternatives by Windows support, bot-free capture, team sharing, CRM integrations, languages and verified per-seat prices.Oct 1, 2026AI
Gamma Pricing (2026): Plans, Credits and Team Costs
Gamma Free, Plus, Pro and Ultra prices verified October 2026. Compare credits, exports, annual billing and solo or team costs.Oct 1, 2026AI
Wispr Flow Pricing (2026): Free Caps and Team Costs
Wispr Flow costs for 1, 5 and 20 people, monthly vs annual billing, free word limits, education discounts and cheaper dictation alternatives.Oct 1, 2026AI
How to Use Muse for Small Business
Set up Meta’s Muse for Small Business, connect Shopify and social accounts, and run a weekly review with approval rules and published pricing.Oct 1, 2026AI
Gemini 4 Argon Explained: Access, Cost and When to Switch
Gemini 4 Argon has restricted access and an undated price step. Compare official rates, published benchmarks and when to evaluate it.Oct 1, 2026AI
Wispr Flow Review (Verified October 2026)
Wispr Flow's current prices, work-week evidence, speed claims, coding prompts and privacy limits. A clear rule for Free, Pro or Superwhisper.Oct 1, 2026AI