Gemini 4 Argon Explained: Access, Cost and When to Switch
Gemini 4 Argon has restricted access and an undated price step. Compare official rates, published benchmarks and when to evaluate it.




Budget Gemini 4 Argon at $4 input and $20 output per million tokens when evaluating a switch, even though Google announced a $2/$10 introductory rate. As verified on 1 October 2026, access is restricted, and Google has dated neither the wider rollout nor the introductory price's end. Google's announcement supports an evaluation plan for difficult jobs; your production migration needs access and workload evidence.
What Gemini 4 Argon changes for your model plan
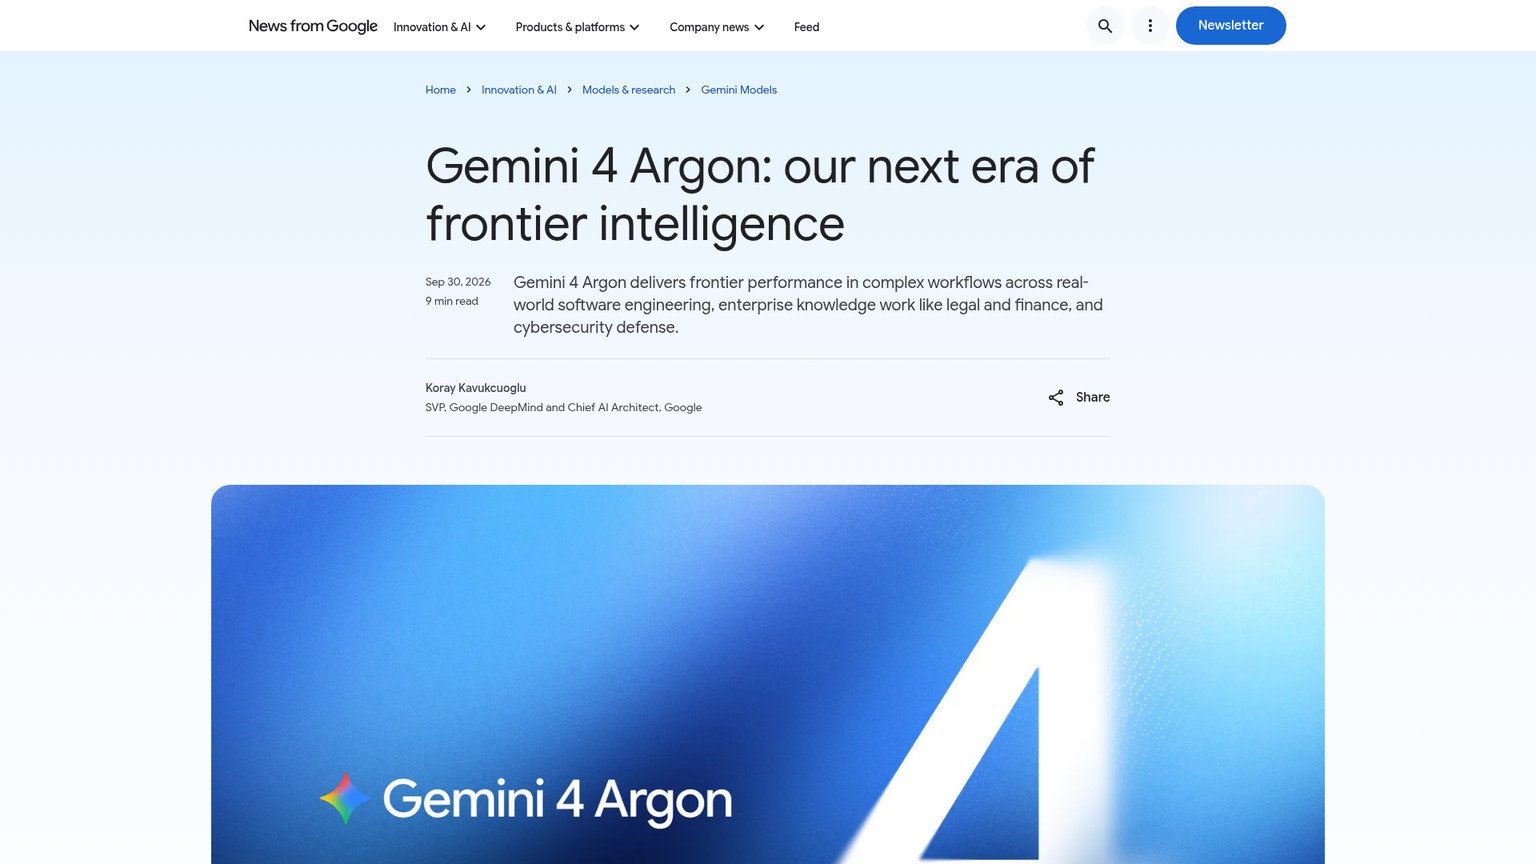
Gemini 4 Argon, Google's new model for complex, sustained work, changes which jobs deserve an evaluation before it changes your default production model. Google announced it on 30 September 2026, with a restricted rollout to trusted cyber defenders and an initial cohort of trusted testers. The announcement describes longer reasoning, software engineering, enterprise knowledge work and defensive cybersecurity.
The practical distinction is access. A model can have published prices and impressive results while your organization still cannot use it. Keep a current provider available for anything your quarter depends on; make Argon a conditional evaluation line in the plan.
Access today: selected defenders and trusted testers
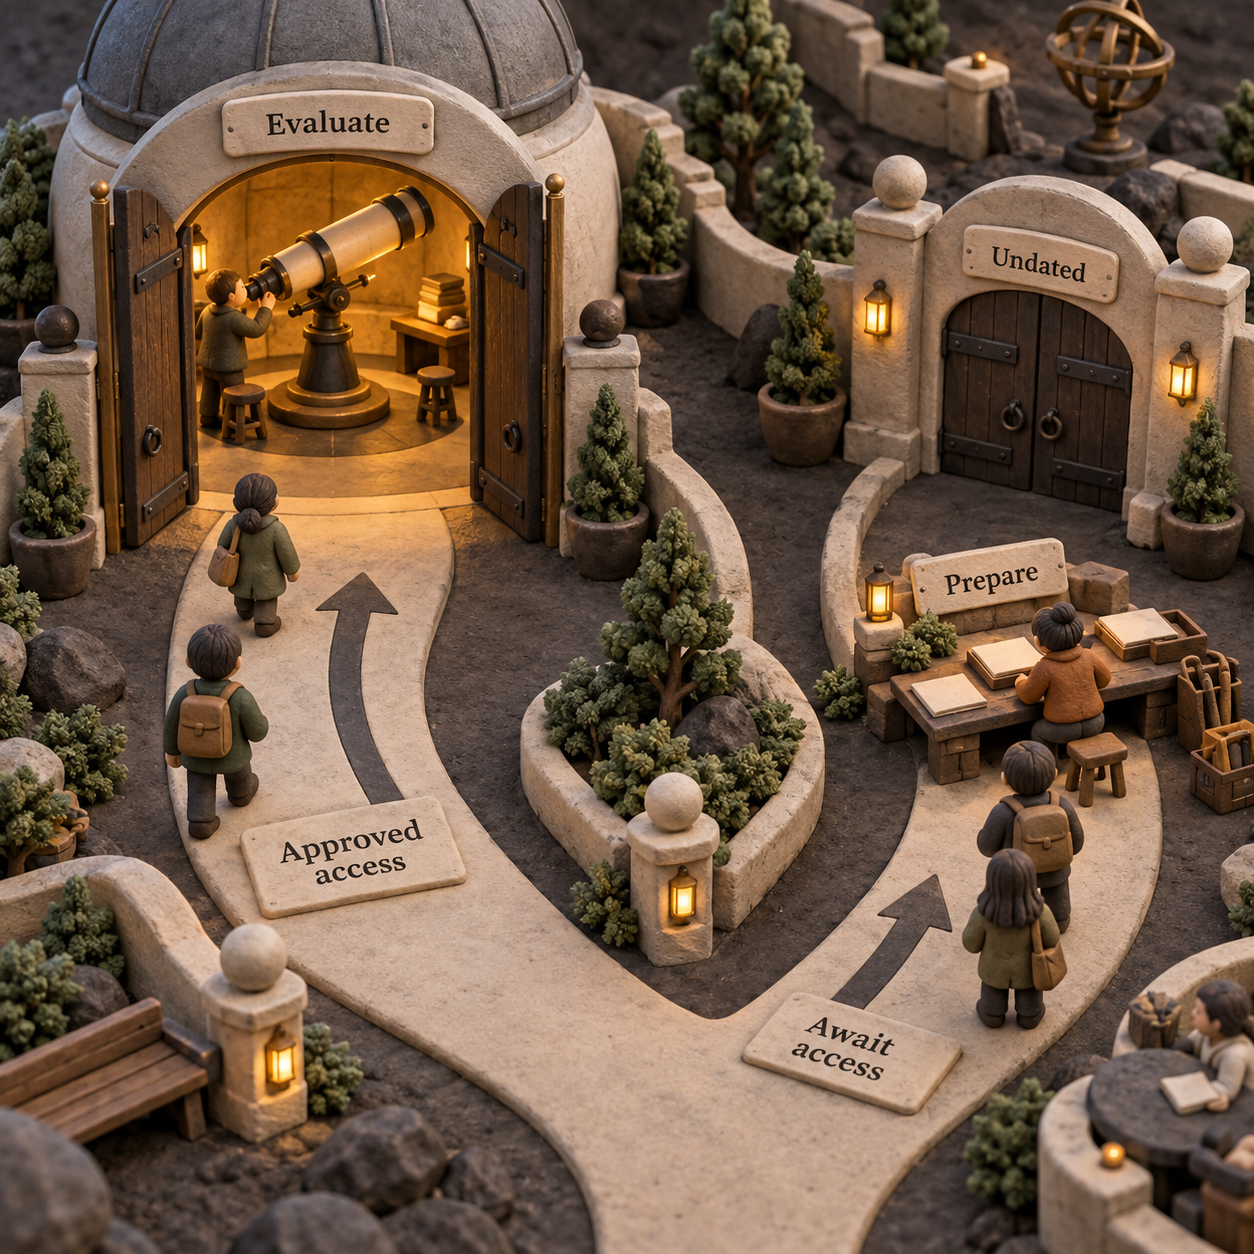
As checked on 1 October 2026, Google's announcement names early cyber defenders and trusted testers. The current Fairwind Program page confirms Argon access for a set of approved partners, rather than every applicant or every Google Cloud customer.
Fairwind is Google's controlled early-access program for cyber defense. Google launched the program on 2 September 2026; that date belongs to the program, not the Argon model. It prioritizes governments, critical infrastructure operators and core technology platforms. Defensive academic labs may also apply.
Membership is an eligibility process. Google vets applicants, restricts employee access and prohibits partners from redistributing model access. For a security lead, the immediate action is to establish whether your organization and intended users have approved Argon access. Being a paying customer alone does not establish it.
Access next: paid API customers and Google AI Ultra subscribers
Google names paid API customers and Google AI Ultra subscribers as the starting groups for the next wider rollout. Its 30 September announcement supplies no calendar date for that step or general availability.
An Ultra subscription is therefore a future access route in this announcement. Do not buy it solely on an assumption that Argon is already available in your account. API token charges and a consumer plan's entitlements are different billing measures. The announcement does not specify Argon usage allowances within Ultra.
Gemini 4 Argon price: compare the later rate
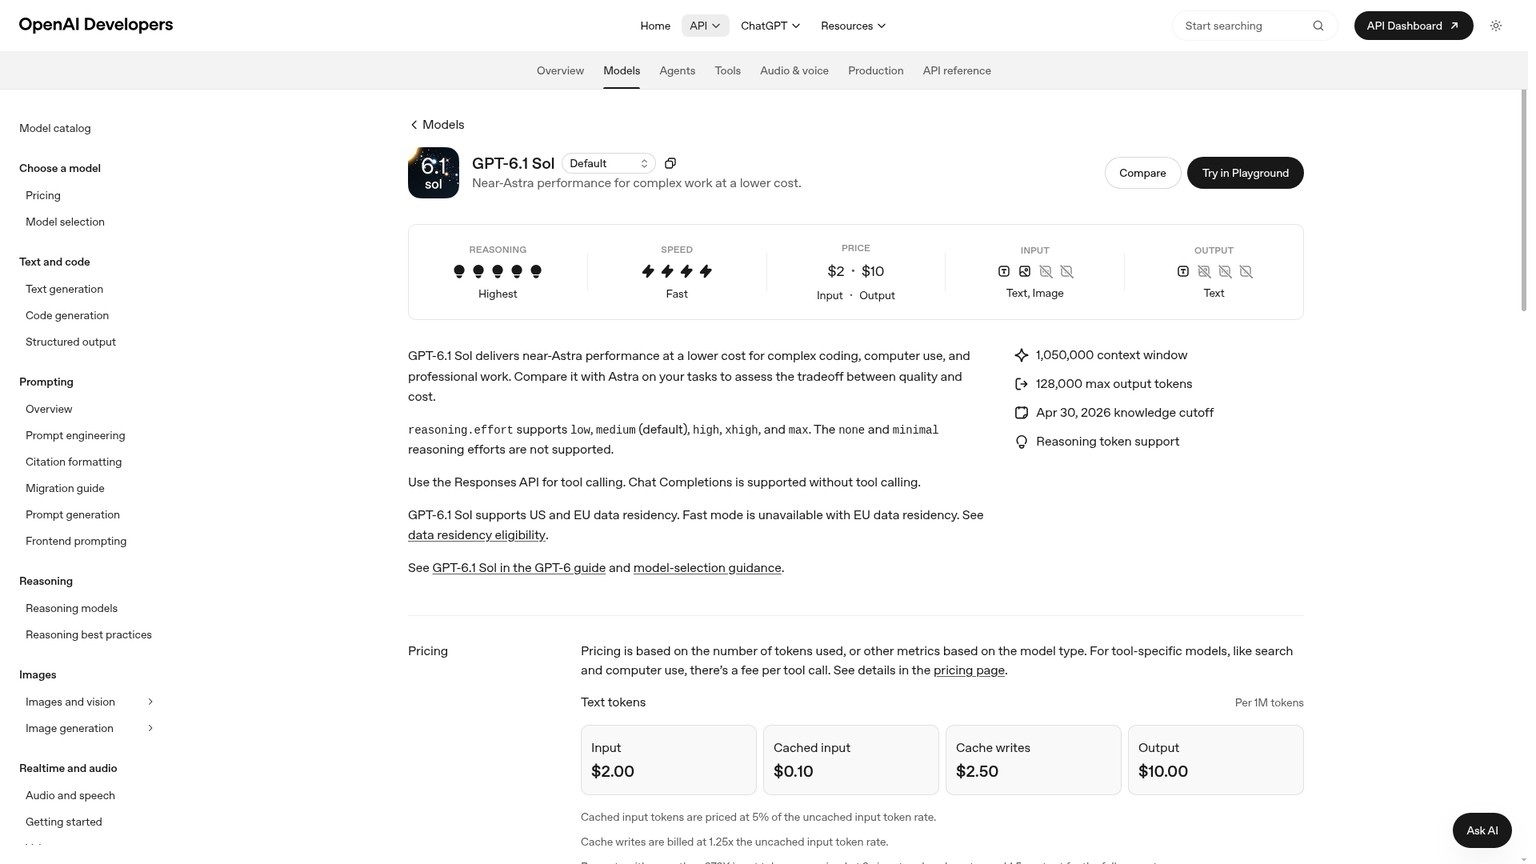
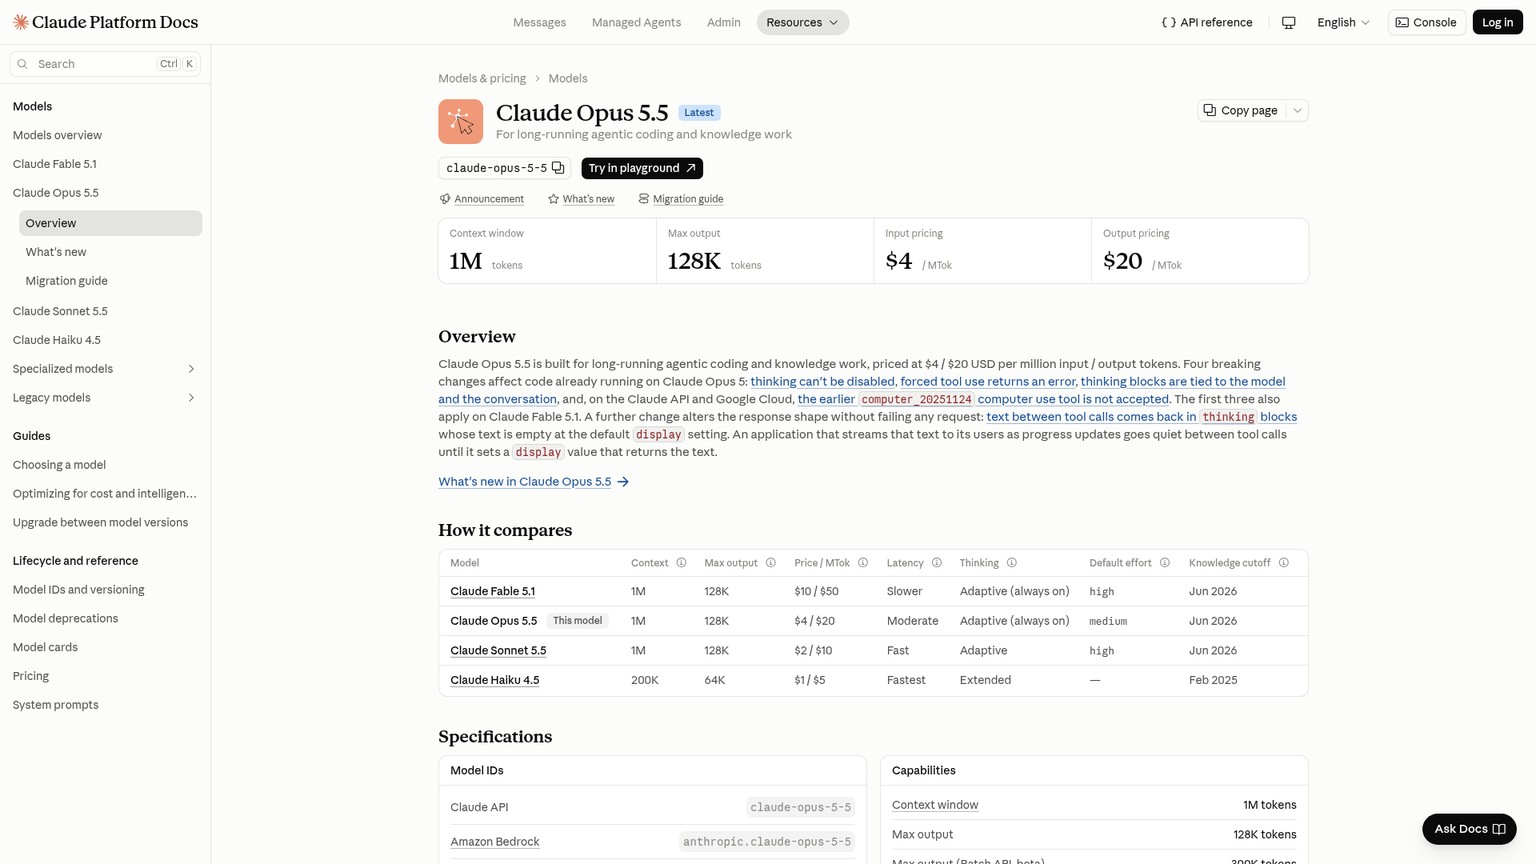
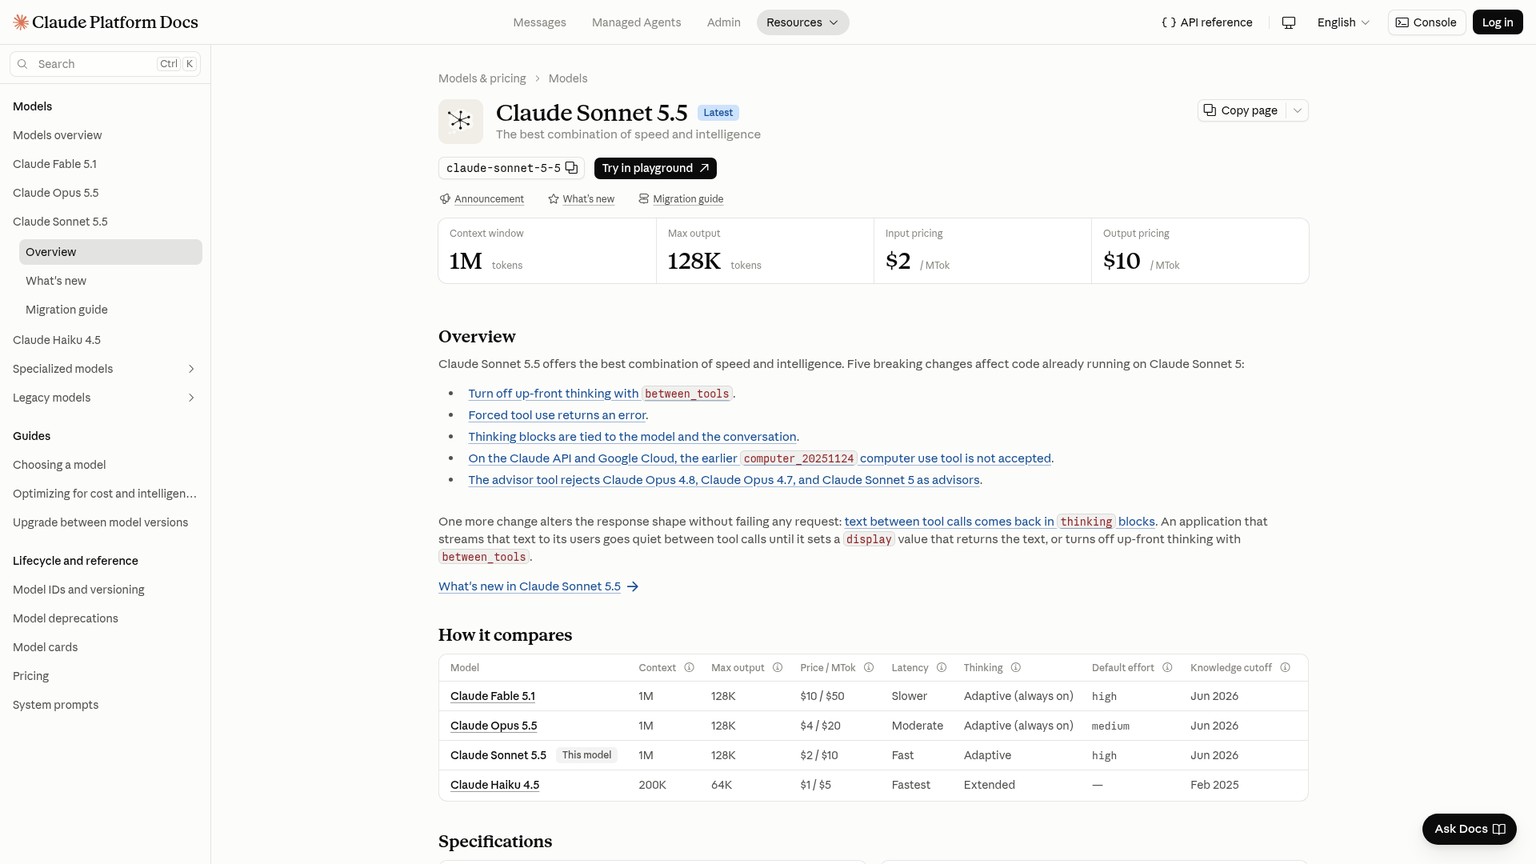
Argon's introductory token price matches GPT-6.1 Sol and Claude Sonnet 5.5's base rates; its announced later price matches Claude Opus 5.5. That makes the later rate the useful budget comparison.
A token is a unit of text processing: you pay for input sent to a model and output it produces. The table uses USD per 1M tokens, standard direct API list prices and uncached input. Prices and access statements were verified against each maker's own pages on 1 October 2026.
OpenAI GPT-6.1 Sol was released in the API on 29 September 2026. Its quoted $2/$10 rate applies to prompts with up to 272K input tokens. Above that threshold, OpenAI doubles input and cache rates and charges 1.5 times the output rate for the full request. Large-input jobs need that qualification even when their output is short. Official OpenAI documentation supplies the threshold.
Anthropic Claude Opus 5.5 has been active since 22 September 2026. Its model page lists Claude API, Amazon Bedrock, Google Cloud, Microsoft Foundry and Claude Platform on AWS. It gives buyers an available candidate at Argon's later base price; it does not establish equal performance on your jobs.
Anthropic Claude Sonnet 5.5 has been active since 28 September 2026, with the same listed API and cloud routes. Its model page verifies the $2/$10 base rate. It belongs in the lower-cost baseline alongside GPT-6.1 Sol when you can complete the job with either.
These are rate comparisons. Different tokenizers, output lengths, cache writes, processing tiers and tool charges can change the bill. Cloud availability also does not promise identical cloud pricing. Keep the same task and acceptance criteria when comparing costs.
For the broader plan decision, use Gemini pricing. For an available OpenAI upgrade decision, read GPT-6.1 Sol vs GPT-6 Sol.
The 1M-token output limit earns its place on long jobs
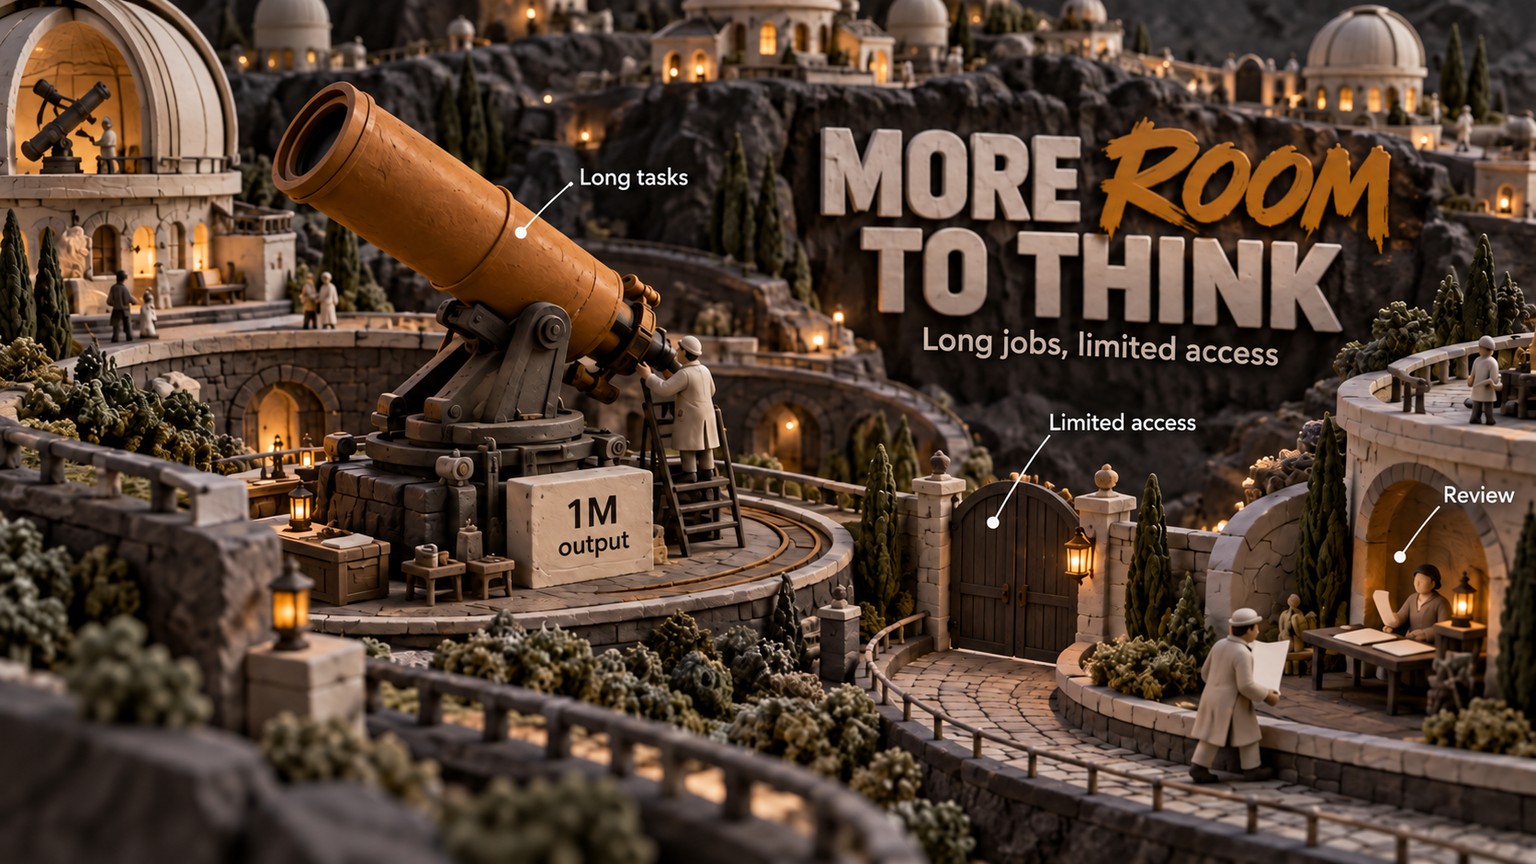
The meaningful limit change is output, the model's room to reason and generate during a trajectory. Google says Argon's output ceiling rises to 1M tokens from 64K. That is roughly 15.6 times the nominal headroom, calculated from Google's rounded figures. It is not evidence of a larger input context window or faster completion. Google's limit description frames it around sustained work.
Input context is what the model can read at once. Output allowance is how much it can produce. A giant reading window cannot help a job that runs out of room while working through a solution, and a giant output allowance does not guarantee a correct solution.
The extra allowance matters when a task has dependent steps. A code migration can require inspecting files, changing interfaces, checking tests and revising a proposed patch. A financial investigation can require reconciling documents, following discrepancies and assembling a supported conclusion. Ending early can leave the expensive part unfinished.
Google names codebase migrations, algorithm design, multi-step financial research, legal research and drafting, chart analysis and long-video understanding as target areas. The jobs worth evaluating have a clear completion condition:
- A solo technical builder: try a repository migration that currently ends with an incomplete patch. Judge the result by tests and reviewable changes, rather than the length of its explanation.
- A mid-market CTO: choose a bounded maintenance job with an owner and a rollback path. Ask whether the model reduces restarts and reviewer work before considering a larger rewrite.
- A senior operator: choose a research packet that requires reconciling several documents and checking charts. Require traceable evidence for the final recommendation.
Those are proposed evaluations, not results from tests performed for this article. Google's internal migration examples also retain automated checks and human review before production.
A funded founder with a reliable short-request workflow has little reason to pay for unused headroom. The Gemini review addresses the broader product and workflow fit; Argon's larger allowance only matters if it removes a constraint in a named job.
The quarterly budget and the cost per accepted job
An unchanged uncached workload costs twice as much after the introductory period. Both announced rates double. Since Google gives no switch date, a quarter-long forecast needs a later-rate scenario rather than an assumed promotional duration.
Consider a hypothetical workload of 100 jobs per month, each using 100K input tokens and 20K output tokens. That totals 10M input and 2M output tokens:
- Introductory Argon: 10 × $2 + 2 × $10 = $40 per month.
- Later Argon: 10 × $4 + 2 × $20 = $80 per month.
If access covers a full three-month quarter at that monthly usage, the token-only scenarios are $120 with introductory rates throughout or $240 with later rates throughout. A price switch partway through falls between them. This is a budget range, not a rollout prediction.
At identical billed quantities, GPT-6.1 Sol and Claude Sonnet 5.5 also total $40 at their quoted base rates; Claude Opus 5.5 totals $80. The example assumes each request stays within Sol's base input threshold. It does not assume all models tokenize the same material or consume the same amount of output.
Cached input reduces one part of the bill
Google announces 95% off input token pricing for cached input, meaning reused input can be charged at a lower rate. At the introductory $2 rate, that computes to $0.10 per 1M cached input tokens. Google's pricing statement is the input to that calculation.
If the hypothetical workload achieves 90% input cache hits, its input becomes 1M uncached and 9M cached tokens. Keeping output unchanged:
1 × $2 + 9 × $0.10 + 2 × $10 = $22.90 during introduction.
That is a token-rate illustration, excluding other charges. A 95% cached-input discount does not make the entire job 95% cheaper, because output still contributes $20 in this example. A reusable repository brief may help input costs; long reasoning still needs its own output budget.
Google's launch footnote gives the later $4/$20 rates without dating the switch or itemizing every future billing term. Recheck those terms when your access is enabled.
The crossover is accepted work
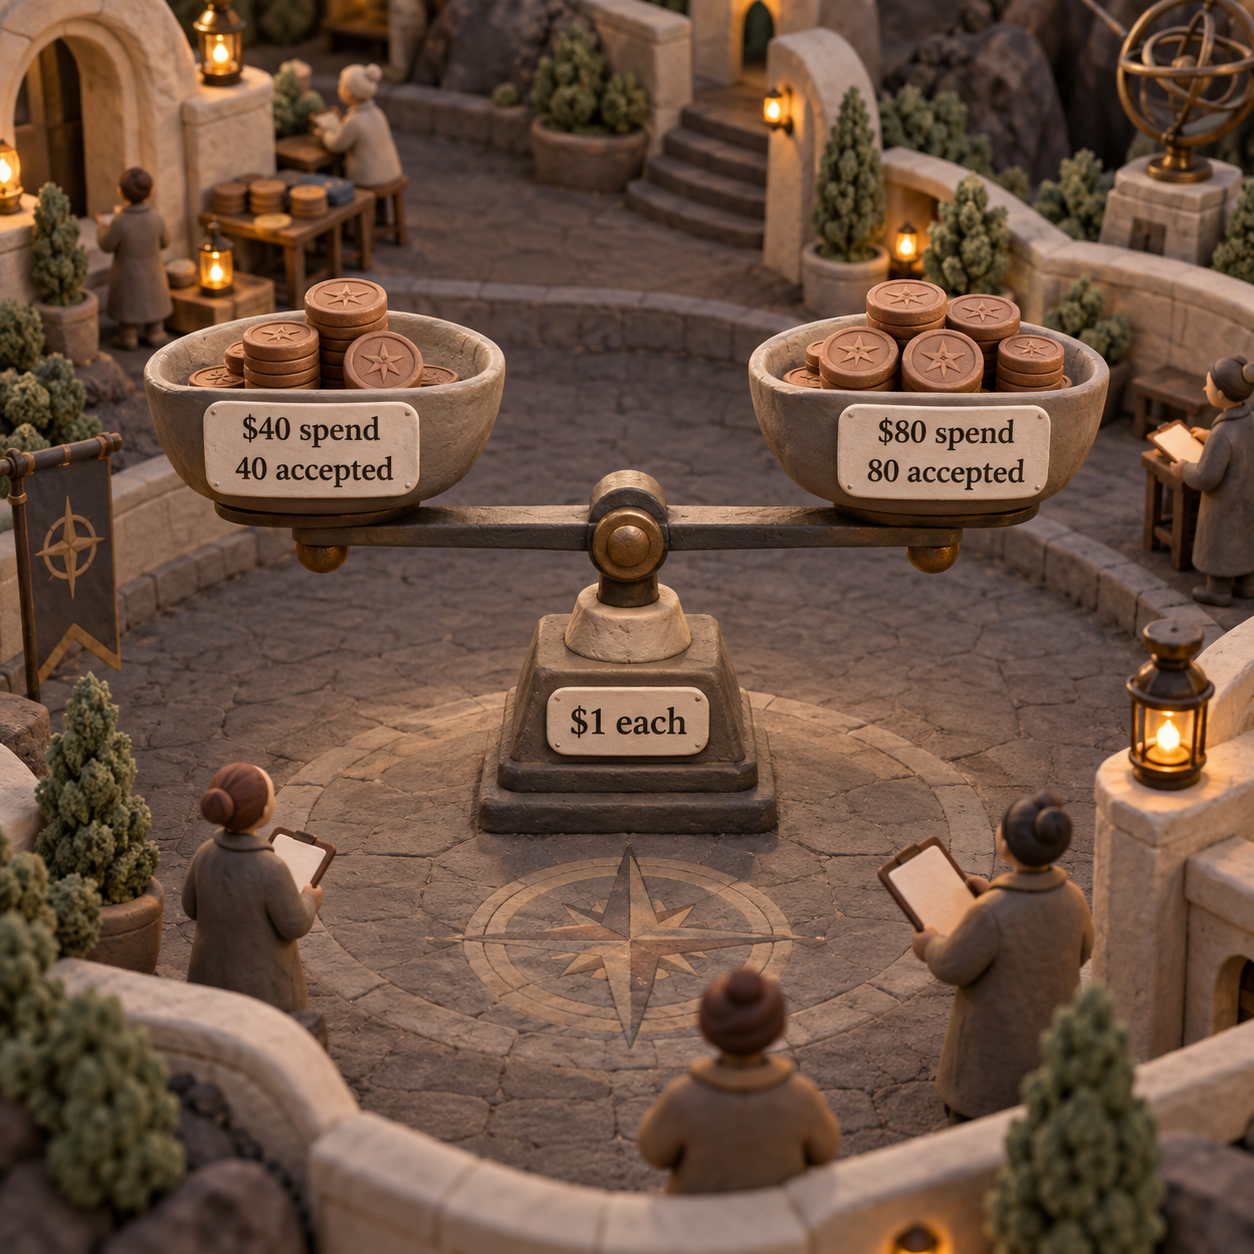
At the example's later rate, Argon costs $0.80 per attempt, against $0.40 at a $2/$10 base rate. If billed tokens per attempt stay fixed, doubling the fraction of accepted attempts offsets doubled token cost.
For illustration, a baseline accepting 40% of attempts costs $0.40 ÷ 0.40 = $1 per accepted job. A model accepting 80% at $0.80 also costs $1 per accepted job. These acceptance rates are assumptions used to explain the crossover, not scores measured for Argon or a competitor.
If your baseline already accepts 60%, acceptance alone would need to reach 120% to erase that premium under the same assumptions. It cannot. The business case then needs lower token consumption, less human review, or valuable work your current model cannot finish.
The full output ceiling also has a bill attached. A hypothetical 1M billed output tokens would cost $10 at introduction or $20 later, before input and other charges. A higher ceiling is useful capacity; spending to that ceiling needs a reason.
Google's benchmarks identify what to evaluate
Google's published numbers support a targeted shortlist of jobs. They do not establish your application's acceptance rate or savings. No hands-on model tests were run for this piece.
All four scores below are Google's reported results from its 30 September announcement.
The percentages measure different things under different evaluation conditions. Do not average them into a capability score or substitute DeepSWE's result for your own code acceptance rate.
In particular, long-video understanding does not prove reliable software changes. A vulnerability-remediation result does not promise the same cyber capabilities or safeguards for every future customer. Pick the benchmark closest to your blocked job, then verify the outcome under your own constraints.
What builders, operators and buyers should do differently
Builders should act now if approved access lets them evaluate a job their current model repeatedly fails to finish. Start with a bounded task and compare accepted outcomes, total billed tokens and reviewer effort. Keep an available provider as the baseline.
Builders awaiting access should prepare that evaluation and continue shipping. For a solo builder producing short patches, or a founder whose existing workflow is dependable, the larger output ceiling changes little until a recurring job needs it.
Operators should prepare the checks that make a long run reviewable. A CTO evaluating a migration needs clear scope, regression tests and an accountable reviewer. A senior operator evaluating research needs a source set and a way to verify the conclusion. Longer execution increases the amount of work you must inspect.
Buyers should reserve budget at the later rate and make migration conditional. Approved access, a finished result and a better cost per accepted outcome are the conditions. A published leaderboard or a consumer subscription purchase does not satisfy them.
Wait when the job already completes reliably at a lower price, when access is unconfirmed, or when you cannot measure whether the result is acceptable.
What's overhyped: the shortcuts to avoid
A named launch is not universal access. Google has announced Argon and selected early users have it. The next groups are named, but their start date remains undated. Keep that distinction in any procurement note.
A larger output ceiling is not a reliability score. More room can allow a model to finish a difficult trajectory; it can also produce more material to review. Longer work earns its cost when it improves an accepted result.
The Arena “Argon checkpoint” story is unverified for this decision. Google's announcement does not authenticate that pre-release checkpoint identity. Do not carry leaked model names, specifications or benchmark tables into a production plan. Use the named model and the published September 30 facts.
The introductory price is not a durable savings case. A business case that works at $2/$10 and fails at $4/$20 depends on a promotion whose end date Google has not supplied. Calculate both cases before committing.
The missing evidence that matters is your cost per accepted job at the eventual price. Google's published results are a reason to evaluate that question.
The Monday move: prepare a decision your team can measure
Give one owner a concrete evaluation brief next week. The result should be a switch decision you can defend when access arrives.
Name the blocked job
Choose a recurring task such as an incomplete repository migration, an authorized vulnerability fix or a document-and-chart research packet. Write down what an acceptable finished result looks like.
Record the baseline
Use your current available model. Track billed input and output, retries, acceptance and reviewer time. Keep the task and acceptance standard consistent.
Prepare the later-rate budget
Price the workload at Argon's announced $4/$20 rates. Keep the introductory case separately, with its expiry marked undated. Confirm account access before assigning delivery work to Argon.
Switch only when the job improves
Once you have access, compare completed acceptable work and total effort. Expand use when the gain covers the token premium and any extra review; keep the baseline when it does not.
Gemini 4 Argon questions
Is Gemini 4 Argon out?
It was announced on 30 September 2026 and has restricted early access. As checked on 1 October, Google's pages name selected Fairwind cyber defenders and trusted testers; they do not establish broad access for every paid customer.
When can we expect Gemini 4?
Google names paid API customers and Google AI Ultra subscribers for the next wider rollout. Its announcement gives no date for that step or general availability.
What is Gemini not allowed to do?
For Argon through Fairwind, Google's program limits use to permitted defensive and research purposes, bans malicious activity and prohibits sharing, redistributing or selling access. Approved access does not remove those terms.
What is Gemini 4?
Gemini 4 Argon is Google's announced model for complex, sustained work across software engineering, enterprise knowledge tasks and cyber defense. The published output limit is 1M tokens, up from 64K.
When did Gemini 4 launch?
Google announced Gemini 4 Argon and its restricted rollout on 30 September 2026. That is distinct from a broadly available API or consumer release, which Google has not dated.
What is the disadvantage of using Gemini?
For an Argon adoption decision, the immediate disadvantages are restricted access, an undated switch to higher token prices and no evidence yet from your own workload. A long output allowance also creates more work to verify.
How much does Gemini cost per month?
Argon's announced API pricing is usage-based: $2/$10 per million input/output tokens during introduction, then $4/$20, with no dated switch. Google AI Ultra is a separate subscription and a named next access group. The announcement does not specify Argon usage allowances within Ultra.
What are the risks of using Gemini?
For long Argon workflows, review mistaken code changes, unsupported conclusions and unintended tool actions. Google describes defenses against misuse, prompt injection and misalignment, alongside hardened sandboxes. Those measures still leave your organization responsible for checking accepted work.
Is Gemini really worth it?
Evaluate Argon when a specific long job needs its extra headroom and the eventual-price cost per accepted result can improve. Keep your current production choice when it already completes the job reliably, or when Argon access is unconfirmed.
For practical model and workflow decisions as access changes, subscribe to the newsletter.
- Last Updated
- Oct 1, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Wispr Flow Review (Verified October 2026)
Wispr Flow's current prices, work-week evidence, speed claims, coding prompts and privacy limits. A clear rule for Free, Pro or Superwhisper.Oct 1, 2026AI
Claude Tag: What It Is, Pricing, and Safe Slack Setup
Claude Tag puts a shared Claude in Slack. See eligibility, usage billing, ambient replies, spend caps, and a safe first-week setup.Sep 30, 2026AI
How to Use GPT-6.1 Sol for Agents and Codex
Set up GPT-6.1 Sol in the Responses API and Codex, choose reasoning effort, price a real task, and know when Sol or Astra still fits.Sep 30, 2026AI
GPT-6.1 Sol vs GPT-6 Sol
Compare GPT-6.1 Sol with GPT-6 Sol on cache costs, coding evidence, and the reasoning and tool-call changes that affect an upgrade.Sep 30, 2026AI
How to Use Claude Sonnet 5.5
Start using Claude Sonnet 5.5, choose an effort level, and fix the thinking and tool-call settings that can break an existing API workflow.Sep 28, 2026AI
Jev vs GLM-5.3-Flash
Compare Jev with GLM-5.3-Flash through Privatemode Decisions for support routing, image inputs, latency and cost per correct decision.Sep 27, 2026AI
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI