How to Use Claude Sonnet 5.5
Start using Claude Sonnet 5.5, choose an effort level, and fix the thinking and tool-call settings that can break an existing API workflow.



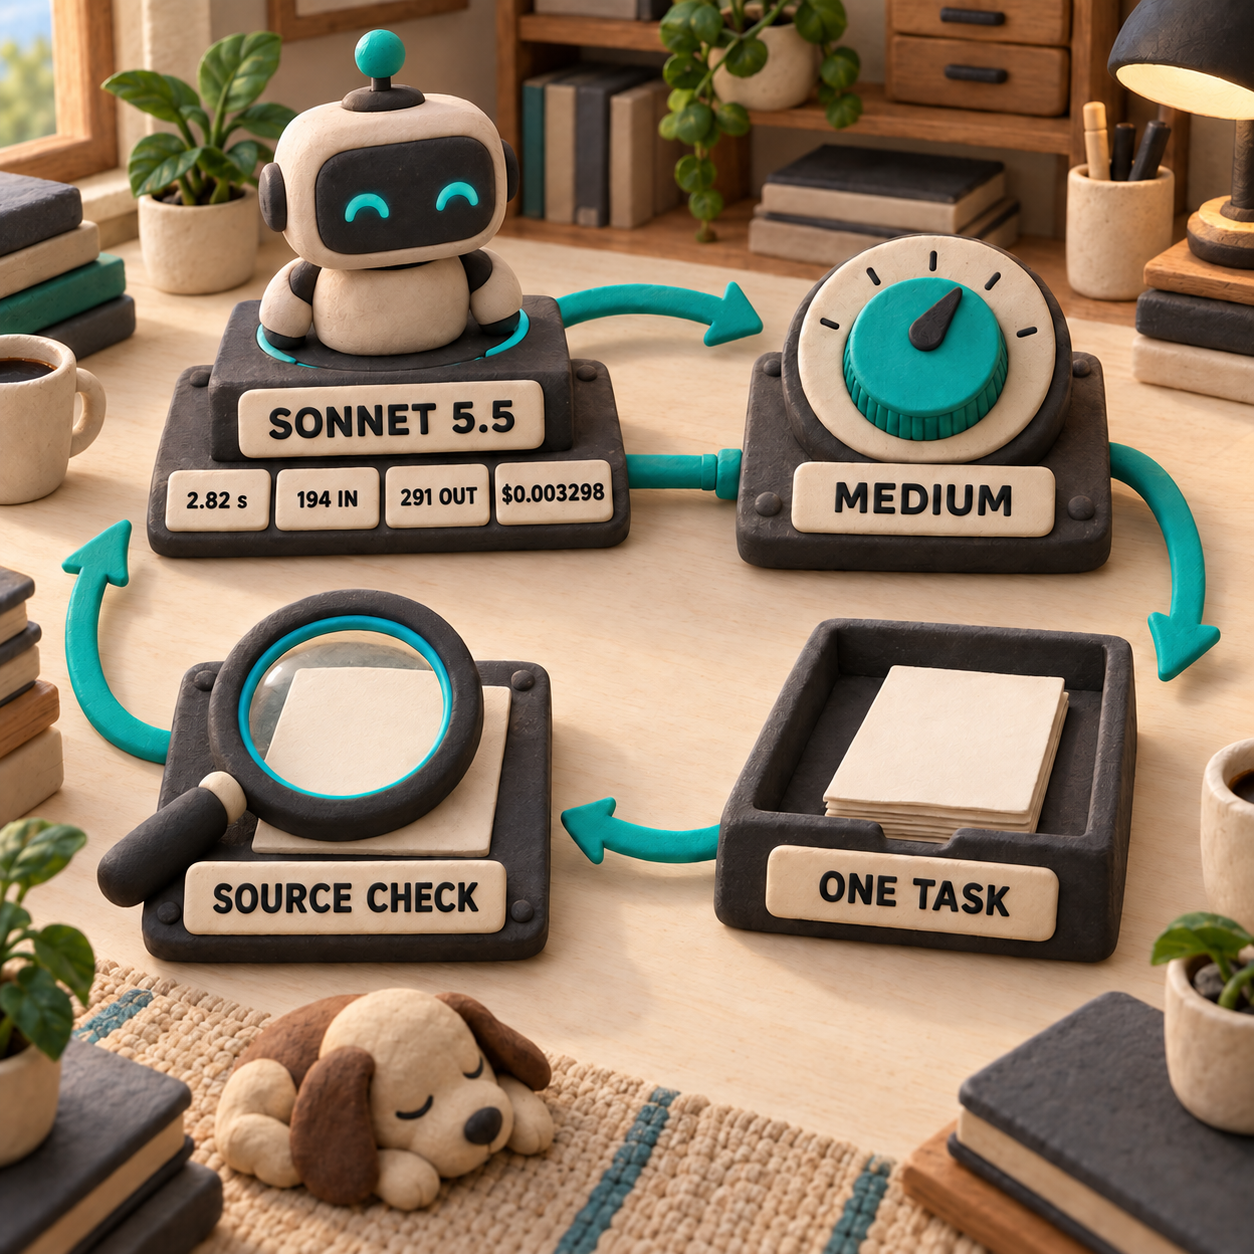
Use Claude Sonnet 5.5 first on one bounded, reviewable job at Medium effort: a support-ticket summary or a client brief. In my local synthetic support run, the model answered in 2.82 seconds, used 194 input and 291 output tokens, and cost $0.003298. It kept the core ticket facts, but it also added plausible remediation assumptions that were not in the source. That is the practical lesson: Sonnet 5.5 can make the draft extremely cheap, while verification remains part of the job.
Start with one task at Medium effort
The quickest useful setup is in the Claude app. Pick Sonnet 5.5, confirm Medium effort, give it one source packet, and ask for an output you can check line by line.
Anthropic sets Medium as the default in its apps and Claude Code. The Claude Platform defaults to High, so API users should set the level explicitly. Medium is the right first test for support summaries, client briefs, routine analysis, and well-specified tool work because it keeps the feedback loop quick without dropping all the way to the lowest setting.
Choose Sonnet 5.5
Open a new Claude chat. Click the model name next to the send button, choose Sonnet 5.5, then open the Effort menu. If the model is not in the first list, click More models. Enterprise administrators can restrict which models and effort levels appear.
Keep the first run at Medium
Leave effort at Medium for a bounded business task. Move to High only when the task needs deeper judgment, a longer chain of work, or stricter verification. Low is useful after your own checks show that quality still holds.
Give it a source and a shape
Paste one ticket, call transcript, or document set. Name the reader and the required fields. For a support ticket, ask for exactly four bullets: Issue, Impact, Evidence, and Next action. Add “Do not invent facts. Mark every inference.”
Check claims against the source
Compare each name, number, cause, commitment, and recommended action with the input. Delete unsupported advice even when it sounds sensible. Save the prompt only after it passes that check on several examples from your own workflow.
The synthetic ticket in my test described six locked-out support agents after a login-domain change, two agents who remained signed in, an “Invalid organization” error, and user records already carrying the new domain. Sonnet 5.5 preserved those details and followed the four-bullet format. It also suggested that the organization mapping probably still pointed at the old domain and called one fix less disruptive. Neither point was in the ticket.
The raw model math is straightforward. At Anthropic's published tariff, 194 input tokens cost $0.000388 and 291 output tokens cost $0.00291, for $0.003298 total. If 10,000 calls had exactly that token shape, raw model spend would be $32.98. That is not the cost of 10,000 resolved tickets. Retrieval, integrations, retries, storage, monitoring, and human review still sit around the model call.
What Claude Sonnet 5.5 actually is
Sonnet 5.5 is the fast, general-purpose model in Anthropic's 5.5 family. Think of it as the operating model for defined work, while Opus 5.5 is the senior specialist you bring in when the problem is open-ended and judgment-heavy.
The release is distinct from Sonnet 5. The direct Claude API ID is claude-sonnet-5-5, with no date suffix. It accepts text and images, returns text, carries a 1 million-token context window, and can produce up to 128,000 output tokens. If you want the previous model's pricing and tokenizer context, the Claude Sonnet 5 review covers that release separately.
Anthropic says Sonnet 5.5 generates output more than 30% faster than Sonnet 5 and costs up to 30% less per completed task in its testing. The second claim is about fewer tokens used to finish work, not a cheaper token tariff. The rates are unchanged from Sonnet 5.
The benchmark claims also belong to Anthropic. It reports 70.6% for Sonnet 5.5 versus 10.3% for Sonnet 5 on Terminal-Bench 4.0, and 55.5% versus 34.1% on CursorBench 4.0. Those figures support testing the new model, but they do not tell you whether your ticket policy, codebase, or document template will pass. Anthropic's launch report makes the same distinction between benchmark scores and sustained judgment on open-ended work.
Choose effort by the cost of being wrong
Effort is a quality, latency, and token control, not a writing-length setting. Higher effort gives the model more room to reason and check; it can also increase the wait and the bill. Prompt separately for a short answer if brevity matters.
Anthropic recalibrated these levels for Sonnet 5.5, so Medium on this model does not represent the same thinking volume as Medium on Sonnet 5. Run a fresh sweep on your own examples. Do not carry a setting forward only because the label matches.
Seven useful workflows, ranked by near-term payoff
The best uses share three properties: the input is available, the desired output has a clear shape, and a person or rule can verify the result.
1. Support-ticket triage
A support operations lead can combine the customer's message, account state, recent ticket history, and escalation policy. Sonnet 5.5 can return the issue, impact, evidence, missing facts, and next permitted action. The payoff is less rereading before routing or handoff. The human still checks account-changing advice, refunds, promises, and root-cause claims.
This is the strongest first workflow because every output can point back to a specific source field. It also exposes model errors quickly. If a summary cannot show where a claim came from, it is not ready to trigger an action.
2. Pre-call client briefs
An account director can supply the latest call transcript, statement of work, open tasks, and renewal notes. Ask for one page covering decisions, commitments, risks, unresolved questions, and the next meeting's agenda. The payoff is a repeatable briefing format instead of a fresh blank page before every call.
Keep “confirmed” and “inferred” in separate sections. That one distinction prevents a model's plausible interpretation from becoming a client commitment.
3. Pull-request review
An engineering lead can give the model a code diff, repository conventions, and a checklist for security, tests, and backward compatibility. Sonnet 5.5 can produce a risk-ranked first pass and propose tests. The payoff is quicker reviewer orientation, not automatic approval. A person who owns the system should still decide whether the change merges.
4. Bounded bug fixes
A product engineer with a reproducible bug can provide the failing behavior, relevant files, and acceptance checks. Medium effort is a sensible start for a well-specified fix. Move to High when the problem crosses several services or the first run skips verification. The payoff is shorter implementation and test loops while the acceptance checks keep the task from spreading.
5. Operating reviews and board drafts
A finance or operations team can provide source materials plus an approved slide or document template. Sonnet 5.5 can draft a structured review, surface gaps, and format a first pass. Anthropic specifically positions it for polished documents, slides, and spreadsheets. The payoff is less assembly work, but every financial claim still needs a source cell or document reference.
6. Incident summaries
An incident commander can feed the model the event timeline, alerts, actions, and owner notes. Ask for confirmed events, hypotheses, customer impact, unresolved questions, and follow-ups in separate blocks. The payoff is a cleaner handoff and post-incident draft. Do not let the model promote a correlation into a root cause.
7. Visual QA and interface polish
A product designer or front-end engineer can pair a screenshot with brand rules and an acceptance checklist. Sonnet 5.5 can identify inconsistencies, prioritize fixes, and help implement a bounded pass. The payoff is faster iteration on visible defects. Taste, accessibility testing, and final product judgment remain human responsibilities.
Three products worth building
Raw model access is not a business. A sellable product adds proprietary context, a controlled workflow, evidence, and a place for a person to make the final decision.
1. Evidence-linked support triage, the strongest opportunity
Build a support copilot that turns a ticket and account record into a structured summary, attaches a source link to every claim, checks the proposed action against policy, and queues the draft for approval. Support leaders and outsourced service teams would pay for faster, more consistent routing.
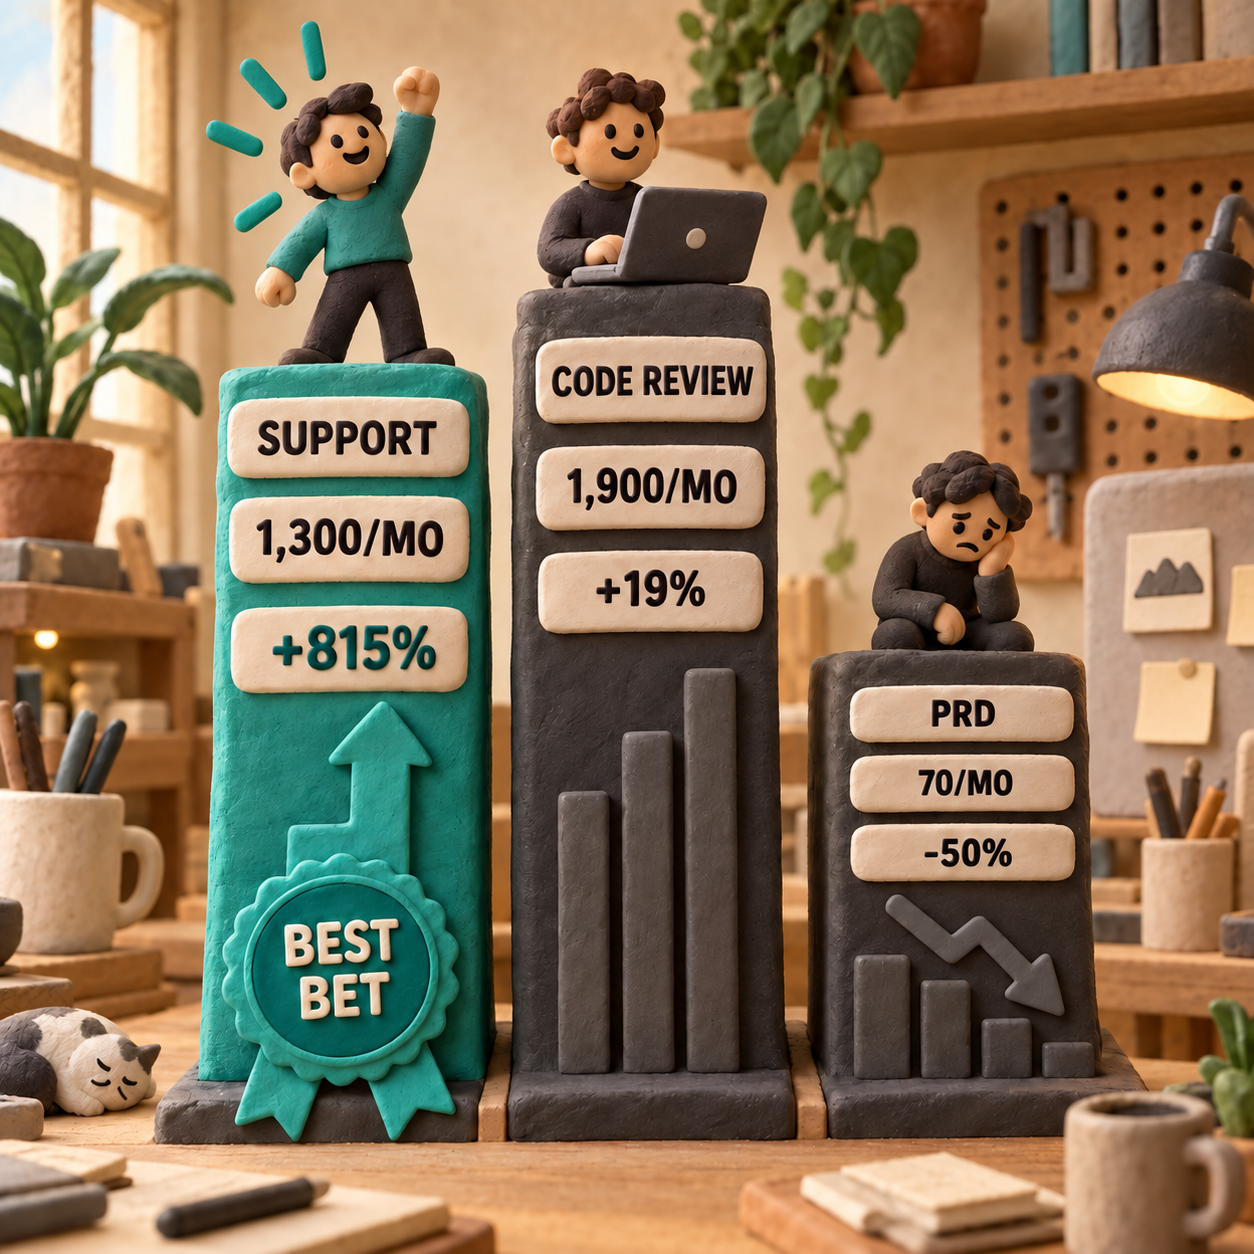
The demand is visible: ai customer service agent shows 1,300 US searches a month, commercial intent, and 815% yearly growth in this run's keyword data. Intercom prices Fin at $0.99 per outcome. That is not directly comparable to a summary call, because a resolved outcome is a larger job, but it proves buyers already accept usage-based support automation.
The smallest sellable version needs one inbox connector, one account-data connector, the four-field summary, source citations, a policy check, and approve or reject controls. The catch is integration and trust. If you cannot prove where a recommendation came from, customers will keep the existing workflow.
2. A policy-aware code-review layer
Build a GitHub app that reads a diff plus each team's own rules, then returns a risk-ranked review, test gaps, and a short merge brief. Engineering managers and platform teams are the buyer.
ai powered code review platform shows 1,900 US searches a month and 19% yearly growth. CodeRabbit's public pricing starts at $24 per developer per month when billed annually, with higher plans at $48 and $72. The MVP is one repository provider, pull-request webhooks, custom checks, a comment view, and an audit trail showing which rule triggered each finding.
The catch is a crowded market. A generic reviewer has no defensible edge. Pick a painful niche such as regulated release checks, data-migration safety, or a specific framework, then measure false positives as carefully as missed defects.
3. A vertical brief-to-PRD tool, but not a generic one
Build a narrow workflow that turns calls, constraints, and prior decisions into a product brief with acceptance criteria and unresolved questions. A product consultancy or a vertical software team could buy it when the template matches their work.
The exact query ai product requirements document generator has only 70 US searches a month and is down 50% year over year. That is a warning, not a pitch. A generic standalone PRD generator is the weakest opportunity here. The viable version is an add-on inside a higher-value workflow, such as agency discovery, healthcare implementation, or enterprise change control.
The MVP is a fixed source packet, one opinionated template, decision traceability, and export to the buyer's existing system. The catch is thin demand and easy copying. Do not build this unless you already own the customer relationship or a vertical data channel.
The price stayed flat, the workflow cost may fall
Sonnet 5.5 costs $2 per million input tokens, $10 per million output tokens, and $0.20 per million cache-read tokens. Those are the same published rates as Sonnet 5. Anthropic's lower-cost claim comes from completing tasks with fewer tokens.
That distinction matters in a forecast. A shorter model trace can reduce both latency and token spend even when the rate card does not move. It can also leave total product cost almost unchanged if retrieval, third-party tools, retries, and human review dominate. Measure cost per accepted output, not cost per call.
Claude app subscriptions and API usage are separate products. Paying for Pro, Max, Team, or Enterprise does not include Claude Console or API usage. The Claude plan guide covers general plan boundaries; an API workflow needs its own Console access and metered billing.
Migrate the API workflow after the task passes
The safest migration order is simple: prove the prompt on representative examples, pin the new model ID, set effort explicitly, then fix the thinking and tool-call contract before sending production traffic.
For a plain request with adaptive thinking, omit the thinking field and read text blocks by type:
from anthropic import Anthropic

client = Anthropic()
response = client.messages.create(
    model="claude-sonnet-5-5",
    max_tokens=4096,
    output_config={"effort": "medium"},
    messages=[{
        "role": "user",
        "content": "Summarize this ticket as Issue, Impact, Evidence, and Next action.",
    }],
)

for block in response.content:
    if block.type == "text":
        print(block.text)
Four migration changes deserve a deliberate check.
thinking: {"type": "disabled"}is no longer accepted by Anthropic's direct Claude API. Usethinking: {"type": "between_tools"}when you want no up-front thinking. It works at Low, Medium, and High, but not Xhigh or Max.- Forced
tool_choicevaluesanyand namedtoolare no longer accepted by the direct API. Useauto, make the schema strict where supported, and say in the prompt when the tool should run. - A response can begin with a
thinkingblock. Parse every content block bytype; never assumecontent[0].textexists. - Pass thinking blocks back unchanged in a tool loop. They carry signatures tied to the earlier conversation, so keep the message history append-only.
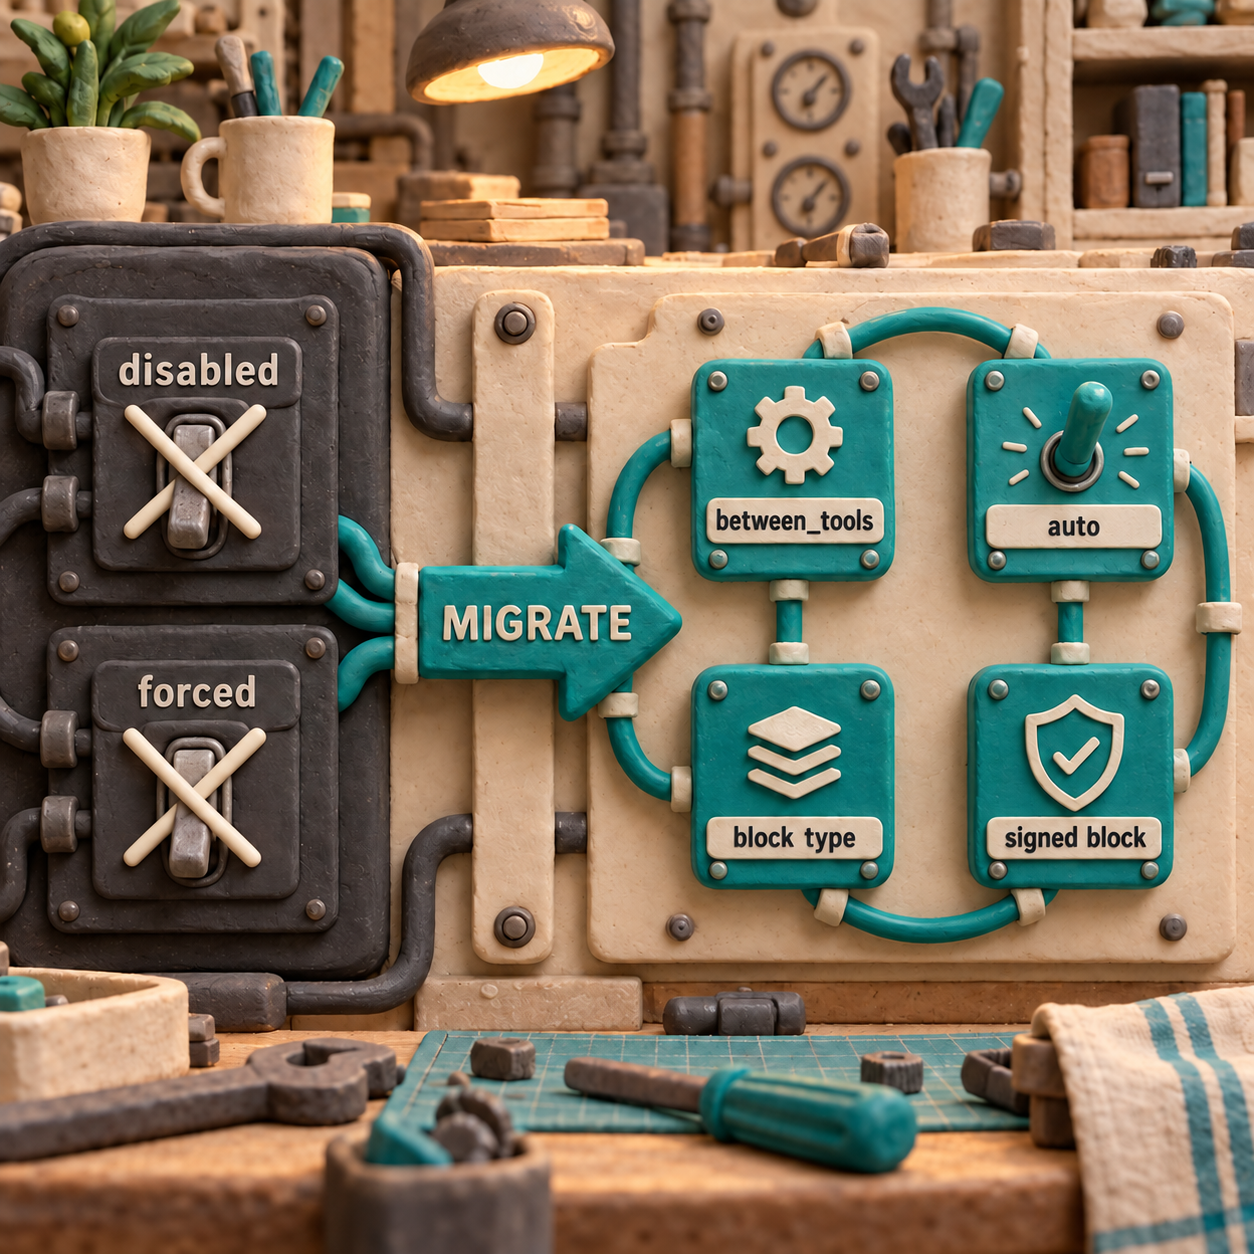
This minimal pattern uses between_tools, keeps tool choice on auto, and preserves the complete assistant turn:
tools = [{
    "name": "lookup_ticket",
    "description": "Look up a support ticket",
    "strict": True,
    "input_schema": {
        "type": "object",
        "properties": {"ticket_id": {"type": "string"}},
        "required": ["ticket_id"],
        "additionalProperties": False,
    },
}]

messages = [{"role": "user", "content": "Use lookup_ticket for T-42."}]
response = client.messages.create(
    model="claude-sonnet-5-5",
    max_tokens=4096,
    thinking={"type": "between_tools"},
    output_config={"effort": "medium"},
    tools=tools,
    tool_choice={"type": "auto"},
    messages=messages,
)

# Keep every block, including signed thinking blocks, exactly as returned.
messages.append({
    "role": "assistant",
    "content": [block.model_dump() for block in response.content],
})

tool_call = next(block for block in response.content if block.type == "tool_use")
messages.append({
    "role": "user",
    "content": [{
        "type": "tool_result",
        "tool_use_id": tool_call.id,
        "content": "Ticket T-42 is open and assigned to Support Ops.",
    }],
})

follow_up = client.messages.create(
    model="claude-sonnet-5-5",
    max_tokens=4096,
    thinking={"type": "between_tools"},
    output_config={"effort": "medium"},
    tools=tools,
    tool_choice={"type": "auto"},
    messages=messages,
)
Anthropic's Sonnet 5.5 migration guide documents the direct-API 400 errors and the replacement fields. My local Medium between_tools request returned HTTP 200 in 1.35 seconds. A separate adaptive tool loop produced a signed thinking block, and replaying the complete block unchanged succeeded on the next turn.
There is one important wrinkle. My calls ran through an AI gateway. That compatibility layer returned HTTP 200 when I deliberately sent the old disabled thinking value and forced tool_choice: any, even though Anthropic documents both as direct-API errors. Do not treat middleware acceptance as proof that your direct integration is compatible. Inspect the raw request in Anthropic's Playground or test the direct endpoint before the switch.
What Sonnet 5.5 does not solve
It does not turn an unsupported inference into a fact. The local support test made that plain. Require source references for high-impact claims and keep approvals around refunds, account changes, legal commitments, medical decisions, and security actions.
It does not make every task a Medium task. Raise effort when your own examples show missed reasoning or incomplete work. Use Opus for open-ended work that needs sustained judgment; the Opus 5.5 comparison explains where that higher tier fits.
It does not make the raw model call a product. Connectors, permissions, policy checks, evals, observability, fallback behavior, and a useful review interface are where most production work lives.
It also does not remove the need for current sources. If a support or research answer depends on what is allowed, required, or charged now, give the model a search or knowledge tool and tell it to check.
The Monday move
Pick one queue with a clear source of truth. On Monday, take 20 recent examples, remove private data you do not need, and run Sonnet 5.5 at Medium with one fixed output schema. Score factual accuracy, unsupported inferences, completeness, elapsed time, and token usage. Only after that prompt passes should you change an existing API model ID and run the migration checks above.
How do I use Claude Sonnet?
In the Claude app, click the model name next to the send button, choose Sonnet 5.5, select Medium effort, and begin with one bounded task whose output you can verify. In Claude Code, run /model and choose Sonnet 5.5, or start a session with claude --model claude-sonnet-5-5.
What is Claude Sonnet 5 best used for?
For the current Sonnet 5.5 release, start with well-scoped everyday work: support summaries, client briefs, bug fixes, code review, and polished business documents. Use a higher effort level or Opus when the work is open-ended and the cost of a subtle error is high.
Is Claude Sonnet free?
Availability and limits depend on the Claude plan and organizational settings. App access and API billing are separate, so a paid Claude subscription does not include API usage. See the linked Claude plan guide for the current plan boundaries.
How much does Claude Sonnet 5 cost?
Claude Sonnet 5.5 is priced at $2 per million input tokens, $10 per million output tokens, and $0.20 per million cache-read tokens. Anthropic says it can cost less per completed task than Sonnet 5 because it uses fewer tokens, not because those rates are lower.
If you want a source-grounded Claude workflow built for your business, see AI production systems.
- Last Updated
- Sep 28, 2026
- Category
- AI
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Jev vs GLM-5.3-Flash
Compare Jev with GLM-5.3-Flash through Privatemode Decisions for support routing, image inputs, latency and cost per correct decision.Sep 27, 2026AI
Claude Opus 5.5 vs Opus 5
Compare Claude Opus 5.5 and Opus 5 on token costs, cache savings, coding work, and the API changes to check before switching.Sep 23, 2026AI
GPT-6 Sol vs Luna
Compare GPT-6 Sol and Luna on task fit, the 20x token-price gap, shared limits, and the checks that show when Sol earns its higher cost.Sep 23, 2026AI
Is GPT-6 Luna Free
GPT-6 Luna is free to try in the desktop app. See which plans and surfaces support it, what limits remain, and when API charges apply.Sep 22, 2026AI
How to Use MiMo V2.6
Set up Xiaomi MiMo V2.6 in Studio and the API, choose the right key and model, and complete a first business task with clear checks.Sep 22, 2026AI
MiMo V2.6 Pro vs Flash
Compare MiMo V2.6 Pro and Flash for coding and agent work: task success, token costs, cache savings and when Pro earns its higher price.Sep 22, 2026AI
Is MiMo V2.6 Free
MiMo V2.6 Flash has a temporary free endpoint. Compare that offer with MIT model downloads, paid API access and desktop plans.Sep 22, 2026AI