How to Block AI Training Without Blocking Search
Use Cloudflare’s new training controls while keeping search access. Check migrated settings and separate crawler preferences from request blocking.



Keep search crawlers working while declining AI model training: set Search to Allow, set Training to Disallow AI Training, then verify both the migrated settings and the robots.txt file Cloudflare serves. This matters now because Cloudflare changed the meaning of Block on September 15, 2026. Block can now stop mixed-use crawlers such as Googlebot, Applebot, and Bingbot from reaching your site for search too.
The safe configuration in one table
The right choice for most search-dependent sites is simple: allow Search, disallow Training, and decide separately what Agents may do.
Cloudflare's September 15 explanation is explicit: use Disallow AI Training when you want to stop training and keep search. Do not follow an older guide that tells you to choose Training: Block. Before the change, mixed-use crawlers were excluded from that block. They are not excluded now.
The control is available on every Cloudflare plan, so there is no separate feature upgrade to buy. The cost shifts from buying another blocking product to checking that policy and behavior agree. For context, a Screaming Frog SEO Spider seat is $279 per year in the US, while one dedicated robots.txt monitoring product advertises a $129 monthly tier. Cloudflare supplies the control. You still need a verification loop.
What Disallow AI Training actually does
Disallow is a preference with selective enforcement, while Block is a locked door.
Think of a mixed-use crawler as one delivery van carrying two job sheets. One says "index this page for search." The other says "use this page for model training." Blocking the van stops both jobs. Disallow AI Training lets an accountable operator keep the search job while rejecting the training job.
Cloudflare divides automated traffic into three behaviors:
- Search builds a search index.
- Training trains or fine-tunes a model.
- Agent visits on behalf of a person, such as a chat fetcher or browser-use agent.
The new Training option tells Bot Preference Sync to publish the relevant no-training instructions in robots.txt. Accountable mixed-use crawlers remain eligible for search access. Training-only crawlers from Amazon, Anthropic, Meta, and OpenAI are blocked without taking their separate search crawlers with them.
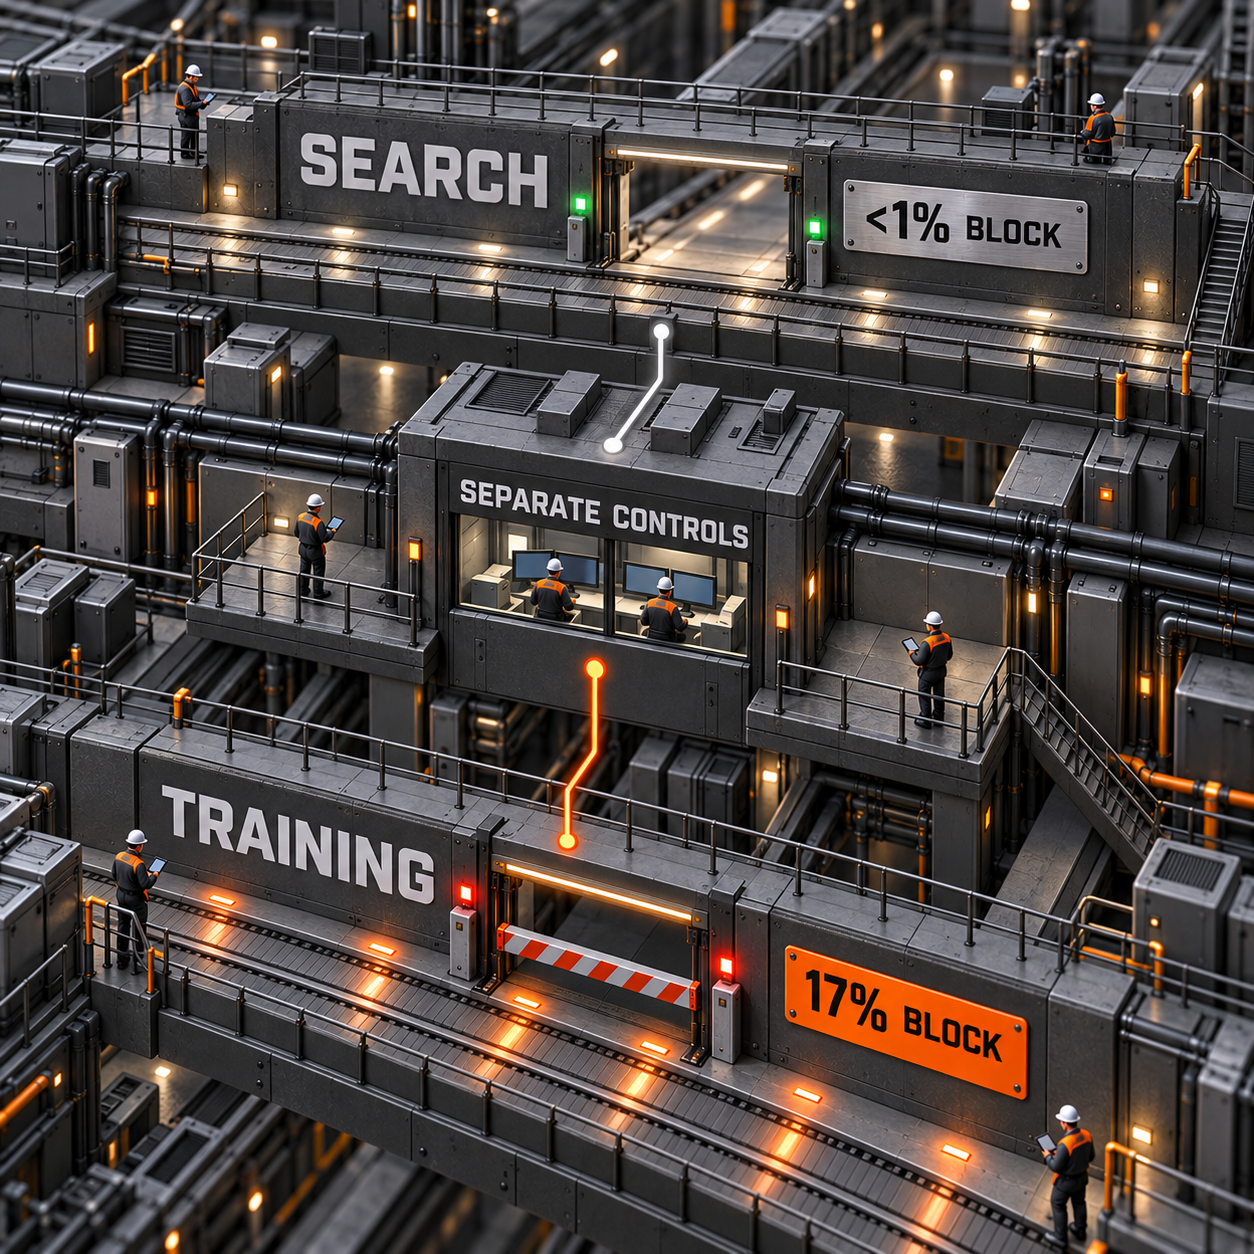
Cloudflare reports that fewer than 1% of its sites block Search bots, while 17% enable some mechanism to block Training. That gap explains the product design. A single Block AI switch was too blunt for what site owners actually want.
There is one important distinction. A robots.txt instruction is not a force field. By itself, it cannot identify who is crawling, determine why they are crawling, or stop a crawler that ignores it. Cloudflare combines the published preference with network classification and blocking for crawlers that do not qualify for the accountable path.
Accountable does not always mean available today
Treat Cloudflare's Accountable label as a roadmap-backed status, not proof that every promised control already exists.
To qualify, an operator must meet or commit to requirements covering a training opt-out, an AI-summary opt-out, URL-level visibility, and assurance that declining training will not hurt traditional search. That wording matters.
- Google: Google-Extended can be disallowed in robots.txt, and Google says that choice does not affect search ranking. Google also offers a webmaster control for generative search and reporting. Extra URL-level Google-Extended transparency was still described as coming in the weeks after the announcement.
- Apple: Applebot-Extended supports a robots.txt training opt-out. Apple also supports
nosnippetfor AI summaries and paywall labeling. URL-level inspection was not available on announcement day and was described as work for the following year. - Microsoft: Bing's current path is different. Site owners can use
NOARCHIVEplus Bing's Block URLs or Content Removal tools. Microsoft targets early 2027 for Bingbot to respect a domain-level no-training preference in robots.txt. Until then, Cloudflare's Disallow AI Training setting does not automatically send that preference to Bing through robots.txt.
So the honest promise is narrower than "one switch controls every use everywhere." The new setting makes the safe search-versus-training decision much clearer, but Bing still needs a separate check today.
Check what Cloudflare migrated
Most settings carry over automatically, but the labels and effects changed enough that you should audit the result.
If a domain never used the granular Search, Training, and Agent controls, Cloudflare maps the legacy Block AI Bots setting like this:
If a domain already used granular controls, Search and Agent retain their practical state. Training: Allow stays Allow. Training: Block and Training: Block on pages with ads both become Disallow AI Training.
Here is the migration check to run:
- Open the domain in Cloudflare and go to Security Settings, then Configure AI bot policies.
- Record the current Search, Training, and Agent values before changing anything.
- Set Search to Allow if organic discovery matters.
- Set Training to Disallow AI Training if you want the training opt-out without removing accountable mixed-use crawlers from search.
- Choose the Agent policy on its own merits. Cloudflare does not offer a Disallow preference for Agents because there is no established Internet directive for it yet.
- Confirm Bot Preference Sync is enabled if you want Cloudflare to publish the category-level policy in robots.txt.
- Save the policy, then inspect the public result instead of treating the dashboard label as proof.
For new ad-supported domains, Cloudflare's recommended preset already follows this pattern: Preference Sync on, Search allowed, Training disallowed, and Agents blocked on pages with ads. New domains that do not monetize with ads start with all three behaviors allowed.
Verify search access after the change
A correct-looking switch is only the first checkpoint. Verify the policy from the outside in.
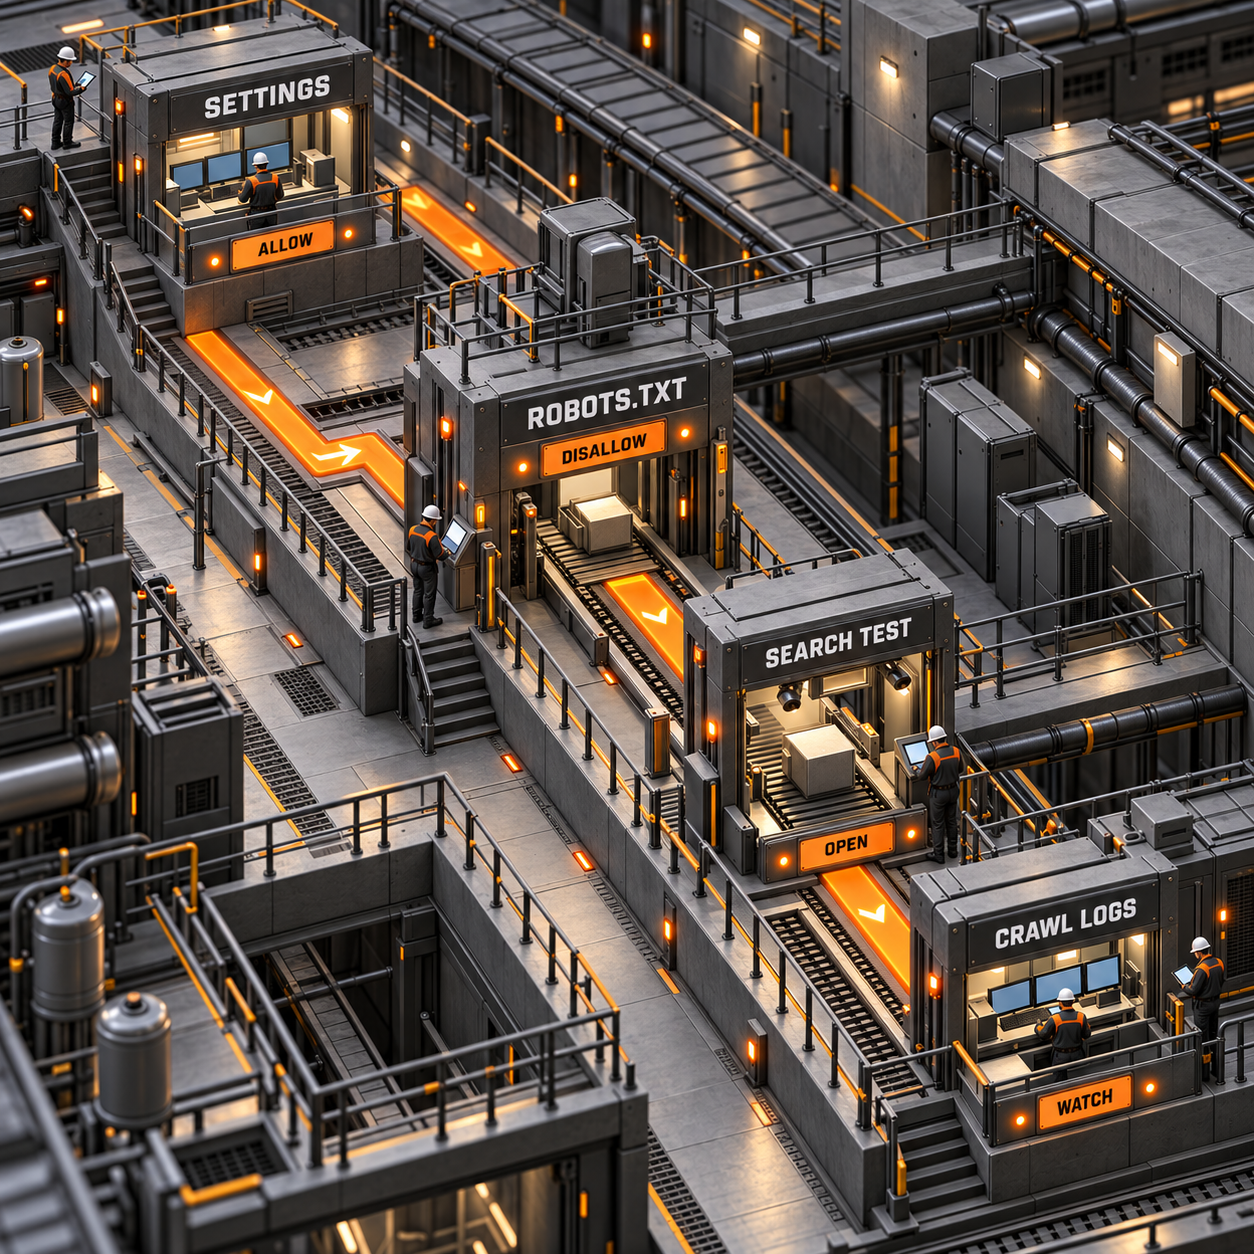
Use this four-part check:
- Settings: Confirm Search says Allow and Training says Disallow AI Training. Review Agent separately.
- robots.txt: Fetch the live
/robots.txtfile from the public domain. Bot Preference Sync prepends its generated rules to an existing file, so your original Disallow directives remain. Check for conflicts in both sections. - Search behavior: Use the search operator's webmaster tools and reporting to inspect representative URLs. Do not infer search access from the word "Disallow" alone. It applies to the training identity or preference, not the traditional search purpose of an accountable mixed-use crawler.
- Crawler activity: Watch AI Crawl Control for requests, robots.txt compliance, and unexpected blocks. Cloudflare can apply individual crawler actions and records activity, which makes it the practical place to catch a policy that behaves differently from your intent.
Custom rules deserve extra attention. Bot Preference Sync reflects category-wide policy, but it does not read complex individual rules into the generated file. If you have a licensing exception for one crawler, path-specific logic, or a custom WAF rule, compare those layers manually. Cloudflare lets you turn Sync off and maintain the file yourself when a category-wide policy is too coarse.
Who profits most from the new split
The biggest winner is any business that earns money when a human lands on the page but does not want its archive absorbed into training data.
The retailer example also exposes a limit: these controls are domain-level. They are not a built-in per-article consent system. Separate zones can carry separate policies, but one zone gets one Search, Training, and Agent posture unless you add more specific rules yourself.
What is worth building
The strongest product is a crawler-policy regression monitor, not another robots.txt generator.
1. Crawler-policy regression monitor
Build a monitor for agencies and multi-site teams that reads the Cloudflare policy, fetches the served robots.txt, checks representative search access, and alerts when those layers drift.
The demand is visible around the job: robots.txt generator gets about 1,000 US searches a month, and google indexing checker gets about 110. Existing tools prove there is a budget too. One robots.txt monitoring product lists $129 per month for a five-domain tier, while a desktop SEO change monitor lists $179 once.
The smallest sellable version needs four things: Cloudflare zone import, a policy-versus-robots comparison, scheduled checks, and an email or Slack alert with the exact change. Add crawler activity and webmaster data after the core drift detector is trusted.
The catch is proof. Configuration and observed requests can show what the site published and blocked. They cannot prove that a model vendor deleted data already collected. The moat has to be reliable evidence across many domains, not a prettier switch.
2. Cloudflare migration auditor
Build a focused audit that finds zones still using risky post-migration combinations and produces a remediation report for an agency, publisher group, or franchise network.
cloudflare block ai bots gets about 50 US searches a month with a $13.19 CPC, while google indexing checker adds another 110 monthly searches around the feared outcome. That is smaller demand than the generator market, but the paid-click price suggests the people who do search have a live operational problem.
The MVP can read the API fields for Search, Training, Agent, and Bot Preference Sync, fetch the public robots.txt, and classify each zone as search-safe, intentionally blocked, or inconsistent. Export a client-ready evidence pack with the setting and observed file side by side.
The catch is platform risk. Cloudflare can add the same portfolio report, and the need spikes around migrations. The better business is to use the audit as the entry product, then sell ongoing regression monitoring across Cloudflare and other edge providers.
What this control does not solve
This is a cleaner policy boundary, not a complete answer to AI content use.
- It does not erase material already collected. Cloudflare describes crawler preferences and request controls, not retroactive deletion.
- It does not guarantee that every operator honors robots.txt. Cloudflare adds network enforcement for crawlers outside the accountable path, but the mixed-use path still depends on the operator honoring the preference.
- It does not opt you out of every AI summary. Summary controls are separate, and Cloudflare describes broader centralized summary control as future work.
- It does not give Agents a Disallow state.
- It does not translate complex per-crawler custom rules into Bot Preference Sync.
- It does not automatically express the Bing no-training preference through robots.txt yet. Check Bing's current
NOARCHIVEand webmaster controls separately. - It is not Cloudflare AI Search indexing for R2 files. That is a separate product and workflow.
Choose Block when you truly want the crawler gone. Choose Disallow AI Training when search discovery is still part of the business model. That distinction is the whole point of the September change.
Your Monday move
Pick three representative domains next week: one ad-funded property, one search-led site, and one domain with custom crawler rules. Record the migrated Search, Training, and Agent values, switch only the sites whose business goal is clear, then save the live robots.txt and crawler report beside the change ticket. If those three pass, roll the same evidence-based check across the portfolio.
How to disable AI training?
On a Cloudflare-managed domain, set Training to Disallow AI Training when you want to publish a no-training preference while keeping accountable mixed-use crawlers available for search. Use Block only when you also accept the search impact for mixed-use crawlers.
Is there any way to block all AI content?
You can block crawler categories or individual crawlers, but "all AI content" mixes several different jobs. Cloudflare separates Search, Training, and Agent traffic so you can choose which automated uses to allow. Blocking Training does not remove AI-generated material from search products or erase data already collected.
How do I disable AI mode in search?
Cloudflare's crawler setting does not turn off an AI search experience for users. It controls access to your domain. Google and other operators expose separate controls for generative summaries, while traditional indexing and training preferences remain distinct decisions.
If you want this kind of crawler-policy audit and monitoring layer built for your business, see AI production systems.
- Last Updated
- Sep 16, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.
Murmure Dictation Review
Review Murmure for offline dictation, custom vocabulary, hardware needs, and what changes when you connect a local or remote LLM.Sep 14, 2026Build
RenderIO FFmpeg API Pricing
Decode RenderIO command charges, chained jobs, download credits, runtime limits, and when an upgrade costs less than overage.Sep 14, 2026Build
Dictare AI Dictation Pricing
Dictare is free, local voice input for coding agents. Separate its software cost from speech-model setup, hardware, and your coding-agent plan.Sep 13, 2026Build
How to Test Claude Code Plugins With Evals
Run Claude Code plugin evals, compare results with a no-plugin baseline, and budget the repeated agent and judge calls before adding CI.Sep 12, 2026Build
Debug Cloudflare Voice Agent Latency
Trace slow and silent Cloudflare voice turns with stage timings and outcomes, then separate transcription, model, speech, and interruption problems.Sep 12, 2026Build
Burn SRT Subtitles Into a Video With Rendi
Turn a video and SRT file into a captioned MP4 with Rendi, covering API submission, completion checks, subtitle styling, and output review.Sep 11, 2026Build
OpenAI Agents API vs Agents SDK
Compare the managed OpenAI Agents API with Agents SDK on session ownership, runtime control, sandbox costs, and migration work.Sep 11, 2026Build