Best Web Scraping Tools in 2026: Firecrawl, Bright Data, Browse AI, and Context.dev (Compared)
Choose web scraping tools by the job: agent-ready pages, no-code monitoring, or collection at scale. Eight tools with verified prices and billing units.




Firecrawl is the first shortlist for clean pages an AI agent can read, Browse AI for monitoring an operator can own, and Bright Data for collection where site access is the constraint. The best web scraping tools solve different jobs: Firecrawl and Context.dev both start at $19/month on monthly billing, but structured JSON changes the credit bill. Choose the output, the schedule, and the person who will repair a failed run before choosing the vendor.
Best web scraping tools at a glance
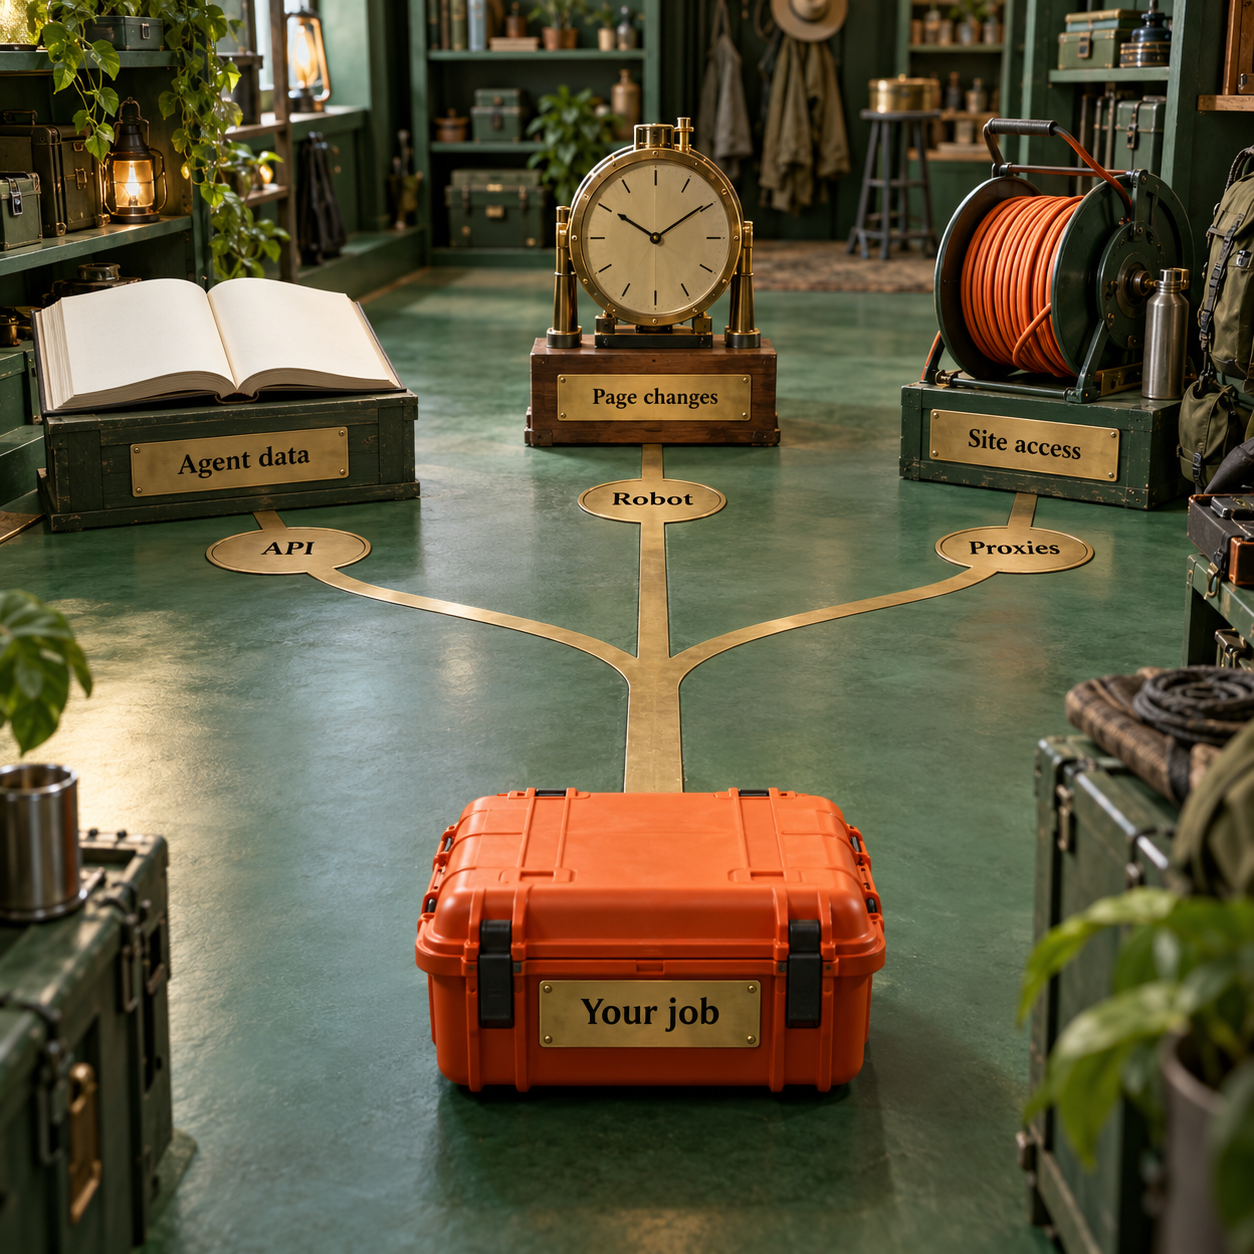
Buy the missing part of your workflow. A scraping API, a service your software calls to retrieve page data, fits a developer building an agent or dataset. A no-code robot fits an operator who needs a repeatable collection task. A proxy network, which routes traffic through other IP addresses, fits a scraper you already own that needs better access to target sites.
Pricing and allowances below were verified against the makers' live pages on 6 October 2026. Annual rates are labeled; free trials are distinguished from allowances that renew. The entry column gives the paid starting offer, while the final column shows what you can evaluate without a paid plan.
The table is a shortlist, not a claim that a delivered record equals a visited page or a gigabyte. Bright Data's proxy coupon, RESIGB50, advertises 50% off for three months. That temporary rate belongs in a trial budget; the regular rate belongs in the recurring forecast.
Start with the output, then the owner
There are three different buying decisions here, and the tool changes when the job changes. A founder loading documentation into an assistant, an operator watching competitor prices, and a developer refreshing a large listings dataset should not start with the same product comparison.
Job one: turn pages into material an agent can use
Start with Firecrawl or Context.dev when your desired output is page content or structured fields inside your application. Markdown is readable text with headings and links preserved; it is useful when an AI agent needs the document. JSON is a set of named fields, such as product, price, currency, and availability; it is useful when a workflow needs a record it can validate and compare.
That difference affects both quality and cost. A support assistant can often work from a clean documentation page. A pricing alert needs the price field, its currency, the correct product variant, and a timestamp. Sending a model a page does not decide which of several prices is the one your business cares about.
Also separate scrape, which retrieves a page, crawl, which follows a site's links to retrieve multiple pages, and map, which discovers URLs. If you already maintain a trusted URL list, repeated discovery may add work without improving the feed. If the site's documentation keeps growing, discovery is part of the job.
Job two: watch known pages without making an operator maintain code
Choose Browse AI for a recorded extraction task and change monitoring that an operator can own. Choose Octoparse when visual task design and a paid cloud extraction setup are a better fit. A robot here is a saved sequence of actions and extraction instructions, not a general employee replacement.
For example, an operations lead may need the title, price, and availability from a supplier's product list every morning. The useful deliverable is a spreadsheet with stable columns and a clear exception when a field disappears. The operator should be able to inspect the task and adjust it when the site changes.
Decide what counts as a change before choosing the frequency. A changed footer is irrelevant to stock availability. A list that reorders its rows should not look like every product was replaced. Keep a stable identifier, compare the relevant fields, and route missing data for review instead of silently overwriting yesterday's valid value.
Job three: collect at scale when access is the problem
Shortlist Bright Data, Zyte, or ScrapingBee when your software already owns the schedule and the dataset, but fetching target pages is becoming the difficult part. An unblocker manages access behavior such as retries and proxy selection. It does not automatically define your dataset's meaning.
Bright Data also offers site-specific Scraper APIs, so it can sell a more complete record rather than just network access. Apify occupies another useful position: a maintained, target-specific Actor may already implement the extraction task you need. An Actor is a reusable cloud program you configure and run.
The choice flips on ownership. If you need someone else's maintained extraction logic, evaluate a Scraper API or Actor. If you need to keep your own parsing logic, evaluate a fetching API or proxy service. Paying for raw access while expecting a finished dataset is an expensive mismatch.
The eight tools and the walls they hit
Each tool below earns its place through a specific recurring job. The numbering makes the shortlist easy to navigate; the best choice within a job depends on the output, limits, and ownership described in its section.
1. Firecrawl: the first shortlist for agent-ready pages
Firecrawl is a scraping API for turning websites into usable page content, and it is the first option to evaluate for a documentation-backed agent. Its Scrape, Crawl, and Map functions cover page retrieval, site traversal, and URL discovery without making those three tasks look interchangeable. A founder building a support assistant can map the documentation, select the relevant paths, and crawl those pages into Markdown. Choose it when clean page content is the deliverable; reconsider when the primary need is an operator-managed spreadsheet monitor.
Best for: A developer feeding documentation, articles, or reference pages into an AI agent.
Standout: Separate scrape, crawl, and map functions, with Markdown and structured extraction.
Pricing: Hobby $19/month, or $16/month billed annually; 5,000 monthly credits.
Free trial: A recurring Free plan with 1,000 credits/month and no card required.
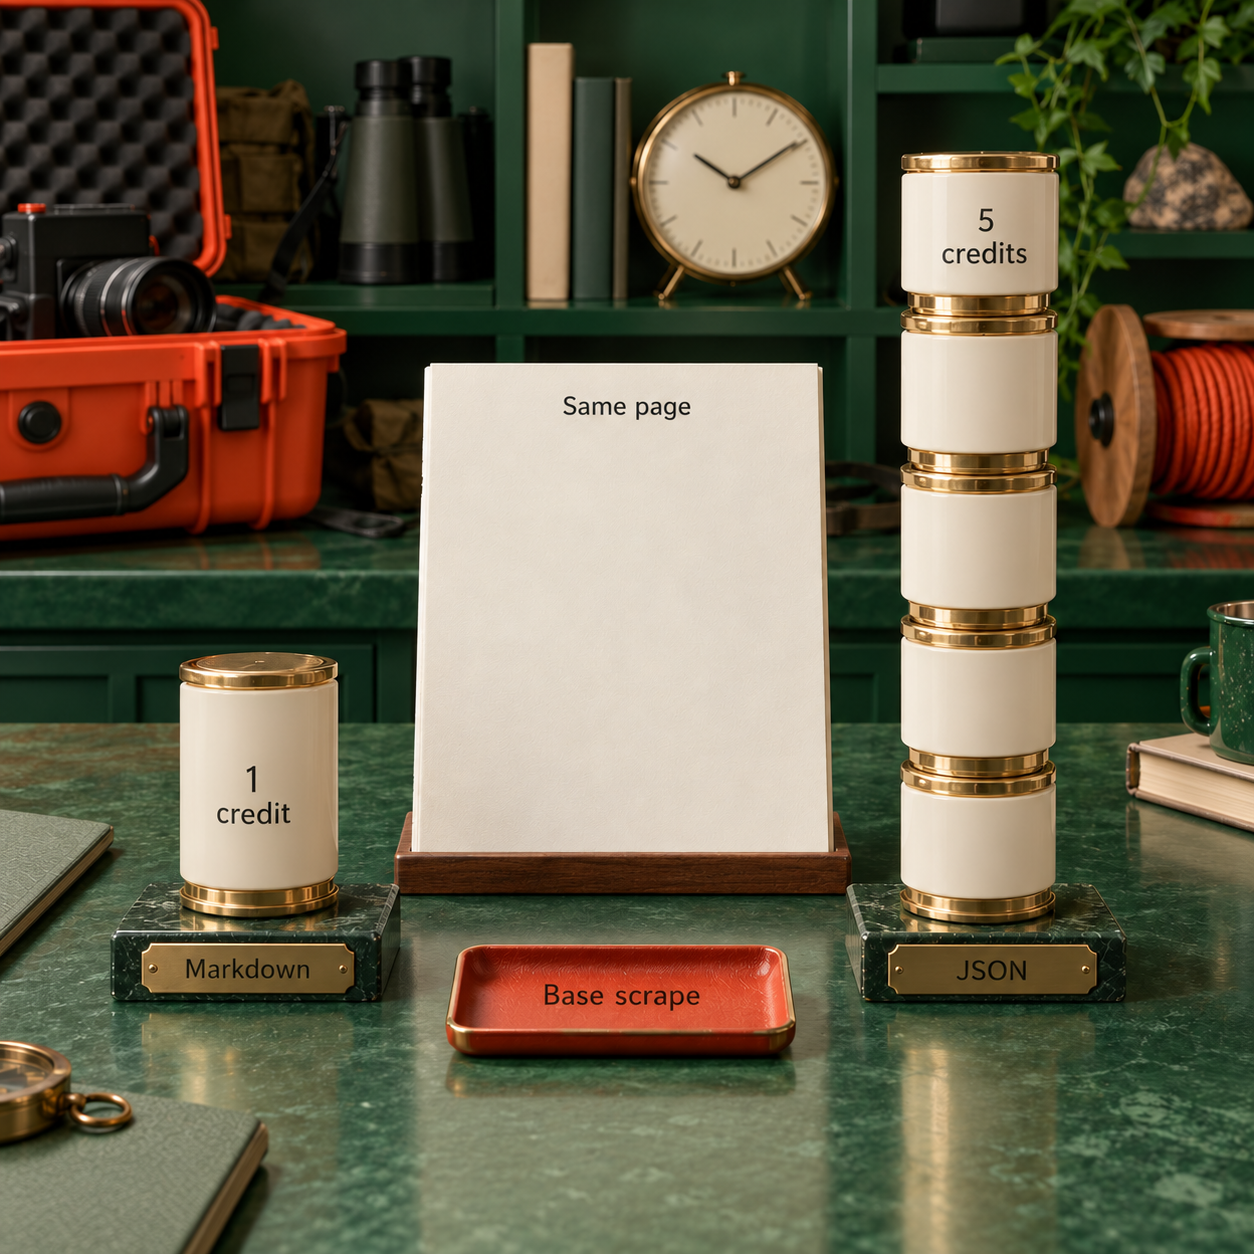
A basic scraped or crawled page costs 1 credit. JSON extraction adds 4 credits, so the standard page-plus-JSON request costs 5 credits. Hobby therefore supports 5,000 basic pages or 1,000 standard JSON pages if the balance is spent on that operation alone. The same subscription looks very different depending on what you ask it to return. Firecrawl's pricing details.
The full plan ladder on monthly billing is Free at $0, Hobby at $19 for 5,000 credits, Standard at $99 for 100,000, Growth at $399 for 500,000, and Scale at $749 for 1,000,000. Enterprise is Custom. The displayed annual equivalents are $16, $83, $333, and $599/month, with annual invoices of $190, $990, $3,990, and $7,190 respectively. These are the maker's displayed figures, including its rounding. All Firecrawl plans.
The first wall is the requested crawl size. Firecrawl's crawl documentation says the default limit is 10,000 pages, and it can reject a job when the remaining credits cannot cover the requested limit. A small site on Hobby can therefore need an explicit lower limit, even before the crawl reaches its first page. The next wall is concurrency: Hobby allows 5 concurrent requests, Standard 25, Growth 50, and Scale 100. More credits do not erase the current plan's parallel-request limit. Crawl behavior.
The acceptance check matters too. Firecrawl says a scrape returning no result is not charged, but a returned target error page, such as a 403 or 404, costs a credit. Read the target status and the returned content before inserting it into the knowledge base. An error page converted neatly into Markdown is still an error page.
- Scrape, crawl, and map make discovery and retrieval separate decisions.
- Markdown suits document ingestion; JSON suits a defined field schema.
- A recurring free allowance can evaluate a small scheduled workload.
- Paid top-ups let you increase usage before changing the plan.
- Structured extraction reduces the base page allowance substantially.
- A large default crawl limit can exceed a small account's balance.
- Returned error pages can be billable and need your own validation.
- Hobby, Standard, and Growth credits do not ordinarily roll over.
Map the source before collecting everything
Use the Map playground to discover the documentation URLs. Keep the paths that answer your assistant's actual questions. Mapping discovers addresses; scraping them is a separate operation.
Choose the least expensive useful output
Start with Markdown for a document-backed assistant. Use a JSON schema when the downstream workflow needs named fields. Verify a representative product page that shows both a regular price and a discounted price before assuming the schema is clear.
Set a crawl limit you can fund
For the illustrative 120-page source set, set an explicit
limitof 120. Apply path filtering rather than allowing a crawler to spend the balance on unrelated blog or account pages.Store the result and its acceptance evidence
Persist the source URL, collection time, target status, and content in your own storage. Firecrawl's documentation says completed crawl results remain available through the API for 24 hours, so the retrieval response should not be your only copy.
Make the next run deliberate
Have your application's scheduler revisit the accepted source set. Keep discovery, extraction, and monitoring charges separate in the budget, and decide who receives an exception when a source stops returning the expected content.
If your existing Firecrawl setup needs a replacement, the Firecrawl alternatives comparison goes deeper into migration and acceptance criteria. Switching providers is a different decision from changing the job from document ingestion to no-code monitoring.
2. Browse AI: the best fit for an operator-owned monitor
Browse AI is a no-code scraper and monitoring platform that records a task into a reusable robot. It fits an operator tracking product prices, job listings, or directory entries on a known set of sites. The operator can record the fields to extract and send the results into a spreadsheet or connected workflow. Its decisive limit is the combination of pages, extracted rows, and monitored domains, so “unlimited robots” should not be read as unlimited data.
Best for: An operator who needs recurring extraction and change monitoring without owning scraper code.
Standout: Recorded robots, scheduled monitoring, and spreadsheet/workflow integrations.
Pricing: Personal $19/mo billed annually, $228 upfront, with 12,000 annual credits.
Free trial: Free plan with 50 credits/month, 2 domains, and unlimited robots.
Browse AI charges one credit per standard page visit or per ten extracted rows, whichever is more. A list page with 50 products costs 5 credits; visiting all 50 detail pages adds 50 more under standard-page assumptions. That turns “one product list” into a 55-credit collection when the details are part of the requirement. Premium sites can cost more, so inspect the task's displayed charge. Browse AI pricing and credit examples.
The live annual plan ladder is Free at $0, Personal at $19/mo with 12,000 credits/year, Professional at $69/mo with 60,000 credits/year, and Premium starting at $500/month billed annually. Personal includes 5 domains and 3 users; Professional includes 10 domains and 10 users. Annual credits are delivered upfront. Premium adds a managed service for setup, maintenance, and data transformations.
The page's monthly-billing option lists Personal at $48/month for 2,000 monthly credits and Professional at $87/month for 5,000. The $19 annual Personal offer is therefore not just the same allowance with a different payment date. Compare the actual quota as well as the billing term. Annual Professional totals $828 upfront; annual Personal totals $228.
The domain boundary can arrive before the credit boundary. A workflow checking a few fields across many supplier sites may need additional domains even when it uses little data. Annual extra domains are listed at $4/mo on Personal and $2.40/mo on Professional. Credit top-ups are available on annual plans, with a 1,000-credit minimum; Personal lists $0.024/credit and Professional $0.017-$0.013/credit.
For a supplier-price workflow, keep a product identifier and the price's currency beside the value. A robot extracting a number cannot decide whether a sale price, member price, or alternative pack size should replace your purchasing record. Your comparison rule and review queue supply that meaning.
- Recorded tasks let an operator inspect the extraction instructions.
- Monitoring, API access, and webhooks are listed across plans.
- Google Sheets, Airtable, Zapier, and Make integrations support common operating workflows.
- Domain add-ons and annual credit top-ups can extend a plan.
- Row-heavy lists and detail-page visits compound the charge.
- Domain limits can force an add-on before credits run out.
- The cheapest advertised annual offer has a different quota from monthly Personal.
- Site changes and ambiguous fields still require an owner to inspect the result.
Choose Browse AI when the person responsible for the dataset should also be able to adjust the robot. Choose an API instead when the extraction is a feature inside your product and engineering already owns its schedule, schema, and failure handling.
3. Bright Data: choose the product before comparing the price
Bright Data is a web-data provider spanning proxy networks, pre-built Scraper APIs, and Web Unlocker. It belongs on the shortlist when access to target sites or collection volume is the constraint. An ecommerce developer might buy a site-specific scraper returning product records, while an existing custom scraper might need residential proxy access instead. Those purchases solve different layers of the job and use different billing units.
Best for: Collection where target access, geography, or a maintained site-specific scraper matters.
Standout: Separate proxy, unblocking, and structured-record products.
Pricing: Web Scraper API PAYG $1.5/1K record; residential PAYG $8/GB before the temporary coupon.
Free trial: Scraper API has 5K records/month free; residential proxy trial is separate.
Use Scraper API when the record is the deliverable. Its site-specific APIs return structured data, with proxies, unblocking, parsing, runtime, storage, and egress listed as included. The pricing ladder is Free Tier with 5K records/month, PAYG at $1.5/1K record, Scale at $499/month with 384,000 records and $1.3/1K additional records, then Enterprise Custom. Check the target scraper's input and output schema before assuming that every required field is included. Web Scraper API pricing.
Use Web Unlocker when your code needs access handling. The page lists automated proxy management, retries, IP rotation, and CAPTCHA solving. Free Tier includes 5K requests/month; PAYG is $1.5/1K requests; the displayed Scale offer is $499/month for 383K requests, with $1.3/1K additional. Enterprise is Custom. Bright Data specifically says Web Unlocker is not an interactive browser for navigating or clicking through a workflow. Web Unlocker pricing and limitations.
Use residential proxies when you want to keep the scraper itself. The detailed PAYG card shows $8/GB, reduced to $4/GB by the three-month RESIGB50 promotion. The displayed promotional monthly packages are $499 with 141 GB, $999 with 332 GB, and $1,999 with 798 GB. Above 1 TB, the page directs buyers to a custom quote. The bandwidth measure includes traffic sent to and received from the target, not just the final records retained in your database. Residential proxy pricing.
That last distinction decides the budget. A request downloading images or other page resources can use bandwidth without producing additional useful records. A record API includes those access costs in its advertised record price; raw proxies leave you responsible for the requests, parsing, and quality checks. A GB price cannot tell you the cost per accepted listing until you measure the actual workflow.
The main wall is buying the wrong layer. Better IP access will not repair a parser that selects the wrong field. A maintained record scraper will not necessarily preserve the exact custom extraction behavior you already rely on. Define the data contract before comparing two prices that happen to share the same vendor name.
- Site-specific Scraper APIs can reduce custom extraction work.
- Record, request, and bandwidth products let engineering buy the layer it needs.
- Scraper API pricing includes access and parsing costs described on its page.
- Recurring free API allowances can evaluate supported targets.
- The product range requires a precise buying decision.
- Residential traffic remains a GB bill, not a valid-record guarantee.
- The promoted proxy rate is temporary.
- Web Unlocker does not replace an interactive browser workflow.
Bright Data is the call when access infrastructure or an appropriate maintained scraper is the missing piece. For a small operator-owned monitor, Browse AI is a more direct starting point; for documentation ingestion, start with the page-output APIs.
4. Context.dev: agent data with monitoring in the same API
Context.dev is a web-context API whose own site lists scraping, URL mapping, crawling, batches, sourced answers, and monitors. It fits a developer who wants agent-ready pages and scheduled updates delivered into an application. A documentation-backed assistant can ingest the initial sources, then receive monitor updates through a webhook, an HTTP message sent to its application when an event occurs. It earns a place beside Firecrawl for this job; brand enrichment is an additional product surface, not the reason to select it for scraping.
Best for: An agent or product combining page extraction with webhook-based source monitoring.
Standout: Scrape, Map, Crawl, Batches, and Monitors in one API.
Pricing: Developer $19/month with 7,500 monthly credits.
Free trial: Free Tier with 1,000 credits/month, no card, and 10 monitors.
The site lists Markdown, HTML, screenshots, and structured fields, with rendering and proxies included in the base scrape. Its monitors watch pages on a schedule and send updates to a webhook. That is a developer integration: your application still receives the update, validates it, and decides what to change downstream. It is not the same ownership model as giving an operator a recorded spreadsheet robot. Context.dev's product description.
The monthly plan ladder is Free Tier at $0 for 1,000 credits, Developer at $19 for 7,500, Pro at $99 for 125,000, Growth at $299 for 500,000, and Scale at $499 for 1,000,000. Enterprise is Custom and lists 2,000,000+ credits/month. Core concurrent-request limits rise from 1 on Free to 10 on Developer, 100 on Pro, 250 on Growth, and 500 on Scale. Context.dev pricing.
A standard scrape uses 1 credit. Successful JSON extraction adds 4, for 5 credits per standard page; browser actions raise the base scrape to 2 before extraction. The base inclusion of rendering and proxies therefore does not make every kind of request cost one credit. Developer's 7,500-credit balance buys 1,500 standard JSON pages when used solely for that operation.
Paid top-up rates for new subscriptions are $2.20 per 1,000 credits on Developer, $1.80 on Pro, $1.40 on Growth, and $1.00 on Scale, billed in 1,000-credit blocks. Existing subscriptions retain their rates. A buyer can therefore compare a small plan plus top-ups against a larger plan instead of upgrading solely because the included balance ran out.
The named crawl wall is 500 pages in one Crawl call. Larger sites use Batches in crawl mode. Split an ingestion design accordingly, and ensure the results reach your storage before treating the batch as complete. A collection endpoint and a durable knowledge base are separate parts of the architecture.
The other wall is partially successful output. Context.dev says most failed requests are not billed, but not-found responses are billed, and a response can contain failed outputs alongside a successful one. Check the returned outputs and key_metadata.credits_consumed rather than equating an outer success response with a complete record.
- Page content and scheduled webhook monitoring fit the same agent-data workflow.
- Rendering and proxies are included in the base scrape price.
- The recurring free plan includes a small monitor allowance.
- Published top-up blocks allow a concrete small-workload budget.
- JSON extraction and browser actions increase credit use.
- A single Crawl call is bounded; larger sources require Batches.
- Webhook delivery still needs application logic and storage.
- Partial outputs and billable not-found pages need acceptance checks.
Pick Context.dev when that combination of API features and its credit budget fits your agent. Choose between it and Firecrawl with the same representative sources and output schema, rather than turning the larger entry allowance into an unsupported quality claim.
5. Apify: strongest when the right Actor already exists
Apify is a cloud platform for reusable scraping and automation programs called Actors. It is a strong choice when your target already has a suitable maintained Actor, because the extraction logic may be more valuable than a generic fetching endpoint. An operator refreshing a business-directory dataset can configure the Actor's input, save the task, and schedule repeated runs. The wall is the selected Actor's behavior and billing, not just the platform subscription.
Best for: A specific target or extraction job already served by an appropriate Actor.
Standout: Reusable cloud programs with task scheduling and integrations.
Pricing: Starter $19/month + pay as you go, including $19 of usage.
Free trial: Free plan with $5/month of usage and no card required.
Apify's Free plan is $0 with $5 to spend on Store or platform usage. Starter is $19/month + pay as you go with $19 included; Scale is $199 with $199 included; Business is $999 with $999 included. Enterprise has custom pricing. Compute costs are $0.2 per compute unit on Free and Starter, $0.16 on Scale, and $0.13 on Business. A compute unit is one GB of RAM used for one hour. Apify pricing.
Do not treat the included dollar balance as a fixed page allowance. A selected Actor can have its own price, while platform resources, proxies, storage, and transfer affect the bill according to the workload. The right comparison is the complete run that returns your accepted records, not the marketplace program's attractive starting label.
For an explicitly hypothetical compute-only run, one GB of RAM for ten hours uses ten compute units. On Starter, that is $2 of compute usage. It says nothing about the number of listings returned or additional charges. Even the statement that $19 buys 95 compute units assumes every dollar goes to compute, which a practical scraping task may not satisfy.
Apify's schedule tooling can run saved tasks with a selected timezone and deliver webhook notifications. Its documentation says new schedules are disabled by default, so saving a schedule is not proof that the next run will happen. Check its enabled state and displayed next run. Apify schedule documentation.
For the directory example, inspect pagination, location coverage, output identifiers, and the Actor's maintenance history before committing. An Actor collecting a category list is not necessarily an Actor enriching every listed business with all the fields your CRM expects. Keep a sample of accepted and rejected records, and make missing fields visible.
- A suitable Actor can supply target-specific extraction logic.
- Saved tasks and schedules support recurring collection.
- The marketplace also includes page-content crawling workflows.
- Included usage gives a small job room to evaluate the complete run.
- There is no universal Apify price per page or record.
- Actor-specific charges can matter more than the platform plan.
- Task input and output still need validation against your dataset.
- A new schedule must be enabled before relying on it.
Choose Apify when the Actor removes meaningful extraction work and its complete run cost is acceptable. Use a direct scraping API when the job is mostly “retrieve these known pages” and the marketplace adds complexity without saving you work.
6. ScrapingBee: managed fetching with explicit request multipliers
ScrapingBee is a scraping API that handles rendering and proxy options for a developer-owned extraction workflow. It fits an engineer who wants to keep the parsing and scheduling code while handing off difficult fetching behavior. For example, a product-data service can request a rendered page and apply its existing field rules to the returned content. The limit to budget first is the credit cost of the settings that actually work on the target.
Best for: A developer keeping custom extraction logic and replacing the fetching layer.
Standout: Rendering/proxy controls and Auto-Mode with a maximum credit cost.
Pricing: Freelance $49/mo with 250,000 API credits.
Free trial: 1,000 API credits, no card; no recurring free plan advertised.
The complete published ladder is Freelance at $49/mo for 250,000 credits, Startup at $99 for 1,000,000, Business at $249 for 3,000,000, and Business + at $599 for 8,000,000. Enterprise 14 is $999 for 14,000,000; Enterprise 24 is $1,599 for 24,000,000; Enterprise 41 is $2,399 for 41,000,000; Enterprise 69 is $3,599 for 69,000,000. Higher capacity is a discussion with the vendor. Prices exclude VAT. ScrapingBee pricing.
Those are credits, not requests. The documented fetching costs are 1 credit for a classic proxy without JavaScript, 5 with JavaScript, 10 for a premium proxy without JavaScript, 25 for a premium proxy with JavaScript, and 75 for a stealth proxy with JavaScript. AI extraction adds another 5 credits. JavaScript rendering is the default behavior. ScrapingBee request costs.
Freelance's 250,000-credit allowance therefore represents at most 50,000 classic JavaScript requests, 10,000 premium JavaScript requests, or 3,333 complete stealth JavaScript requests if all credits fund that one configuration. These are allowance calculations, not measured success rates. Extra features and a mixed target set change them.
Auto-Mode can try configurations and charge for the one that succeeds, with zero charge if every configuration fails. Its max_cost setting caps the configurations it may try. But the documentation says it does not automatically choose page-specific wait or click instructions. If the desired price appears only after a selection or an asynchronous load, you still need to define the relevant behavior. Auto-Mode documentation.
That is the wall: fetching configuration is not extraction intent. A correct HTML response may contain an empty placeholder, a default region's price, or a selection your customer would not make. Keep the response evidence and verify the business field rather than stopping at a successful API call.
- Fits a custom scraper whose parsing and scheduling should stay in your code.
- Rendering and proxy settings have published credit costs.
- Auto-Mode can cap how expensive an access configuration becomes.
- Concurrency and capacity increase through an explicit plan ladder.
- The same advertised credit allowance buys very different request counts.
- AI extraction is an additional credit charge.
- Auto-Mode does not supply target-specific wait or click settings.
- The free offer is a trial, not a perpetual scheduled-work allowance.
Choose ScrapingBee when you value control over the request and already know how to validate the response. Prefer a record API or suitable Apify Actor when maintaining the target's extraction rules is the work you want to stop doing.
7. Octoparse: visual tasks, with cloud scheduling behind a paid plan
Octoparse is a visual scraping application that fits an operator willing to design and maintain extraction tasks. It makes sense for recurring catalog or listings collection when the operator needs a task builder rather than an API integration. A purchasing analyst can define the list and detail fields, then move the accepted workflow into paid cloud execution. Its Free plan is useful for local evaluation, but it is the wrong assumption for an unattended feed.
Best for: An operator building visual extraction tasks and buying cloud execution when needed.
Standout: Task-based scraping with paid cloud scheduling and automatic export.
Pricing: Standard from $69/MO billed annually.
Free trial: Free Plan with 10 local tasks and 50,000 exported rows/month.
Free includes 10 tasks, local-device execution, up to 10,000 rows per export, and 50,000 rows of monthly export. Standard adds cloud extraction, task scheduling, automatic export, and the Data Export API, with 100 tasks and up to 3 concurrent cloud processes. Professional allows 250 tasks and up to 20 concurrent cloud processes, plus its Advanced API and additional support. Enterprise lists 750+ tasks and 40+ concurrent cloud processes. Octoparse plan details.
The published plan ladder is Free at $0, Standard from $69/MO, Professional at $249/MO, and Enterprise with custom pricing. Both paid figures are billed annually. Treat those monthly equivalents as annual offers, and confirm the invoice amount at checkout before forecasting cash outlay. Octoparse pricing.
The billing unit is a subscription with task and process limits, not a standard per-request credit. That can suit a workflow with substantial extraction inside a manageable set of tasks, but “unlimited data export” on paid plans does not mean unlimited parallel cloud work. Three simultaneous cloud processes on Standard can be the relevant constraint long before you reach 100 saved tasks.
Add-ons remain separate. The pricing page lists residential proxies at $3/GB, CAPTCHA solving at $1-1.5 per thousand, and pay-per-result templates at $0.001-3 per thousand results. A paid subscription does not turn every advanced access cost into a free inclusion.
For a supplier-catalog workflow, start locally with a small task and validate list/detail coverage. Then confirm how the cloud run handles the same input, where the export lands, and who sees a failure. An analyst who can build the task still needs an operating routine for checking that it collected the expected records.
- Visual task design suits an operator who wants to own extraction instructions.
- Free local tasks can evaluate a workflow before a cloud purchase.
- Standard explicitly includes scheduling and automatic export.
- Task and cloud-process limits make the execution boundary visible.
- Free execution is local, so it does not supply the intended unattended cloud job.
- Paid export volume does not remove task or concurrency limits.
- Proxy, CAPTCHA, and template add-ons can add usage charges.
- The entry rate requires annual billing.
Choose Octoparse when visual task design is a meaningful advantage and its cloud process limits fit the schedule. Browse AI is the more direct first shortlist for a recorded monitor; an API is a better fit when the extraction belongs inside a software product.
8. Zyte: access pricing that follows the target site
Zyte is a web-data provider whose Zyte API prices successful responses by site difficulty and whether you request HTTP content or browser rendering. It fits a developer operating a collector who wants automatic access handling without buying a raw proxy fleet. A listings service can keep its own dataset and parsing while budgeting the actual response mode needed for each target. Its price floor is useful only when you also name the commitment and site tier attached to it.
Best for: A developer-owned collector with a target-specific access budget.
Standout: Successful-response pricing with separate HTTP and browser rates.
Pricing: PAYG HTTP $0.13-$1.27 per 1,000; browser $1.01-$16.08 per 1,000.
Free trial: $5 credit for 30 days, no commitment; no recurring free tier advertised.
The PAYG HTTP prices across Simple, Easy, Moderate, Complex, and Advanced targets are $0.13, $0.23, $0.44, $0.70, and $1.27 per 1,000 responses. PAYG browser prices are $1.01, $2.01, $4.02, $8.04, and $16.08. The same request volume can therefore have a very different bill depending on the target and whether rendered content is necessary. Zyte pricing.
Monthly commitments lower those rates. A $100 commitment lists HTTP at $0.10-$0.95 and browser at $0.75-$12.00 per 1,000. At $200, the ranges are $0.08-$0.76 and $0.60-$9.60. At $500, they are $0.06-$0.61 and $0.48-$7.68. Enterprise pricing goes through sales. The page's “from $0.06” headline belongs to the commitment ladder; it is not the PAYG HTTP entry price.
For an illustrative 100,000 successful responses, the Simple PAYG HTTP rate produces a $13 usage bill. The Simple browser rate produces $101; the Advanced browser rate produces $1,608. These are calculations using published rates, not a claim that your site will fall into a particular tier. Advanced features can add charges, so use the vendor's site-specific estimator with the intended output mode.
The named wall is target-specific economics. A low-complexity HTTP target and an advanced rendered target should not share one assumed cost per page. Segment the URL list by target and mode, preserve the accepted response count, and compare commitment plans against that mix.
Successful access also leaves the extraction contract with you. Your parser still needs the right listing identifier, fields, and completeness checks. If a maintained record API or Actor already returns the dataset you need, the lower access price alone may not justify keeping custom extraction work.
- Separate HTTP and browser pricing supports a precise target budget.
- Five difficulty tiers expose variation that a flat entry price can hide.
- Monthly commitments offer a visible rate ladder.
- The API lists rendering, IP rotation, and geolocation capabilities.
- The cheapest headline rate requires a monthly commitment.
- Browser rendering can change the economics substantially.
- Advanced features may cost extra.
- Your response still needs parsing and business-level validation.
Choose Zyte when your engineering workflow needs managed access and can measure the target mix. Start with the PAYG estimate rather than taking a subscription merely to obtain the smallest number printed on the page.
What scheduled web data will cost
Count the repeated work and the output format before comparing entry prices. Use this explicit planning example: a founder revisits 120 known pages daily over a 30-day month, producing 3,600 page visits. Assume ordinary pages, no extra browser actions, no discovery calls, no monitor-endpoint charges, and no chargeable retries. This is a budget worksheet, not a measured workload or a promise about target access.
For basic Markdown scrapes, those 3,600 visits use 3,600 credits on both Firecrawl and Context.dev. Firecrawl Hobby includes 5,000 credits for $19/month, and Context.dev Developer includes 7,500 for $19/month. Both entry monthly subscriptions cover that specified scrape volume. Firecrawl, Context.dev.
Request successful structured JSON on the same standard pages and the requirement becomes 18,000 credits on each. Firecrawl Hobby needs 13 additional 1,000-credit blocks at $5: $19 + $65 = $84/month. Context.dev Developer, using the published new-subscription rate, needs 11 additional 1,000-credit blocks at $2.20: $19 + $24.20 = $43.20/month. The block rounding leaves some unused credits in the Context.dev calculation.
A no-code monitor needs the same frequency arithmetic. On Browse AI, 3,600 standard page checks/month becomes 43,200/year before larger row counts or premium targets. Professional's 60,000 annual credits fit that illustrative volume; Personal's 12,000 do not. The monthly Professional allowance is 5,000 credits for $87, while annual Professional is $69/mo with $828 paid upfront. Browse AI.
Raw proxies require a different worksheet. Start with measured GB, then add your scraper's hosting, extraction work, and exception handling. A record API starts with billable delivered records. Apify starts with the selected Actor and resource usage. Do not convert any of those into a per-page promise without measuring the actual job.
Who should pick what
The explicit decision rule is whether you need page content, an operator-owned monitor, a finished target-specific record, or access for code you already maintain. The paid upgrade should solve the boundary you are hitting, not simply reward a vendor for having a larger feature list.
The best tools for web scraping depend on who repairs the next run
If engineering owns the data feature, shortlist an API that returns the required content and metadata. If operations owns a spreadsheet-based process, shortlist a visual robot the operator can inspect. If nobody owns failures yet, assign that role before increasing collection frequency.
The tool choice flips when ownership changes. A developer can make a scraping API the right component for a product. That same API can be the wrong purchase for an operator who needs a daily result and has no application in which to receive it. Conversely, a recorded task may be quick to evaluate but add friction when extraction becomes a core product feature.
Web scraping AI needs a schema and an acceptance rule
Treat extraction as a data contract. For a price record, define the product identifier, variant, numeric amount, currency, source URL, and collection time. Decide how missing or ambiguous values are handled before the first automated update. A clean JSON object is a format; a correct business record is a judgment against that contract.
For document ingestion, retain the source and retrieval time, and exclude irrelevant repeated navigation where appropriate. Keep the original response when an automated check rejects a page. The evidence is what lets the owner distinguish a changed site from a mistaken field definition.
The best AI web scraper for an agent depends on the output
Start with Firecrawl for the page-oriented scrape/crawl/map workflow. Add Context.dev to the shortlist when its batch and webhook-monitoring combination fits the application. If a suitable Apify Actor already collects the target's required fields, evaluate that complete run alongside the generic page APIs.
Choose with a fixed source set and identical expected output. Include an ordinary page, a rendered page, a list/detail relationship, and a page with an ambiguous field. An entry allowance is a cost input, not evidence that one service produces better data.
Best web scraping tools Python developers can schedule
A Python workflow can call an API and keep scheduling, parsing, persistence, and validation in its own application. Choose Firecrawl or Context.dev when you want page content or managed structured extraction. Choose ScrapingBee or Zyte when your parsing should stay under your control and fetching is the component you want to replace.
The extra control creates operating work. Keep a clear distinction between a transport error, a target error page, a missing field, and a rejected business record. Do not retry every category blindly: a wrong extraction rule will not improve because the same request ran again.
The best free web scraper depends on a recurring allowance
Firecrawl and Context.dev each advertise 1,000 monthly credits. Browse AI gives 50 monthly credits across 2 domains. Apify supplies $5/month of usage, and Bright Data Scraper API supplies 5K records/month. These can support small evaluations or modest recurring jobs if the relevant operation fits the allowance.
For a single standard page checked daily in a 30-day month, Browse AI's 50-credit allowance covers the 30 checks. That is a meaningful free monitor example, provided the page is not a premium target and the extracted row count does not increase the charge. ScrapingBee's 1,000 credits and Zyte's $5 are trials; Octoparse Free runs locally. Those distinctions matter more than a “free” label.
Free web scraping tools open source teams can own
Firecrawl's self-hostable core is an option when source or infrastructure control justifies operating the services. Open source removes a vendor subscription for that core; it does not supply hosting, monitoring, recovery, or an engineer to fix the next failure.
Use the Firecrawl self-host guide to assess that operating boundary before treating it as the cheapest way to scrape. For a small product team that only needs an endpoint returning known pages, managed entry plans can avoid a separate infrastructure project. Choose self-hosting for a concrete control requirement and an owner who can sustain it.
How these were picked
The comparison prioritizes job fit, billing transparency, and the wall that changes the buying decision. Pricing pages and relevant maker documentation were opened in this run, and the figures were checked on 6 October 2026. The cost examples are arithmetic using those published rates and explicit workload assumptions. This was not a hands-on product trial, and no speed, accuracy, or success-rate ranking is claimed.
Firecrawl, Bright Data, Browse AI, and Context.dev are partner tools on this site; Apify, ScrapingBee, Octoparse, and Zyte provide independent alternatives. Partner status does not make raw proxies the right purchase for an operator's monitor, or a recorded robot the right API for a software feature. The recommendations follow those boundaries.
The practical criteria are: does the product return the needed output; who owns its setup and repair; what repeated operation is billed; which quota or concurrency limit arrives first; and what happens to an incomplete or rejected response? A larger marketplace or a lower teaser price cannot answer those questions alone.
Framework and browser-library catalogs were kept outside the ranked shortlist because this reader is choosing a recurring service, a no-code workflow, or access infrastructure. Interactive browser operation is a separate requirement when a job depends on substantial navigation rather than page collection.
Check the target site's terms and robots.txt before scheduling collection.
The ones to avoid
Avoid the wrong fit, even when the product is good at another job. These are the choices most likely to create work that the purchase was meant to remove.
- Octoparse Free for an unattended cloud feed. Its tasks run locally. Pay for the cloud execution your process requires, or choose a service with the appropriate operating model.
- Bright Data residential proxies as a finished-dataset purchase. They supply access; you still own requests, parsing, and acceptance. Use a suitable Scraper API when the record is what you want to buy.
- Browse AI Personal's annual headline for a frequent large monitor. The 12,000-credit annual allowance is not enough for the illustrative 43,200-credit yearly job. Size visits, rows, premium targets, and domains first.
- Zyte's $0.06 headline as a PAYG quote. It is the low end of the $500 commitment tier. Estimate the actual target and mode before buying the commitment.
- ScrapingBee's credit total as a request guarantee. Rendering and proxy settings can spend several credits on the same request. Budget the configuration that works.
- Firecrawl or Context.dev as a complete data-quality system. Both can deliver content you must reject. Persist status and output evidence, and protect downstream records from incomplete updates.
The product to avoid is the one that leaves you maintaining the layer you expected it to take over. A precise boundary is more valuable than a confident overall ranking.
The Monday move
Run a small, scheduled evaluation with one accountable owner. Select ten representative URLs, define the fields or document content you expect, and name what will make a response unacceptable. For a no-code task, record the workflow; for an API, connect it to your scheduler and storage.
Run once daily for seven days. Preserve the original response, target status, output, consumed billing units, and accepted-record count. Inspect pagination, missing values, duplicate identifiers, and changes that should or should not trigger an update.
Then price the complete month using that observed target mix. Select the least complex option that meets the output and ownership requirements, and leave the acceptance checks in place after the trial. A feed earns production status through repeatable useful results, not its first successful request.
What are some good tools for web scraping?
Firecrawl and Context.dev fit page content for agents; Browse AI and Octoparse fit visual extraction workflows; Bright Data, Zyte, and ScrapingBee fit different access and fetching needs. Apify is especially useful when the right target-specific Actor already exists. Choose the output and owner first, then compare the complete monthly bill.
Can Chatgpt scrape websites?
ChatGPT can open websites and gather information using its browser capability, as described in the official OpenAI documentation. That can serve an interactive collection task. For recurring prices, listings, or agent documents, evaluate the schedule, output schema, saved results, and failure owner separately. The choice here is which service supplies that recurring workflow, rather than whether an AI assistant can read a page.
Which AI is best for web scraping?
Choose the extraction service and expected output before selecting a language model. Firecrawl and Context.dev belong on the shortlist for Markdown or structured fields; Browse AI fits an operator-owned robot. The best choice is the one that returns the required information on your representative sources at an acceptable complete cost.
Is web scraping outdated?
Check whether the target offers an appropriate API or feed first. When the needed information is published only as pages, extraction remains an option. The useful buying distinction is who owns retrieval, extraction, scheduling, and validation, rather than whether the product labels itself AI.
What are the top 10 web scraping tools?
This shortlist covers eight products for three recurring jobs: agent data, no-code monitoring, and access at scale. Choose within those jobs rather than adding tools merely to reach ten. A browser automation project or a self-hosted framework introduces a different ownership decision from the services compared here.
Get the AI Business Workflow Audit Checklist through the newsletter and map the output, schedule, acceptance rules, and owner before committing to a web-data workflow.
- Last Updated
- Oct 6, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Agent Memory Explained: Context, Sessions, Stores and Costs
Agent memory explained for builders: context, sessions, long-term stores, files and skills, provider costs, and fixes for stale facts and user leaks.Oct 5, 2026Build
Pinecone Pricing (2026): What 1M to 100M Vectors Cost
Pinecone pricing verified October 2026: free Starter, $20 Builder, paid minimums, and costs for 1M to 100M vectors at stated query volumes.Oct 5, 2026Build
Lovable Alternatives (2026): Emergent, Blink, Bolt, Replit and Base44
Compare Lovable alternatives by credit costs, backend depth and code export. Live pricing for Emergent, Blink, Bolt, Replit, Base44 and v0.Oct 5, 2026Build
LLM Observability Tools in 2026: Costs by Team Size for Langfuse, LangSmith, Helicone, Arize Phoenix, Braintrust and Datadog (Compared)
Compare six LLM observability tools by team size, pricing at 100,000 monthly runs, self-hosting licenses and OpenTelemetry support.Oct 5, 2026Build
How to Use OpenCode
Install OpenCode, connect existing model access, run a real coding task, configure AGENTS.md and plugins, and understand API and Zen costs.Oct 4, 2026Build
Netlify Pricing (2026): What a Month Costs in Credits
Netlify's current Free, Personal and Pro prices, credit rates, and monthly budgets for a marketing site, Next.js app and 10-site agency.Oct 4, 2026Build
Softr Review (Verified October 2026)
Softr review for client portals and internal tools: current monthly and annual prices, user and record limits, AI features, and the plan to choose.Oct 4, 2026Build