Firecrawl Alternatives
Compare Firecrawl alternatives for business AI pipelines by crawl support, Markdown and JSON output, migration work and cost per usable page.




Firecrawl alternatives split at 10,000 accepted pages: in this model, Firecrawl costs $83 in vendor fees plus three operator hours, while ScrapFly costs $30 plus three hours. The cheaper invoice is not automatically the cheaper replacement, because discovery, rendered retries, JSON extraction and downstream chunking can erase the difference.
The Short Answer: Replacing Firecrawl Means Replacing a Pipeline
Pick Apify Website Content Crawler when you need the closest broad managed replacement, Crawl4AI when infrastructure control is the point, ScrapFly when one credit pool should cover crawling and structured extraction, and Jina Reader when another system already supplies the URLs. ScrapingBee, Zyte API and Bright Data Crawl API become stronger when access to difficult pages matters more than a native site-to-Markdown workflow.
The unit that matters is not a request or a discovered URL. It is an accepted page that reaches the retrieval-augmented generation pipeline, meaning the model receives usable retrieved source material, with the required Markdown, JSON fields, links and metadata intact. A cheap response that loses a table, invents an empty price field or breaks the chunker is a paid failure.
Firecrawl: The Baseline
Firecrawl is the baseline because its Crawl endpoint already bundles discovery, rendering and page processing, then returns Markdown or schema-shaped JSON. It charges 1 credit per crawled page and another 4 credits for JSON mode, so the relevant baseline for this comparison is 5 credits per attempted page.
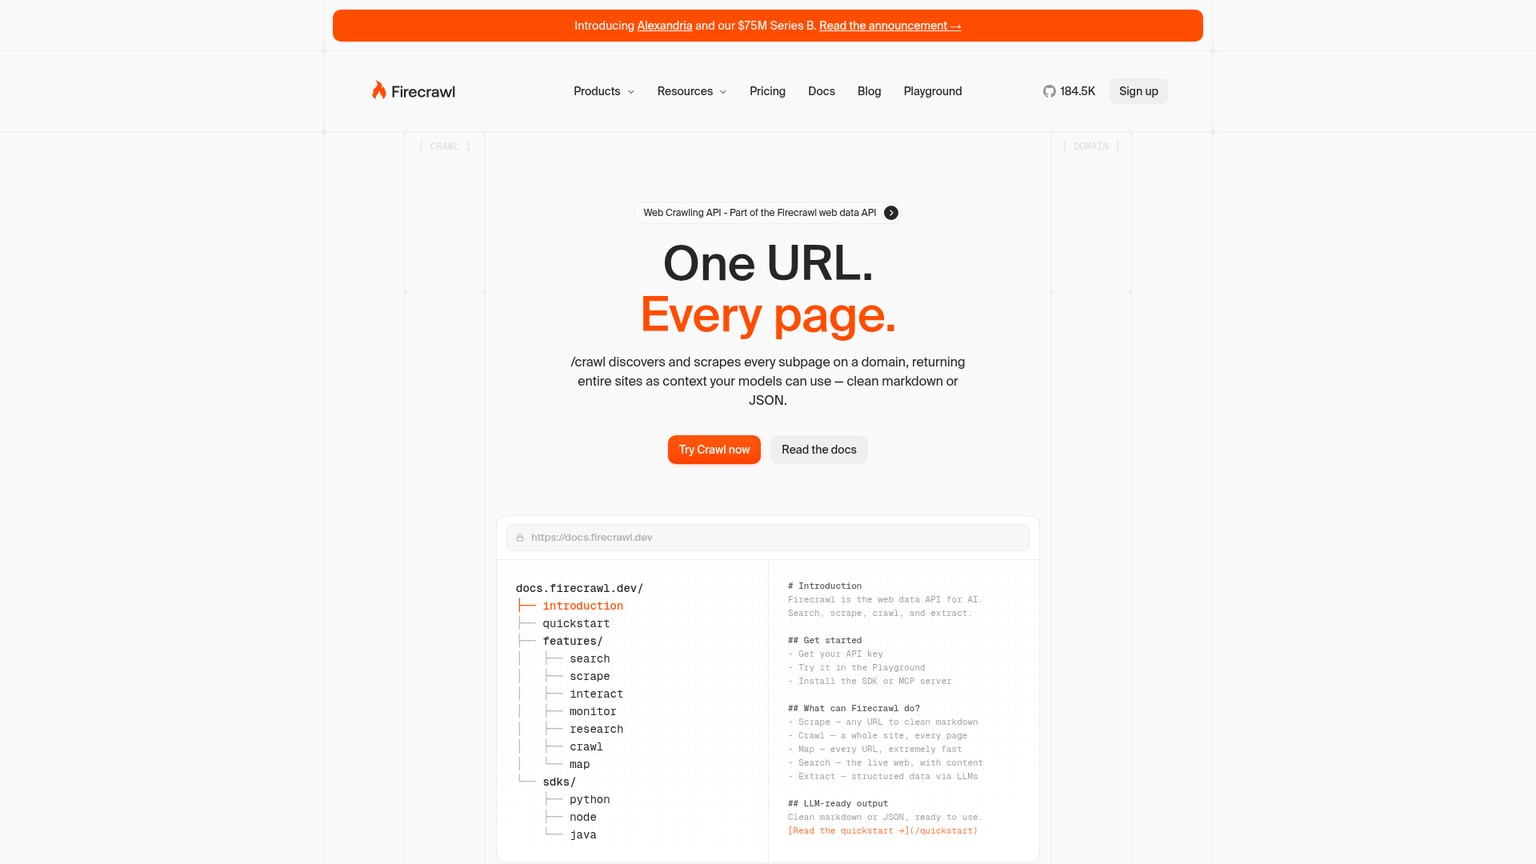
That bundle is why staying can beat an apparently cheaper replacement. Firecrawl also handles crawl scope, subdomains, paths, depth and streamed page delivery. A reader API may cost less per URL but leave discovery to your team; an access API may fetch protected pages but leave Markdown conversion and schema normalization downstream.
Firecrawl Pricing in the Accepted-Page Model
Firecrawl's current plans are Free at $0 for 1,000 credits, Hobby at $16 per month billed yearly for 5,000 credits, Standard at $83 for 100,000 credits, Growth at $333 for 500,000 credits, Scale at $599 for 1,000,000 credits, and Enterprise with custom pricing. Overage is $9 per 1,500 credits on Hobby, $47 per 35,000 on Standard, $177 per 175,000 on Growth and $397 per 350,000 on Scale. Those figures, limits and crawl capabilities were checked against the current Firecrawl Crawl page on September 25, 2026.
At a 10% reserve for successful responses that fail the local acceptance gate, 1,000 accepted Markdown-and-JSON pages need 5,500 credits. Hobby plus one overage block is $25. Ten thousand accepted pages need 55,000 credits, so Standard is $83. One hundred thousand accepted pages need 550,000 credits, so Growth plus one overage block is $510.
Search is a separate layer. If the job begins with a query and needs ranked sources rather than a known site or URL set, use the AI search API comparison for that decision, then hand selected URLs to the extraction layer.
Firecrawl Alternatives at a Glance
The table scores documented fit, not measured output quality. Prices were verified on first-party pages on September 25, 2026. "Free trial" also includes a permanent free allowance where that is what the vendor offers.
There is no universal winner because three different products hide inside the phrase "web extraction." A crawler discovers a site, a reader converts a supplied URL, and an access layer gets through rendering or blocking. Buy the narrowest product that owns every stage your team does not want to operate.
How These Were Picked
A candidate made the list only if its current first-party material supports a credible route to both useful page content and machine-readable output. Search-only APIs were excluded because ranked discovery is not a crawler replacement. Proxy-only services were excluded because an IP does not produce clean Markdown, required JSON or a saved crawl manifest.
The comparison turns on five acceptance checks:
- Discovery: Can it traverse a site, obey scope and retain a canonical URL manifest, or must another component supply every URL?
- Rendering and access: Can it execute JavaScript and handle the site's access conditions without an unbounded retry bill?
- Output contract: Does it preserve headings, tables, code and links in Markdown, and can it satisfy required JSON fields without a second opaque transformation?
- Evidence: Can the team save the request, raw response, normalized output, headers, configuration, content hash and verdict for every fixture URL?
- Complete cost: What is paid for discovery, rendering, extraction, successful-but-rejected retries, minimum commitments and operator time?
No candidate was executed for this article. There are therefore no claimed pass rates or latency rankings. Every quality statement below is a documented capability; every dollar comparison is a model whose assumptions are visible.
The Fixed 20-URL Acceptance Fixture
Do not migrate on a vendor demo URL. Use the same fixed fixture against the old and new configuration, then save every response. The fixture deliberately mixes content shapes that expose different failures:
- Code and long documents: MDN Fetch API, Python classes, Rust ownership, RFC 9110 HTML and HTTPBin HTML.
- Tables, links and structured pages: MDN table reference, W3C table tutorial, Wikipedia web scraping, Books to Scrape catalog and one fixed product page.
- Pagination and JavaScript: Quotes to Scrape, its JavaScript route, its scroll route, the MDN JavaScript guide and HTTPBin link normalization.
- Encoding and PDFs: HTTPBin Unicode, RFC 9110 PDF, a two-column research PDF, a minimal W3C PDF and IRS Form W-9.
Every result must contain source_url, final_url, title, markdown, links, status_code, fetched_at and content_sha256. Product pages also require entity_name, amount and currency; the research PDF requires published_at. A field may be explicitly null only where the fixture manifest allows it. Missing is not the same as null.
Save one directory per tool, version and configuration. For each URL, retain request.json, response headers, the unmodified body, normalized.json, verdict.json and the SHA-256 digest. The verdict should name the first failed rule, not only pass: false. That evidence lets another engineer reproduce a decision after a vendor, parser or page changes.
The Accepted-Page Cost Worksheet
The model uses 1,000, 10,000 and 100,000 accepted pages per month, with a 10% reserve for responses that the vendor calls successful but the local schema or Markdown gate rejects. Those are billable retries. Explicit vendor failures are treated according to each published refund policy.
The base formula is simple: vendor or host cash, plus discovery, rendering, extraction and paid retry charges, plus operator hours multiplied by the team's loaded hourly rate. The table prints vendor cash and hours separately so the $100 hourly assumption can be replaced without rebuilding every vendor formula.
At $100 per operator hour, the 10,000-page totals are $383 for Firecrawl, $419 for Apify, $1,248 for Crawl4AI, $330 for ScrapFly, $401.10 for Jina, $449 for ScrapingBee, $555.22 for Zyte and $516.50 for Bright Data. The Jina number applies only when a reliable URL manifest already exists; it is not a full-site crawl total. The Bright Data and Zyte hours include downstream Markdown and schema work because neither product page documents native Markdown as the output contract used here.
The extraction line is deliberately explicit. Firecrawl uses 1 crawl credit plus 4 JSON credits. ScrapingBee uses 5 JavaScript credits plus 5 AI credits in this scenario. ScrapFly uses 5 browser or Unblocker credits plus 5 extraction-model credits. Zyte uses tier-3 browser pricing plus one fixed custom-attribute extraction. Apify uses a deterministic JSON envelope, 80% raw HTTP and 20% headless pages at the published upper headless estimate; optional AI summaries are not included.
Jina assumes 2,000 output tokens per attempt at $0.050 per million. Its consumption value is tiny, but cash flow is lumpy: once the 10 million free tokens are gone, the smallest listed top-up is 1 billion tokens for $50. Crawl4AI assumes $24, $48 and $96 DigitalOcean hosts at the three volumes, but those are planning inputs, not measured capacity claims.
1. Apify Website Content Crawler: Best Overall Managed Replacement
Apify Website Content Crawler is the strongest broad managed replacement when a team needs discovery, JavaScript rendering, Markdown and a durable dataset in one service. It crawls with raw HTTP or headless Firefox, stores each result as a dataset record and exports JSON or CSV. That makes the migration shape close to Firecrawl without pretending the APIs are identical.
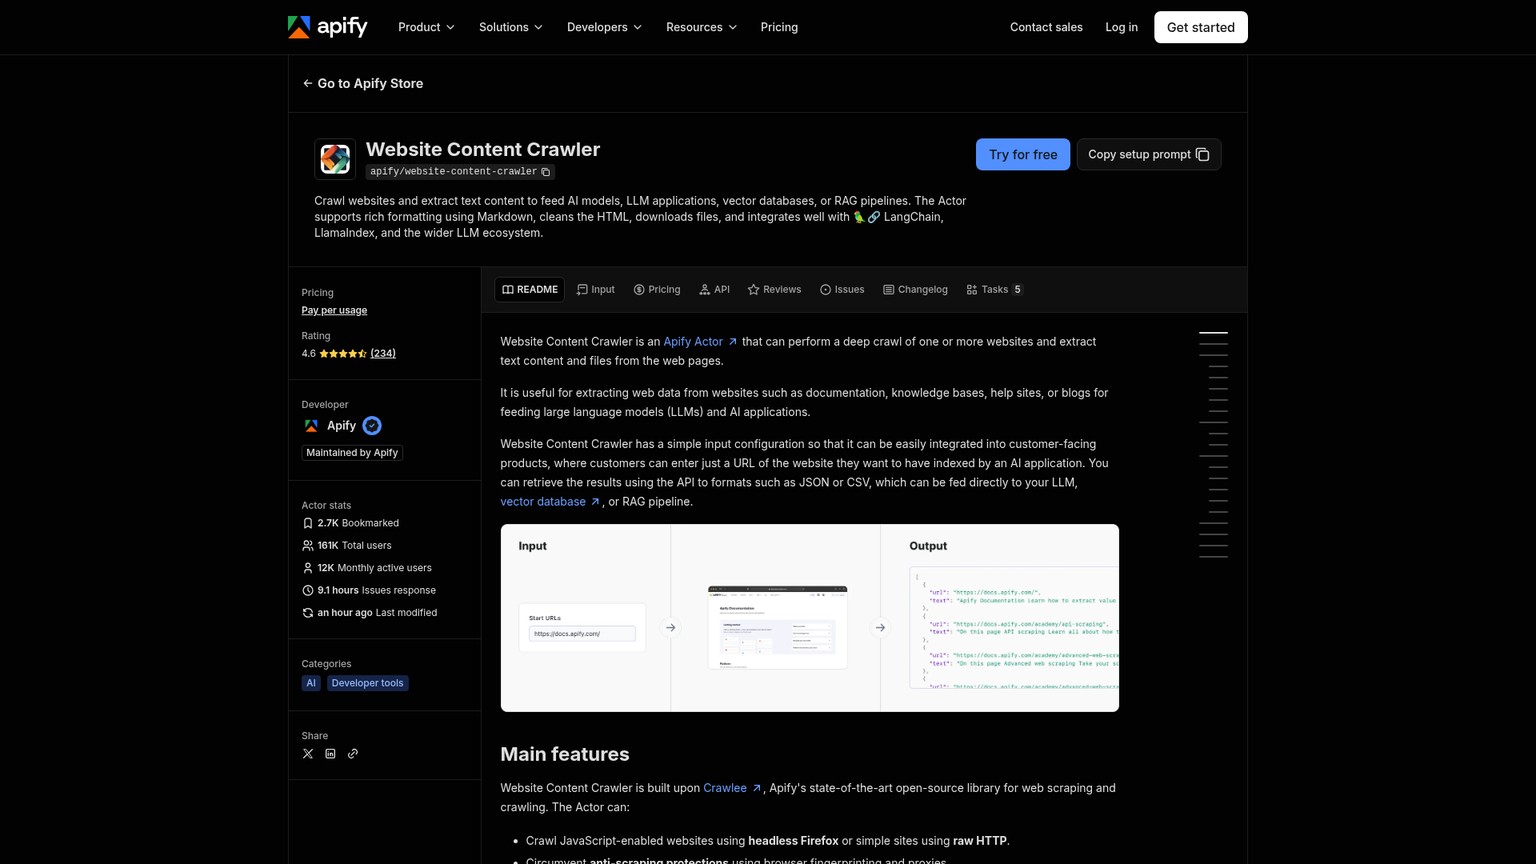
Its clearest advantage is control over the crawl as a job. Scope, output and saved dataset records live together, and files such as PDFs can be downloaded. Its named wall is semantic extraction: the Actor's JSON dataset is a structured envelope containing text, Markdown and metadata, but a custom business schema still needs deterministic rules, another Actor or a model stage.
The Actor's published estimate is approximately $0.20 per 1,000 raw-HTTP pages and $0.50 to $5 per 1,000 headless pages at its stated baseline. Optional AI summaries add roughly $2 to $3 per 1,000 pages, with pages lacking headings reaching about $7 per 1,000. The model above avoids that add-on because a summary is not a substitute for required JSON fields.
Apify's plans are Free at $0 with $5 monthly usage and 5 concurrent runs; Starter at $19 with $19 usage and 32 concurrent runs; Scale at $199 with $199 usage, $0.16 compute units and 128 concurrent runs; Business at $999 with $999 usage, $0.13 compute units and 256 concurrent runs; and custom Enterprise. Free usage stops when exhausted. Paid plans continue as overage, and unused usage does not roll over. The current Apify pricing page is the source for those platform terms.
Best for: A small product or data team replacing a managed crawl job, especially when run history and dataset exports matter.
Standout: Full-site discovery, browser rendering, Markdown and persisted JSON dataset records in the same managed run.
Pricing: Free $0; Starter $19; Scale $199; Business $999; Enterprise custom. Actual Actor cost also includes compute, storage, proxies and transfer used by the run.
Free trial: The permanent Free plan includes $5 of monthly platform usage without a card.
- Raw HTTP and headless Firefox cover both cheap static pages and JavaScript pages.
- Dataset records make saved-response review and export straightforward.
- Crawl scope, file downloads, metadata and Markdown sit in one managed job.
- The platform bill spans compute, storage, transfer and proxy usage rather than one page credit.
- A JSON dataset record is not automatically the business schema your downstream code expects.
- AI summaries add a separate Actor cost and still do not prove extraction acceptance.
A Five-Step Apify Migration Trial
Load the fixed URL manifest
Start with the 20 fixture URLs, not the whole production domain. Pin the Actor input, crawler type, page limit and scope so a second run means the same thing.
Use raw HTTP until a page proves it needs a browser
Keep the cheap path for static pages and route JavaScript fixtures to headless rendering. Save the chosen crawler mode with each result.
Export Markdown and the dataset record
Retain the unmodified
markdown, canonical URL, metadata and links. Transform that record into the required local JSON schema in a separate deterministic step.Reject before chunking
Run table, code, link and required-field checks against the normalized record. One failed rule sends the URL to the retry ledger, not into the vector index.
Price only accepted pages
Divide the full Actor, proxy, storage and operator bill by accepted pages. Compare that result with the Firecrawl baseline before expanding the crawl.
2. Crawl4AI: Best Self-Hosted Alternative
Crawl4AI is the best self-hosted choice when infrastructure ownership, data boundaries or reusable extraction rules are hard requirements. It produces Markdown and supports structured extraction with CSS, XPath or an LLM strategy, so it can cover both retrieval text and JSON fields without a per-request software fee.
The current security floor matters more than the license price. Version 0.9.4 was released September 23, 2026 and fixes three advisories, including two server-side request forgery paths and a configuration trust-boundary flaw that could expose environment values. Any evaluation should pin v0.9.4 or later and review the project security notices before exposing its API.
Crawl4AI vs Firecrawl
Firecrawl sells the operated service around the crawl: managed queues, browsers, credits, delivery and support. Crawl4AI supplies the crawler and extraction system while your team owns deployment, upgrades, observability, proxy strategy and incident response. The choice flips when those responsibilities are already shared platform capabilities, not when a single engineer must create them for this project.
Self-hosting recommends at least 4 GB RAM, Docker 20.10 or later and Compose 2.24 or later. The cost worksheet uses DigitalOcean's current Basic Droplet prices of $24 for 4 GiB, $48 for 8 GiB and $96 for 16 GiB. Those sizes are scenario inputs only; no page throughput was measured in this run.
Best for: Teams with an existing container platform, a strict data boundary and engineers who can own crawler operations.
Standout: Open-source control plus deterministic CSS or XPath extraction schemas that can avoid per-page model spend.
Pricing: $0 software license. The model uses $24, $48 and $96 monthly hosts, plus proxies, storage, monitoring, model calls and labor as needed.
Free trial: The software is open source; infrastructure is not included.
- Markdown and structured extraction run inside infrastructure the team controls.
- CSS and XPath schemas can make stable sites cheap and deterministic.
- The project now defaults its self-hosted server toward authenticated, loopback-safe operation.
- Proxy reputation, browser capacity, patching, queues and recovery become your problem.
- Host size does not establish accepted-page throughput without a saved run.
- LLM extraction moves model-token cost and data-boundary review to a separate provider or local model.
The Firecrawl self-host guide covers the separate decision between the Firecrawl repository and Firecrawl Cloud. Do not count Crawl4AI's $0 license as savings until the same worksheet includes the people who keep it patched and available.
3. ScrapFly: Best Small-Team Crawl and Extraction Combination
ScrapFly is the strongest small-team alternative when one account should cover access, crawling, Markdown conversion and typed extraction. Its products share one credit pool, and the extraction layer accepts HTML, Markdown, XML, JSON, CSV, RSS or plain text. Teams can use deterministic templates, pretrained models or a JSON-schema prompt without stitching together separate vendors.
The credit model is legible once the configuration is fixed. A simple datacenter HTTP request is 1 credit, JavaScript rendering or Unblocker is 5, residential routing is 25 and a full-page screenshot is 60. Template extraction costs 1 additional credit, while an extraction prompt or model costs 5. Documents larger than 500 KB repeat the extraction base charge for each additional 500 KB.
That makes the article's scenario 10 credits per successful attempt: 5 for browser or Unblocker plus 5 for extraction. With the 10% retry reserve, it becomes 11 credits per accepted page. The model does not add residential routing; a target that needs it changes the answer sharply.
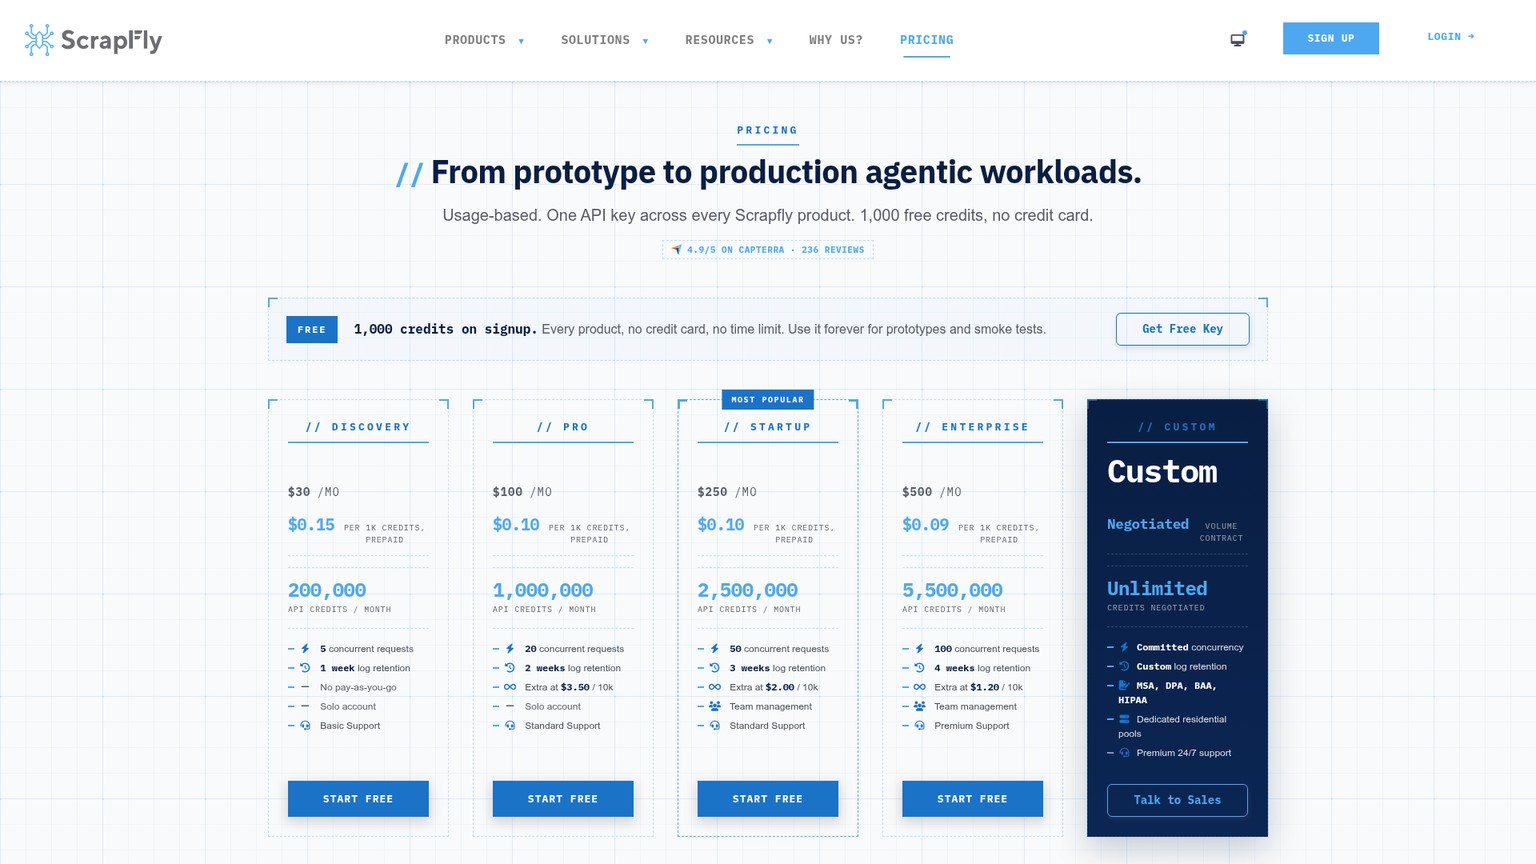
The current plans are Free with 1,000 one-time credits; Discovery at $30 per month with 200,000 credits and 5 concurrent requests; Pro at $100 with 1,000,000 credits and 20 concurrent requests; Startup at $250 with 2,500,000 credits and 50 concurrent requests; Enterprise at $500 with 5,500,000 credits and 100 concurrent requests; and negotiated Custom. Discovery stops at its quota. Pro overflow is $3.50 per 10,000 credits, Startup is $2 and Enterprise is $1.20. Unused credits do not roll over. These terms come from ScrapFly's current pricing.
Best for: A small team that wants a managed crawler, access controls and typed extraction under one bill.
Standout: The same credit pool can fund the crawler, browser, Unblocker and three extraction strategies.
Pricing: Free 1,000 credits; Discovery $30; Pro $100; Startup $250; Enterprise $500; Custom negotiated.
Free trial: 1,000 credits on signup, no card and no listed expiry.
- Template extraction can cut model cost on stable layouts.
- Pretrained and prompted extraction return typed JSON without a separate model vendor.
- Failed requests cost zero credits, while the response reports the credits consumed.
- Browser, residential and extraction options compound quickly on difficult pages.
- Documents above 500 KB multiply the extraction charge.
- Discovery has no overflow, so production jobs need Pro or a hard stop before quota exhaustion.
ScrapFly is the worksheet winner at 10,000 accepted pages in this particular scenario: $30 plus three operator hours, compared with Firecrawl's $83 plus three. That $53 monthly cash difference is too small to justify a loose migration. It becomes persuasive only if the fixed fixture passes, production targets avoid the 25-credit residential path and the schema requires no extra cleanup.
4. Jina Reader: Best When You Already Have the URL List
Jina Reader is the best low-variable-cost converter when discovery is already solved and each supplied URL needs clean Markdown or schema-shaped JSON. Its default engine renders JavaScript in a headless browser, while the direct engine takes the simpler HTTP route. ReaderLM-v2 accepts a JSON schema or natural-language instruction for structured output.
Its advantage is also the boundary: Reader reads a URL. It does not replace a full site's scope rules, frontier, duplicate policy or crawl manifest. If a sitemap, search stage or internal catalog reliably supplies the URL list, that narrow job can be a virtue. If not, discovery cost belongs back in the worksheet.
Reader basic usage is free. A new key includes 10 million tokens, and output tokens are charged when a key is used. A 1 billion-token top-up is $50, or $0.050 per million; an 11 billion-token top-up is $500, or $0.045 per million. Failed requests do not deduct tokens. Rate limits are 20 requests per minute without a key, 500 with a free or paid key, and 5,000 with a premium key. All figures come from the current Jina Reader page.
The worksheet assumes 2,000 output tokens for each successful attempt. That makes consumed token value $0.11 for 1,000 accepted pages, $1.10 for 10,000 and $11 for 100,000 after the retry reserve. These are economic-use values, not the cash charged at checkout. After the free pool is gone, the smallest listed purchase is still $50.
Best for: A pipeline with a trusted URL manifest that needs low-cost page-to-Markdown or JSON conversion.
Standout: Output-token billing, JavaScript rendering and JSON-schema extraction in a narrow reader API.
Pricing: Basic Reader usage is free; every new key gets 10 million tokens; paid packs are $50 for 1 billion or $500 for 11 billion.
Free trial: 10 million tokens with a new API key.
- The default renderer handles client-side JavaScript before conversion.
- JSON-schema and instruction modes can produce structured fields from the same reader.
- Failed requests do not consume tokens.
- Site discovery, scope and crawl-state persistence need another component.
- A $50 token pack is the minimum cash step after the free pool, even when current consumption is worth much less.
- Output-token cost varies with page length and response format.
Jina is the apparent 100,000-page cost winner at $11 plus six hours, but only under the supplied-manifest assumption. Adding an unreliable discovery job and manual deduplication would make that row incomparable with Firecrawl or Apify. Use it when the component boundary is real, not to hide missing crawl work.
5. ScrapingBee: Best Credit-Capped Scraping API
ScrapingBee is the best request-level alternative when a team wants to cap how expensive any one page may become. It can return page Markdown or a JSON response, apply CSS extraction rules, and add AI extraction when layouts are not stable enough for selectors.
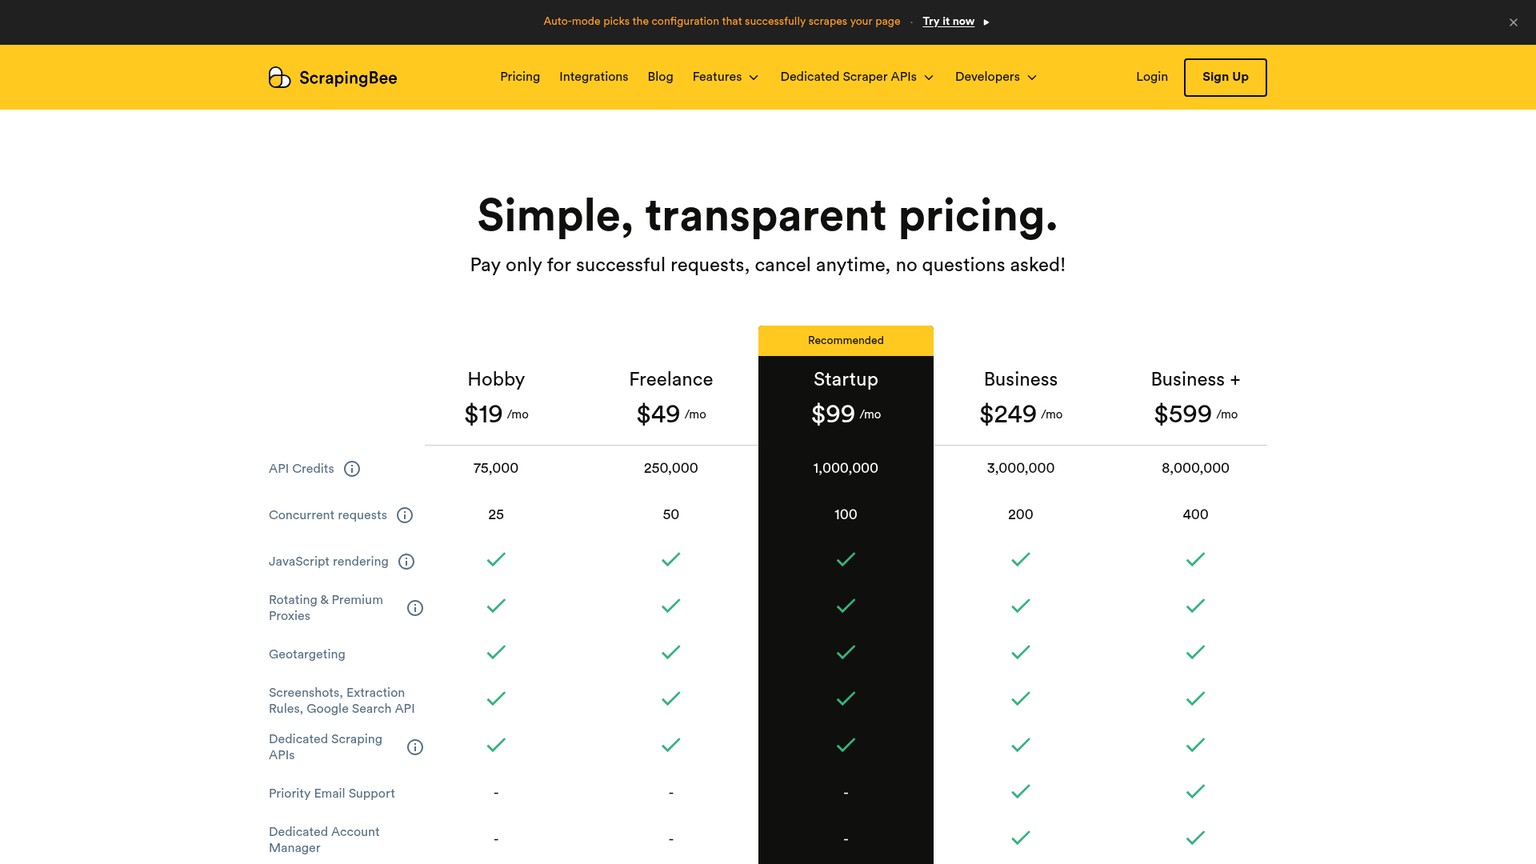
The useful control is the credit ladder. Classic HTTP is 1 credit, classic JavaScript is 5, premium without JavaScript is 10, premium with JavaScript is 25, and stealth with JavaScript is 75. AI features add 5 credits. Auto mode charges the configuration that succeeds, charges zero if all configurations fail, and allows a maximum-cost cap.
The wall is orchestration. ScrapingBee fetches requested pages; it is not the closest match for Firecrawl's site discovery and crawl frontier. A team must own the URL manifest, scope, duplicate handling and job state, then distinguish a vendor failure from a successful response that its local acceptance gate rejects.
Current plans are Hobby at $19 per month for 75,000 credits and 25 concurrent requests; Freelance at $49 for 250,000 and 50; Startup at $99 for 1,000,000 and 100; Business at $249 for 3,000,000 and 200; and Business+ at $599 for 8,000,000 and 400. The evaluation allowance is 1,000 credits with no card. Those figures come from ScrapingBee's current plans.
Best for: Teams that already own discovery and need explicit render, premium-proxy and per-request cost ceilings.
Standout: Auto mode can escalate access while max_cost limits what a single response may consume.
Pricing: Hobby $19; Freelance $49; Startup $99; Business $249; Business+ $599.
Free trial: 1,000 credits without a card.
- Markdown, CSS extraction and AI extraction are available in one request API.
- The 1, 5, 10, 25 and 75-credit ladder makes access cost inspectable.
- Auto mode charges zero when every internal configuration fails.
- Site discovery and crawl persistence remain outside the product boundary.
- A vendor-success response rejected by your schema is still a paid attempt.
- Credit usage can rise 15 times from classic JavaScript to stealth JavaScript before AI extraction is added.
In the model, JavaScript plus AI extraction uses 10 credits per attempt. The retry reserve makes that 11 per accepted page, putting 1,000 pages on Hobby at $19, 10,000 on Freelance at $49, and 100,000 on Business at $249 because 1.1 million credits exceed Startup's 1 million.
6. Zyte API: Best Per-Site Anti-Bot Pricing
Zyte API is the best fit when access difficulty varies sharply by target and the buyer wants the vendor to assign each site a pricing tier. It bundles the necessary datacenter or residential path, rendering and access work into the response price, and charges only successful responses.
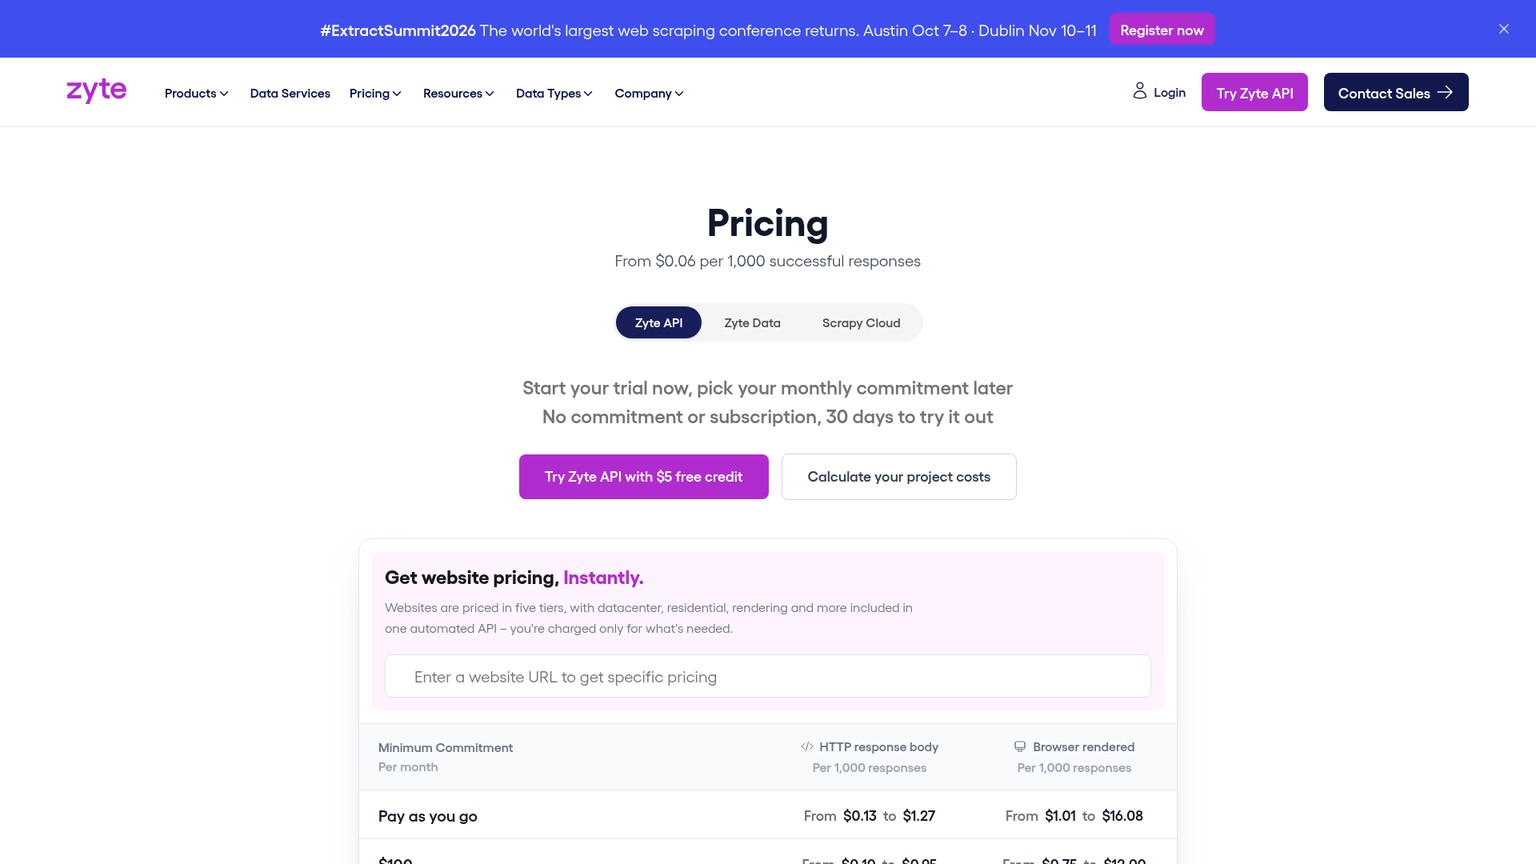
Pay-as-you-go HTTP prices per 1,000 responses are $0.13, $0.23, $0.44, $0.70 and $1.27 across site tiers 1 through 5. Browser-rendered prices are $1.01, $2.01, $4.02, $8.04 and $16.08. At a $100 monthly commitment, those browser rates become $0.75, $1.50, $3, $6 and $12; at $200 they are $0.60, $1.20, $2.40, $4.80 and $9.60; at $500 they are $0.48, $0.96, $1.92, $3.84 and $7.68.
The HTTP commitment schedules matter too. At $100, tiers 1 through 5 cost $0.10, $0.17, $0.33, $0.53 and $0.95 per 1,000. At $200 they cost $0.08, $0.14, $0.26, $0.42 and $0.76. At $500 they cost $0.06, $0.11, $0.21, $0.34 and $0.61. Enterprise offers further negotiated discounts. The current Zyte pricing page also lists $5 of trial credit for 30 days.
Custom attributes can use a fixed extract method at $0.001 or a generative method at $0.002 per 1,000 input tokens and $0.01 per 1,000 output tokens. Automatic extraction is $0.0004 to $0.0016 per data type. That creates a clean extraction line in a worksheet instead of hiding model usage inside an undifferentiated plan.
The wall for this comparison is output. Zyte documents HTTP bodies, browser HTML and structured fields, not a native Markdown response contract. A downstream HTML-to-Markdown conversion and its regression tests therefore remain part of the migration.
Best for: Multi-domain extraction where target difficulty, browser need and access infrastructure drive most of the vendor bill.
Standout: Five per-site request tiers and no charge for unsuccessful or rate-limited responses.
Pricing: PAYG with no commitment; $100, $200 and $500 monthly commitments; Enterprise with further discounts. Response price depends on site tier and HTTP versus browser output.
Free trial: $5 credit for 30 days with no commitment.
- The target-specific tier folds access infrastructure into one response price.
- Successful-response billing removes direct cost for rate limits and vendor-declared failures.
- Fixed and token-priced custom attributes make extraction charges visible.
- Native Markdown is not the documented output, so conversion remains yours.
- A target's tier can change, and successful responses may still fail the local content gate.
- Full-site discovery and downstream crawl-state design require deliberate configuration.
The worksheet uses tier-3 browser rendering plus one fixed custom extraction. That produces $5.52, $55.22 and $374 in modeled vendor usage across the three volumes. It is a scenario, not a universal Zyte price; replace the tier with the quote for the domains you will crawl.
7. Bright Data Crawl API: Best for Protected-Site Scale
Bright Data Crawl API is the strongest candidate when protected-site access, proxy infrastructure and concurrency dominate the requirement. Its price includes JavaScript rendering, residential proxies, validation, CAPTCHA solving, geotargeting, discovery, JSON or CSV parsing and unlimited concurrency.
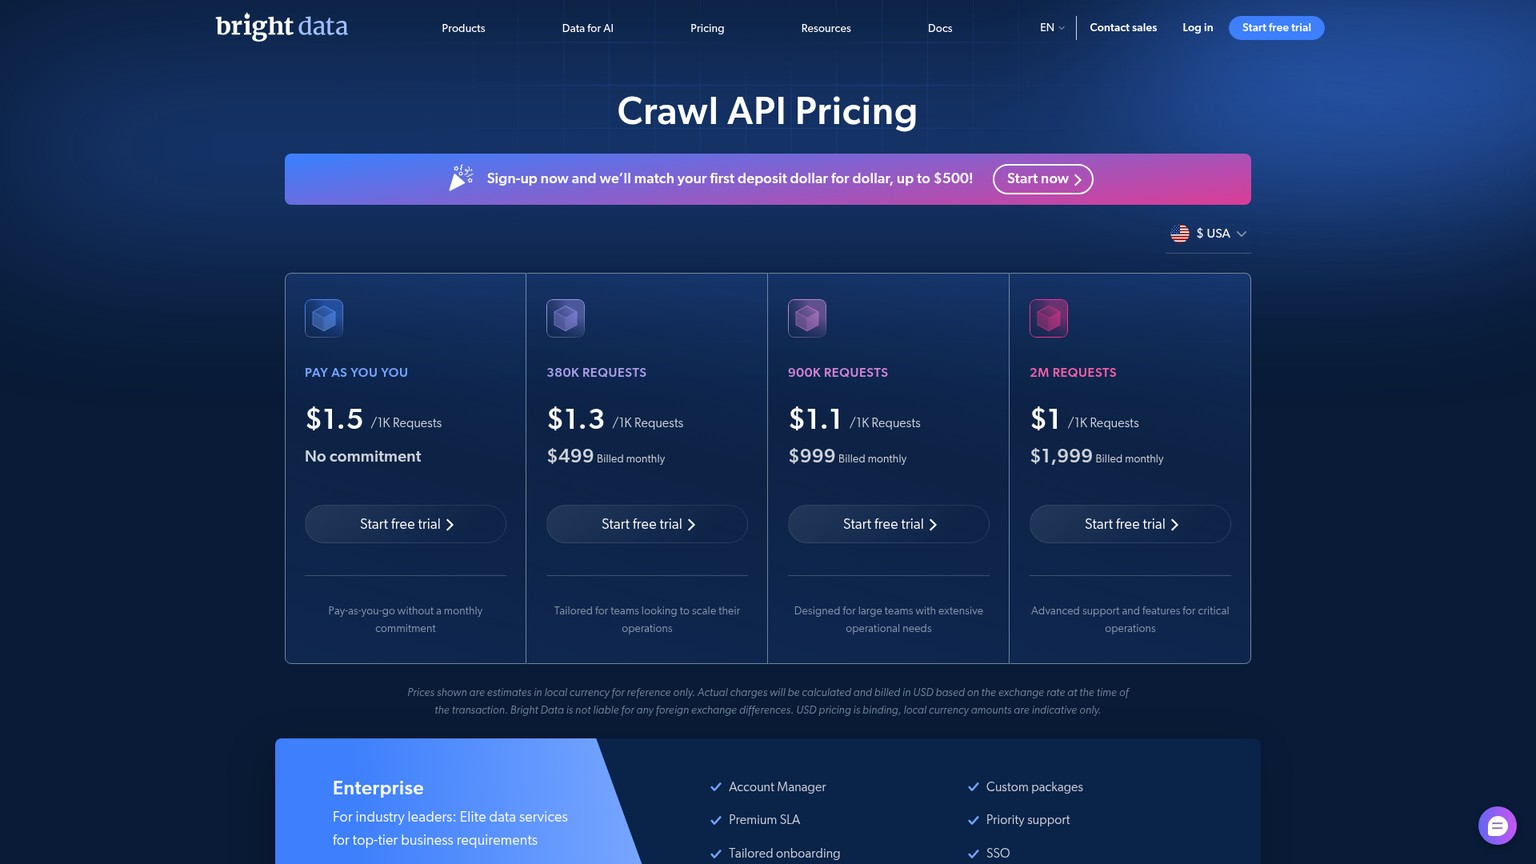
The product begins at $1.50 per 1,000 pay-as-you-go requests with no commitment. The 380,000-request plan is $499 per month at $1.30 per 1,000; 900,000 requests cost $999 at $1.10 per 1,000; and 2 million requests cost $1,999 at $1 per 1,000. Enterprise is custom. These are the current Bright Data Crawl API prices.
The important wall is the same one that affects Zyte: the documented delivery formats are NDJSON and CSV, not native Markdown. For a retrieval pipeline that requires stable headings, code fences, tables and source links in Markdown, the converter is a production component. Its failures and operator time belong in the denominator.
At pay-as-you-go rates, a 10% billable retry reserve puts vendor cash at $1.65 for 1,000 accepted pages, $16.50 for 10,000 and $165 for 100,000. Those small request figures should not be read as complete costs. The worksheet assigns four, five and eight hours for Markdown conversion, schema normalization and review, and a difficult target may change request behavior.
Best for: High-concurrency collection from protected domains where managed access work is more valuable than native Markdown.
Standout: Rendering, residential routing, CAPTCHA handling, validation and unlimited concurrency in the Crawl API price.
Pricing: PAYG $1.50 per 1,000 requests; $499 for 380,000; $999 for 900,000; $1,999 for 2 million; Enterprise custom.
Free trial: The current pricing cards offer a free trial but do not state the credit amount in the visible plan terms.
- Access infrastructure that would otherwise require several components is bundled.
- Unlimited concurrency suits large jobs with strict delivery windows.
- NDJSON and CSV provide machine-readable delivery without scraping the provider's dashboard.
- Native Markdown is not the documented output contract.
- PAYG request cost alone hides conversion, schema and accepted-page review work.
- The broad access stack is unnecessary overhead for public documentation sites that raw HTTP handles cleanly.
Firecrawl Alternatives Open Source Teams Can Operate
Crawl4AI is the clearest open-source alternative in this shortlist, but Firecrawl also publishes a self-hostable core. The meaningful distinction is not whether a repository can be cloned. It is whether the open deployment reproduces the discovery, browser access, queues, persistence, observability and output contract the business pipeline depends on.
For Crawl4AI, pin 0.9.4 or later, require authentication, bind private evaluation instances appropriately and save the exact image or package version with every result set. Prefer CSS or XPath extraction on stable templates, then isolate any LLM extraction provider as a separate cost and data boundary. The model's 8 to 20 monthly operator hours are not a benchmark; they are a prompt to price patching, proxy failures, schema drift and recovery instead of calling them free.
For the Firecrawl core, treat Cloud-versus-self-hosting as its own architecture choice. The repository can remove a vendor credit line while adding PostgreSQL, Redis, RabbitMQ, browser workers, monitoring and upgrades to the team's workload. The dedicated self-host article linked above includes a verification pack for that decision.
What Is the Best AI for Web Scraping?
The best choice follows the input boundary. If the input is a domain and the output must be a complete Markdown-and-JSON corpus, start with Firecrawl or Apify, then price ScrapFly. If the input is already a trusted URL list, Jina Reader removes crawl machinery and can be much cheaper. If access is the hard part, compare ScrapingBee's cost ceiling with Zyte's site tiers and Bright Data's bundled access stack.
AI Agents for Web Scraping Need an Acceptance Gate
An agent should never decide that a 200 response is ready for retrieval. Give it a deterministic gate: required fields, minimum Markdown length, table and code preservation, normalized links, content hash, allowed content type and explicit null rules. The agent can route failures, but it should not waive the contract to keep a job moving.
The decision flips in four places:
- Stay with Firecrawl when it passes the fixture and the six-month savings cannot repay migration and dual-run work.
- Choose Apify when a managed crawl job, persisted dataset and flexible Actor workflow matter more than a single page-credit number.
- Choose Crawl4AI when the team already owns containers, access routing and on-call coverage, or a data boundary makes managed processing unacceptable.
- Choose a narrower API when discovery is already handled or protected-page access dominates the job. Jina, ScrapingBee, Zyte and Bright Data are strongest only when that boundary is written down.
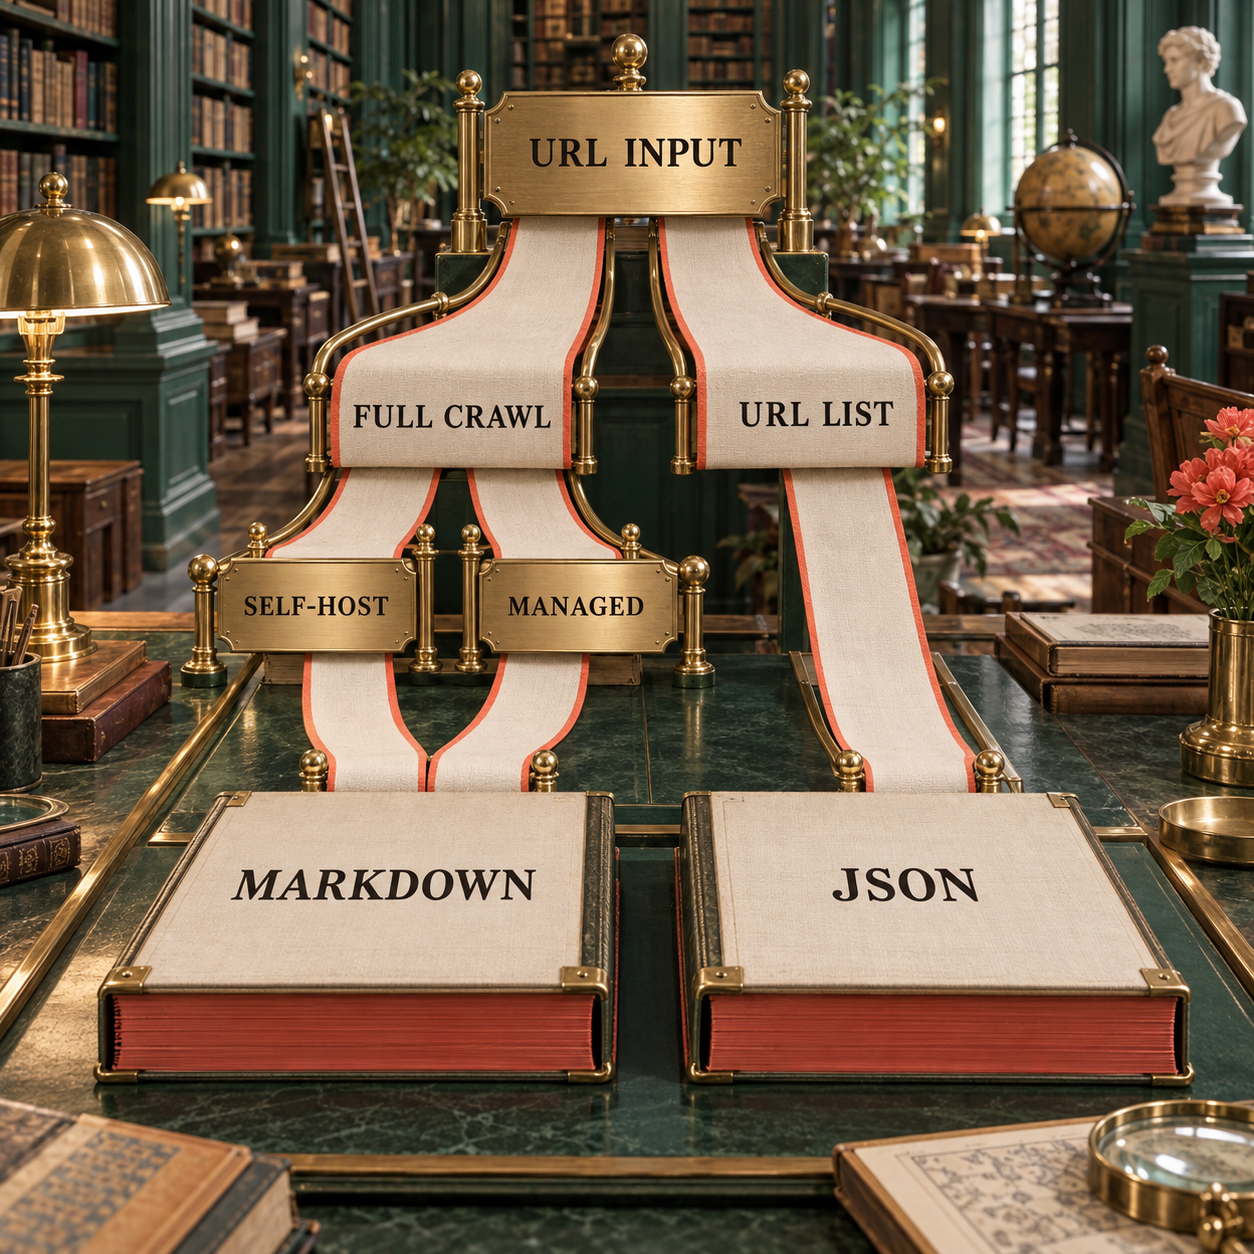
Do not pick by the prettiest playground output. The chosen configuration has to pass the same fixture, save the same evidence and produce the same downstream chunks. A tool that looks cleaner on one article page can still fail the table, PDF or JavaScript route that decides production acceptance.
The Ones to Avoid as a Direct Replacement
Avoid buying a neighboring category and pretending the pipeline is complete. These tools can be useful, but they do not replace the full Firecrawl job defined here:
- Exa and Tavily: keep them in the search-provider evaluation. They were cut from this shortlist because this replacement starts after a domain or URL set has been chosen and must produce accepted page bodies.
- Playwright and Puppeteer alone: browser automation is a building block, not a managed crawl manifest, Markdown contract, retry ledger or structured delivery system. Pick them only when building those layers is the intent.
- A proxy-only service: access to a response does not clean navigation, retain links, validate JSON or keep chunk boundaries stable.
- An unmaintained crawler fork: a free repository becomes an incident when browser versions, security fixes or target behavior change and nobody owns the release path.
Also avoid using a marketing benchmark as migration proof. Unless the exact configuration ran against the saved 20-URL fixture, the number describes somebody else's workload. This article intentionally publishes no synthetic pass rate or latency league table.
Migration Worksheet for a Small Team
A safe migration keeps Firecrawl and the candidate in parallel until the normalized outputs, retry behavior and chunks agree on the fixed fixture and a representative production sample. The worksheet needs one owner, one versioned schema and one rollback trigger.
1. Lock the input and discovery contract
Record whether URLs come from a domain crawl, sitemap, search API, queue or internal database. Save allowed domains, subdomain policy, include and exclude paths, depth, page cap, canonicalization and duplicate rules. A Jina or ScrapingBee trial is not comparable with Firecrawl unless another component supplies this entire row.
2. Freeze the output schema
Version the required fields and types. At minimum retain source_url, final_url, title, markdown, links, status_code, fetched_at and content_sha256. Mark which business fields may be null and which make the page fail. Preserve the raw response so a parser change can be re-run without paying the crawler again.
3. Define retries as accounting events
For each attempt save vendor status, HTTP status, acceptance verdict, retry reason, credit or request cost and next action. Separate transport errors, vendor-declared failures, access blocks, empty content, schema failures and downstream conversion failures. Cap retries and route exhausted items to a dead-letter queue rather than creating an invisible spending loop.
4. Save the evidence bundle
Use a path keyed by tool, release, configuration hash, run date and fixture ID. Store the request, headers, unmodified response, normalized JSON, Markdown, verdict and digest. A reviewer should be able to answer which renderer, extraction mode and schema created any accepted chunk.
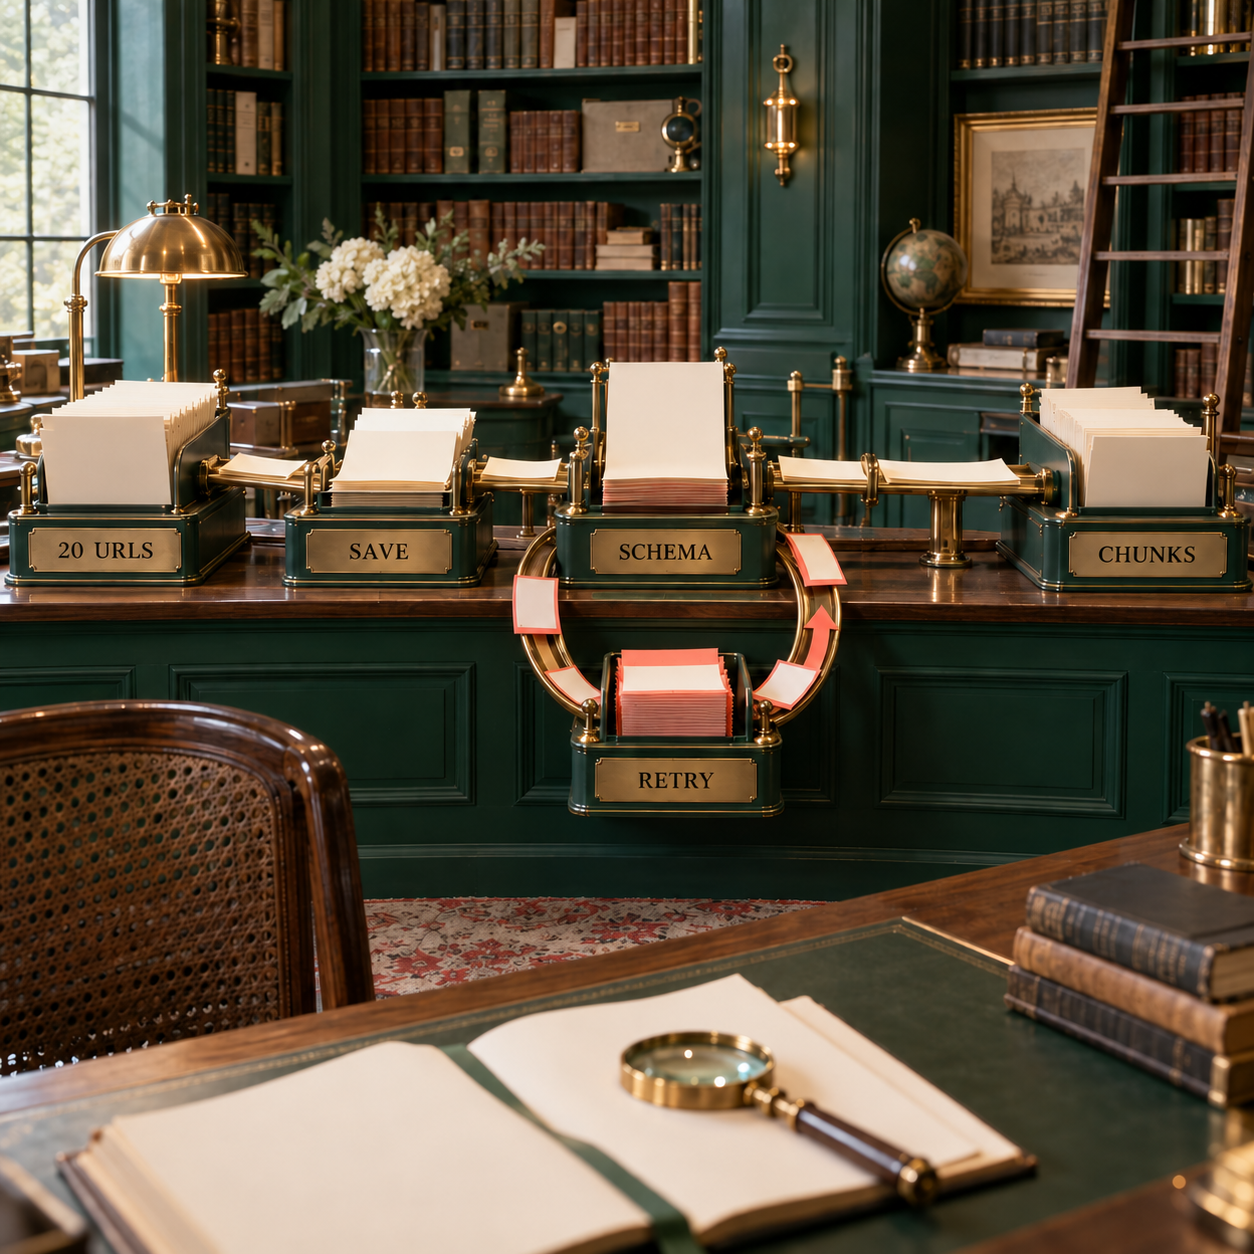
5. Regress downstream chunking
Compare heading hierarchy, code fences, tables, link targets, document order and content hashes before re-embedding anything. Then compare chunk count, chunk boundaries and source citations. A cleaner Markdown string can still change retrieval behavior if headings disappear or table rows split across chunks.
6. Price the accepted corpus and set rollback
Add vendor cash, host cost, extraction tokens, paid retries, storage and operator hours. Divide by accepted pages, not requests. Set a rollback trigger before launch, such as a required-field failure, an unexpected target tier, a material increase in chunk count or an operator-hour ceiling. Keep the old path available until the new one clears that window.
For a small team, the first useful artifact is not a vendor score. It is a worksheet with one row per fixture URL and columns for both systems. Once the row holds saved evidence, a pass or failure becomes reviewable instead of a preference.
Frequently Asked Questions
Is scraping the web illegal?
There is no universal yes-or-no answer. In the United States, the Department of Justice CFAA policy distinguishes technical access boundaries from a mere contract restriction, but contract, copyright, privacy, data use, access controls and jurisdiction can still change the analysis. This is not legal advice; production collection deserves counsel for the exact targets and use.
Is Firecrawl expensive?
It depends on the accepted output. Crawl is 1 credit per page and JSON adds 4, so 10,000 accepted pages with a 10% retry reserve need 55,000 credits in this model and fit Standard at $83. Operator work and migration cost can matter more than that invoice.
What is the best web scraping tool?
Apify Website Content Crawler is the broadest managed replacement in this shortlist. Crawl4AI is stronger when self-hosting is mandatory, ScrapFly is strong for combined managed crawl and extraction, and Jina Reader wins only when a reliable URL list already exists.
Can Firecrawl be self-hosted?
Yes. The self-hosted core gives the team control, but the team also owns its databases, queues, browser workers, upgrades, security, access routing and monitoring. It is not the same operating product as Firecrawl Cloud.
What are some alternatives to Firecrawl?
Apify Website Content Crawler, Crawl4AI, ScrapFly, Jina Reader, ScrapingBee, Zyte API and Bright Data Crawl API are the seven alternatives compared here. They divide into full crawlers, supplied-URL readers and access-first APIs.
Is self-hosting legal?
Running software on infrastructure you control is generally a separate question from what that software accesses. Authorization, access controls, site terms, copyright, privacy, data-protection rules and the intended use still need their own review.
Is it worth self-hosting?
It is worth it when a required data boundary, customization or shared platform capability outweighs the operating work. It is usually not worth creating a new on-call surface only to remove a modest monthly API bill.
What are the risks of free hosting?
Free instances may sleep, throttle CPU or memory, rotate storage, share weak IP reputation and offer no production recovery guarantee. Those limits can make a crawler look unreliable even when the software is not the cause.
Can I self host a website for free?
A hobby website or crawler evaluation may fit a free allowance. A production crawl still has compute, storage, bandwidth, access infrastructure, monitoring, backups and operator time, so a $0 host line is not a $0 operating cost.
Is Firecrawl open source?
Firecrawl publishes a self-hostable open-source core. Firecrawl Cloud adds managed infrastructure and operating services, so the repository does not by itself reproduce the Cloud product's cost or reliability boundary.
- Last Updated
- Sep 25, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

CodeRabbit Alternatives
Compare CodeRabbit alternatives by Git support, hosting, review limits and real team cost, with clear reasons to switch or stay.Sep 25, 2026Build
Greptile vs CodeRabbit
Compare Greptile and CodeRabbit on review limits, real team costs, Git support and the checks to run before buying.Sep 25, 2026Build
How to Use Perplexity Portable Computer
Set up Perplexity Portable Computer on a supported Windows PC, choose a local model, and test a recurring file task with clear cloud permissions.Sep 25, 2026Build
AgentRun Review
Test AgentRun's workflow beta on support tasks, inspect branching and escalation, and see when it earns its place beside your existing agent.Sep 24, 2026Build
Perplexity Fast Search vs Default
Compare Perplexity Fast Search with default web search on price, latency, source coverage, and the API setting your agent should use.Sep 24, 2026Build
AI Agent Fallback Costs
A sandboxed writer triggered paid image fallbacks until a shared balance ran out. The incident, missing outputs, and fix at the upload boundary.Sep 24, 2026Build
Is Cursor Rollouts Free
Cursor Rollouts needs Teams or Enterprise. Understand the 10-day launch credits, roughly 50 or 500 changes, and the costs to check.Sep 24, 2026Build