Firecrawl Self Host
Self-host Firecrawl from a pinned release, verify a scrape, and compare features and 30-day costs with Cloud before choosing a deployment.



Self-hosting Firecrawl buys control over the code and infrastructure, not a free managed service. Pin v2.11.162, prove a real /v2/scrape request, save the evidence, then price the operating work. In the 30-day worksheet below, Firecrawl Cloud costs $0 for 1,000 basic pages and $44 for 10,000, while the self-host model reaches $725.20 in month one once an explicitly assumed six operator hours are counted.
The short answer: Cloud wins on cost at this scale
Self-host Firecrawl when source access, infrastructure control, or a required network boundary is worth owning the stack. Choose Cloud when the job is simply to turn public URLs into clean content. Firecrawl reaches the same conclusion in its self-hosting guide: Cloud is the fastest supported route to production, while self-hosting makes your team responsible for the machinery.
The self-host figures are a budget, not a throughput promise. Firecrawl publishes no verified minimum host size, and this run could not test whether the quoted machine sustains either volume. The honest reason to accept the premium is control. Cost savings have to be demonstrated on your pages, with your concurrency and failure rate.
What self-hosting actually gives you
You get the core Firecrawl engine on infrastructure you control, plus the job of operating every dependency around it. Think of Cloud as a staffed commercial kitchen and self-hosting as receiving the kitchen plan. The plan is useful, inspectable, and adaptable. It does not include the cooks, fire inspection, refrigeration checks, or night shift.
The pinned default stack supports the core scrape, crawl, map, and search routes. Fetch and Playwright processing are included. The stack also depends on services such as PostgreSQL, Redis, and RabbitMQ, and the readiness endpoint does not verify that the full chain works.
That boundary matters because {"status":"ok"} only proves that one HTTP endpoint answered. It does not prove a page can leave the host, render, pass through the workers, and return Markdown. A successful scrape is the minimum usable proof.
Install the release the guide was written for
Use Firecrawl v2.11.162, not the moving main branch. The tag was created on July 30, 2026 and points to commit 7666c1f9ae8720a6bba271e0f60b6a217f8a5210. Pinning makes the code, Compose file, and setup instructions refer to the same thing.
The official prerequisites are Git, Docker Engine or Docker Desktop, Docker Compose v2, curl, an available port 3002, and enough host capacity to build and run several services. Firecrawl does not publish a verified minimum machine size.
Pin the source
Clone Firecrawl and check out
v2.11.162. Record the resulting commit so a future operator can reproduce the deployment.Create the baseline environment
Disable database authentication only for this trusted-network evaluation, keep the PostgreSQL database name as
postgres, and use a random password of at least 32 characters. Do not commit.env.Build and inspect every service
Start the Compose stack, then read
docker compose ps --all. Long-running services should be running and one-shot initialization work should be complete.Prove a real scrape
Check readiness, then call
/v2/scrapeforhttps://example.com. Do not stop at the readiness response.
git clone https://github.com/firecrawl/firecrawl.git
cd firecrawl
git checkout v2.11.162
git rev-parse HEAD

db_password="$(openssl rand -hex 32)"
printf 'USE_DB_AUTHENTICATION=false\nPOSTGRES_USER=postgres\nPOSTGRES_PASSWORD=%s\nPOSTGRES_DB=postgres\n' \
  "$db_password" > .env

docker compose up --build -d
docker compose ps --all

curl --fail --silent --show-error --max-time 5 \
  http://localhost:3002/v0/health/readiness

curl --fail-with-body --silent --show-error --max-time 75 \
  -X POST http://localhost:3002/v2/scrape \
  -H 'Content-Type: application/json' \
  -d '{"url":"https://example.com","formats":["markdown"],"timeout":60000}'
The scrape passes only when the response contains success: true, returned Markdown, and metadata with statusCode: 200. Exact metadata can vary by target. If readiness passes and scrape fails, inspect the API and Playwright logs because the green heartbeat did not exercise those paths.
Save a verification record you can hand to another engineer
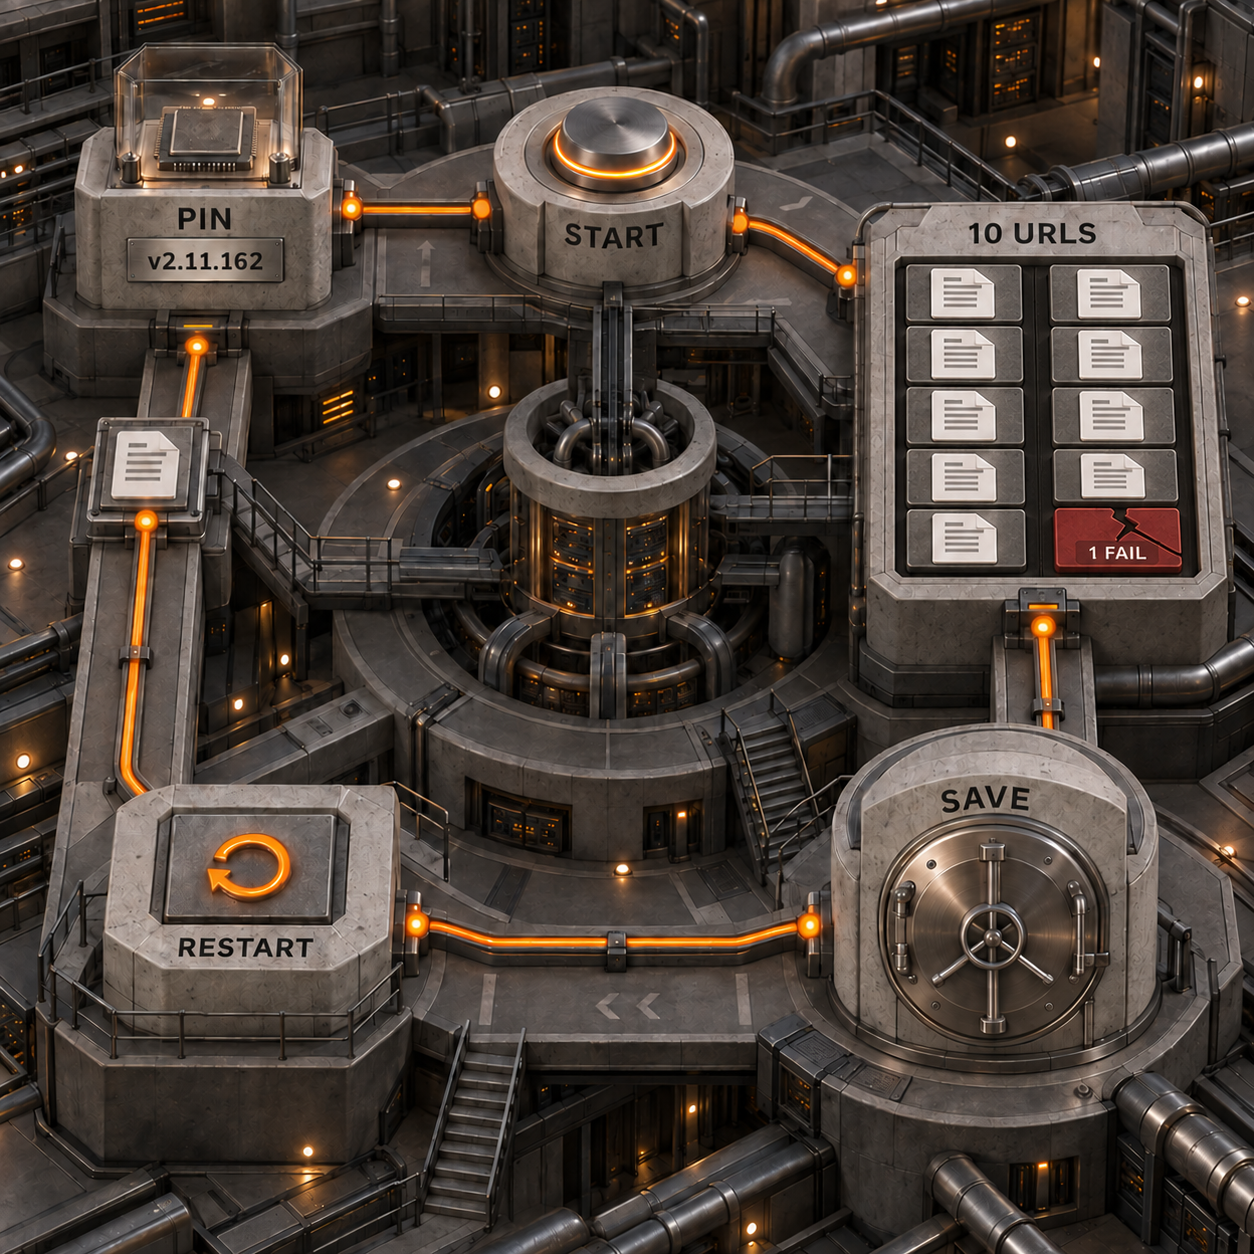
A setup is not verified until its raw evidence survives the terminal session. The script below starts from the pinned repository and writes a timestamped directory containing the host specification, exact release, build time, container state, readiness output, 10 raw scrape responses, a summary, one resource snapshot, restart output, and a second successful scrape.
The tenth URL uses the reserved .invalid domain, so the fixture contains a deliberate failure without depending on a real site breaking. The other nine targets are fixed public pages. Install jq before running the script because it builds request JSON and reads the result fields.
#!/usr/bin/env bash
set -euo pipefail

base_url="${FIRECRAWL_BASE_URL:-http://localhost:3002}"
stamp="$(date -u +%Y%m%dT%H%M%SZ)"
out="firecrawl-verification-${stamp}"
mkdir -p "$out/responses"

actual_release="$(git describe --tags --exact-match)"
[[ "$actual_release" == "v2.11.162" ]] || {
  printf 'Expected v2.11.162, found %s\n' "$actual_release" >&2
  exit 1
}

{
  printf 'checked_at_utc=%s\n' "$(date -u +%FT%TZ)"
  printf 'release=%s\n' "$actual_release"
  printf 'commit=%s\n' "$(git rev-parse HEAD)"
  printf 'cpus=%s\n' "$(getconf _NPROCESSORS_ONLN)"
  awk '/MemTotal/ {printf "memory_kib=%s\n", $2}' /proc/meminfo
  uname -a
  docker version
  docker compose version
} > "$out/host.txt" 2>&1

setup_start="$(date +%s)"
docker compose up --build -d > "$out/compose-up.log" 2>&1
printf '%s\n' "$(( $(date +%s) - setup_start ))" > "$out/setup-seconds.txt"
docker compose ps --all --format json > "$out/containers-before.json"
curl --fail --silent --show-error --max-time 5 \
  "$base_url/v0/health/readiness" > "$out/readiness.json"

targets=(
  https://example.com
  https://example.org
  https://example.net
  https://httpbin.org/html
  https://www.iana.org/help/example-domains
  https://www.rfc-editor.org/rfc/rfc9110
  https://www.w3.org/TR/PNG/iso_8859-1.txt
  https://docs.python.org/3/
  https://www.firecrawl.dev/
  https://fixture-failure.invalid/
)

printf 'index\turl\tcurl_exit\tsuccess\tstatus_code\n' > "$out/summary.tsv"
i=0
for target in "${targets[@]}"; do
  i=$((i + 1))
  response="$out/responses/$(printf '%02d' "$i").json"
  payload="$(jq -n --arg url "$target" \
    '{url:$url,formats:["markdown"],timeout:60000}')"
  if curl --silent --show-error --max-time 75 -X POST \
    "$base_url/v2/scrape" -H 'Content-Type: application/json' \
    -d "$payload" > "$response"; then curl_exit=0; else curl_exit=$?; fi
  success="$(jq -r '.success // false' "$response" 2>/dev/null || printf false)"
  status="$(jq -r '.data.metadata.statusCode // .error // "none"' \
    "$response" 2>/dev/null || printf unreadable)"
  printf '%s\t%s\t%s\t%s\t%s\n' \
    "$i" "$target" "$curl_exit" "$success" "$status" >> "$out/summary.tsv"
done

docker stats --no-stream --format json > "$out/container-stats.json"
docker compose restart > "$out/restart.log" 2>&1
for attempt in $(seq 1 60); do
  if curl --fail --silent --max-time 5 "$base_url/v0/health/readiness" \
    > "$out/readiness-after-restart.json"; then break; fi
  sleep 2
done
docker compose ps --all --format json > "$out/containers-after.json"
jq -n '{url:"https://example.com",formats:["markdown"],timeout:60000}' | \
  curl --fail-with-body --silent --show-error --max-time 75 \
    -X POST "$base_url/v2/scrape" -H 'Content-Type: application/json' -d @- \
    > "$out/restart-scrape.json"

jq -e -s 'all(.[]; .success == true and .data.metadata.statusCode == 200)' \
  "$out/responses/01.json" "$out/restart-scrape.json" >/dev/null
printf 'Saved verification record: %s\n' "$out"
Do not publish a success claim from this record until the first scrape and restart scrape both pass. Keep every failed response too. A failure is evidence about DNS, egress, anti-bot behavior, target status, or the stack itself, and deleting it makes the record less useful.
Know where the default stack ends
Self-hosted Firecrawl includes the core routes, not every Firecrawl product surface. Add services because a measured requirement calls for them, not because a configuration option exists.
For Cloud search and retrieval choices beyond this deployment decision, the AI search API comparison covers the wider vendor field. Replacement scrapers are a separate buying question.
Who profits most from self-hosting
The best fits already have a platform function and a control requirement. Lower page price alone is not enough at small volume.
The weak fits are just as clear. A two-person product team that wants one reliable scrape endpoint is buying an operations project it did not need. A team that depends on Agent, Browser, Interact, screenshots, page actions, or managed advanced scraping is also starting on the wrong side of the feature boundary.
The 30-day worksheet: control has a real bill
At 1,000 and 10,000 basic pages, managed Firecrawl is cheaper under explicit, conservative assumptions. The self-host budget uses a DigitalOcean Basic Droplet with 8 vCPUs, 16 GiB RAM, and 320 GiB SSD at $96 per month, plus a 100 GiB persistent Volume at $10 and a weekly backup allowance of $19.20. DigitalOcean listed those prices on September 22, 2026.
The 16 GiB choice is not an official minimum. It is a budgeting assumption informed by the pinned Compose file, which caps the API service at 8 GiB and Playwright at 4 GiB while the database, cache, queue, and other processes still need room. Only a workload test can size the host.
Operator time is the larger line. This worksheet assumes four setup hours and two maintenance hours in the first 30 days at a loaded rate of $100 per hour. That is an assumption, not a market rate. Replace it with your own number.
Firecrawl Cloud charges one credit for a basic scraped page. The Free plan includes 1,000 credits at $0. For 10,000 pages on month-to-month billing, Hobby costs $19 for 5,000 credits and another 5,000 Hobby credits cost five $5 increments, producing the $44 total. The annual Hobby price lowers that effective month to $41 but requires annual billing.
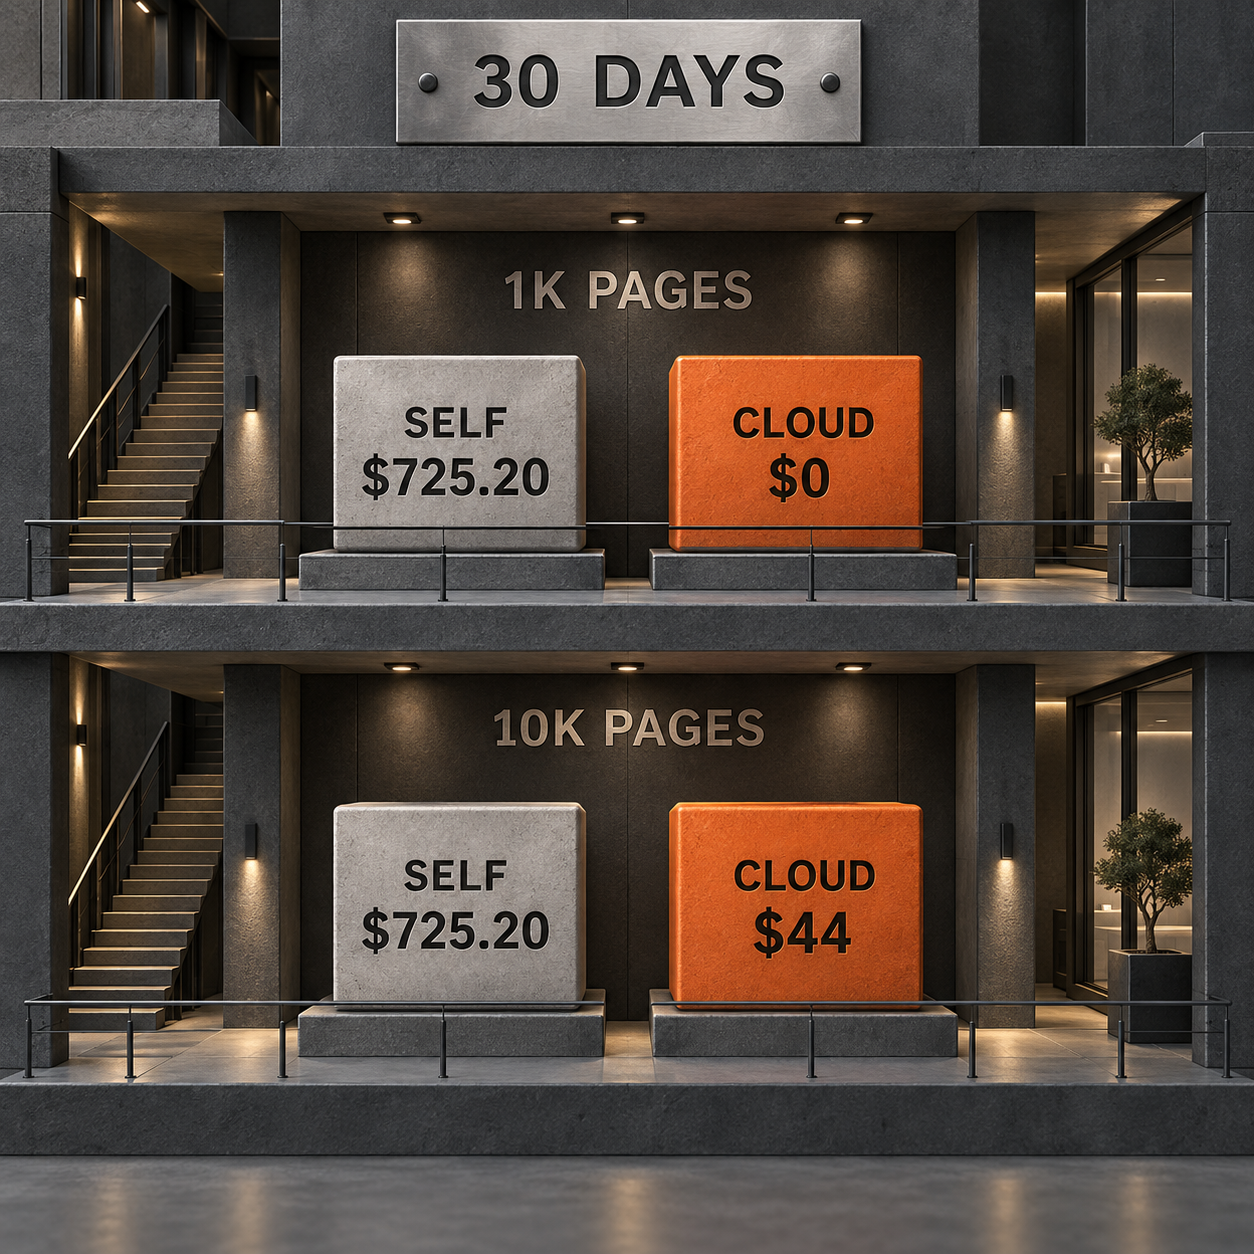
This model excludes taxes, optional LLM providers, proxy fees, Fire-engine, high availability, excess transfer, legal review, and incident remediation. It also gives the self-host machine no unproven throughput credit. In a later illustrative month, removing the four setup hours brings self-hosting to $325.20, still above Cloud at both modeled volumes.
The conclusion is not that self-hosting can never save money. It is that savings begin only after a benchmark proves capacity and enough volume spreads fixed infrastructure and operator time across more successful pages. At 10,000 pages, the control requirement has to justify a first-month premium of $681.20 in this worksheet.
Three products worth building around the gap
The strongest opportunity is the verification pack, because it turns an ambiguous setup into evidence without competing with Firecrawl itself. The single live search snapshot returned eight related searches and nine People Also Ask questions. Five related searches focus on Docker, Docker Compose, free usage, Cloud comparison, or API keys, while the questions explicitly ask whether Firecrawl is expensive and safe.
1. Self-host readiness and verification pack
The product is a local CLI and report for engineering leads. It checks the release, host, Compose state, real scrape path, expected failure, restart behavior, and production gaps, then produces a signed archive for review.
The demand signal is direct: Google related searches include Firecrawl self-host Docker, Firecrawl self-host docker compose, and Firecrawl self-host API key. The smallest sellable version is one command, the fixed fixture, an HTML report, and redaction controls. The catch is environmental variety. A report can prove what ran; it cannot promise that every target or future release will behave the same way.
2. Cloud versus self-host cost planner
The product is a deployment calculator that takes successful pages, options, concurrency, operator rate, recovery target, and required features. It shows Cloud credits beside infrastructure and labor, with every assumption visible.
The search snapshot includes Firecrawl self-hosted vs cloud, and People Also Ask includes Is Firecrawl expensive? and Is there a free version of Firecrawl available? The live price anchors are concrete: $0 for 1,000 Cloud credits, $19 month-to-month for 5,000 Hobby credits, and $5 for each extra 1,000 Hobby credits. The MVP is a versioned pricing table plus a worksheet export. The catch is self-host capacity: without the buyer's benchmark, the calculator must show a range rather than a fake break-even point.
3. Production hardening blueprint
The product is an opinionated infrastructure module for teams that passed the evaluation and now need authentication, TLS, persistent data, backups, restore tests, monitoring, secrets, and controlled egress.
The demand signal is split between the People Also Ask question Is Firecrawl safe to use? and the related search Firecrawl self-host API key. Firecrawl's own guide lists every missing production decision, so the value is implementation and evidence, not pretending the responsibilities were undocumented. The MVP is one supported cloud target, version-pinned infrastructure code, alerts, and a recovery drill. The catch is liability. A reusable module cannot certify a customer's security or compliance posture.
Limits and the honest take
Do not self-host Firecrawl to save $19 before you have measured the operating work. The baseline disables API authentication, has no TLS, does not add durable storage for PostgreSQL, Redis, and RabbitMQ, and is not highly available. Exposing it to an untrusted network would turn an evaluation shortcut into a security mistake.
Do not assume the default stack matches Cloud feature for feature. LLM formats need a provider. Fire-engine is separate. Screenshots and actions are not available in the default paths. Agent, Browser, Interact, dashboards, and enterprise controls remain Cloud surfaces or require separately verified services.
Do not size production from the Compose limits or this worksheet. A memory cap is not a recommended host. Run the fixed fixture, add representative pages from your own workload, measure concurrency and failure classes, then test backup restoration and an upgrade rollback.
The strongest reason to proceed is a control requirement that Cloud cannot meet for the team. The weakest reason is the word "free."
The Monday move
Give one engineer a two-hour evaluation window on a disposable, private host. Pin v2.11.162, run the official single scrape, execute the saved verification script, and stop if the restart scrape does not pass. Then replace the worksheet's $100 operator rate with your loaded rate and write one sentence naming the control requirement. If that sentence is vague, use Cloud. If it is concrete, plan production controls before adding volume.
Is Firecrawl expensive?
It depends on the deployment and page volume. Firecrawl Cloud costs $0 for the first 1,000 basic page credits each month. In this worksheet, 10,000 basic pages cost $44 on month-to-month Hobby plus pay-as-you-go, while the illustrative self-host first month costs $725.20 with six assumed operator hours. Self-hosting makes financial sense only after your benchmark and control requirements justify its fixed work.
Is there a free version of Firecrawl available?
Yes. Firecrawl has an open-source deployment path, and Firecrawl Cloud has a Free plan with 1,000 credits per month. Open source removes the Firecrawl plan charge, not the cost of compute, storage, security, monitoring, upgrades, recovery, and operator time.
Is Firecrawl safe to use?
The evaluation baseline is safe only inside a trusted network with appropriate host and network controls. It disables database authentication and does not include a production authentication design, TLS, durable storage, high availability, or recovery. Safety depends on implementing and testing those controls before exposure.
How do you self-host Firecrawl with Docker Compose?
Install Git, Docker, Docker Compose v2, and curl. Check out v2.11.162, create the four-value baseline .env, run docker compose up --build -d, inspect every service, check readiness, and then require a successful POST /v2/scrape response. Save raw results and repeat the scrape after a restart.
Does self-hosted Firecrawl need an API key?
The trusted-network evaluation sets USE_DB_AUTHENTICATION=false, so its local requests do not use an API key. That is not a public-production design. Firecrawl says production authentication needs a complete supported identity and database design, plus network controls and TLS. One environment variable is not enough.
If you want a version-pinned, observable deployment built around your control requirements, see AI production systems.
- Last Updated
- Sep 22, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Human Approval for AI Agent Retries
An agent spent $5.48 before anyone looked. See why paid redos need approval that the model cannot grant itself.Sep 22, 2026Build
MindStudio AI Agent Builder
Evaluate MindStudio AI Agent Builder by workflow fit, plan limits, model charges, and the cost of 1,000 or 10,000 completed jobs.Sep 22, 2026Build
Superwhisper vs Wispr Flow
Compare Superwhisper and Wispr Flow for business dictation: local and cloud settings, supported devices, correction work, and the full subscription cost.Sep 22, 2026Build
AI Automation Agency
Choose an AI automation agency by workflow fit, 90-day total cost, support, and ownership. Compare providers and check the pilot before signing.Sep 22, 2026Build
How to Use Claude Code Projects
Set up Claude Code Projects, check beta access, share context across cloud threads, and see which usage and local-tool limits matter.Sep 21, 2026Build
How to Use Jev
Use Jev to route a support ticket, read its confidence scores, and test when your workflow should hand the decision to a person.Sep 21, 2026Build
How to Make Claude Code Read AGENTS.md
Set up Claude Code's native AGENTS.md support, check which instruction file loads, and handle provider limits and existing CLAUDE.md files.Sep 19, 2026Build