AgentRun Review
Test AgentRun's workflow beta on support tasks, inspect branching and escalation, and see when it earns its place beside your existing agent.


AgentRun earns its place when a repeated job needs visible branches, schema-checked state, and a hard stop on agent calls. In this review, 0.1.0-beta.4 completed the two simple support cases with no agent call, used one agent call for the two investigation cases, and escalated the unresolved case with exit code 2; a fixed 31-line function still won on simplicity.
AgentRun Review: What It Actually Is
AgentRun is Parcha's TypeScript workflow interpreter for putting deterministic structure around tools, narrow model decisions, and agent calls. Parcha open-sourced it on 23 September 2026. A workflow document names the state contracts, steps, branches, limits, and escalation path; your application supplies the tools, model access, permissions, storage, and delivery. It is not Alibaba Cloud's product with the same name, the older Python package that executes model-generated code, or the 2014 mobile game that still occupies search results. The current core package is @parcha/agentrun-dsl version 0.1.0-beta.4, released under Apache-2.0.
Who Parcha AgentRun Is For, and Who Should Skip It
AgentRun is for a TypeScript team that already has an agent runtime and can point to one repeated job where ordinary code has become hard to inspect. Support triage is a good fit: search first, judge whether the answer is sufficient, spend one agent call only when investigation is needed, then return or hand the case to a person. Evidence screening, approval routing, and research pipelines have the same shape. The value is strongest when a product, operations, or risk owner needs to read the control flow without tracing a web of callbacks.
Skip AgentRun when the job is one fixed function with two or three obvious branches. The control implementation used for this review matched all four support outcomes with a 31-line function body, while the AgentRun example workflow file is 93 lines before host integration. Raw brevity belongs to the function.
Choose LangGraph.js instead when the central problem is a long-running, stateful agent with persistence, streaming, and human interruption. Choose Temporal when the non-negotiable requirement is durable application execution across crashes, network failures, and long waits. AgentRun exposes recovery hooks, but it is not a bundled durable scheduler. If your team needs Python, browser execution, a hosted dashboard, or a production support SLA, beta.4 is also the wrong purchase decision because none of those comes with this release.
AgentRun DSL Capability 1: Typed State Catches Contract Drift
AgentRun DSL earns its first point by refusing a final value that no longer matches the declared contract. That sounds basic until a workflow combines a search result, a semantic decision, and an agent submission. Without one final validator, a shape change in any branch can reach the caller as a partial success.
The support workflow distinguishes a loose Candidate from the final Answer. Search may return empty text or no sources because that condition is allowed to trigger investigation. Completion is stricter: the final answer needs nonempty text and at least one source. The authoring guide also validates declared input and output contracts while intermediate state paths are checked during execution.
The contract test added one required field without changing the fixture output:
schemaWorkflow.schemas.Answer.properties.resolutionCode = {
  type: 'string',
  minLength: 1,
};
schemaWorkflow.schemas.Answer.required.push('resolutionCode');
The password path still performed its help lookup and first decision. Completion then failed with WorkflowOutputInvalidError, code output_invalid, because resolutionCode was absent. No invalid answer was returned. That is the right failure mode: the system stops at its boundary instead of treating a semantically plausible object as a contract-complete result.
The protection has a precise limit. A valid text string and a valid sources array can still contain the wrong answer. Schema validation proves that downstream code can consume the value, not that a customer should trust it. The companion review of Jev support-ticket routing covers that decision layer: probabilities and typed outputs still need labelled cases and a human fallback.
AgentRun Workflow Capability 2: Branch Control Bounds Agent Calls
AgentRun workflow control did exactly what the graph promised across four support cases: two requests stopped after search and one decision, while two entered one bounded investigation and a second decision. The useful unit is not an autonomous agent. It is a deterministic path that has one place where an agent may be called.
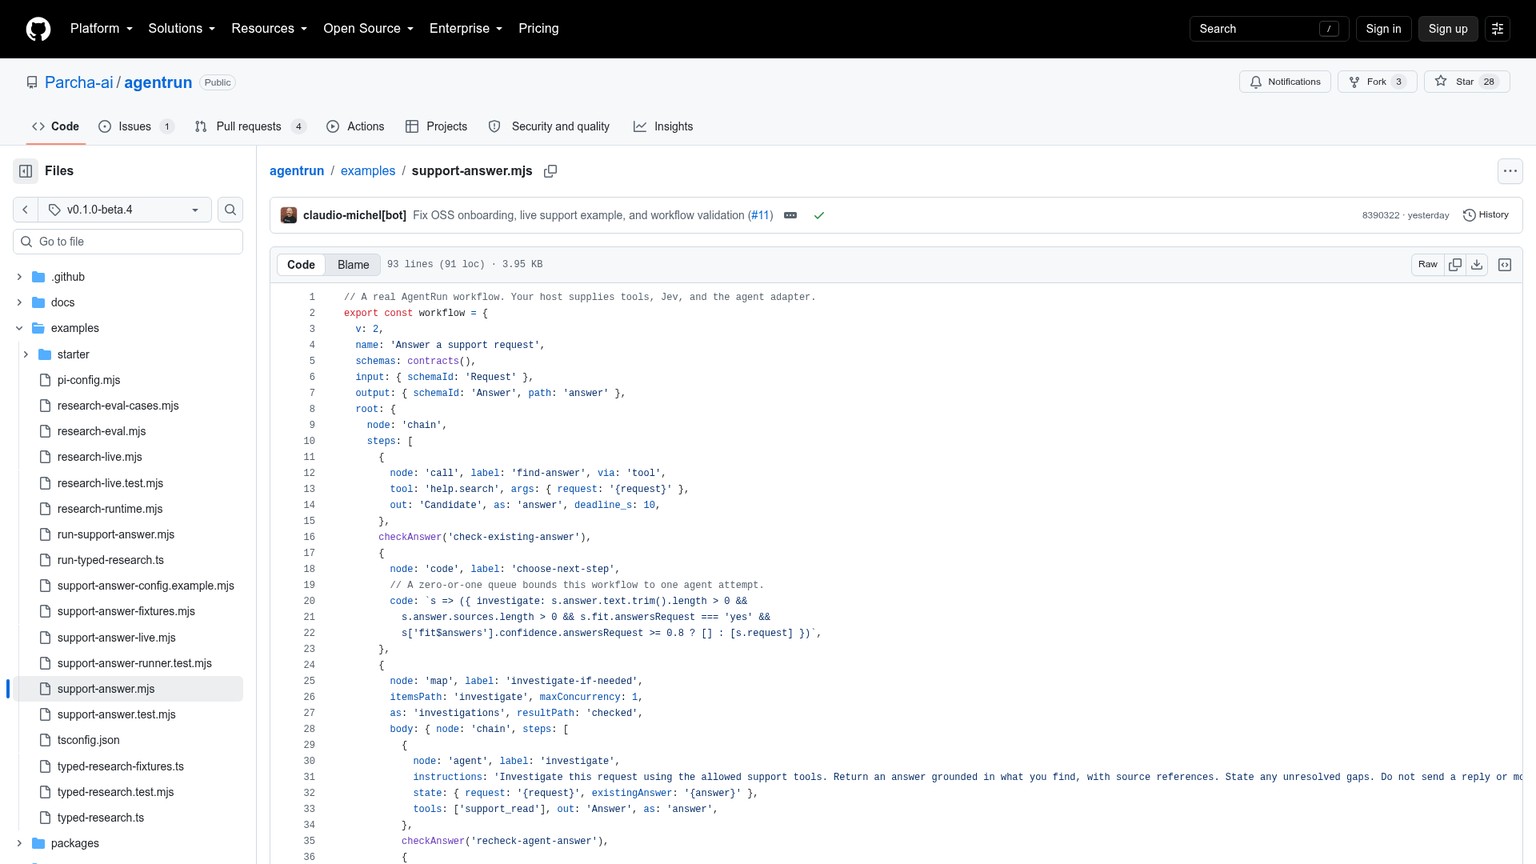
Each direct fixture run exited as documented. Password, invoice, and failed payment returned code 0. Unresolved payment returned code 2 and the reason that the answer remained insufficient or uncertain after one investigation. All four wrote zero bytes to stderr. The repository's focused support suite also passed all 31 tests in 2.92 seconds, including invalid submissions, low-confidence decisions, cancellation, and adapter-error cases.
Those results demonstrate call discipline, not customer-support quality. The search answers, Jev decisions, and investigation outputs were fixed fixtures. Changing a prompt does not make them adapt, and no live customer reply is sent. What the run proves is narrower and useful: when the first answer passes, the interpreter does not spend an agent call; when it fails, the interpreter permits exactly one investigation; when the second check fails, the case does not leak through as complete.
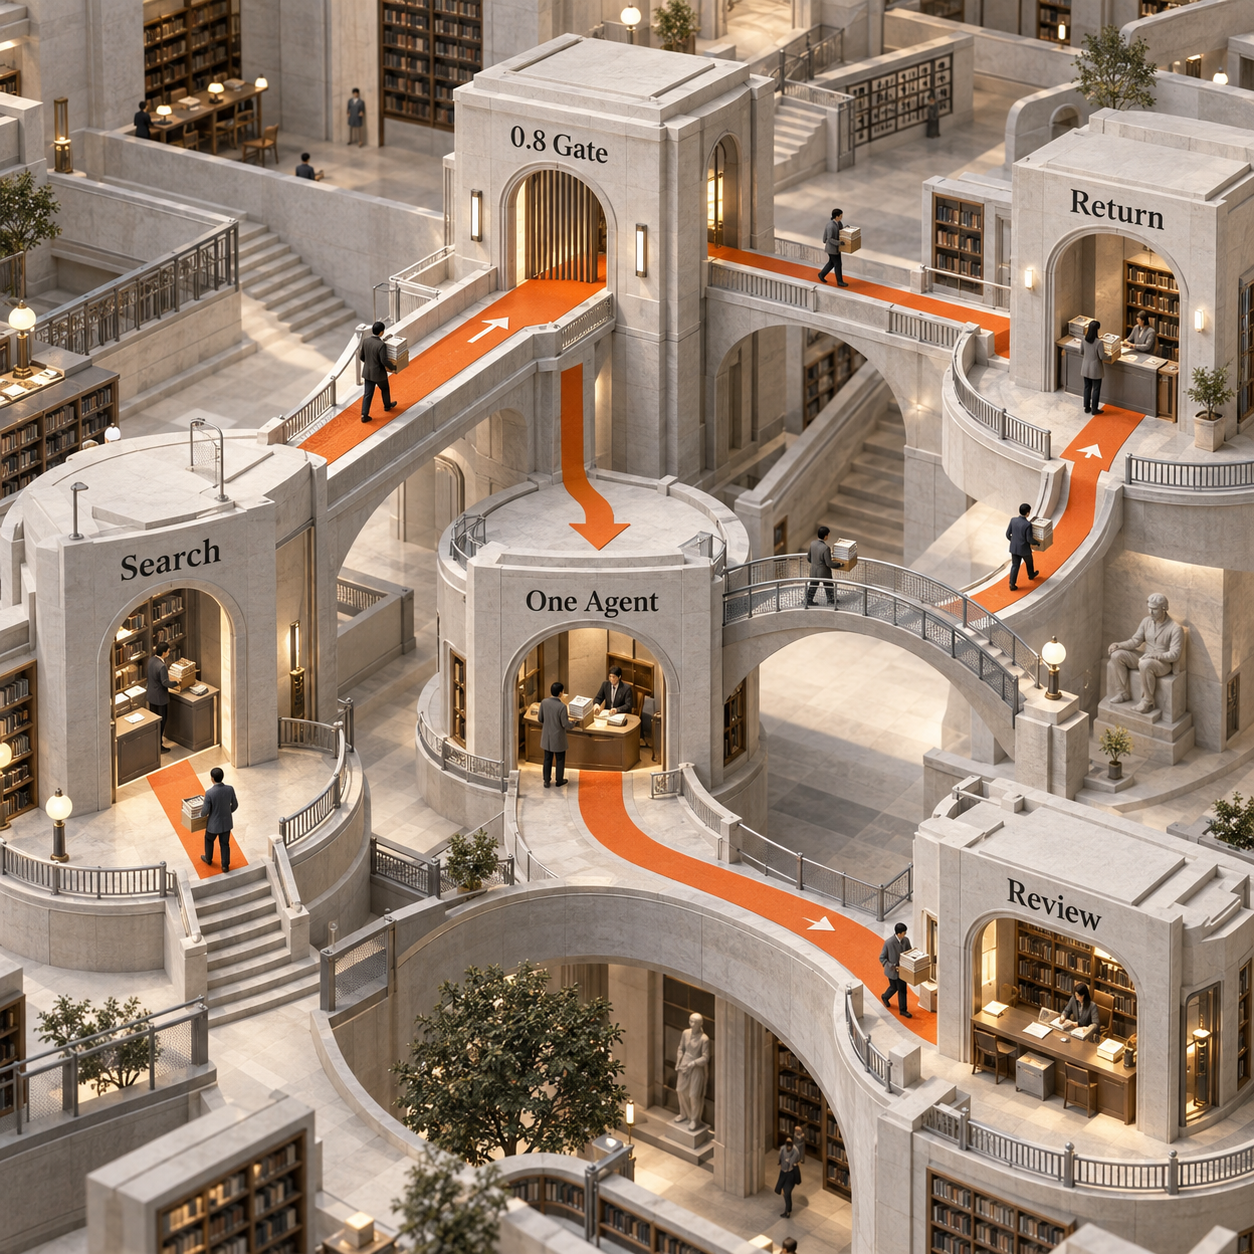
This is the strongest reason to adopt the runtime. A general agent loop can decide to search again, revise again, or call another tool because the conversation still looks unfinished. AgentRun makes the allowed work finite in the workflow itself. That gives an operator a call budget they can inspect before execution, even though the host must still enforce provider spend and tool permissions.
Capability 3: Escalation Is Code, Not a Prompt Wish
AgentRun turns escalation into a returned runtime state with a reason, not a sentence buried in an agent prompt. The tested workflow accepts an answer only when the decision is yes, the answer satisfies its contract, and confidence reaches 0.8. Otherwise it opens a zero-or-one investigation queue, checks the result again, and escalates if the same gate still fails.
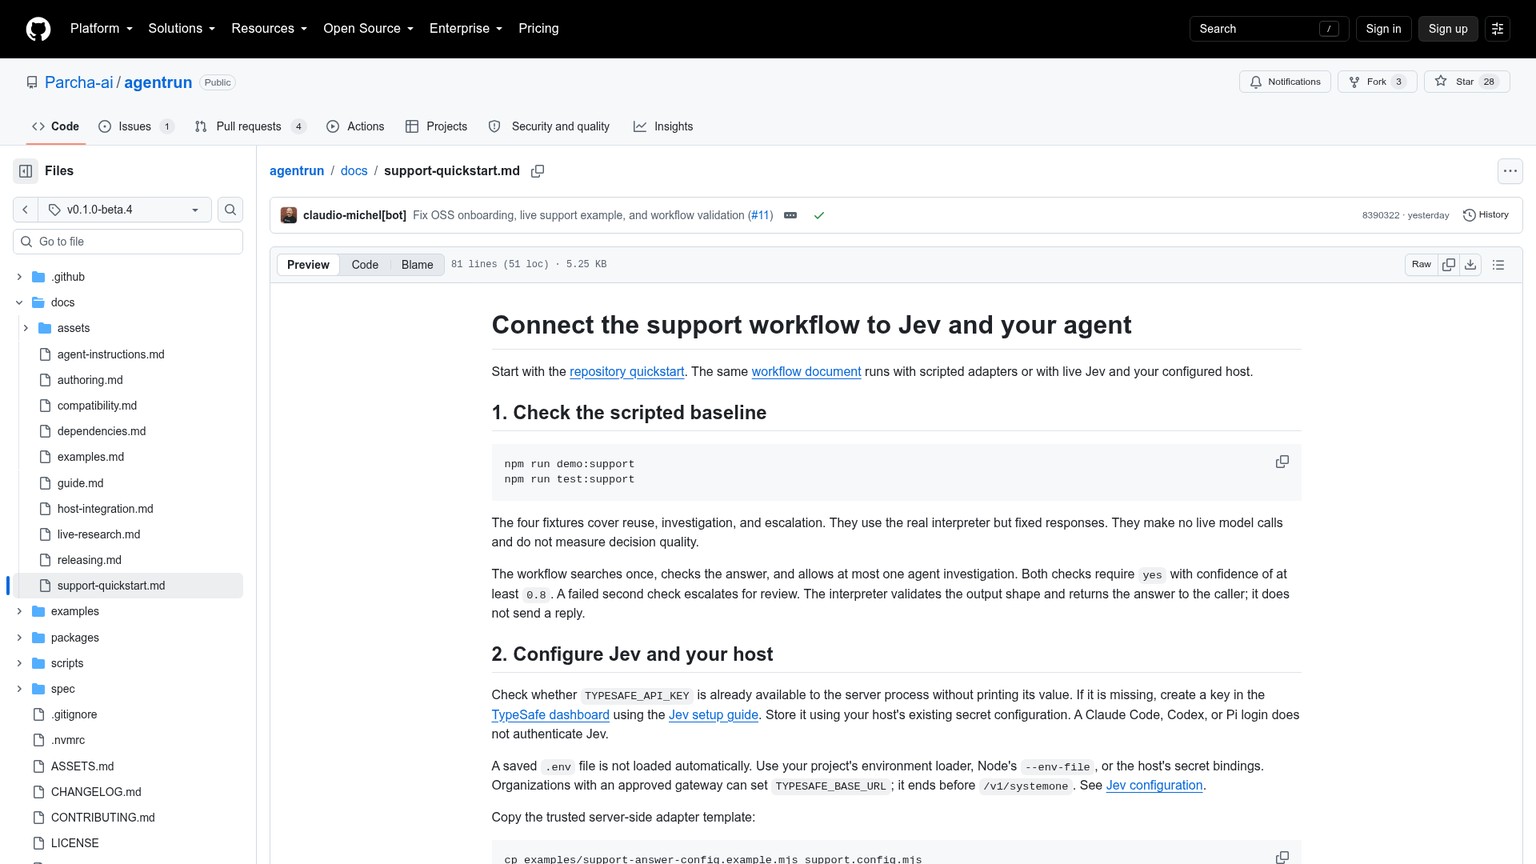
To test whether the number truly controlled behavior, both comparisons were raised from 0.8 to 0.98. The password fixture's scripted decision remained yes at 0.97. Under the original workflow, that case completed immediately with no agent call. Under the stricter workflow, it entered investigation, received the same valid answer, returned another yes at 0.97, and escalated after one agent call and two decisions.
That small edit changed the branch without changing the prompt, fixture answer, or adapter. This is the practical advantage of keeping confidence policy in code. A team can review the threshold change like any other behavioral change, run labelled cases against it, and see the resulting handoff rate before release.
Escalation also stays outside delivery. The runtime returns complete or escalated; the host decides whether to open a support ticket, alert a person, or do nothing. That separation prevents a workflow document from granting itself permission to contact a customer or mutate an account.
Capability 4: Inspection Is Useful, Integration Is Still Yours
AgentRun inspection makes the workflow legible before code executes, but it does not remove the application work around it. On the generated triage example, agentrun inspect returned a workflow digest, the judge, escalate, and code nodes, the required runJudge adapter, and executableCode: true. validate returned ok: true. dry-run also returned ok: true, while clearly reporting that the synthetic escalation path was skipped.
The skip matters. A green dry run is wiring evidence, not branch coverage. The four support fixtures supplied the behavioral proof because they deliberately exercised return, investigation, and review. Keep that distinction in CI: inspection checks structure, validation checks contracts, and fixed cases check behavior.
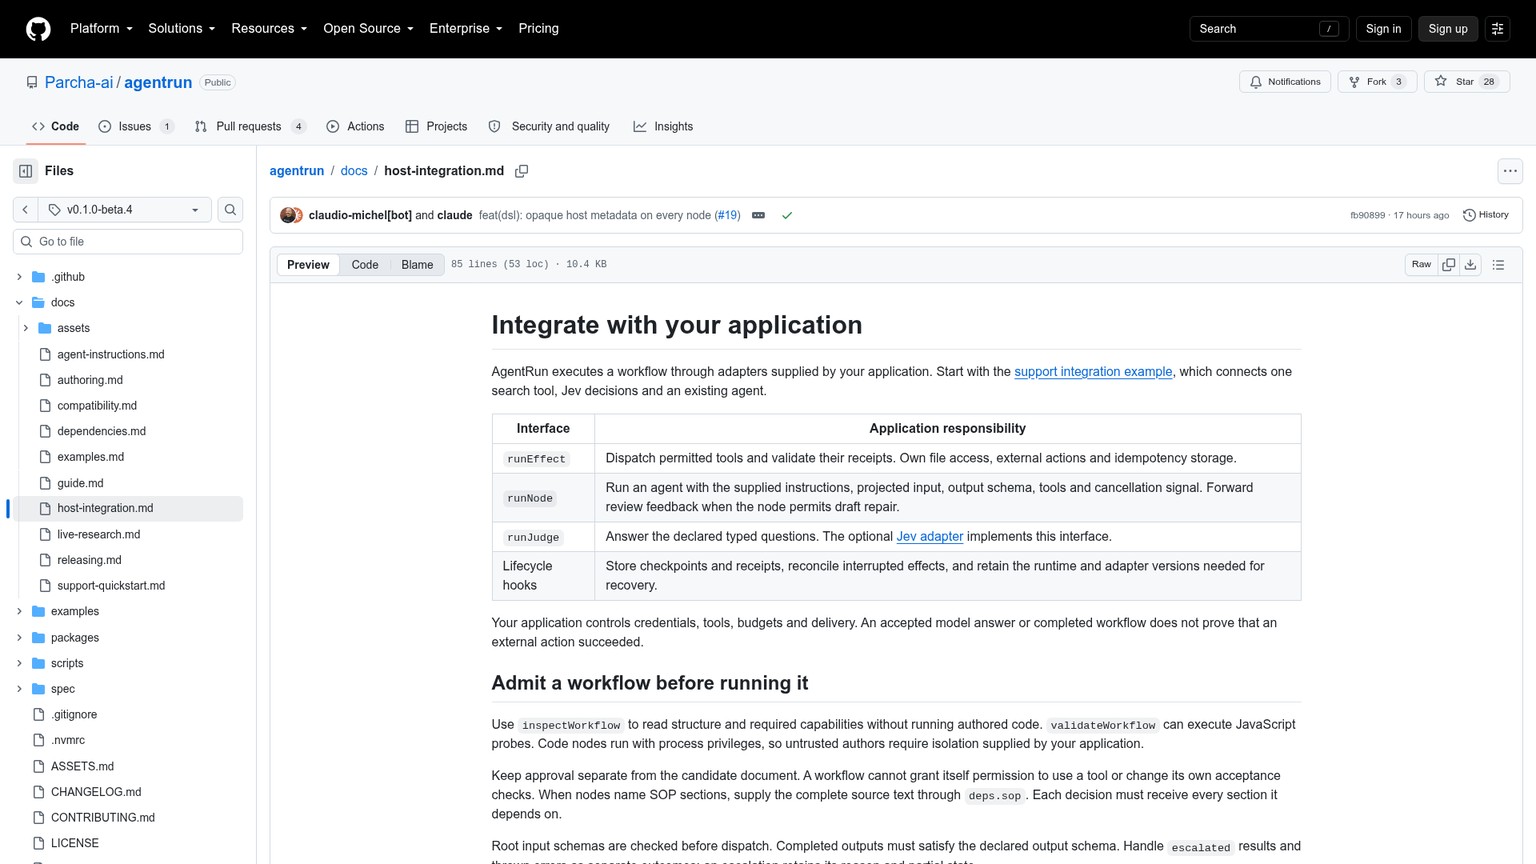
Integration requires three main adapters. runEffect dispatches tools and other effects. runJudge provides typed decisions, optionally through Jev. runNode connects the agent runtime and must forward the schema, tools, cancellation signal, and any review callback. The host also owns authentication, secrets, model choice, turn limits, budgets, logs, redaction, delivery, and durable receipts.
The plain-function control sharpens the tradeoff. Its 31-line body used the same scripted adapters and matched every baseline status and call count. For one support route, that function is easier to read and ship. AgentRun's extra 62 workflow-file lines buy a reusable document, generic inspection, shared node semantics, output contracts, structured escalation, and a surface an authoring agent can generate. They do not buy less code by default.
Pin the interpreter and the document
Store the package version beside the workflow digest. A
v: 2document does not identify the interpreter, adapters, tools, or host policies that executed it.Prove every terminal path
Create fixed cases for immediate completion, the expensive branch, escalation, and invalid output. Treat dry-run skips as work to cover, not as a pass.
Connect the host boundaries
Implement tools, decisions, agent calls, cancellation, redaction, and delivery in application code. Keep permissions and acceptance rules outside the workflow document.
Adopt only after the second workflow
The abstraction starts paying back when adapters, inspection, and regression patterns are reused. For one stable path, keep the function.
This is the same boundary behind the broader build-versus-buy decision for internal agent workflows: adopt shared machinery when repeated operating work exceeds the cost of maintaining it.
AgentRun Beta Pricing: The Interpreter Is Free, the Runtime Is Not
AgentRun beta has one software price: $0 for the Apache-2.0 code. There is no paid AgentRun tier and no hosted AgentRun runtime in beta.4. The npm package, source, CLI, workflow interpreter, and examples are the product. Parcha does not bundle model tokens, tool execution, storage, observability, or production support into that license.
Jev is a separate optional decision-model cost. Verified against TypeSafe's live model page on 24 September 2026, Jev 1.13 costs $0.042 per million input tokens and output tokens are free. At a stated assumption of 500 input tokens per decision, one check costs $0.000021 and two checks cost $0.000042. Across 100,000 cases, those decision calls would total $2.10 or $4.20 respectively.
That arithmetic excludes the agent investigation. AgentRun can connect to whichever agent runtime the host supplies, so there is no honest universal per-case figure. A support case that stops after one Jev check has a different cost profile from a case that invokes an agent, tools, a second check, storage, logs, and human review. The scripted review used no live model calls, making its observed inference spend $0 and its production-cost evidence equally zero.
Temporal illustrates why durable hosting is a separate purchase. Temporal Cloud currently starts at $50 per million actions plus storage, with $150 in credits for 90 days. AgentRun does not charge that platform fee because it does not provide the comparable hosted execution layer.
The Real Limitations
AgentRun's limitations are substantial enough that the beta should enter through one bounded workflow, not become a default architecture.
1. The release artifacts disagree about their own version
The published package manifest identifies the installed package as 0.1.0-beta.4, but its bundled README says Beta: 0.1.0-beta.3. The beta.4 tag's root README also calls the release beta.3, and its changelog labels beta.4 as unreleased. Current main corrects the root README to beta.4, but a buyer pinning the published tag sees contradictory status text.
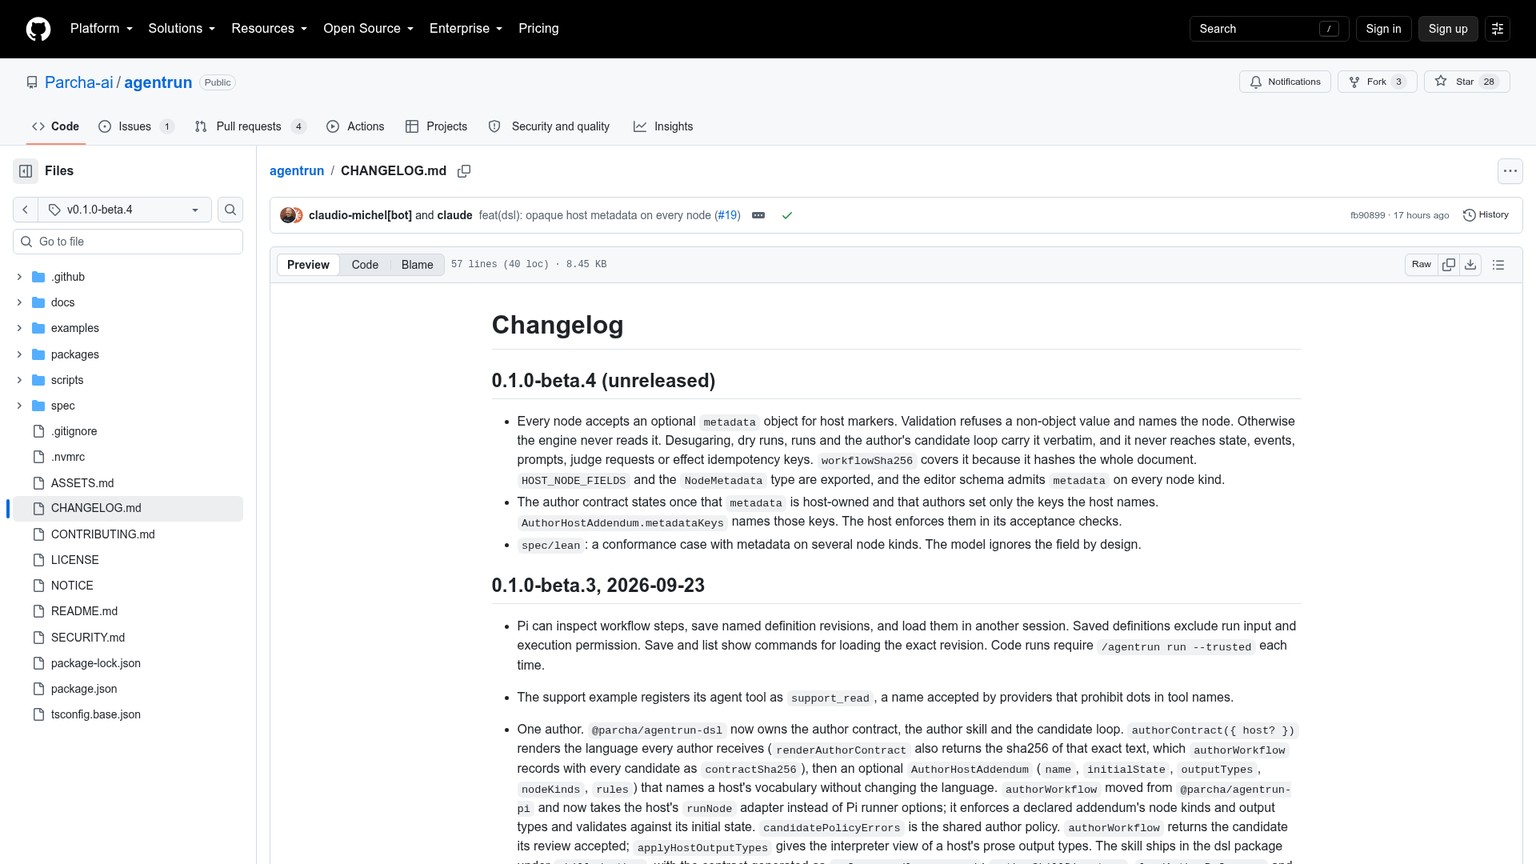
That does not break the interpreter, but it is meaningful in a workflow system where version provenance matters. Pin the npm version, store the workflow digest, and record adapter and policy versions separately. Do not rely on a prose badge to reconstruct a production run.
2. The host burden is the product boundary
AgentRun supplies control flow, not a finished support system. You still need authenticated tools, an agent adapter, Jev access if used, secrets, budget enforcement, cancellation, private diagnostics, customer-data policy, delivery, monitoring, and human-review handling. The 30.48-second source setup says nothing about that integration effort.
3. Recovery hooks are not durable execution
The runtime exposes checkpoint, memo, receipt, and recovery interfaces, but the host implements storage and reconciliation. An idempotency key helps deduplicate; it does not guarantee exactly-once delivery. A timed-out external effect may still complete, and the host must inspect its eventual settlement before retrying. If crash recovery is the primary requirement, use Temporal. If persistent stateful agent graphs are primary, evaluate LangGraph.js.
4. Trusted JavaScript is a hard security boundary
Code nodes execute JavaScript with process privileges, and validation can execute probes. The CLI's --trusted flag is an acknowledgement, not a sandbox. A team accepting workflows from users, generated artifacts, or another trust domain must isolate them with host-controlled process, filesystem, network, and credential boundaries.
5. Typed results can still be confidently wrong
The schema test failed exactly as it should, but it cannot detect a well-formed bad answer. A yes decision at high confidence is still a model result. The workflow needs labelled cases, task-specific thresholds, production monitoring, and a review path. The 31 passing support tests validate the supplied scenarios, not live Jev accuracy.
6. Platform and support options are narrow
Beta.4 is a Node.js ESM library with a Node 22.19 floor and TypeScript 5.4 floor for TypeScript consumers. Python, browser execution, and a hosted runtime are out of scope. The beta carries no production support SLA, and API or execution changes can require migration between beta releases.
7. A fixed function remains the better abstraction surprisingly often
The 31-line control function is not a toy counterexample. It matched the workflow on all four scripted cases. If the job has one search, one condition, one optional agent call, and one handoff owned by one team, a function gives better locality and fewer concepts. AgentRun becomes justified when the workflow itself needs to be inspected, generated, versioned, composed, or evaluated independently from the surrounding application.
For operational adoption, pair this review with a failure-evidence plan. The agent failure-analysis tools guide covers the logs and traces needed after the happy-path graph stops being enough.
Verdict: When AgentRun Earns Its Place
AgentRun is a credible beta for turning the repeatable middle of an agent job into explicit software. Its interpreter was easy to install, its support graph followed every bounded branch, its output contract failed closed, and its threshold behaved like code. The project is unusually direct about what remains outside the library.
The verdict is still conditional. Choose AgentRun only when all four statements are true: the workflow repeats; at least one model or agent branch needs a visible bound; more than one person or system must inspect or generate the workflow; and your host can own adapters, permissions, recovery, evaluation, and delivery. If any of those is false, start with a TypeScript function.
Use LangGraph.js when the product is fundamentally a persistent agent graph. Use Temporal when the workflow is fundamentally a durable distributed process. AgentRun sits between them and a function: narrower than either runtime, but more structured than handwritten control code.
The Monday move is concrete. Take one existing agent job and mark each step as deterministic code, typed decision, agent investigation, or human review. If the diagram contains one fixed line, keep the function. If it contains a repeated branch whose agent spend or escalation policy needs review, encode that one path in AgentRun, pin beta.4, and build four fixtures before connecting live models.
AgentRun FAQ
Is AgentRun worth it?
AgentRun is worth it when a repeated workflow needs inspectable branches, schema-checked boundaries, bounded agent calls, and an explicit review state. It is not worth the abstraction for one fixed sequence that a small function expresses clearly.
How good is AgentRun?
AgentRun beta.4 executed the scripted support graph cleanly in this review: all four outcomes matched, the unresolved path exited with code 2, and all 31 focused support tests passed. Those results establish interpreter behavior, not live model accuracy, uptime, or production savings.
What are the best AgentRun alternatives?
Use plain TypeScript for a small fixed workflow, LangGraph.js for long-running stateful agent graphs with persistence, and Temporal for durable application workflows that must resume after infrastructure failure. The right alternative depends on whether your problem is code clarity, agent state, or operational durability.
How are you thinking about state management when you handle things?
AgentRun keeps structured state inside the workflow, validates declared contracts, copies branch and map state, and detects conflicting parallel writes. Durable checkpoints, storage, retention, access control, and recovery remain host responsibilities, so the workflow document is not a database or custody layer.
- Last Updated
- Sep 24, 2026
- Category
- Build
Prefer this site in Google


Mark omidsaffari.com as preferred and Google lifts it in Top Stories, AI Overviews and AI Mode for you.

Perplexity Fast Search vs Default
Compare Perplexity Fast Search with default web search on price, latency, source coverage, and the API setting your agent should use.Sep 24, 2026Build
AI Agent Fallback Costs
A sandboxed writer triggered paid image fallbacks until a shared balance ran out. The incident, missing outputs, and fix at the upload boundary.Sep 24, 2026Build
Is Cursor Rollouts Free
Cursor Rollouts needs Teams or Enterprise. Understand the 10-day launch credits, roughly 50 or 500 changes, and the costs to check.Sep 24, 2026Build
How to Use Unreal Agent
Run Unreal Agent from Unreal Labs on a bounded repo task. Check Go setup, provider keys, JSONL output, sessions and actual usage.Sep 24, 2026Build
How to Use JetBrains Air
Install Air Alpha in your JetBrains IDE, connect an agent, add project context, and review your first code change.Sep 23, 2026Build
Is JetBrains Air Free
Air's IDE plugin is free. Compare Junie Lite, existing agent subscriptions, provider API billing, and JetBrains AI credits.Sep 23, 2026Build
Firecrawl Self Host
Self-host Firecrawl from a pinned release, verify a scrape, and compare features and 30-day costs with Cloud before choosing a deployment.Sep 22, 2026Build